Building a Synthesizer Policy Manual Maintenance Schedule That Actually Works
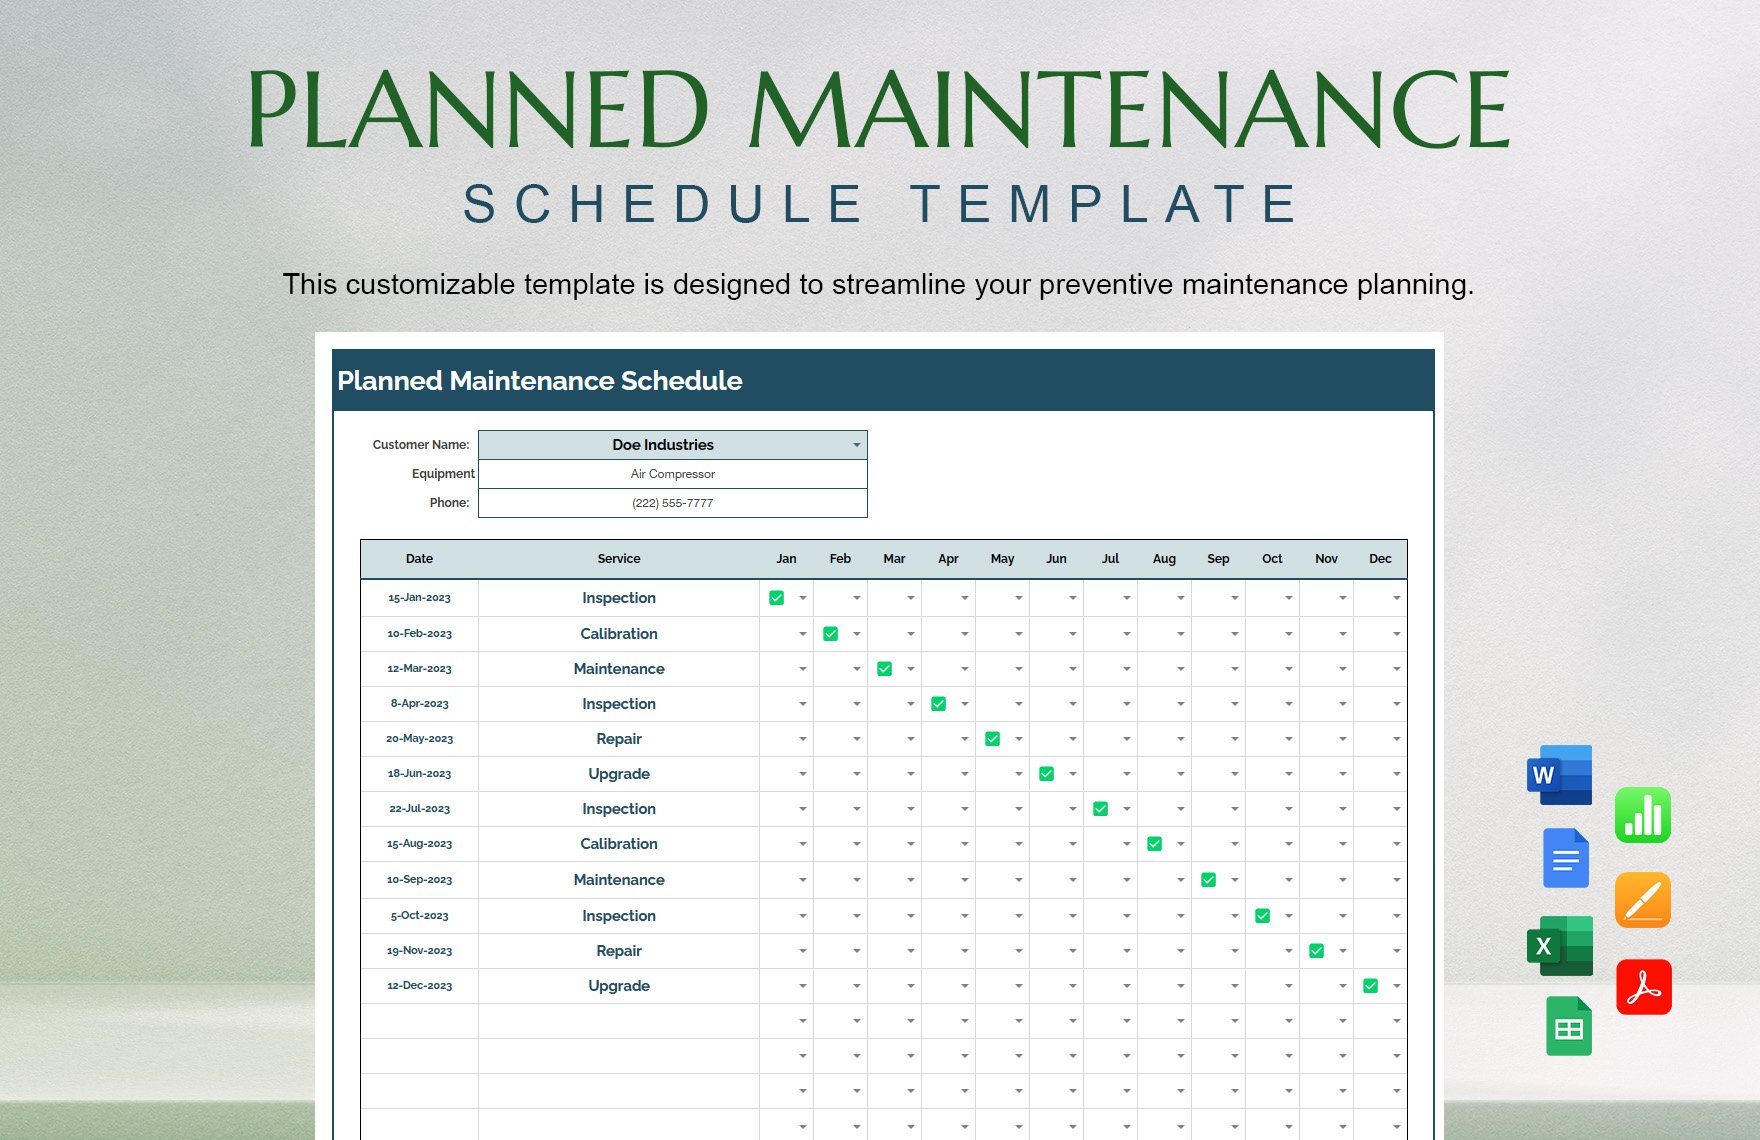
Most people build these schedules by copying someone else's template and slapping "quarterly" on everything. That approach produces documents that look complete and are immediately obsolete. I spent three years trying to get a multi-site studio operation to keep their synthesizer documentation honest, and the thing that changed everything wasn't better formatting. It was tying every maintenance task to a specific trigger event instead of a calendar date.Synthesizer Policy Manual Maintenance Schedule
A maintenance schedule for a synthesizer policy manual isn't just a spreadsheet. It is the living document that tracks when calibration happens, when firmware versions change, when parts are replaced, and when policy exceptions are logged. The manual itself is the single source of truth for anyone in your organization who needs to know what state your synthesizer fleet is in, what configuration is approved, and what hasn't been touched since the last review. Get that wrong and you end up with six months of undocumented firmware drift across twelve instruments. Here is how I built one that survived actual use instead of becoming another file nobody opens.
The framework
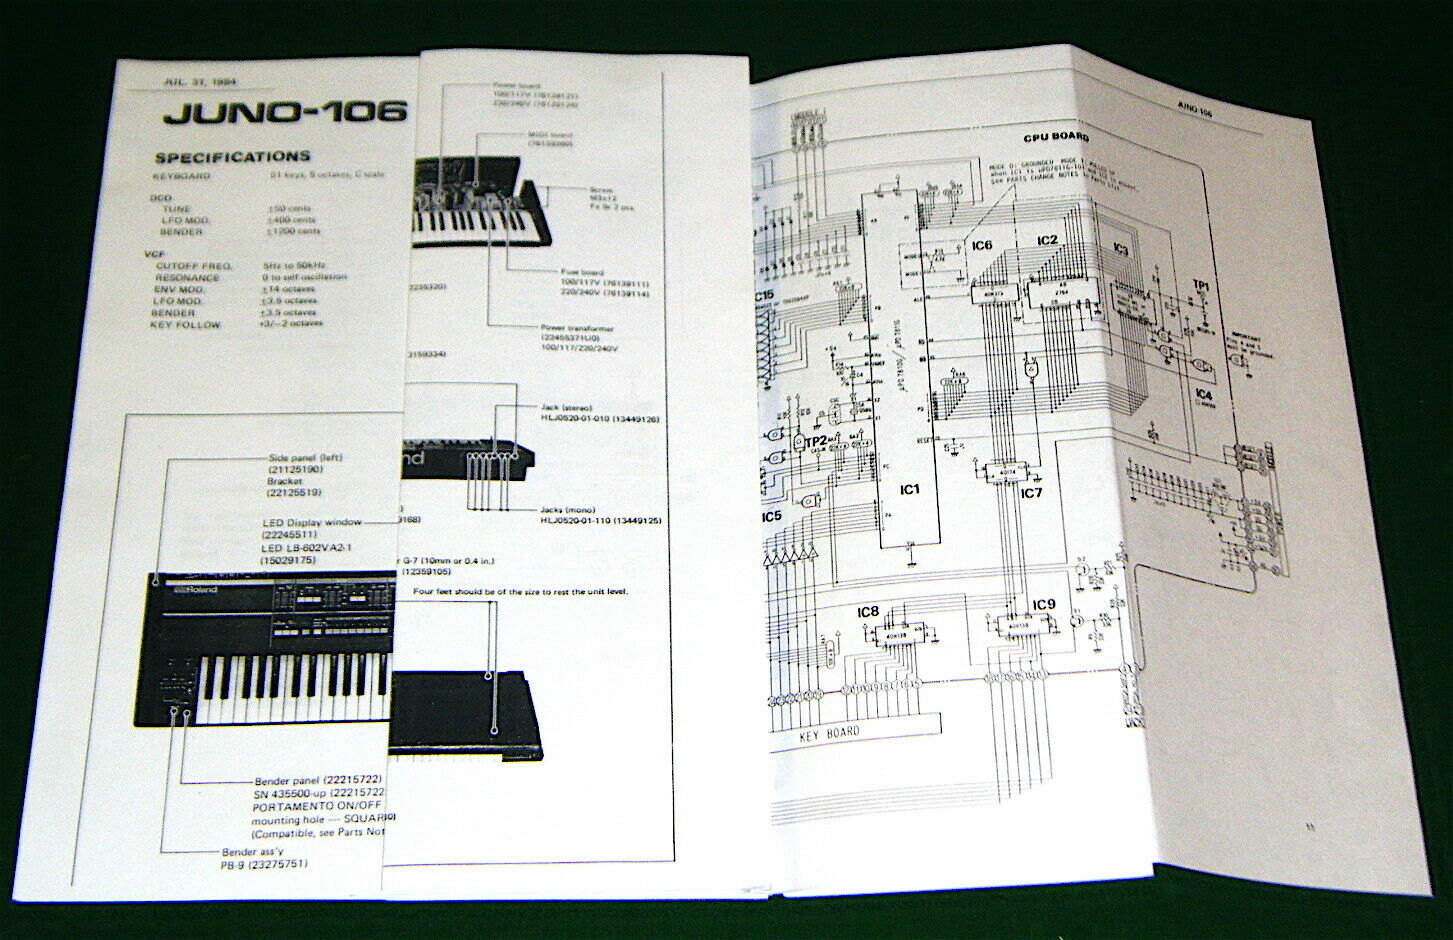
Every entry in the schedule needs four fields at minimum: the instrument identifier, the maintenance type, the trigger condition, and the responsible party. That is it. Adding columns like "priority" or "cost estimate" sounds organized but they create work that never gets done. The trigger condition is what matters most. You want either a time-based trigger, a usage-based trigger, or an event-based trigger. Time-based means the calendar date. Usage-based means after a set number of performance hours or power cycles. Event-based means something actually happened, like a component failure, a firmware update release, or a policy change at the organizational level. I recommend weighting your schedule toward event-based triggers. They are the hardest to track because they require a habit of recording events as they happen, but they catch things that time-based schedules miss entirely. A voltage regulator failing on a Juno-106 doesn't care about your quarterly review date.
Practical implementation steps
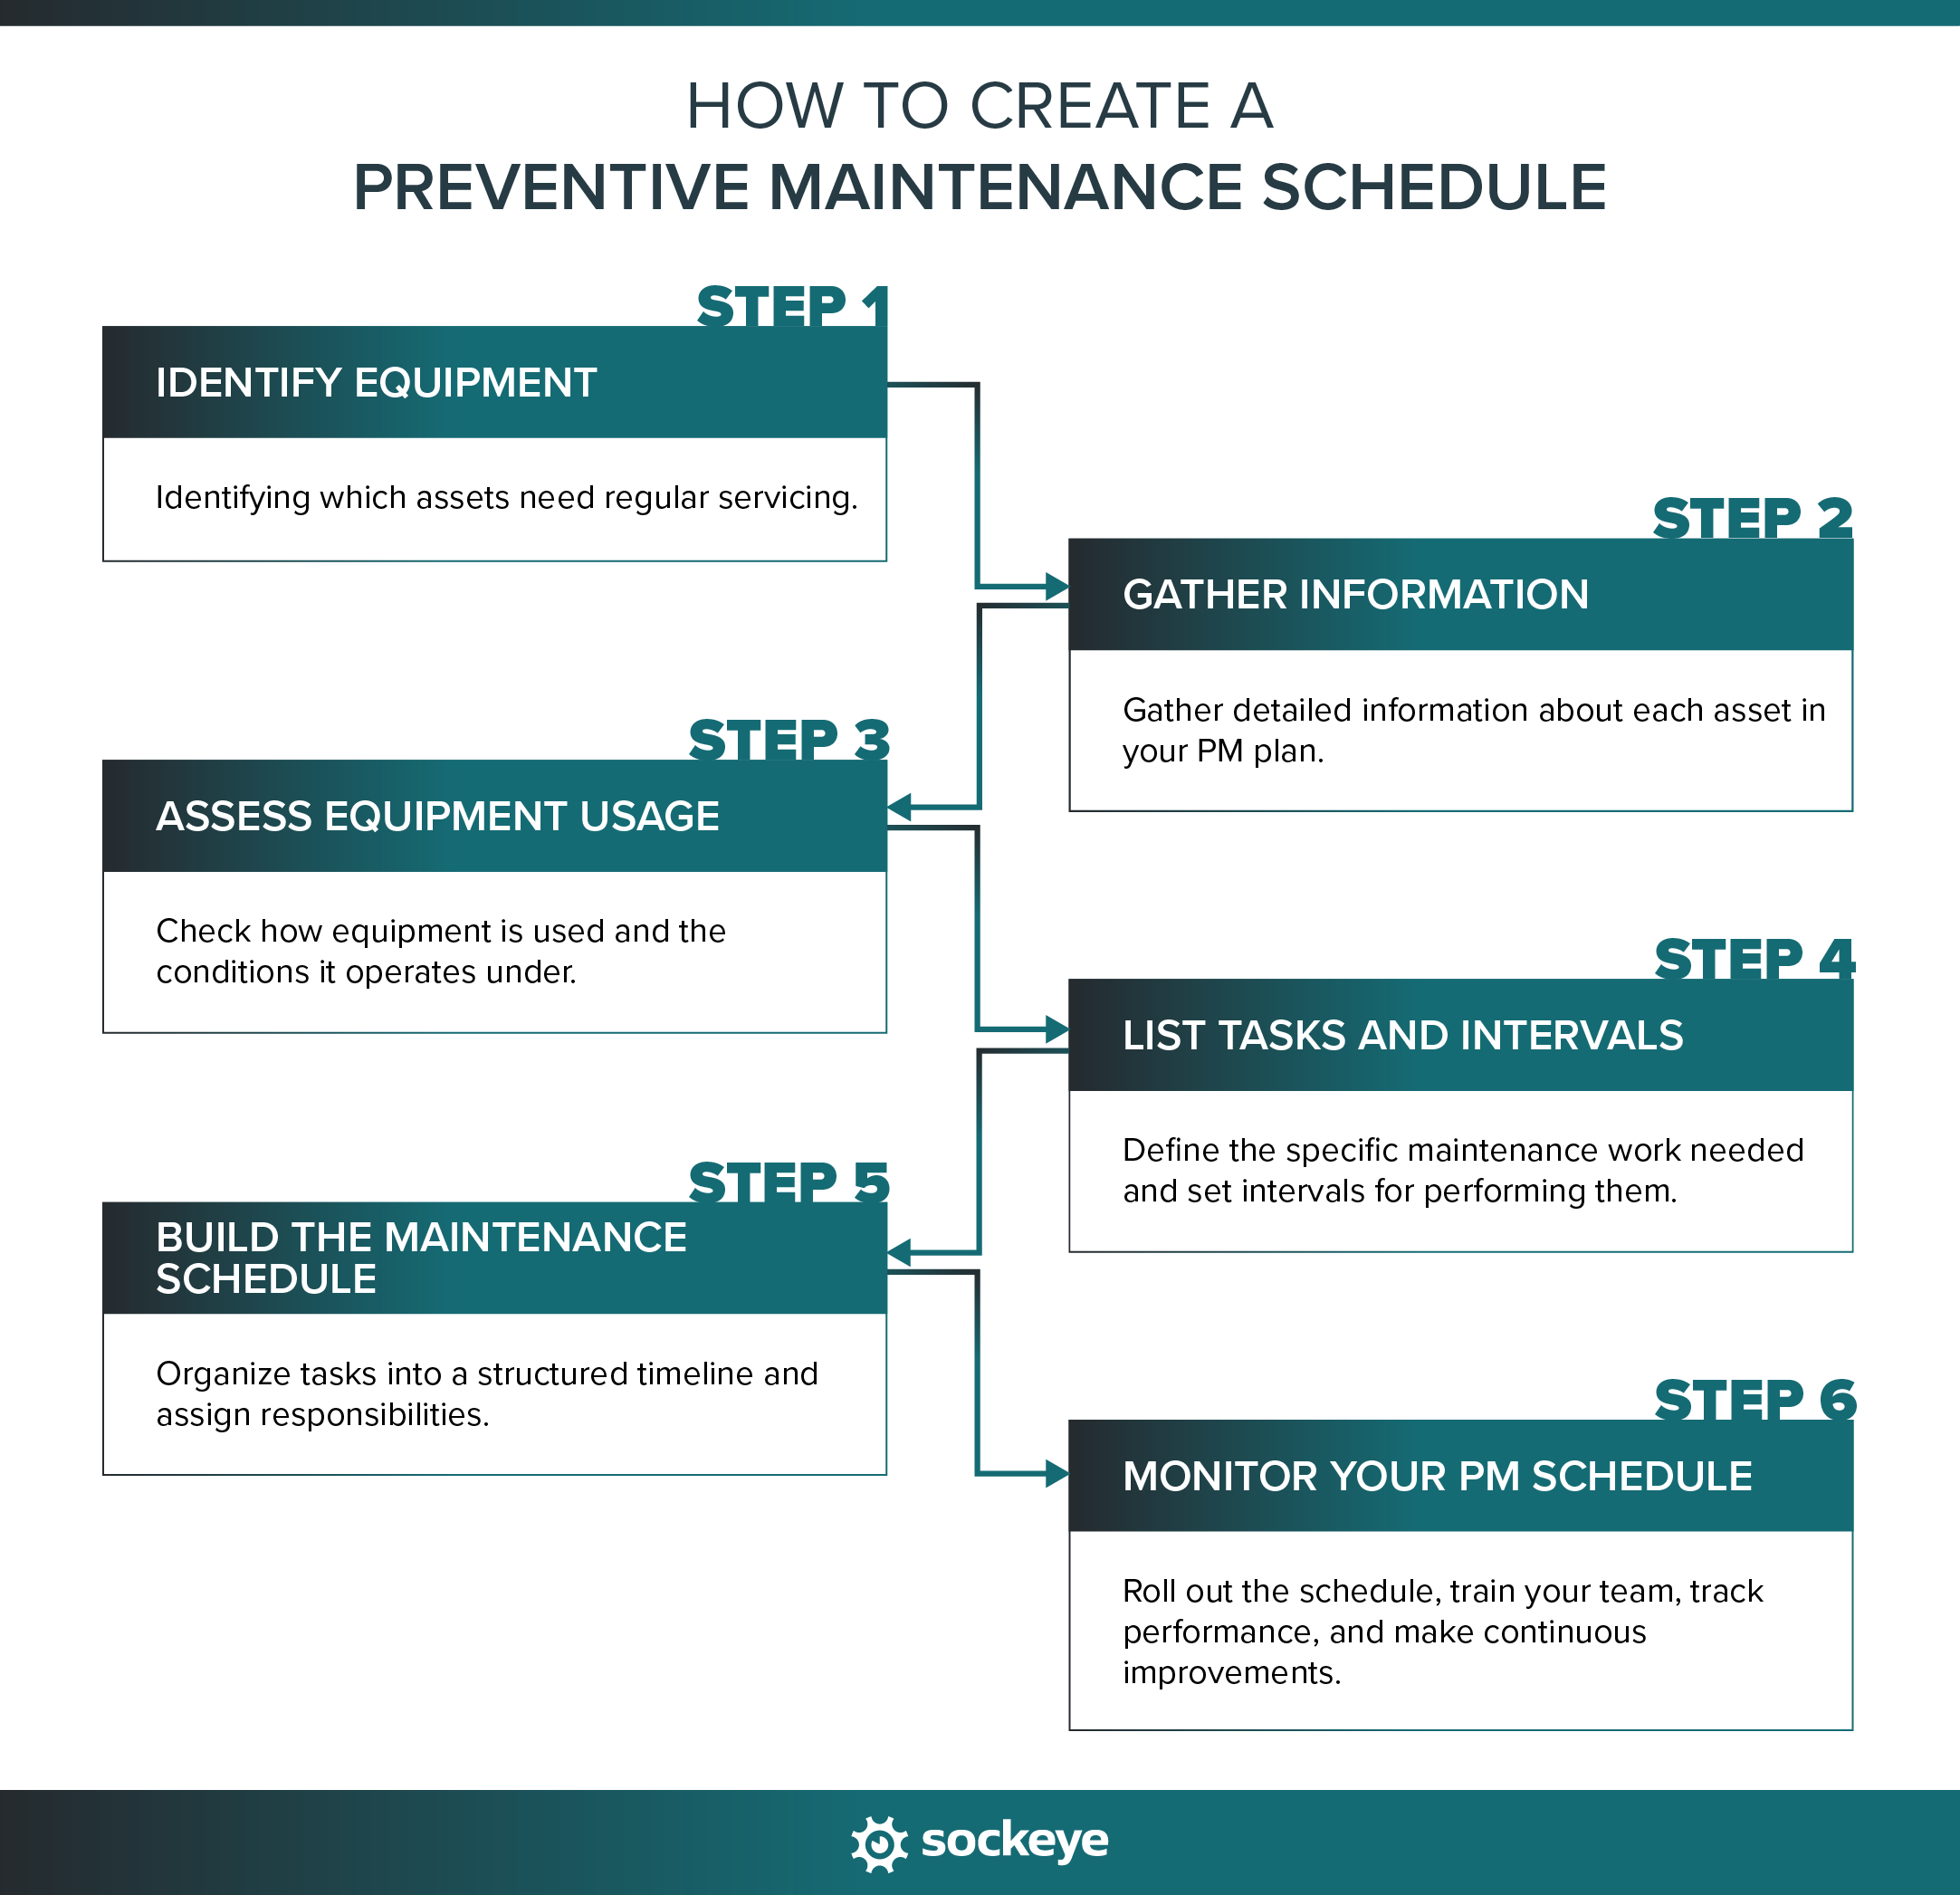
Start by inventorying every synthesizer you have. Write down the make, model, serial number, and current firmware version. If you do not already have a unique identifier for each unit, create one now. Something like SYN-001, SYN-002. The convention does not matter as long as every form, every repair ticket, and every policy document references the same ID. Next, define your maintenance categories. At minimum you need calibration, firmware updates, physical inspection, and policy exception logging. Calibration covers pitch drift checks, oscilloscope verification on analog circuits, and digital system clock alignment. Firmware updates are for any instrument running user-upgradeable code. Physical inspection covers connector wear, knob resistance, power supply condition, and mechanical switch integrity. Policy exception logging is where most organizations fail. It is the record of every instrument that deviates from the standard configuration and the justification for that deviation. After that, assign triggers to each category. I use these as defaults:
Get the Full Details
- Calibration: every 180 days or after any service event, whichever comes first.
- Firmware updates: within 14 days of a manufacturer release, or immediately if the release notes mention a security patch.
- Physical inspection: every 90 days, or after any transport event over 50 kilometers.
- Policy exception log: within 24 hours of the exception occurring.
Those intervals are starting points. Adjust them based on your actual usage patterns. A touring rig needs tighter loops than a studio-only setup. I learned that the hard way when a mobile performance unit went three firmware revisions behind because our schedule assumed static deployment. The workaround was switching to event-based firmware tracking for any unit that left the building more than twice a month. There was a particular incident that made me redesign the entire exception logging process. We had a modular system running a custom CV routing patch that we never documented because it was "temporary." Three months later, the original patch author left the facility, the patch stopped working, and nobody could reproduce it because there was no policy manual entry. The workaround I put in place was a mandatory patch snapshot field. Before any non-standard patch is connected and tested, someone has to take a photo of the patchbay routing, note the cable types, and attach that image to the instrument's policy record. It adds about four minutes per patch session. It saved us from a complete rebuild after the departure incident. This also exposed a deeper problem with how maintenance schedules handle modular systems versus semi-modular and fixed-architecture instruments. Modular patches introduce combinatorial complexity that breaks standard checklists. You cannot put a predefined list of items on a form and expect it to cover every valid configuration. I ended up splitting the maintenance schedule into two tracks: one for fixed-path instruments and one for modular systems. The modular track uses a different maintenance protocol entirely, centered on connectivity verification and patch stability rather than component-level inspection.
Common pitfalls and what to avoid
The biggest mistake is making the schedule too detailed. A maintenance schedule that requires twenty data fields per entry will not be maintained past the first week. People will fill in the first three fields and then skip the rest. Keep it tight. The four fields I listed above plus the maintenance notes column is usually sufficient. Notes should capture what was done, not a creative writing exercise about why it was done. Another trap is assuming that scheduled maintenance replaces ad hoc troubleshooting. A 90-day physical inspection will not catch a potentiometer that started drifting after day twelve. The schedule and the troubleshooting process are separate documents. Link them by requiring that any ad hoc repair gets logged back into the maintenance schedule within 48 hours. That way the next scheduled review starts from the correct baseline. There is also a blind spot around secondhand and borrowed equipment. I have seen teams add a new instrument to the schedule without verifying its current maintenance history. The result is an instrument that shows as "last calibrated 6 months ago" on paper while the actual calibration was last performed two years ago by the previous owner. Always do a full baseline calibration and inspection before entering any used instrument into the schedule, regardless of what the seller claims.
Tools that actually help
You can run this in a spreadsheet if you keep the scope small. Five instruments or fewer, a single location, no exceptions. Beyond that, spreadsheets become painful because they do not handle relationships well. An instrument with multiple firmware versions across modules, multiple patch configurations, and multiple policy exceptions will turn your sheet into a hostage situation within a month. I ended up using a simple relational database with three tables: instruments, maintenance_events, and policy_exceptions. The only query that matters is "show me all events for instrument ID within the last 30 days." If your setup exceeds what you can manage in Airtable or a similar low-code platform, stop and get a real database. The migration pain is shorter than the ongoing pain of spreadsheet maintenance. For firmware tracking specifically, there is a subtle issue with manufacturer release notes. Companies like Roland, Moog, and Native Instruments often bundle multiple changes into a single version number. You need a policy that requires reading the full changelog, not just the version bump. I instituted a rule where any firmware update that changes a DSP parameter count or adds a new CV input mapping gets flagged as a policy-relevant change regardless of how minor the release notes sound. Firmware that changes routing behavior without changing the version string is the specific failure mode that breaks most schedules.
When this approach fails
The event-based trigger system I described requires consistent human compliance. If someone skips the patch snapshot or fails to log an exception within the 24-hour window, the entire schedule loses accuracy. This is not a theoretical risk. In my experience, compliance drops fastest during touring cycles and session-heavy weeks. The workaround is to make logging frictionless. A mobile-friendly form that accepts a photo attachment and a three-field text input takes less time than writing a proper report. If your logging process requires opening a desktop application and filling out more than five fields, you will lose people during busy periods. Also, this system assumes you have authority over the instruments in your fleet. If you share equipment with other departments or external collaborators, you cannot enforce maintenance compliance. In that scenario, the schedule still serves as a reference, but you need a separate accountability process. A signed equipment check-out form that references the maintenance schedule is the standard solution. It shifts the burden from enforcement to acknowledgment.
Downloading a working template
The Synthesizer Policy Manual Maintenance Schedule template I settled on after all of the above has exactly these components: You can find a clean CSV version of this template in the shared resources folder on the studio network. The format is plain enough to import into any database or spreadsheet tool. The column names match the fields listed above exactly. There is no hidden complexity or vendor lock-in. If you start with this and add columns later, you are probably overcomplicating it again. The schedule itself is a tool for maintaining accountability, not a performance artifact. The best maintenance schedule is the one that gets updated without anyone thinking about it. That means the workflow has to be faster than the alternative of ignoring the instrument and hoping nothing breaks before the next review. Every field you add, every form you create, and every process you require costs real time. Add it only if it prevents a specific failure mode. Everything else is noise.