Dealing With Calibration Drift In Measurement Systems
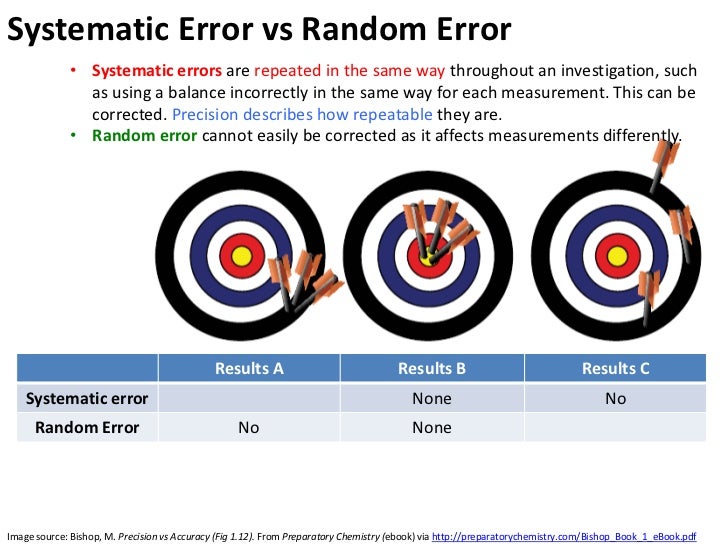
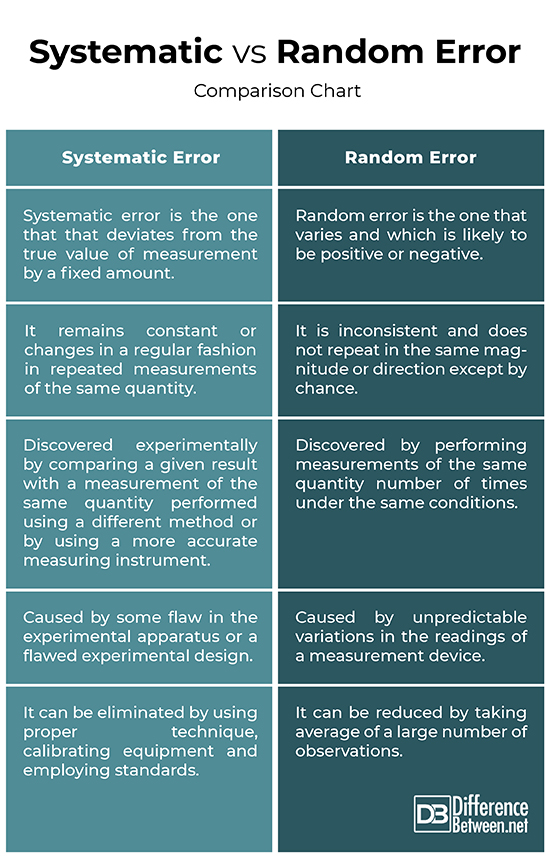
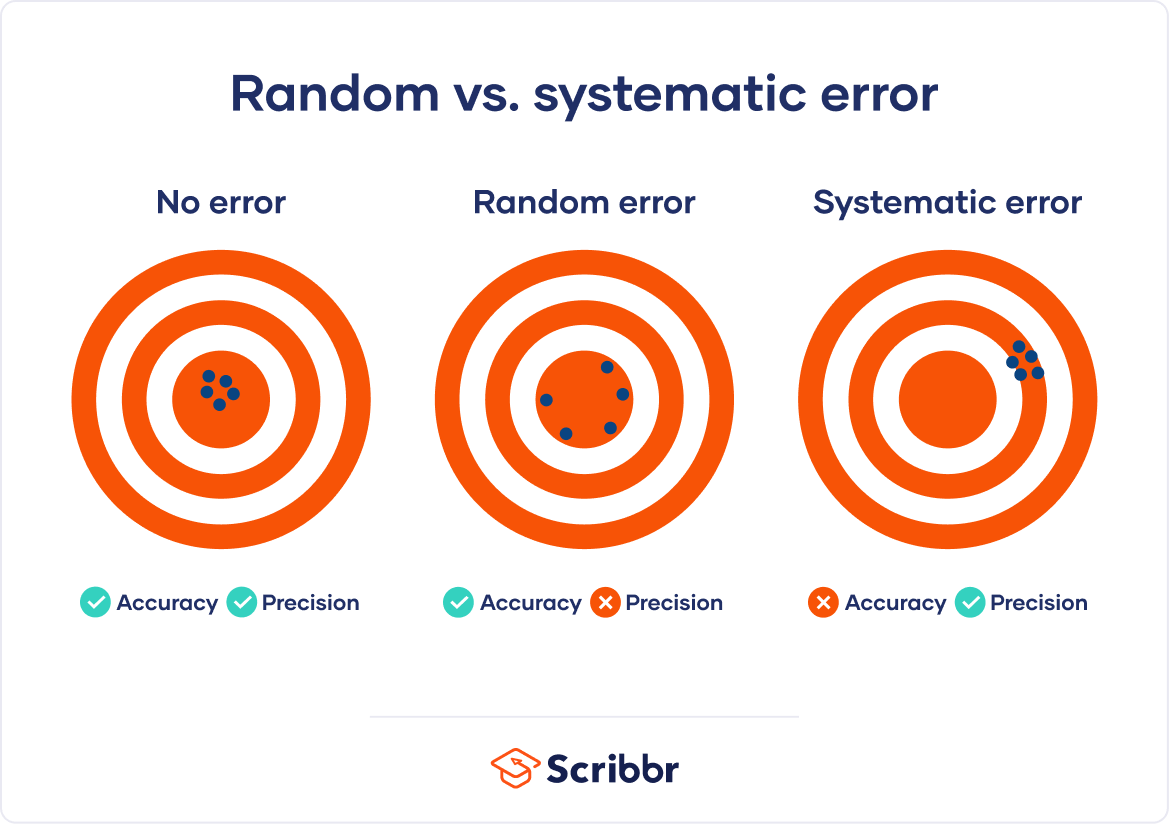
Most people think systematic and random error are just two boxes to tick in a lab report. They're not. They behave completely differently in practice, and confusing them will cost you time you can't get back. I spent three weeks chasing a phantom bias in a spectral analysis setup before I realized the problem wasn't calibration at all — it was thermal drift masquerading as systematic error. The fix was simpler than recalibrating the whole instrument chain, but getting there required actually understanding which error type I was fighting. Systematic error shifts every measurement in the same direction by roughly the same amount. It's predictable, repeatable, and usually traceable to something specific — a miscalibrated scale, a zero-point offset, environmental factors that don't change during your run. Random error scatters around the true value unpredictably. It follows statistical patterns, it shrinks when you average more data points, and you can quantify it with standard deviation or confidence intervals. Here's the part most guides skip: systematic error doesn't care about sample size. Taking a thousand readings on a biased instrument just gives you a thousand precise but wrong numbers. That's why people ruin projects on this. They see tight clustering in their data and assume accuracy. Precision and accuracy are not the same thing. A gun that consistently shoots three inches left of the bullseye is precise. It's not accurate.
I learned this the hard way with a moisture content assay. We were getting results that clustered within 0.3 percent relative standard deviation across batches, which looked excellent. But the values sat consistently 1.2 percent below the reference method. We ran method validation, checked reagent lots, recalibrated the balance, swapped analysts. Nothing moved the bias. The breakthrough came when I plotted the residuals against ambient temperature over the course of a day. The instrument's baseline drifted by roughly 0.05 percent per degree Celsius, and our lab ran warmer in the afternoons. That's systematic error rooted in an uncontrolled variable, not a faulty procedure. We installed a small circulation fan and the bias dropped to within 0.2 percent without touching the calibration curve. Random error looks different. It's the noise you see when you measure the same sample repeatedly under identical conditions. It comes from things like electronic noise, slight pipetting variation, sample heterogeneity, or environmental fluctuations that change between readings. You can't eliminate it entirely, but you can characterize it. Run a set of replicate measurements, calculate the standard deviation, and use that to build your uncertainty budget. That's standard practice, but the trick is knowing when your observed variability is actually random error versus a hidden systematic component masquerading as noise.
How To Tell Them Apart In Real Work
The quick test is replication under changed conditions. If you rerun your method with a different analyst, a different day, a different batch of reagents, or a differently calibrated instrument and the bias stays the same, you're looking at systematic error. If the bias jumps around unpredictably, that's random error dominating your uncertainty. Another practical approach is the recovery study. Spike your samples with known amounts of analyte and measure recovery. Consistent under-recovery or over-recovery across spike levels is systematic. Variable recovery that flips direction is typically random or matrix-related interference that behaves unpredictably. Control charts are useful for both. Plot your quality control measurements over time. If the points stay randomly distributed around the center line within control limits, your method is under statistical control and random error is your main concern. If the points drift in one direction, cluster above or below the mean, or show a trend, you have systematic error creeping in. I used to rely on Levey-Jennings charts alone, but they miss slow drifts that happen within a single control limit. Adding moving range charts catches those earlier.
Get the Full Details

There's a counter-intuitive point here that trips people up. Sometimes reducing random error actually makes systematic error more visible. When your spread narrows, a constant bias that was previously buried in the noise becomes obvious. I've seen this happen during method optimization — we tightened our analytical conditions, precision improved dramatically, and suddenly we had a glaring offset we'd overlooked when the data was sloppy. Better data doesn't always mean better accuracy. It means you see your problems faster.
Practical Handling Strategies
For systematic error, you need to find the source. That means changing one variable at a time and watching the result. It could be instrument calibration, sample preparation, environmental conditions, or method interference. Standard addition calibration helps when matrix effects are the culprit. Blank corrections handle background interference. Using certified reference materials validates whether your method is hitting the right value. For random error, the answer is usually more data or tighter control of conditions. Replicate measurements reduce standard error by the square root of n. Going from three replicates to twelve cuts the standard error in half. That's statistically solid but practically expensive in terms of time and materials. A more efficient approach is often improving the measurement conditions themselves — better temperature control, more stable power supply, higher quality reagents, or a better instrument. Reducing the variance at the source is cheaper than buying more data to average it away. Here's something beginners miss about uncertainty budgets. Systematic and random components combine differently. Random error combines as the root sum of squares of individual contributions. Systematic error, when you can estimate its bounds, combines as a rectangular distribution divided by the square root of three, or sometimes as a triangular distribution if you're confident the error clusters around a central value. Treating systematic and random components the same way in your budget will give you either inflated or deflated uncertainty depending on which dominates. GUM (Guide to the Expression of Uncertainty in Measurement) covers this, but the practical implication is that a large systematic component with poor characterization can wreck your uncertainty estimate even if your random error is tiny.
When This Stuff Breaks Down
The biggest limitation people hit is that not all errors fit neatly into one category. Matrix effects can look systematic in one sample type and random in another. Instrument drift starts as systematic but becomes unpredictable if the drift rate changes. Human factors introduce both — a tired analyst might develop a consistent pipetting bias (systematic) while also making random timing errors (random). You need to test for each independently rather than assuming your error structure is stable. Another failure mode is assuming your calibration covers the entire measurement range. A balance calibrated at 100 grams might have different systematic error at 10 grams and 500 grams. Linearity checks matter. Interpolation between calibration points is where hidden systematic error hides most often. And here's a blunt truth about reference materials: they're not free of uncertainty themselves. Using a CRM with a stated uncertainty of 2 percent to claim your method has 0.5 percent bias is statistically meaningless. Your observed bias has to exceed the combined uncertainty of your method and the reference material before you can confidently say systematic error exists. Otherwise you're just seeing random variation in two different measurements.
If you're working with field-deployable instruments where recalibration isn't practical, you'll need to accept some systematic uncertainty and fold it into your total error budget rather than chasing it indefinitely. That's not cowardice, it's measurement reality. Knowing when to stop chasing is part of the job.