Getting Raw Data Out of Tableau Without Losing Your Mind
Data science workflows usually involve a messy sequence of data extraction, cleaning, and visualization. Tableau sits somewhere in the middle of that sequence, and most people treat it like a magic box that turns spreadsheets into dashboards. It doesn't work like that. The tool has real power for exploratory analysis and quick prototyping, but it also has very specific ways of handling data that will trip you up if you are coming from a Python or R background. I use Tableau as part of a data science pipeline rather than as a standalone visualization tool. That changes how I interact with it. Instead of just dragging columns onto a canvas, I think about data sources, extract transformations, calculated fields, and LOD expressions as actual programming constructs. The workflow is different from what the documentation describes. Here is how I actually approach it in practice. First I connect to the data source. This can be a direct database connection, a Tableau Extract (.tde or .hyper), a CSV file, or a web data connector. The choice between live connection and extract matters a lot. A live connection sends queries to the database every time you interact with a view. An extract pulls the data into Tableau's own columnar storage format, which makes most interactions much faster but requires you to refresh it manually or on a schedule. For large datasets, the extract approach is almost always better, and you should create the extract with Tableau Prep or by writing the Hyper API in Python.
After the connection is established, I define the data model. Tableau has a somewhat opinionated way of handling relationships versus joins. I prefer using relationships because Tableau implements them as logical layer joins rather than physical SQL-level joins. This means the underlying query gets generated at visualization time, which can sometimes produce unexpected results if you have multiple relationships that create ambiguous paths. I learned this the hard way with a dataset that had orders, customers, and products. When I added a relationship between customers and a secondary table for regional promotions, Tableau started duplicating rows in ways that broke my revenue calculations. The workaround was to convert that relationship into a physical join and handle the filtering in the filter shelf instead. I still end up mixing both approaches depending on the complexity of the schema. Calculated fields are where things get interesting. Tableau uses its own expression language, which is more Excel-like than anything you would find in Python. You write formulas directly in the calculated field dialog, and they can reference dimensions, measures, table calculations, and level of detail expressions. LOD expressions are particularly powerful but also the most confusing part of the tool for beginners. An LOD expression lets you compute a value at a different grain than your current view. For example, {FIXED [Customer ID] : SUM([Sales])} gives you total sales per customer regardless of what other dimensions are in the view. I use these constantly for creating ratios and normalizations that would take multiple subqueries in SQL. One thing people miss about Tableau for data science is that it supports Python and R integration directly. You can run Python scripts from within Tableau by going to the analyze menu and selecting Python. This lets you do things like train a simple model, generate a forecast, or compute statistics that Tableau does not natively support. I use this to generate Z-scores and basic clustering labels that I then bring back as new columns in the visualization. It is not a replacement for a proper data science environment, but it is useful when you want to quickly iterate on a visual without switching tools.
Another area that most tutorials skip over is Tableau's extraction and preparation pipeline. Tableau Prep is a separate product that allows you to build visual ETL flows before the data ever reaches the main Tableau interface. I typically use it to clean messy source files, aggregate daily transaction data into monthly summaries, and standardize column names. The output is then consumed by Tableau as a refined dataset. The two products integrate seamlessly because they share the same Hyper engine. There are significant limitations to be aware of. Tableau is not a substitute for a proper statistical computing environment. The built-in forecasting functions are basic linear models, not time series decomposition. There is no native support for machine learning model training beyond what you can call through Python or R scripts. Performance degrades sharply when you combine many calculated fields with high-cardinality dimensions. A dashboard with fifteen separate LOD expressions pulling from a multi-terabyte extract will be slow even on a professional license. You also need to understand how Tableau handles nulls and blanks, because they behave differently than you might expect from SQL. A null in a dimension will create its own group in a legend, while a blank string from a text field behaves completely differently depending on whether it came from a data source or a calculated field. The download and installation process is straightforward. Tableau offers a free trial version called Tableau Desktop which you can download from their website. There is also Tableau Public, which is free but requires that any workbooks you publish are publicly accessible on their platform. For actual data science work where privacy matters, the full Desktop license is necessary. The server version adds collaboration features, row-level security, and scheduling, but the core analytical capabilities are the same across all editions.
Get the Full Details
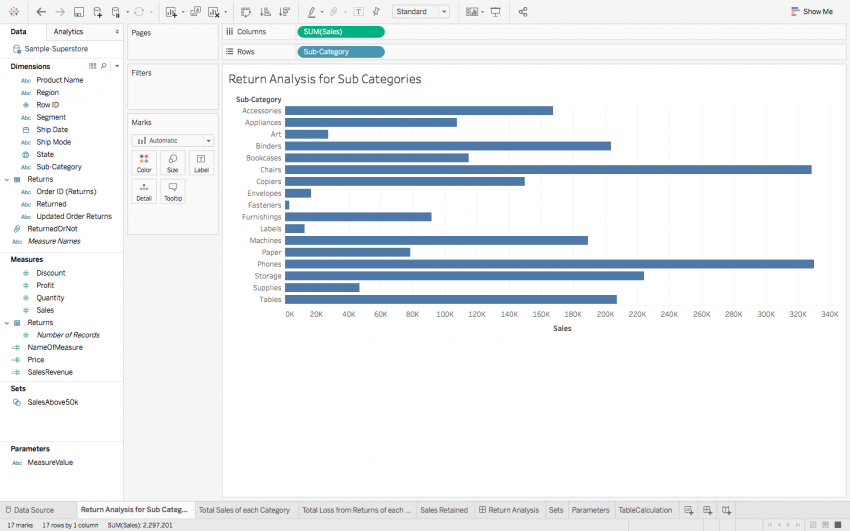
The most practical workflow I have found combines multiple tools rather than trying to force everything into Tableau alone. I start in Python or SQL to clean and transform the raw data. I bring the cleaned data into Tableau for exploration, pattern finding, and hypothesis generation. I use the LOD expressions and calculated fields to create summary metrics and normalized views. When I need more sophisticated statistical work, I go back to Python. The value of Tableau in a data science context is really about speed of iteration and visual thinking. It lets you test an idea in minutes instead of writing a notebook from scratch every time. Documentation and community resources are available through Tableau's official site, their forums, and various third-party tutorials. The Knowledge Base has detailed articles on performance tuning, extract optimization, and advanced calculation techniques. I rely on these heavily because the behavior of certain features like table calculations versus LOD expressions is not intuitive from reading the help pages alone. You tend to learn the edge cases only after you have encountered them in a real project. The tool has improved significantly over the past few years with better performance, more flexible publishing options, and deeper integration with cloud data platforms. But the fundamental approach remains the same: treat it as a visual query and analysis layer rather than a complete data science platform. If you understand where it fits in your pipeline, it is quite effective. If you expect it to replace your statistical computing environment, you will be frustrated fairly quickly.