How Talent Assessment Platforms Actually Work Under the Hood
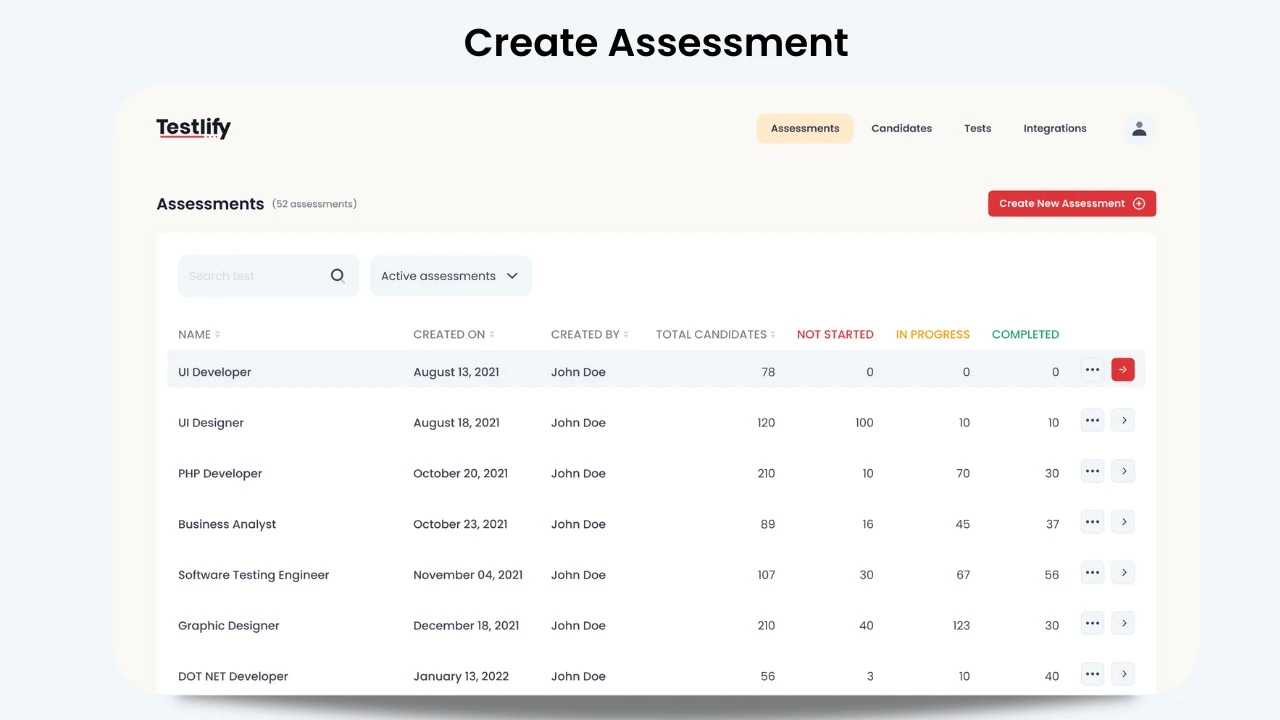
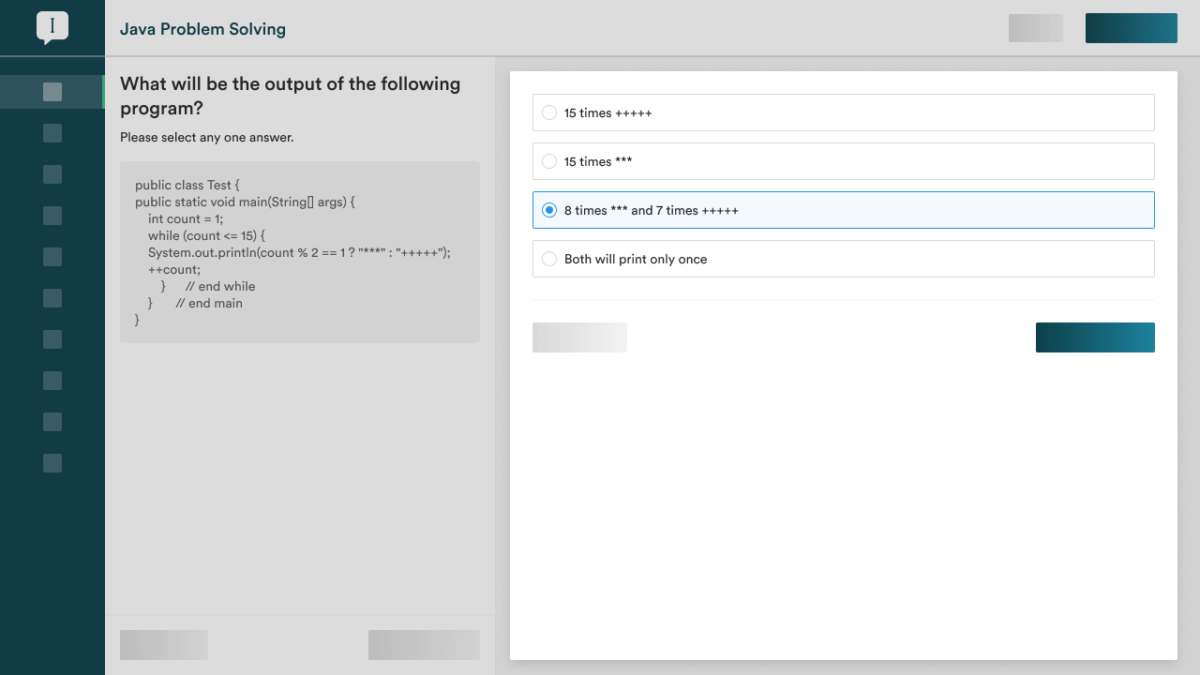
Most people think talent assessment platforms are just fancy questionnaires. They're not. A proper platform maps cognitive ability, behavioral fit, and role-specific skills against validated scoring models. The answer keys alone are more complicated than any quiz you'd find on a career site. Below is a practical breakdown of what these platforms do, how to set them up so they don't produce garbage data, and where they commonly fall apart in production environments. When I first started building assessments for technical hiring, I assumed "answers" meant you pick a correct option and move on. That assumption cost us about six months of rework. The short version is that platform answers are tied to a psychometric scoring engine, not a simple right-or-wrong key. Each question has a weighted answer, and the weight depends on the competency being measured, the seniority level of the role, and the candidate profile you're targeting. A junior developer taking a coding assessment gets scored differently than a senior architect taking the same assessment. The answer key doesn't change, but the interpretation of the answer does. I remember working with a team that tried to use an off-the-shelf assessment platform for a dual-track hiring process—engineers and product managers applying for the same pipeline. The platform defaulted to a single answer rubric. We ended up with product managers scoring impossibly low on spatial reasoning sections they were never supposed to take, and engineers scoring abnormally high on communication-based items we hadn't calibrated for. The workaround was setting up custom question routing. Instead of forcing both tracks through one assessment, I created two branching paths with different question subsets and different scoring weights. It took about three weeks to configure the routing logic, but after that the data quality improved dramatically. Candidates only saw questions relevant to their track, and the scores became meaningful again.
Setting Up the Assessment Structure Correctly
The biggest mistake I see is people building the assessment before they define the competency framework. You need to know what you're measuring before you write a single question. Start by mapping the role to three to five competencies. Don't go higher than five or you dilute the signal. For a mid-level data scientist role, I'd typically pick logical reasoning, statistical literacy, SQL proficiency, communication, and cross-functional collaboration. Anything beyond that turns your assessment into a guessing game. Once you have the competencies, match question types to each one. Logical reasoning gets puzzle-style questions. SQL proficiency gets hands-on coding exercises with actual database environments. Communication gets scenario-based prompts where the candidate writes a short response. Behavioral fit gets situational judgment questions with scored multiple-choice answers. Each type needs a different validation approach. Coding exercises need automated test suites. Scenario responses need human reviewers with a rubric. Situational judgment needs norm-referenced scoring against a benchmark population.
Calibration and Validation That Most Teams Skip
Calibration is where most implementations fail. I once worked with a company that launched an assessment with zero calibration data. They used published norm scores from the vendor's website. The problem was those norms were based on a global sample, and their hiring pool was entirely within a specific region with a different education background. The result was systematic bias against candidates from non-traditional educational backgrounds. We caught it when we noticed that candidates from certain universities were consistently scoring in the bottom quartile regardless of their actual performance on practical tasks. The fix was building our own calibration cohort. We administered the assessment to ten people already in the role across different seniority levels. Their scores became our internal benchmark. If the median score for current senior engineers was 78 percent, anything below 60 percent flagged as a potential misfit regardless of what the vendor's global norms said. This usually takes four to six weeks to set up properly. It sounds like a lot of time, but it prevents you from making bad hiring calls based on inflated or deflated scores.
Get the Full Details
Common Pitfalls and How to Avoid Them
Time pressure is a legitimate concern in live assessments, but most platforms don't account for variables like slow internet connections or candidates using unfamiliar interfaces. I had a candidate whose score dropped because her internet throttled during the timed coding section. She completed every question correctly but ran out of time on three problems. The platform recorded incomplete answers and gave her a low score. The workaround was adding a review window after submission where candidates could revisit flagged questions. This didn't change the timed nature of the exercise, but it accounted for technical hiccups without inflating scores artificially. Another pitfall is over-indexing on one competency type. I've seen platforms heavily weighted toward cognitive reasoning while ignoring practical skills. A candidate might score in the 95th percentile on logical reasoning but fail to write clean SQL or explain a technical decision clearly. The answer key captures the reasoning score perfectly, but the hiring outcome doesn't reflect reality. The solution is multi-dimensional scoring where no single dimension can override the others. If a candidate scores poorly on the practical component, the high reasoning score should not compensate enough to pass the threshold. Set clear minimums for each dimension rather than a single aggregate score. There's also the issue of answer pattern recognition. Some platforms can detect when a candidate is pattern-matching answers instead of reasoning through them. This happens frequently with timed assessments where candidates speed through without reading carefully. The detection algorithms flag inconsistent response patterns and mark those responses as unreliable. This is useful, but it has a false positive rate of around 8 to 12 percent. I recommend manually reviewing flagged assessments rather than automatically disqualifying candidates based on pattern detection alone.
Scoring Interpretation and Report Generation
Raw scores mean almost nothing without context. A score of 82 on one platform's logical reasoning section is not comparable to a score of 82 on another. Always look at the percentile ranking and the confidence interval, not just the raw number. Most good platforms provide both. If the confidence interval is wide—say, plus or minus 10 points—the score is not reliable enough to make a hiring decision on its own. Use it as one data point among others, not as a definitive gate. Report generation should include a breakdown by competency, not just an overall score. Hiring managers need to see that a candidate struggled specifically on SQL but excelled on statistical reasoning. That kind of detail determines whether someone is a fit for your particular team composition. I've seen managers reject strong candidates because the overall score was average, missing the fact that the candidate's specific strengths aligned perfectly with the team's gaps. The answer platform can provide this if you configure the report template correctly. Default templates from vendors are often too generic to be useful. One limitation worth noting is that these platforms cannot assess cultural add. They can measure cultural fit to some degree, but fit is the wrong metric. Fit means someone blends into the existing culture. Add means someone improves the culture by bringing a missing perspective. No multiple-choice question captures that. If your hiring process relies solely on platform scores, you'll systematically hire people who are similar to your current team. Use the assessment as a screening tool, not a final decision maker. Combine it with structured interviews, work sample reviews, and team panels to get a complete picture.
The technology keeps improving, and the platforms are getting better at reducing bias and improving accuracy. But they still require deliberate configuration and ongoing calibration. A platform that works well today will drift over time as your hiring needs change. Plan for regular reassessment of your question sets and scoring models, ideally every six to twelve months, to keep the data relevant to what you actually need in the role.