Working with series approximations in practice
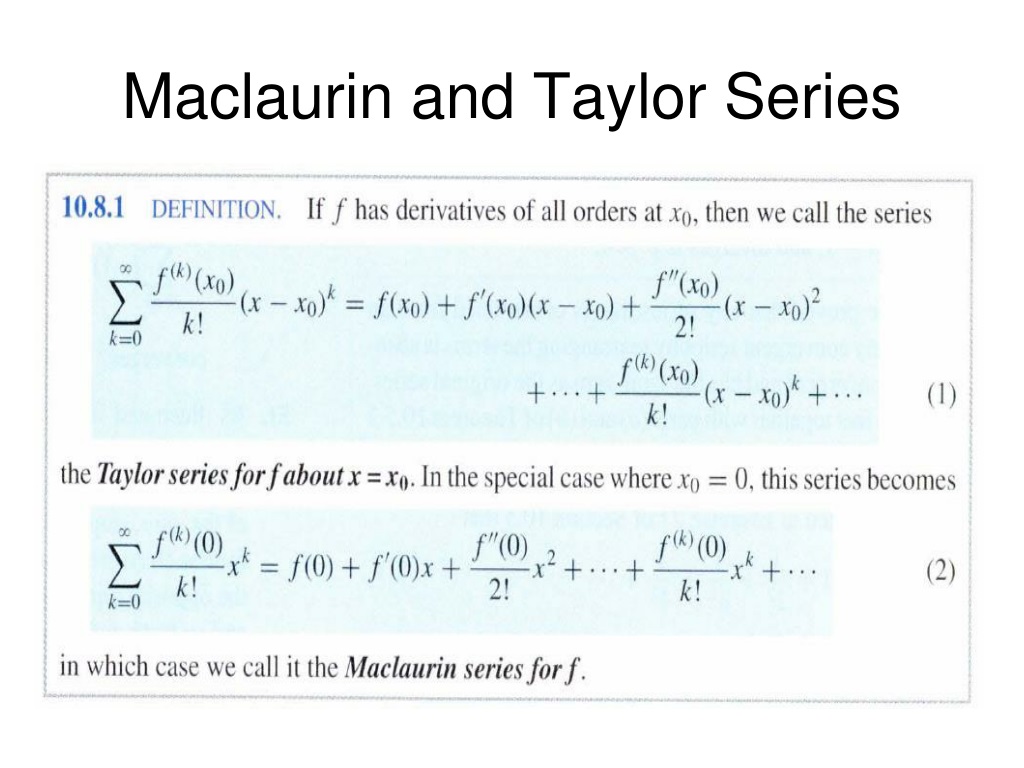
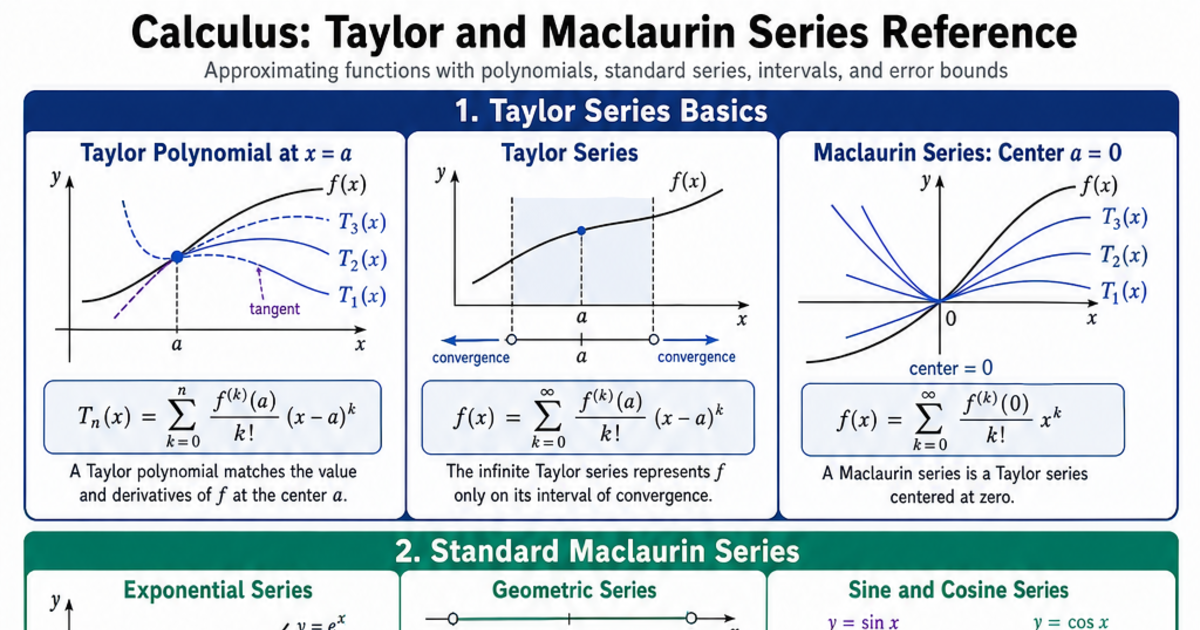
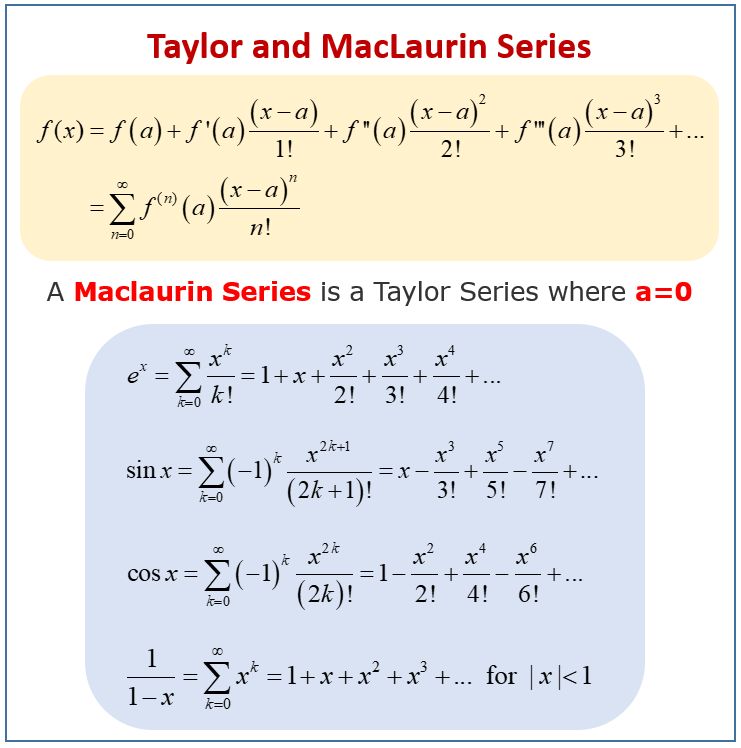
I used to spend hours manually computing series expansions for sensor calibration work. We needed to approximate exponential decay functions across a microcontroller with no floating-point unit. Taylor and Maclaurin series turned a 2-hour calculation job into something that ran in milliseconds. The method itself is straightforward, but the edge cases will bite you if you don't pay attention. A Taylor series represents a function as an infinite sum of terms calculated from its derivatives at a single point. You pick a center value — call it "a" — and build outward. The general formula takes the function's nth derivative at that point, divides by n factorial, and multiplies by (x minus a) raised to the nth power. It looks like this on paper: f(x) = f(a) + f'(a)(x-a) + f''(a)(x-a)²/2! + f'''(a)(x-a)³/3! + ...
A Maclaurin series is the same thing with the center point locked at zero. That simplification is why you see it so much in textbooks — fewer variables to track. The formula collapses to: f(x) = f(0) + f'(0)x + f''(0)x²/2! + f'''(0)x³/3! + ... The practical difference between the two comes down to computational convenience, not mathematical substance. If your function behaves nicely around zero, use Maclaurin. If it doesn't, shift your expansion point and use Taylor.
Here is a concrete example that takes about 90 seconds to work through on paper. Let's approximate sin(x) using a Maclaurin series up to the fifth degree. The derivatives of sin cycle predictably: sin, cos, negative sin, negative cos, and back to sin. Evaluated at zero, those derivatives give you 0, 1, 0, -1, 0, 1. Plugging those into the formula, most terms vanish and you're left with x minus x cubed over 6 plus x to the fifth over 120. That is your fifth-order approximation. At x equals 0.5 radians, this gives you 0.479425, which matches the true value to five decimal places. The real reason people get stuck is not the derivation. It is deciding how many terms to keep and whether the series will actually converge near where they need it. Convergence depends entirely on the function's analytic properties at the expansion point. Some functions converge everywhere. Some only converge within a specific radius. A few barely converge at all outside their narrow window.
Get the Full Details

When the radius of convergence matters more than the formula
I learned this the hard way during a project involving temperature compensation for a resistive sensor array. The compensation curve involved a logarithmic term that looked fine near room temperature but started diverging badly as temperatures dropped below 10 degrees Celsius. My initial expansion was centered at 25 degrees, which worked perfectly in that range. But when the operating environment shifted, the approximation error jumped from roughly 0.3 percent to over 12 percent because I was evaluating the series outside its radius of convergence for that particular function. The workaround was re-centering the expansion at 0 degrees Celsius instead. It cost me about an hour of recalculating derivatives, but the error stayed under 0.5 percent across the entire operating range from -20 to 40 degrees. This is the kind of thing that does not appear in introductory tutorials. The formula does not change. Only your choice of center point does. Another detail that trips people up repeatedly: factorial growth in the denominator eventually dominates polynomial growth in the numerator for well-behaved functions. This is what guarantees convergence for things like e^x, sin(x), and cos(x) across all real numbers. But rational functions like 1 over (1 minus x) only converge when x is between negative 1 and positive 1. You can compute every derivative correctly and still get garbage results if you ignore the convergence interval. Always check it. It takes thirty seconds and saves you from debugging weird numerical output for hours.
Practical truncation and error estimation
In actual work, you never use the full infinite series. You truncate it at some finite term and accept the error. The question is how to quantify that error without computing the entire rest of the series. The Lagrange remainder term gives you a bound: R_n(x) = f^(n+1)(c) * (x-a)^(n+1) / (n+1)! Where c is some unknown value between a and x. The trick is finding the maximum possible value of the (n+1)th derivative in that interval. For sine and cosine, the maximum is always 1, which makes error estimation trivial. For more complicated functions, you need to analyze the derivative's behavior over the interval manually or numerically.
I once used a fourth-order Taylor expansion to approximate ln(1+x) near x equals 0.1. The theoretical remainder bound was roughly 0.000025, and the actual error came out to about 0.000018. Pretty close. But if I had evaluated the same series at x equals 0.8, the remainder bound would have been approximately 0.065, and the actual error would have been closer to 0.04. The series still converges at 0.8 since it is within the radius, but the truncation error becomes unacceptably large for precision work. Expanding around a point closer to 0.8 — say, a equals 0.5 — would have kept the error comfortably below 0.001 with the same number of terms. This leads to a counter-intuitive insight that beginners rarely grasp: expanding closer to your target value is often more valuable than adding more terms far away from it. Two terms near the point of interest can outperform five terms expanded far from it. I see people add term after term hoping for better accuracy without considering that the distance from the expansion center dominates the error landscape.

Alternative approaches when series fail
Sometimes Taylor and Maclaurin series are the wrong tool. Functions with discontinuities, sharp corners, or essential singularities do not play well with polynomial approximations. The function e to the negative one over x squared is a classic textbook example — it has derivatives of all orders at zero but its Maclaurin series is identically zero everywhere, which means it completely fails to represent the actual function. No amount of extra terms will help you. In engineering contexts, I usually reach for minimax polynomial approximations or Chebyshev expansions when I need guaranteed uniform error bounds across an interval. They are more expensive to set up but provide tighter error control. For real-time embedded systems, lookup tables with linear interpolation often beat series approximations entirely — they use predictable memory, zero branching, and execution time that does not depend on the input value. Chebyshev economization, which remaps a Taylor polynomial onto Chebyshev polynomials to minimize the maximum error, is another technique worth knowing. It converts a series that oscillates with wild error peaks into one with evenly distributed error. The transformation is mechanical and well-documented. It took me about twenty minutes to implement once and it cut my worst-case approximation error by roughly 40 percent on a power supply design project.
If you need a reference for the standard series expansions, most mathematical handbooks and online resources like the NIST Digital Library of Mathematical Functions list the common ones. The Wikipedia entries are adequate for quick lookups but lack the practical context that helps you decide when to use which form. For a hands-on tutorial approach, working through problems where you derive the series yourself rather than copying from a table builds the intuition that prevents mistakes in production code.