Using Taylor Series for Quick Function Approximations
You take a function, compute its derivatives at a specific point, and build a polynomial that mimics the function near that point. That is the entire idea. The more terms you include, the closer the polynomial tracks the original curve. This works because polynomials are trivial to compute by hand or in code, while something like sin(x) or e^x requires more machinery unless you have a calculator nearby. The standard formula looks like this: f(x) = f(a) + f'(a)(x-a) + f''(a)(x-a)^2/2! + f'''(a)(x-a)^3/3! + ... and so on. You pick your center point a, evaluate the function and its derivatives there, plug them in, and truncate wherever you want. The choice of where to cut off determines your accuracy, and that is the tradeoff you manage throughout. I use this kind of approximation regularly in work that involves signal processing and numerical estimation. When you need to evaluate a transcendental function inside a tight loop without calling a library routine, a low-order Taylor polynomial is often fast enough and removes dependency on external math libraries. The downside is that you have to respect the region where the polynomial stays accurate. Step too far from your center point and the approximation falls apart completely.
Taylor Series Khan Academy
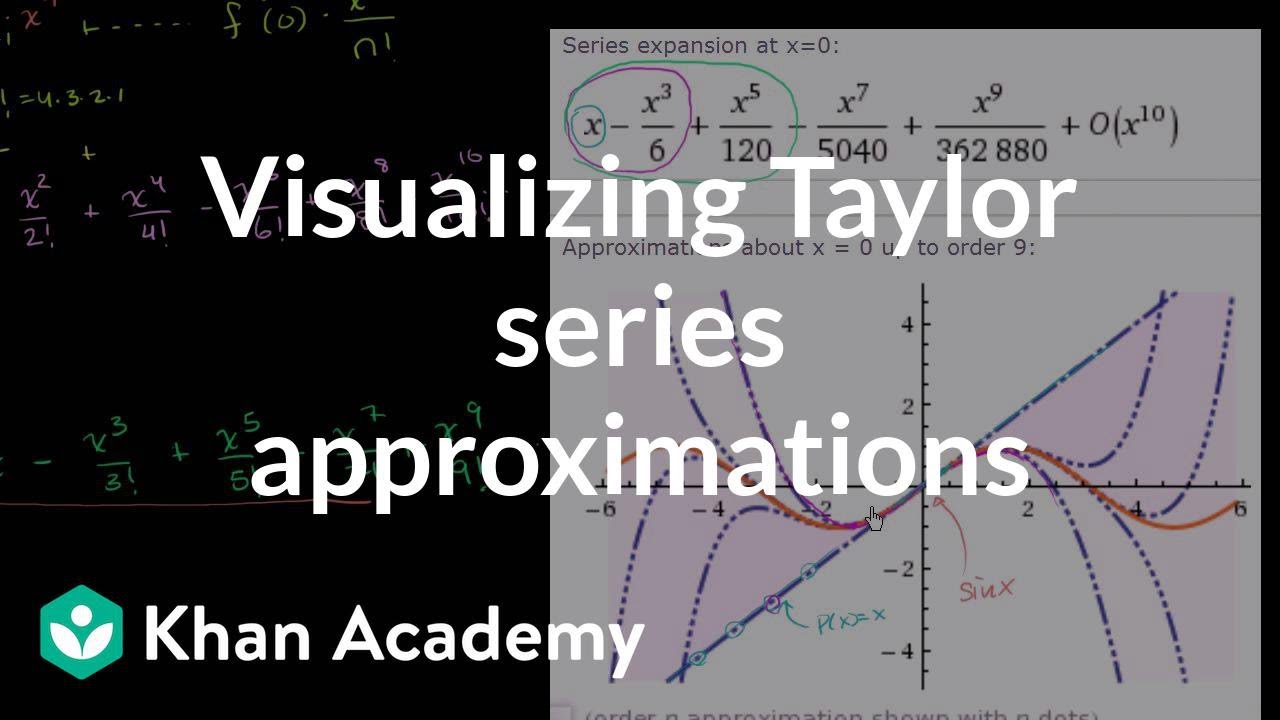
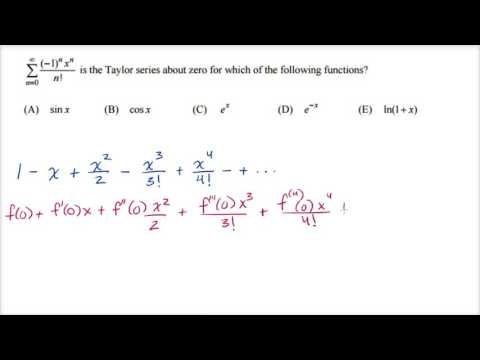
The Khan Academy section on this topic walks through the derivation from first principles. They start with the linear approximation, show how the second derivative adds curvature correction, and build up from there. The pacing is deliberate. Each video focuses on one concept instead of cramming everything together, which actually matters here because the notation gets messy fast. What works well is how they handle the factorial denominators and the pattern recognition. A lot of people trip over the (x-a)^n part because they forget whether the power matches the derivative order. The Khan Academy examples make the correspondence explicit, so you see that the nth term always pairs the nth derivative with (x-a)^n divided by n factorial. The practice problems reinforce that connection directly. I ran into a real snag recently when I was approximating ln(1+x) using the standard Maclaurin expansion. The series converges for -1 < x
= 1, but the convergence near x = -1 is extremely slow. I needed about 50 terms just to get three decimal places of accuracy at x = -0.9, which made the whole approach impractical for my use case. The workaround was switching to a Taylor expansion centered at a different point, specifically a = 0.5, which gave me reasonable accuracy with far fewer terms because I was closer to the region I cared about. Khan Academy covers the radius of convergence but does not spend enough time on this practical reality: the center point you choose changes how many terms you actually need in practice.
Where the Approximation Breaks Down
The biggest limitation people miss is that Taylor series only approximate locally. The polynomial may track your function perfectly at the center point, but as you move away, the error grows. For e^x centered at 0, the series converges everywhere, so this is less of a concern. For something like ln(x) centered at 1, you are stuck within the interval (0, 2]. Go outside that range and the series diverges entirely. Another practical issue is computational cost. Each additional term requires computing another derivative and another factorial. By the time you reach the fifth or sixth derivative of a composite function, manual calculation becomes tedious and error-prone. Even with software assistance, generating high-order expansions for arbitrary functions takes time. If you need accuracy beyond sixth or seventh order, you are usually better off using a minimax polynomial approximation or a rational approximation like a Padé approximant, which converges faster over a wider interval. The error bound is another thing Khan Academy mentions but does not emphasize enough. The Lagrange form of the remainder tells you the maximum error for a truncated series, but computing it requires knowing something about the (n+1)th derivative over the entire interval between your center point and your target x value. In practice, this is often hard to bound tightly without significant extra work. My rule of thumb is to compute two successive partial sums and compare them. If the difference between them is below your tolerance, you are probably fine. If not, add another term and check again.
Get the Full Details
Practical Steps for Building Your Own Expansion
Start by choosing your center point a. This should be close to the x values you care about evaluating. If you are approximating sin(x) near x = pi/4, center at pi/4, not at 0, unless you have a good reason to use the Maclaurin series. The further you are from the center, the more terms you need, and the less useful the approximation becomes. Compute the derivatives. For standard functions like sin, cos, and e^x, the derivatives follow predictable cycles. sin and cos rotate through four derivatives. e^x is its own derivative. For products or quotients, you will need the product rule and quotient rule repeatedly, which gets unwieldy past the third or fourth derivative. In those cases, consider whether a different approach makes more sense. Write out the first few terms. A first-order approximation uses just the function value and the first derivative. A second-order approximation adds the curvature term. For most engineering estimates, second or third order is sufficient if you stay close to the center point. Beyond that, you are usually better served by a numerical method designed for the specific function you are working with.
Check your error. Use the remainder term if you can bound it easily. Otherwise, compare successive partial sums. If the change from one term to the next is smaller than your acceptable error margin, stop adding terms. You do not need to prove the series converges; you just need to know that adding more terms will not meaningfully change your result. The Khan Academy videos cover all of this at a foundational level, and they are worth watching if you are encountering Taylor series for the first time. The explanations are clear, the examples are incremental, and the practice problems align with the concepts being taught. Where they fall short is in addressing the practical edge cases: slow convergence near interval boundaries, the tradeoff between computational effort and accuracy, and when to abandon Taylor expansion entirely in favor of other approximation methods. Those lessons tend to come from running into them yourself rather than from any single video or article. One thing worth noting is that Taylor series are not the only polynomial approximation technique available. If you need a uniform approximation over an interval rather than a local one near a point, Chebyshev approximation or minimax polynomials will give you better accuracy for the same number of terms. The math is more involved, but modern tools handle the computation, and the result is often significantly more efficient than a raw Taylor expansion.