Blocking sockets and select() loops
You write a server that listens on a port, accepts connections, reads from them, writes responses. That is the basic shape of Tcp Ip Sockets In C. The system call API has not changed meaningfully since the 1980s. On Linux and macOS it lives in sys/socket.h. On Windows it is winsock2.h and ws2tcpip.h. The function names are nearly identical across both. Here is the straight sequence you will use again and again: socket() to create a descriptor, bind() to attach it to an address, listen() to mark it as passive, accept() to pull a new client off the queue, then read() and write() for data transfer. Close() when you are done. Every tutorial shows this. The part nobody mentions until they hit it is what happens after accept().
Tcp Ip Sockets In C: where most tutorials fail you
I wrote a socket server once that accepted connections fine but hung after about thirty clients. The accept loop was running in a tight while(1) without any kind of multiplexing. Each client got its own thread. On Linux the default stack size is eight megabytes per thread. Thirty threads meant roughly two hundred and forty megabytes of virtual address space just sitting there, and the context-switching overhead started climbing fast. The process was not crashing. It was just slowly choking. The fix was straightforward. I switched to a single-threaded select() loop with a pollfd array tracking readability and writability on each descriptor. That cut the memory footprint down to something under five megabytes for the same number of clients and removed the thread scheduling noise entirely. It also meant I could handle thousands of connections before hitting file descriptor limits instead of forty or fifty. select() is not the only option. poll() removes the hard limit of FD_SETSIZE that select() imposes. epoll() on Linux scales much better past a few thousand descriptors because it does not require you to re-pass your entire fd set on every call. If you are writing something that needs to handle even moderate concurrency, start with epoll or a cross-platform wrapper like libevent rather than assuming select() will be sufficient.
The actual socket setup
The minimum server looks like this on POSIX systems: socket() returns an int fd. Pass AF_INET for IPv4, SOCK_STREAM for TCP, and 0 for the default protocol. If it returns -1, check errno. On Windows you must call WSAStartup() first or the socket functions will fail with WSAEINIT. setsockopt() with SO_REUSEADDR on the socket before calling bind() is critical. Without it, you will hit EADDRINUSE for up to two maximal segment lifetimes (typically 120 seconds on Linux) after the process exits if there were TIME_WAIT connections still holding the port. I have seen junior engineers waste half an hour debugging why their restarted server could not bind to the same port when adding SO_REUSEADDR would have prevented the issue entirely.
Get the Full Details

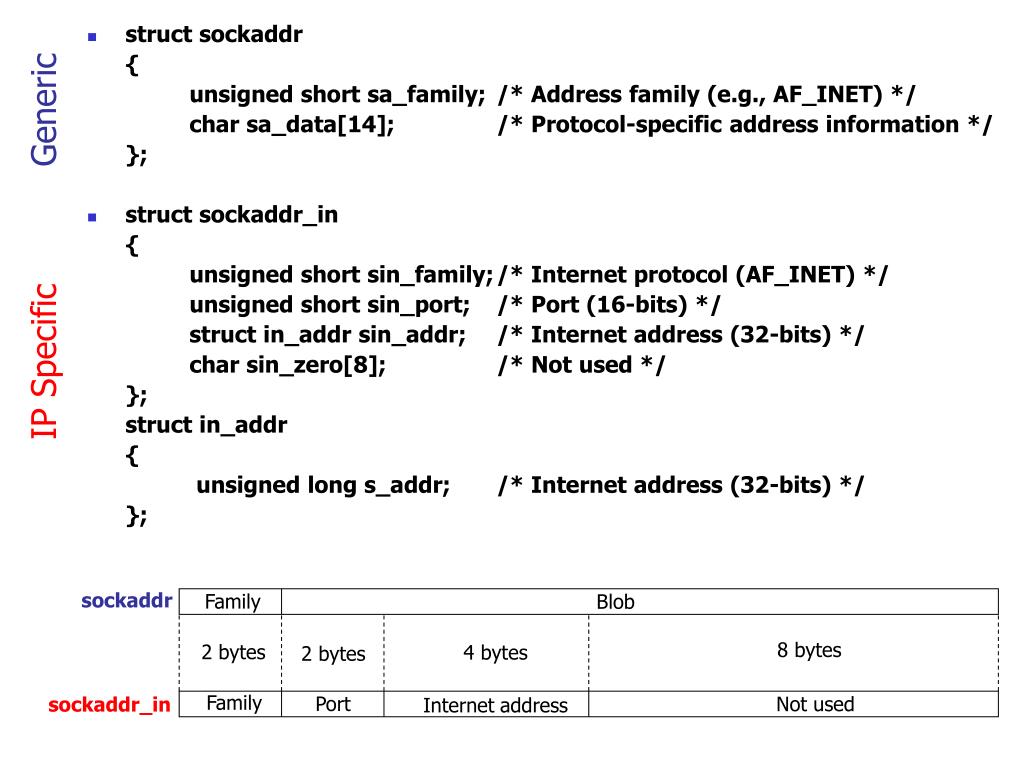
bind() takes a struct sockaddr_in. Fill in sin_family, sin_port using htons(), and sin_addr.s_addr using INADDR_ANY if you want to accept on all interfaces. htons() converts from host byte order to network byte order. The port number must be in network byte order. This is a detail that causes real bugs because it is easy to forget. listen() takes a backlog parameter. The value here controls how many completed connections can queue before accept() is called. On Linux the actual kernel behavior caps this at /proc/sys/net/core/somaxconn (usually 4096) and silently lowers values below 128. Setting it to 1 works technically but means your server will drop connections under even light load spikes. A value of 128 or 256 is reasonable for most applications.
Reading and writing without blocking your entire process
The default socket behavior is blocking. A read() call will sleep until data arrives or the connection closes. A write() call will sleep until the kernel can accept the bytes into the send buffer. This is fine for simple single-client tools but useless for anything concurrent. You have three choices for handling multiple clients: One: threads. Create one per connection. Simple. Scales poorly past a few hundred active connections due to stack memory and scheduling overhead. Also introduces synchronization complexity if your application state is shared.
Two: non-blocking sockets with select(), poll(), or epoll(). Set the socket with fcntl(fd, F_SETFL, O_NONBLOCK) on POSIX systems. Then use an event loop to watch for readability and writability. When a socket becomes readable, call read(). If it returns -1 with EAGAIN or EWOULDBLOCK, there is genuinely no data right now. Do not treat that as an error. This is the normal case for non-blocking sockets when no data has arrived yet. Three: async I/O libraries. libuv, libevent, or Boost.Asio handle the platform differences for you. If you are building something production-grade and do not want to maintain platform-specific event loop code, use one of these. Writing your own epoll wrapper is educational. Maintaining it across edge cases is not. On Windows the equivalent non-blocking approach uses WSAAsyncSelect() for message-based notification or OVERLAPPED I/O with completion ports for higher throughput. Completion ports on Windows scale significantly better than select() on any platform. If you are targeting Windows servers, IOCP is worth the learning curve.

The shutdown() vs close() distinction that bites people
close() destroys the file descriptor. The kernel drops its reference. If there is buffered data still unsent, the kernel may attempt to deliver it depending on the socket state, but you have no control over that from user space after close(). shutdown(fd, SHUT_WR) tells the kernel to send a FIN packet to the peer, completing the TCP half-close. The local process can still read incoming data from the client after sending the FIN. This matters for protocols where the server needs to read a final response after it is done writing, such as HTTP/1.1 where a client might send a trailer or additional data after the server signals it finished its response. I encountered a case where a client implementation expected the server to perform a graceful shutdown rather than an abrupt close(). The server called close() directly. The client saw RST instead of FIN and treated it as a connection error rather than a clean termination. Some clients are tolerant of this. Others fail silently or log spurious errors. Using shutdown(SHUT_WR) followed by a read loop until EOF, then close(), resolved the incompatibility.
Handle EINTR and partial reads
A common mistake is assuming read() will either return the exact number of bytes you asked for or an error. It returns whatever is available, up to your buffer size. On a slow network or under load, you might receive one byte at a time. You need a loop that accumulates until your protocol message is complete. Similarly, signal handlers interrupting syscalls cause EINTR. On Linux, man 2 read documents this explicitly. If a SIGCHLD handler runs between your fork() and waitpid(), the signal can interrupt accept() or read(). The robust approach is to retry the syscall on EINTR rather than treating it as a failure condition. Wrapping read() and write() in a small helper macro that retries on EINTR prevents a class of intermittent bugs that are extremely difficult to reproduce in testing.
IPv6 and the address resolution mess
getaddrinfo() exists to solve the problem of supporting both IPv4 and IPv6 without writing separate code paths. Pass NULL for the node parameter to resolve a hostname, or pass a literal address string. It returns a linked list of addrinfo structures. Iterate through them and try each one with socket(), bind(), and connect() until one succeeds. The common pitfall is ignoring the return value of getaddrinfo() or freeing the wrong structure. You must call freeaddrinfo() on the entire linked list when done. If you allocate a temporary struct sockaddr_storage to pass to getaddrinfo() hints, do not free that separately. It is not allocated by getaddrinfo(). On Linux, if your system has dual-stack support enabled (which is the default on modern kernels), binding to IN6ADDR_ANY_INIT with a V6 socket will also accept IPv4 connections. On Windows, the behavior depends on the IP_ENABLE_ADDRESS_FORWARDING registry setting and socket options. If you need IPv4-only behavior on a V6 socket, set IPV6_V6ONLY to 1 with setsockopt().

What TCP sockets cannot do for you
They do not enforce message boundaries. TCP is a byte stream. If you send three separate write() calls, the receiver may read them as one chunk, three chunks, or any fragmentation in between. If your protocol requires discrete messages, you must implement your own framing with length prefixes or delimiters. There is no built-in message preservation at the socket layer. They do not protect against malformed data. The kernel validates the TCP checksum and sequence numbers, but it does not understand your application protocol. A client can send garbage, send incomplete messages, or send data faster than you can process it. Your application must validate everything it receives. This is not a socket limitation. It is a reality of network programming that people learning from toy examples often discover too late. Socket buffers have finite size. The kernel send buffer is controlled by SO_SNDBUF and the receive buffer by SO_RCVBUF. Default values are usually 128 KB on Linux but can vary by distribution and kernel version. If you set them too low, high-throughput transfers will throttle. If you set them too high on systems with many concurrent connections, memory usage scales linearly with connection count. I had a service on a containerized Linux host where SO_RCVBUF was set to 16 MB by default through an application configuration, and forty thousand concurrent connections consumed over six hundred gigabytes of kernel memory before oom-kill triggered. Capping receive buffers to something reasonable like 256 KB per connection and letting the application manage its own buffering is usually safer.
A minimal working server skeleton
Here is the essential structure you would build on: Create the socket with socket(AF_INET, SOCK_STREAM, 0). Set SO_REUSEADDR with setsockopt(). Build a sockaddr_in with the port in htons() and address as INADDR_ANY. Bind to it. Listen with a reasonable backlog. Enter an accept loop. For each accepted fd, add it to your event tracking structure. Use poll() or epoll_wait() to determine which descriptors are ready for reading. Call read() in a loop handling EAGAIN and short counts. Process the accumulated data. Write the response. Close or shut down when the connection should terminate. On Windows, replace socket() with the Winsock equivalents, use WSAPoll() instead of poll(), and call closesocket() instead of close(). The logical flow is identical.
When you should not use raw sockets
Raw sockets in C are powerful but most application-level networking does not require them. If you are writing an HTTP server, a game protocol handler, or a database client, the standard stream socket API is sufficient. Raw sockets become necessary when you need to craft custom IP packets, implement ICMP tools, write packet sniffers at the kernel level, or build certain types of network infrastructure. They require root or CAP_NET_RAW privileges on Linux. They bypass the TCP stack entirely. They are also significantly more complex to debug because you are responsible for checksums, header construction, and fragment handling that the kernel normally manages for you. For the vast majority of applications, including most distributed systems and client-server architectures, the standard BSD socket API gives you everything you need without the additional complexity. The tradeoff is that you are working closer to the metal than you would with a language-level abstraction, which means more code, more places for bugs to hide, and less automatic handling of platform differences. That is the actual cost of using Tcp Ip Sockets In C compared to higher-level networking libraries. The FreeBSD man pages for socket(2), accept(2), and epoll(7) remain the most precise documentation available for Linux behavior, since Linux inherited much of the socket API design from 4.4BSD. The Linux kernel documentation at Documentation/networking/ provides supplementary detail on queue lengths, buffer scaling, and epoll internals that the man pages do not cover.