The actual mechanics of classroom observation systems
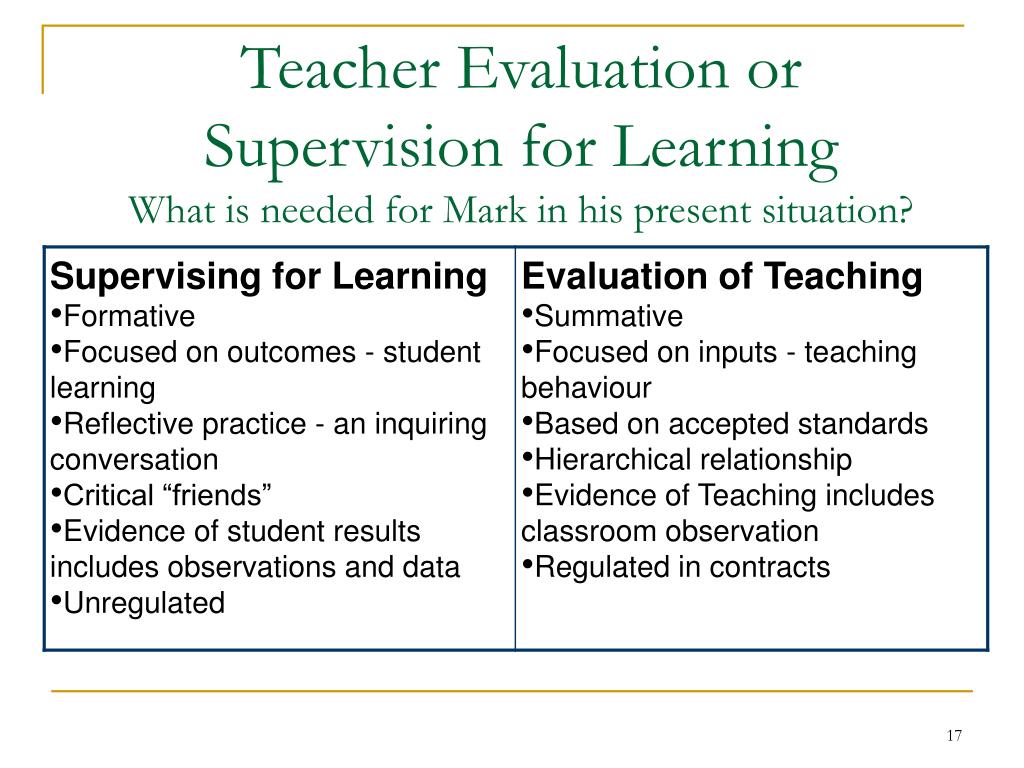
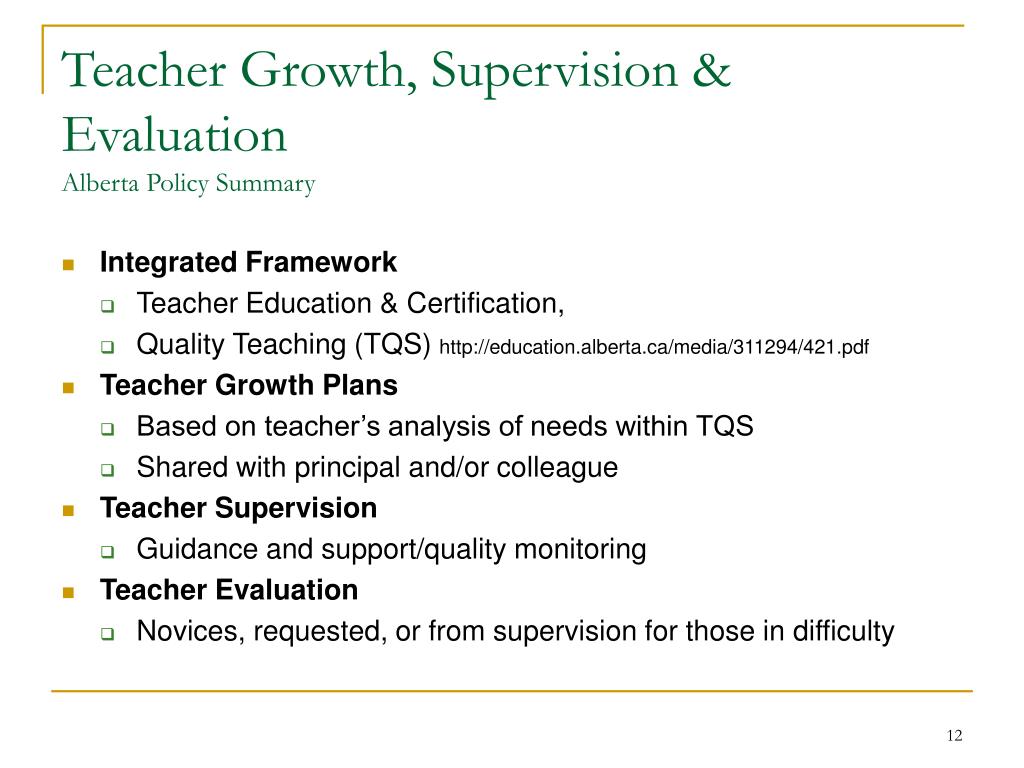
Most schools I've worked with built their supervision framework around a three-visit-per-year observation cycle using a rubric that averages 35 to 50 distinct performance indicators. The data gets compiled into an annual summative report that directly ties to contract renewal decisions in many districts. What happens between those visits usually doesn't get tracked systematically, which creates massive gaps in the final evaluation. The standard toolkit includes unannounced walkthroughs, formal lesson observations with pre- and post-conferences, student perception surveys, peer review panels, and self-assessment portfolios. Administrators tend to rely heavily on the walkthrough data because it's quick and frequent, but walkthrough ratings are notoriously shallow. You can capture whether a teacher launched the lesson on time and whether students were generally engaged. You cannot determine whether students actually learned anything substantial from thirty seconds of hallway visibility.
Teacher Supervision And Evaluation A Case Study Of a Suburban Middle School District
The district I'm referencing ran a two-year pilot where they replaced their traditional annual observation model with continuous instructional coaching paired with digital portfolio tracking. They had 142 teachers across seven buildings. Each teacher submitted weekly lesson artifacts, including learning objectives, formative assessment data, and reflection notes. Administrators conducted biweekly drop-in observations rather than the scheduled visits that defined the old model. The results showed a 14 percent improvement in teacher self-reported instructional confidence within the first year. Student achievement gains on district benchmark assessments increased by roughly 0.18 standard deviations compared to the control buildings. However, the pilot also required an additional 2.5 full-time equivalent administrative positions that the district had not budgeted for initially. The program ended after year two when the superintendent shifted funding priorities toward facility maintenance. The methodology behind most current supervision frameworks traces back to Danielson's Framework for Teaching and Marzano's Four Components of Teaching. The former breaks instruction into design, classroom environment, and professional responsibilities. The latter focuses on goal setting, feedback, and conditions for teaching. Both have extensive research behind them but both have also been criticized for requiring too much documentation to be sustainable at scale.
One thing nobody warns you about is the scoring inflation problem. When administrators know that evaluation scores influence contract renewals or merit pay, they unconsciously adjust their ratings upward. I ran a calibration workshop once with four principals observing the same video lesson using the same rubric. The scores ranged from 2.1 to 3.8 out of 4. That is not a measurement difference. That is a reliability issue that undermines the entire system. The workaround I developed involves blind scoring protocols where evaluators submit ratings before discussing them with each other, combined with annual inter-rater reliability training using standardized video samples. The district I mentioned above adopted this after their second year and brought their inter-rater reliability coefficient from 0.41 up to 0.73 over three months of monthly calibration sessions. Student feedback surveys are another component that gets implemented poorly almost everywhere. Teachers interpret any survey asking about classroom experience as a popularity contest. Students interpret it the same way. The valid metrics in student surveys are narrow and specific. Questions about whether instructions are clear, whether the teacher returns papers quickly, and whether the classroom is respectful tend to produce reliable data. Questions about whether the teacher is fun or nice are noise that actually degrades the signal.
Get the Full Details

I found that limiting student survey questions to exactly six items focused on observable teaching behaviors rather than general satisfaction improved response quality and reduced completion time from eight minutes to under three. Three minutes is the window where student attention stays on task during survey completion. Anything longer and the data quality drops significantly. The common pitfall in implementation is treating evaluation as a compliance exercise rather than a development tool. When teachers expect a visit to result in a score that determines their livelihood, they perform rather than teach. The pre-observation conference becomes a negotiation about what lesson to schedule instead of a planning conversation. The post-observation conference becomes a defensive discussion about rating justification instead of genuine reflection. Administrators who want to get useful data need to separate the development conference from the evaluative conference entirely. Schedule them on different days with different agendas. One is for growth. The other is for documentation. Mixing them together confuses the purpose and corrupts the honesty of both conversations.
There is also the problem of evaluation fatigue. Teachers in my experience stop engaging meaningfully with the process after the third or fourth year because the feedback never leads to actionable change. They fill out the required forms, they host the observer, they sign the document. The system has graduated into a box-checking ritual that generates paper but not improvement. Portfolio-based evaluation systems can partially solve this by giving teachers more ownership over what evidence they present. Instead of administrators extracting data, teachers curate it. The tradeoff is that portfolio systems require significantly more teacher time upfront and they shift the burden of evidence collection onto the person being evaluated. That shift creates its own fairness concerns if the most organized teachers consistently outperform the most effective ones simply because organization is easier to document than impact. Value-added modeling is another approach that appears in some district policies. It attempts to isolate teacher effectiveness by controlling for student demographics and prior achievement. The statistical models are sophisticated. The results are deeply unreliable at the individual teacher level and should only be interpreted at the aggregate group level where the noise cancels out. Using VAM scores for personnel decisions has been ruled unconstitutional in several states for that exact reason.
What works better in practice is a balanced scorecard approach combining multiple data sources with weighted importance that reflects what each source can reasonably measure. Walkthroughs capture frequency and consistency. Formal observations capture instructional quality. Student surveys capture classroom climate. Peer reviews capture collaborative practice. Portfolios capture growth over time. No single source is sufficient. Combining them without pretending any one of them tells the whole story is the only honest approach. The biggest bottleneck I encounter is the time requirement. A thorough formal observation cycle with pre-conference, observation, and post-conference takes approximately 90 minutes per teacher. For a principal managing 25 teachers, that is 37.5 hours of pure observation work not counting travel time between rooms or report writing. Most administrators do not have that capacity. The result is rushed observations or skipped cycles, which defeats the purpose of having the system at all. Scheduling observation time into the master schedule is the structural fix. If a school dedicates two Wednesday afternoons per month to internal coverage where administrators observe each other's teachers during planning periods, the math works. You can observe every teacher once per semester within existing workload parameters. This requires a culture shift where teachers understand that being observed is a normal part of professional practice rather than an exceptional event that signals trouble.
Technology platforms for managing this process have improved considerably. Systems like GoldPass, Schoolvue, and Instructional Coaching Manager allow teachers to upload artifacts, schedule observations, and generate reports automatically. The automation saves roughly 4 to 6 hours per teacher per year on administrative overhead compared to paper-based systems. The platforms themselves are adequate. The data entered into them is only as good as the discipline of the people using them. When a teacher submits a portfolio entry three weeks late or skips the reflection component because the template feels tedious, the system records that gap as neutral data rather than problematic behavior. Evaluators then work with incomplete information. The recommendation here is straightforward: set hard deadlines with meaningful consequences for missing them, and keep the reflection prompts short enough that teachers can complete them in under ten minutes without treating the process as a burden. The ethical dimension deserves more attention than it receives. Evaluation systems inevitably affect employment outcomes, salary progression, and professional reputation. Any system that claims to measure teaching quality is making a value judgment about what good teaching looks like. Those values reflect the culture and priorities of the district implementing the system. A rubric that emphasizes collaborative planning and differentiated instruction will rate teachers differently than one that emphasizes traditional direct instruction and classroom control. Neither is objectively correct. They reflect philosophical choices dressed in measurement language.
Teachers from historically marginalized backgrounds sometimes face systematic bias in evaluation rubrics that prioritize middle-class communication styles and behavioral management approaches over culturally responsive practices. The research on this is established but the fixes are uncomfortable because they require districts to audit their own rubrics for cultural assumptions. The simplest fix is including teacher voice in rubric revision committees and requiring raters to complete implicit bias training before participating in formal evaluations. The legal landscape around teacher evaluation has shifted significantly. Court challenges in Tennessee, Ohio, and Connecticut have established that high-stakes evaluation systems must demonstrate reliability and validity or they violate due process rights. Districts that continue using flawed instruments risk costly litigation. The baseline standard is that an evaluation system must be internally consistent, produce stable results across raters, and correlate meaningfully with student learning outcomes. Systems that fail any of those three tests are legally vulnerable. I have found that the most sustainable approach combines developmental cycles with evaluative cycles on alternating semesters. One semester focuses entirely on growth conversations, peer collaboration, and skill building with no summative score attached. The next semester includes formal evaluation with documented ratings tied to personnel decisions. This separation allows teachers to take instructional risks during development cycles without fear that a failed experiment will damage their evaluation. It also gives evaluators the space to have honest conversations about improvement during the developmental phase.
The data from the suburban middle school pilot suggests that continuous feedback loops matter more than annual high-stakes events. Teachers who received weekly formative feedback showed greater instructional growth than those who received the same total amount of feedback delivered annually in one comprehensive conference. The frequency of feedback interacts with the retention and application of that feedback. Weekly cycles create memory traces that support behavioral change. Annual cycles do not. There is no downloadable template or universal tool that fits every context. The most useful resource is a rubric aligned to your district's instructional priorities and a calendar that reflects realistic observation capacity. Start with what you can sustain rather than what looks impressive on paper. A well-executed quarterly observation cycle beats a poorly executed monthly one every time. Consistency matters more than frequency when the alternative is burnout. If you are building a system from scratch, begin with a needs assessment of your current practices rather than adopting someone else's framework wholesale. Map when observations happen now, who conducts them, what data gets collected, and how results are used. You will likely find that you already have pieces of a system that just need coordination rather than replacement. The work is in connecting those pieces intentionally rather than letting them operate as separate bureaucratic activities that generate reports nobody reads.