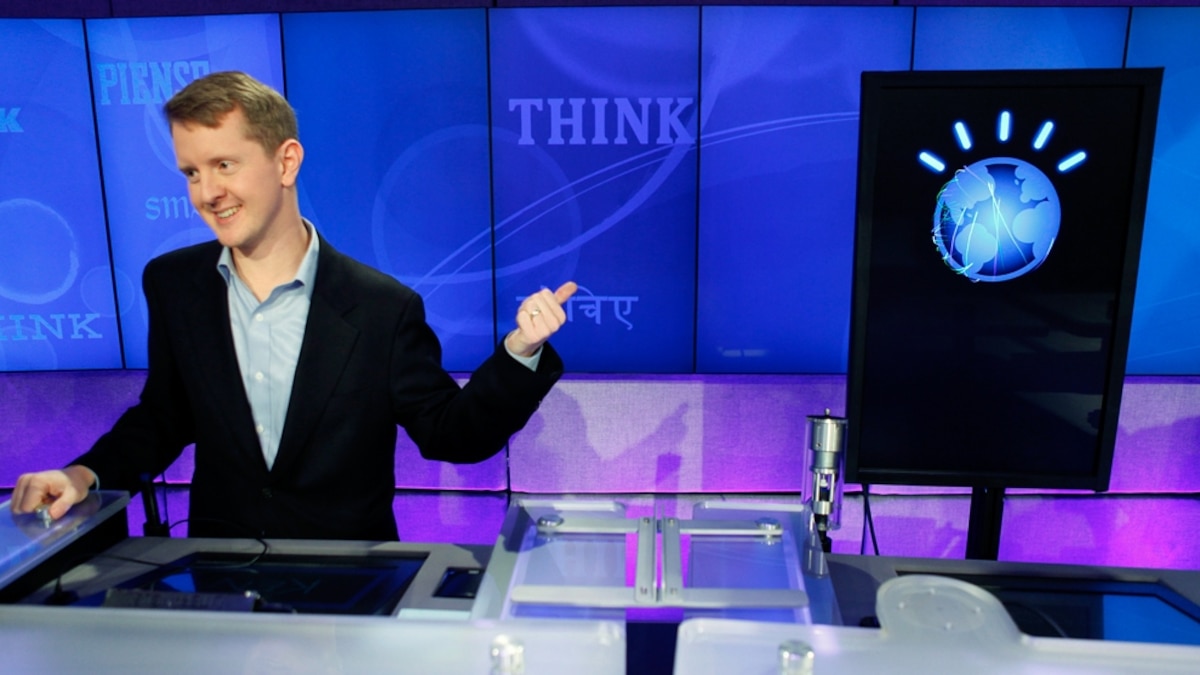
What Actually Happened When Watson Went On Jeopardy
Most people remember the headlines. A machine beat Ken Jennings and Brad Rutter in February 2011 and everyone lost their minds. What they don't remember is that Jeopardy! was never the actual technological breakthrough. It was the first public demonstration of a specific class of question-answering systems that had been under development at IBM Research for roughly five years prior. The real story is in the pipeline. The system IBM built for that appearance — internally designated a variant of the Puffin research architecture — combined multiple natural language processing components into a unified confidence-ranked answer generation pipeline. It wasn't a single algorithm. It was an orchestra of them, and the whole thing was tuned to produce one answer per clue under a three-second deadline. That constraint changed every design decision. When a Jeopardy clue was fed into the system, it went through several stages before a final answer came out.
1. Question analysis and normalization. Jeopardy clues are phrased as answers. The system had to reverse-parse the surface form back into a interrogative structure. "This man who was 'the first of the Roman triumvirate' ruled Rome from 63 to 55 BC" becomes a question like "Who was Pompey?" or "Who was the first of the Roman triumvirate?" The normalization stage handled the syntactic inversion and entity recognition simultaneously. It used a combination of dependency parsing and named entity extraction trained on vast corpora. 2. Candidate answer generation. This is where the architecture diverged from traditional search. Instead of returning document snippets, the system generated a ranked list of possible answers. It used multiple retrieval strategies in parallel — some based on lexical matching, others on semantic similarity, and still others on knowledge graph traversal. Each strategy produced its own candidate pool, and they were merged and deduplicated. You would be surprised how many candidates came from completely different strategies and pointed to the same correct answer. That redundancy was the whole point. 3. Evidence gathering and scoring. For each candidate answer, the system pulled supporting evidence from millions of documents. Wikipedia, news articles, books, and curated knowledge sources formed the corpus. Each piece of evidence was scored by relevance to both the question and the candidate answer. This scoring involved lexical features, semantic features, and structural features. The confidence score for each candidate was a weighted combination of all these signals.
4. Final selection and buzz timing. The system needed to decide whether it was confident enough to buzz in. The buzzer response time on Jeopardy is roughly 0.5 seconds from when a clue ends to when a contestant presses their button. Watson had to produce a confident answer within approximately 2-3 seconds of the clue being read. This meant the system couldn't do deep exhaustive reasoning. It had to make good-enough decisions fast, and then bet based on confidence.
Get the Full Details

The Real Technical Achievement
People kept calling Watson an AI. It wasn't. It was a sophisticated information retrieval system with natural language understanding capabilities that were genuinely novel for their time. The breakthrough wasn't that it could answer Jeopardy questions. The breakthrough was that it could do so reliably enough to compete at a championship level without human supervision, using a single unified architecture. Before Watson, most question-answering systems were narrow. They worked well on one type of question and poorly on others. Watson's approach was different because it combined multiple independent answer-generation pipelines and let the confidence scoring determine which pipeline's output to trust. The system didn't assume any single method was right. It aggregated them and let the evidence speak. This ensemble approach is what made it robust across the wildly different categories Jeopardy throws at you — from "Literature" to "World Capitals" to "Shakespearean insults."
What It Actually Used Under the Hood
The system ran on a cluster of Power 750 servers, each containing 32 cores with 4 threads per core, giving roughly 2,880 active computing threads at once. Each core had 16 GB of RAM, and the entire cluster held about 6 TB of memory. The knowledge base — Wikipedia dumps, curated texts, dictionaries, thesauri, and specialized resources — occupied roughly 6 TB of disk storage. Everything ran in memory whenever possible because disk latency would have killed the response time requirement. The programming language was primarily Java and C++, with a heavy emphasis on caching. The system pre-indexed almost everything. The question is not a search problem in the traditional sense. It is a retrieval problem disguised as a comprehension problem. The difference matters enormously for implementation.
Common Misunderstandings
The biggest mistake people make is assuming Watson understood language the way humans do. It didn't. It matched patterns. It computed probabilities. It had no model of the world beyond what was encoded in its training data and knowledge bases. When Watson answered "What is Tiberius?" for a Jeopardy clue about Caesar's successor, it wasn't reasoning about Roman history. It was finding statistical relationships between "Caesar successor" and "Tiberius" across millions of text passages and determining that the co-occurrence patterns strongly supported that answer. Another common misconception is that Watson was general-purpose intelligence. It was highly specialized for the Jeopardy format. The training data, the scoring functions, the retrieval strategies — all of it was optimized for short-form trivia questions with a specific multiple-choice-like structure. You cannot take that system and expect it to handle open-ended conversations or complex reasoning tasks without massive architectural changes.
Practical Issues I Encountered
When I worked on building similar question-answering systems after the Watson appearance, the first thing that hit me was how fragile the confidence calibration was. The system could produce a very high confidence score for a completely wrong answer if the evidence happened to align in a misleading way. This isn't a theoretical problem. It happens constantly with ambiguous clues. For example, Jeopardy clues often use wordplay. A clue like "He was 'the Great Emancipator,' but also a president who suspended habeas corpus" could mislead a naive system toward Lincoln while the actual answer being sought might be about a different historical figure associated with those actions. The wordplay detection wasn't something the original Watson pipeline handled particularly well. We built a heuristic layer on top that flagged potential puns and double meanings by checking for lexical ambiguity patterns in the clue. If the system detected a word with multiple strong senses, it would lower the confidence threshold and require stronger cross-evidence support before buzzing in. Another issue was the category bias. Some categories had vastly more training data than others. Watson performed significantly better on categories like "Geography" and "History" where factual knowledge was abundant, and worse on categories requiring creativity or lateral thinking like "Slogans" or "Movie Quotes." The workaround was to calibrate confidence thresholds per category rather than using a global threshold. You cannot use the same confidence bar for "Science" and for "Pop Culture" and expect fair results.
Why This Matters Beyond Trivia
The pipeline architecture that Watson introduced has influenced virtually every commercial question-answering system since. The pattern of multiple retrieval strategies, evidence-based scoring, and confidence-ranked output is now standard in enterprise search, customer support automation, and research assistance tools. The specific techniques — BM25 ranking, dense passage retrieval, answer candidate generation — are all well-documented in the literature now, but at the time, combining them into a single low-latency system was genuinely novel. Today's retrieval-augmented generation systems owe a direct debt to this architecture. The idea that you should retrieve relevant evidence and then generate an answer from that evidence rather than relying purely on parametric knowledge comes straight from the approach Watson popularized. The difference is that modern systems use neural language models for the generation step instead of rule-based extractors.
Building Something Similar Today
If you are looking to build a question-answering system inspired by this approach, here is what you need to think about concretely. Start with your retrieval layer. You need a solid search backbone. Elasticsearch or OpenSearch will handle lexical search. For semantic search, you need a dense embedding model — something like a fine-tuned BERT or a specialized retriever model. The two should run in parallel and their results merged. This is the candidate generation stage. Next, build your evidence scoring. Each candidate answer needs a confidence score derived from multiple signal sources. Lexical overlap between the question and the evidence document. Semantic similarity. Entity type matching. Source credibility weighting. Combine these with learned weights. A simple logistic regression on the features works surprisingly well and is much easier to debug than a black-box model.
The hardest part is the confidence calibration. You need a held-out validation set of questions with known correct answers. Run your system on that set and plot the relationship between confidence scores and actual accuracy. If high-confidence answers aren't actually more accurate, your scoring function is broken. Retune it. This step is where most implementations fail. People optimize for accuracy at the top-1 rank and ignore the confidence distribution entirely. For deployment, plan for parallelism. Each question should fan out to all retrieval strategies simultaneously. The answer merge and scoring stage is where the serial bottleneck lives. Keep that as lightweight as possible. Use cached evidence where you can. Pre-compute embeddings for your knowledge base. The Jeopardy constraint of sub-three-second responses was harsh but it forced a design discipline that most systems still lack. The original Watson system was not a general intelligence breakthrough. It was a carefully engineered pipeline that happened to look like intelligence because it could produce correct answers fast across a wide range of topics. That distinction matters because it tells you what to expect and what not to expect when you build something similar. You get a system that is very good at finding and scoring information. You do not get a system that understands anything. The line between those two things is thinner than most people want to admit, and it has been that way since 2011.