The Reality of Modern Switching Infrastructure
Telecommunication switching isn't what most people think it is anymore. The old toll switches with their spinning crosspoints and time-division multiplexing are mostly museum pieces. What you're dealing with now is either SS7 routing equipment or SIP-based softswitch architectures, and understanding how they actually operate under load is where most people get tripped up. At the hardware level, a switch is just a massively parallel crossbar fabric with signaling controllers attached. Your basic ADM/DSA shelf in a central office can handle somewhere between 2 million and 4 million B-channels depending on the generation. The real trick isn't the fabric itself, it's the inter-switch signaling that keeps paths connected across multiple nodes without collapsing when one route goes down. SS7, or Signaling System 7, is still the backbone for traditional PSTN switching. It's a separate packet-switched network that carries call setup and teardown messages between switches. The data channel is completely independent from the voice channel, which is a design decision that saved carriers enormous amounts of money when they realized out-of-band signaling didn't tie up trunk circuits during call processing. It also means you can do number portability, voicemail, and caller ID without modifying the actual voice path.
When you move to IP, the whole paradigm shifts. SIP trunking replaces TDM trunks, and softswitches replace physical toll switches. A SIP proxy or registrar handles registration and routing decisions, while media gateways do the actual codec translation between SIP and TDM if needed. The advantage is operational cost reduction. The disadvantage is that you now have to deal with NAT traversal, QoS tuning, and a layer of complexity that TDM never required because the circuit was always dedicated.
How Call Routing Actually Works Under Load
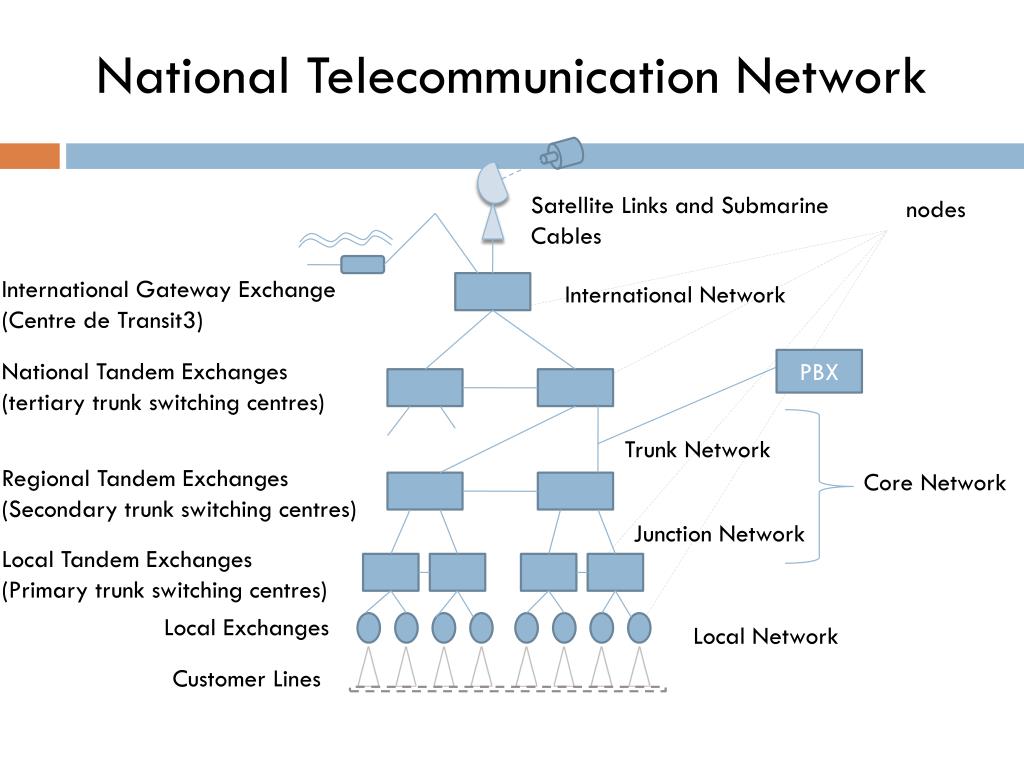
Route selection in a switching system follows a hierarchical pattern. The called number comes in, the switch does a pattern match against its routing table, applies any number portability database queries, evaluates least-cost or quality-based routing policies, and then sets up the outgoing signal path. This happens in milliseconds on a modern switch, but the timing budget gets tight when you're doing real-time CDR generation, fraud detection checks, and protocol translation all at once. One thing people don't think about enough is the signaling link capacity. In an SS7 network, your MTP layer uses signaling links, usually at 64 Kbps per link in North America, grouped into linksets. A typical STP (Signal Transfer Point) will have anywhere from 8 to 64 signaling links depending on the traffic density of the point it serves. If your signaling links are undersized, you get congestion indications, call setup failures, and delayed answer messages that users interpret as poor call quality. The voice path might be perfectly fine, but the control plane can't keep up. I spent about three days once troubleshooting why a carrier's call completion rate dropped to about 87% during morning traffic peaks. The voice trunks had plenty of capacity, the switches weren't CPU-bound, everything looked normal on the surface. Turns out the STP was dropping point codes during congestion because the M3UA adaptation layer wasn't properly tuning its congestion control timers. The fix was adjusting the M3UA availability timer and the route availability delay parameters. After that, completion rates jumped back to 99.6% almost immediately. Nobody checks the signaling layer unless the voice layer is fine and something else is broken.
Get the Full Details

Common Pitfalls That Cost Money
Number portability databases are one area where beginners make expensive mistakes. When a carrier ports a block of numbers, the LNP (Local Number Portability) database needs to be updated within a specific regulatory window, usually two business days in the US. If you miss it, calls get routed to the old serving switch, your interconnection partner bills you for the wrong routing, and then you spend weeks trying to reconcile those charges. I've seen teams lose six figures in a single quarter from porting database sync delays across multiple interconnection points. Another pitfall is assuming that SIP rewrite rules are simple text substitutions. They're not. When you're rewriting SIP headers across different administrative domains, you need to account for Via header hop counting, Record-Route interactions, and the fact that some older POTS phones and softswitches don't handle certain SIP extensions gracefully. I once had a carrier deploy a SIP gateway that added Route headers aggressively to force a particular path for recording compliance. The result was that 12% of all calls using that gateway failed with a 483 error because the called party's switch rejected the unexpected Route header chain. We switched to a passive monitoring approach instead, and the failure rate dropped to near zero. Codec negotiation on IP switches is another place where things go sideways. G.711 is the default, but bandwidth costs make that expensive over long-distance IP links. You'll want G.729 or possibly AMR-WB for mobile backhaul. The problem is that not every switch in the chain supports the same codec set, so you end up needing transcoders. Transcoders introduce latency, they add cost per minute, and they become a single point of failure. The workaround is to negotiate end-to-end codec support between the originating and terminating switches and only transcode when absolutely necessary. Document your codec capability matrix across every interconnection point before you ever go live.
Testing and Validation That Actually Matters
Load testing a switching system means something different than load testing a web application. You're not measuring response time for individual requests, you're measuring sustained call setup throughput, call completion rate under congestion, and recovery time after a node failure. A proper test run takes at least 72 hours of continuous traffic at 80% of rated capacity. Anything less and you won't see the memory leaks or the gradual signaling queue buildup that shows up after eight hours of operation. For SS7 systems, you need a signaling test set that can generate and analyze both ISUP and MAP messages. Tools like Anritsu's MT8820C or Viavi's JDSU platforms do this, but they're expensive. Cheaper alternatives exist in the form of software-based SS7 simulators, but those only cover the message generation side. You still need hardware to verify the actual interworking with the switch under test. For SIP-based systems, a load generator like Kamailio with the KEMI module or a commercial tool like Metaswitch's SIPSuite can simulate thousands of concurrent registrations and call flows. The key metric is not just setup time but also registration refresh rate and proxy state memory consumption over time. I've seen SIP proxies that handled 5,000 concurrent calls fine for the first six hours, then started dropping REGISTER messages because the location service data structures weren't being cleaned up properly. The calls still worked, but new devices couldn't register, and nobody noticed until the field reported it.
When to Stick With TDM and When to Migrate
The migration from TDM to IP switching isn't a technical decision anymore, it's an economics decision. TDM equipment is more expensive to maintain because spare parts for legacy switches are getting harder to find and the technicians who know how to troubleshoot them are retiring. IP infrastructure has commodity hardware and a much larger talent pool. But migration introduces SIP trunk security concerns, jitter buffer management, and emergency calling compliance issues that TDM never had. If your current TDM network is operating reliably and your traffic patterns aren't growing faster than 15% annually, there's no urgent reason to migrate. Plan for it within a three to five year horizon, but don't rush. The carriers that moved too fast in the late 2000s learned that the hard way, particularly around E911 and law enforcement intercept compliance on IP networks. For greenfield deployments, SIP-only architectures make sense from day one. There's no legacy baggage, you can integrate with OTT services more easily, and the provisioning tools are significantly better. Just make sure your VoIP security posture is in place before you go live, because SIP is trivially exploitable if you leave the door open.