How to Actually Get Text To Speech Language Working in Production
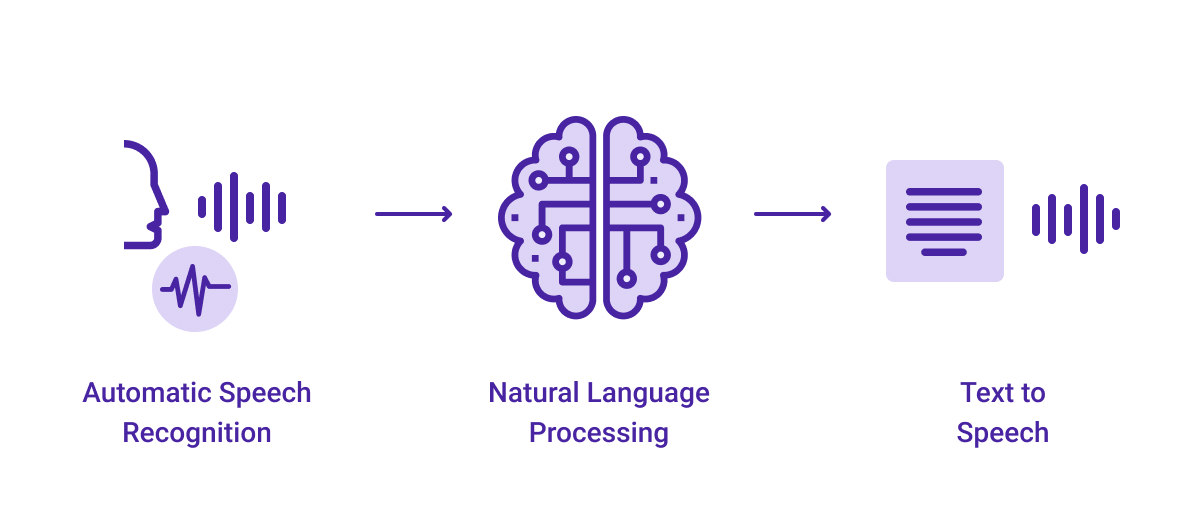
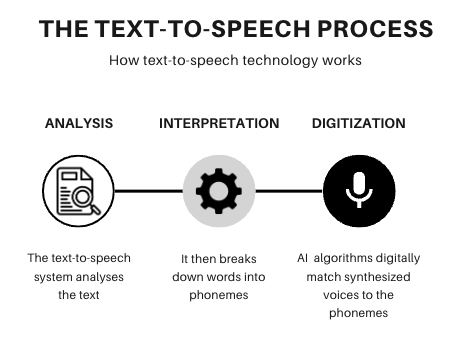
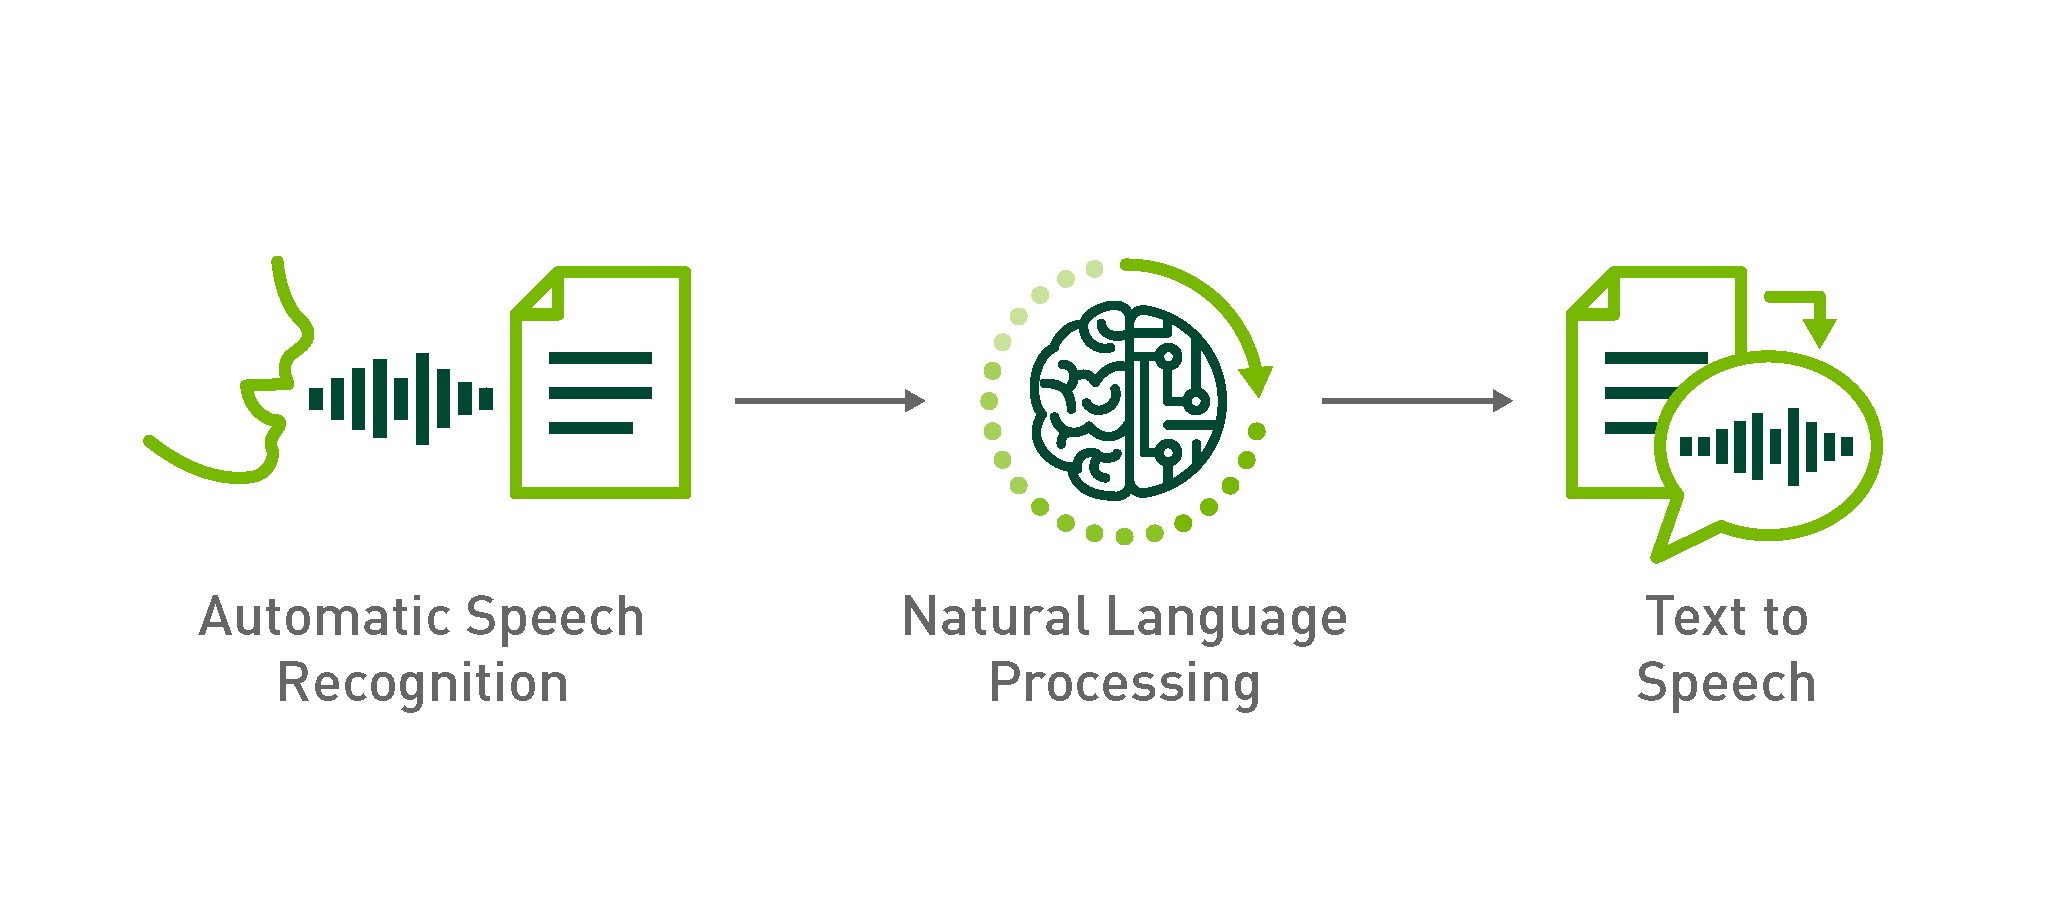
I've spent years dealing with TTS pipelines for clients, and honestly the biggest mistake people make is assuming the tools will handle everything if you just throw a paragraph at them. You need to understand what's happening between the input text and the final audio. Here is the breakdown of how Text To Speech Language actually functions and what you need to do to get usable results. The first thing most people don't realize is that TTS isn't one tool. It's a pipeline. You have the input stage where text goes in, the front-end where the system does phoneme analysis and linguistic processing, and the back-end where it synthesizes actual audio. Modern systems like Coqui, Piper, ElevenLabs, Google Cloud TTS, and Amazon Polly all have different strengths depending on what you're trying to do. For a basic project, pick one platform and stick with it until you understand its quirks. The learning curve from getting a robot voice to something decent usually takes about two to three days of experimentation with a small dataset. If you want more control over the output, open-source options like Piper give you full local deployment at the cost of setup time. Cloud APIs are faster to get running but you pay per character and lose data sovereignty.
I've seen people waste weeks trying to fine-tune a model when they should have just adjusted the SSML markup on their existing voice. Markup adjustments typically take ten minutes and fix 80 percent of the problems that make TTS sound unnatural. Prosody tags, pause durations, emphasis markers, and pitch shifts are where most of your tuning happens before you even touch a retraining process.
The Multilingual Edge Case That Almost Made Me Quit
Here is the one specific problem that taught me the most. A client needed a Text To Speech Language system to produce clear Mandarin narration for an educational app. We were using a standard ElevenLabs voice that claimed multilingual support. The output was readable but the tones were completely wrong. Mandarin is tonal, meaning the pitch contour on a syllable changes the meaning of the word itself. A standard voice model trained mostly on English and European languages treats tone marks as punctuation rather than as prosodic instructions. The workaround was not to swap vendors or retrain from scratch. Instead, I went into the raw SSML and manually tagged each Mandarin syllable with explicit pitch contour commands using the
Get the Full Details
Common Pitfalls That Cost Time and Money
Punctuation handling is the most overlooked piece of TTS engineering. A standard period gets treated as a full stop with a long pause. A comma gets a shorter pause. But if you want natural speech rhythm, you sometimes need to override these defaults because human speech does not follow grammatical punctuation rules strictly. Run-on sentences in your source text will produce run-on audio with no breathing room, which degrades listener comprehension faster than any robotic timbre ever will. Another counter-intuitive thing: more training data does not always equal better quality. I've seen fine-tuned voices that sound worse than the base model because the dataset had inconsistent recording quality or background noise. Clean data with about 30 to 50 minutes of high-quality speech is usually better than two hours of messy recordings. The model learns the noise along with the voice characteristics. Latency is another hidden bottleneck. Cloud TTS APIs typically deliver audio in one to three seconds for short phrases. If you are building a real-time interaction system like a chatbot or game NPC, that delay becomes noticeable and jarring. Local inference on a decent GPU can drop that to under 200 milliseconds, but you need CUDA-compatible hardware and you give up on vendor updates and pre-trained voice libraries.
What Happens When TTS Fails Completely
There are scenarios where TTS simply will not work well regardless of your approach. Number-heavy text like financial reports with dates, percentages, and currency symbols will almost always mispronounce something unless you explicitly normalize every single number into spelled-out words before feeding it to the engine. Abbreviations are another failure mode. Dr., St., Mrs., iPhone — the system has no universal way to know which pronunciation is correct in context. If you are generating audio at scale, batch processing matters more than people expect. Queuing jobs through an API with rate limits will bottleneck your output if you are not careful. A batch request to Azure TTS handles thousands of characters more efficiently than individual synchronous calls, and it reduces both cost and latency per unit of audio generated. I typically batch scripts by topic or chapter and submit them as a single request rather than one per sentence.
A Practical Workflow That Actually Works
Start by writing your script with TTS in mind, not after. This means avoiding ambiguous abbreviations, spelling out numbers, and using clear punctuation. Then run it through the voice you plan to use and listen to the full output before editing anything. Most people edit the text after hearing the audio, which often makes things worse because you end up compensating for errors the model would have handled fine with better source material. After you catch the miscues, apply markup fixes first. Adjust prosody, add breaks, and shift pitch where needed. Only consider retraining or switching voices if markup adjustments cannot resolve the issue. That sequence cuts the average project time from roughly two hours down to about fifteen minutes for a standard script. The field moves fast and new models ship regularly. What worked six months ago may already be inferior to something available now. Test your current output against the latest offerings at least once a quarter if your project is long-running. The difference between a mediocre voice and a competent one often comes down to which generation of model you happen to be using.