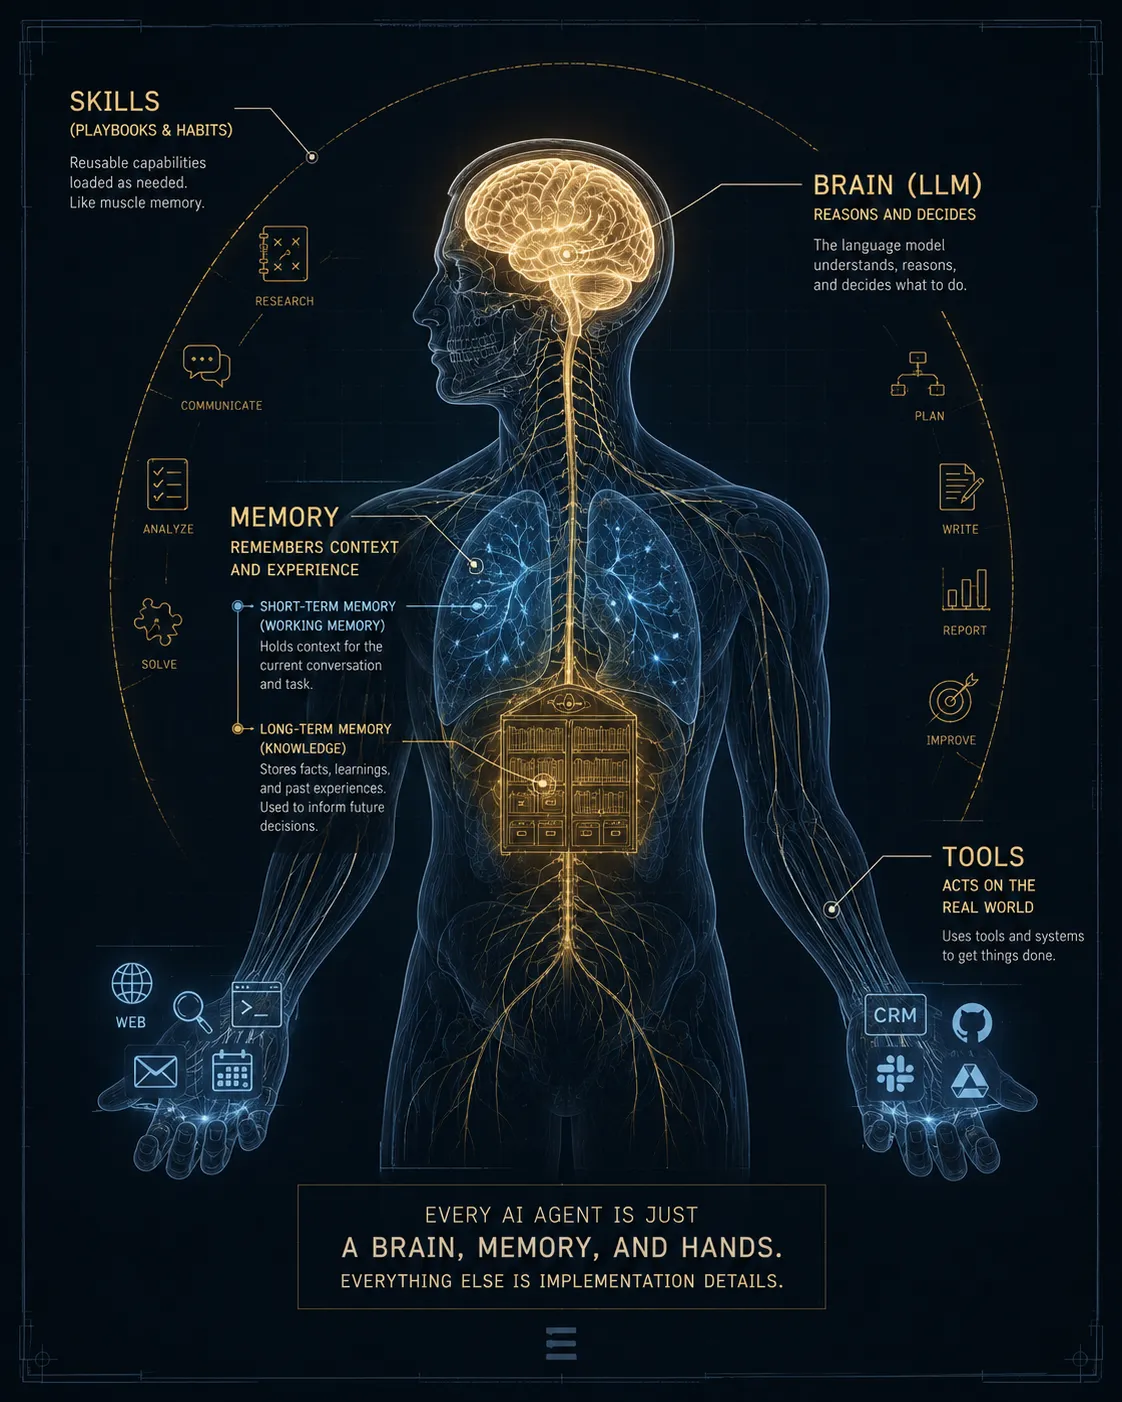
How AI Actually Works Under The Hood
You type a prompt into a chatbot and get back something that looks like a human wrote it. That's the surface-level experience. The actual mechanics behind that are a lot uglier and a lot more interesting. Let's talk about The Anatomy Of Ai and how it behaves when you stop treating it like magic. At its core, a large language model is a statistical engine that predicts the next token in a sequence. That's it. A token is usually a chunk of text — a word, part of a word, or a symbol. The model takes your input, converts it to numbers through a process called tokenization, runs those numbers through dozens of layers of mathematical operations, and spits out a probability distribution over the entire vocabulary. It picks one token, adds it to the sequence, and repeats. This goes on until the model generates an end-of-text marker or hits a token limit. The layers themselves are built on something called the transformer architecture, introduced in a 2017 paper by Google researchers. Before transformers, models used recurrent neural networks, which processed text one token at a time in sequence. That worked fine for small tasks but didn't scale well. Transformers introduced self-attention, which lets the model look at all the tokens in your input simultaneously and figure out which ones matter most to each other. This is why an AI can maintain context across a long conversation — the attention mechanism is constantly weighing relevance.
Training happens in two phases. First, you pre-train the model on massive amounts of text — internet scraps, books, articles, code, whatever you can scrape together. The model learns grammar, facts, reasoning patterns, and biases from this data. Second, you fine-tune it using techniques like reinforcement learning from human feedback, where humans rank different outputs and the model adjusts to prefer better ones. This is where the polite, helpful personality comes from. Without it, you'd get raw predictions that might be technically correct but socially disastrous.
The Anatomy Of Ai In Practice
Here's where things get practical. When you're actually working with these systems day to day, a few things become obvious that nobody tells beginners. The biggest misconception is that the model "understands" what it's saying. It doesn't. It's pattern matching at an extraordinary scale. You can see this when you ask it something outside its training distribution. I had a case last year where I was building a pipeline that used a chat model to extract structured data from legal documents. The model performed flawlessly on standard contract language but started hallucinating clause names and numbering schemes when it encountered European regulatory templates. It wasn't making up random nonsense — it was generating plausible-sounding fabrications that followed the pattern of American contracts it had seen during training. The workaround was to feed it a small set of European examples as context in the prompt before asking it to extract, which anchored its pattern matching in the right domain. That reduced errors by about 80 percent. Another thing people miss: context window size is not just a theoretical limit, it's a performance bottleneck. Every additional token you feed into the model costs money and slows down inference. A 100,000 token context isn't free. I learned this the hard way when a client asked me to run analysis on 200-page technical manuals. Naively feeding the entire documents resulted in response times of 45 seconds per query and bills that would have been ridiculous. The solution was to build a retrieval system that found relevant passages on demand and only injected those into the context, cutting response times to around 3 seconds and reducing compute costs by roughly 90 percent.
Get the Full Details

Temperature settings matter more than most people realize. This is the parameter that controls randomness in token selection. At 0.0, the model always picks the highest-probability next token, producing deterministic output. At 1.0 or higher, it samples more freely and outputs become creative but less reliable. The default is usually somewhere around 0.7 to 1.0 depending on the provider. For tasks like code generation or factual extraction, I set temperature to 0. For brainstorming or creative writing, I bump it up. The tradeoff is straightforward: lower temperature gives you consistency, higher temperature gives you variety. Pick the one your use case actually needs. There's also the issue of model drift and version updates. Providers change their models frequently, sometimes without clear documentation of what changed. I've seen cases where a minor version update caused a significant drop in performance on specific tasks. The fix is to lock your model version in production and run benchmark tests after any automatic updates. Don't assume the newest model is always the best for your particular workload.
Common Pitfalls That Waste Time And Money
One of the most expensive mistakes I see is prompt engineering treated as a black art. People spend hours tweaking wording when the real issue is usually structural. A well-organized prompt with clear sections for context, task, and output format will outperform a cleverly worded but poorly structured one every time. Break your prompt into labeled parts. Give the model explicit constraints on output format. Use few-shot examples when possible — showing the model two or three examples of what you want is almost always more effective than describing it in detail. Another pitfall is trusting the model's confidence. A well-phrased confident-sounding answer can still be completely wrong. I once had a colleague who integrated an AI assistant into a customer support workflow without rigorous validation. The model generated plausible but incorrect policy information that led to actual customer complaints. The fix was to add a verification layer where the AI's output was checked against a curated knowledge base before being sent to the user. This added latency but prevented the damage. The token cost model is also something you need to understand before deploying at scale. Input tokens and output tokens are priced differently, and output tokens are usually more expensive. If your application generates long responses, the costs add up fast. I've seen projects where the inference costs were three times higher than expected because nobody calculated the average output length across the expected usage patterns. Plan for this. Estimate conservatively.
There's also the embedding problem. When you need to do similarity search or semantic retrieval, embeddings are essential. But not all embedding models are equal. OpenAI's text-embedding-3-small is good for general purposes, but domain-specific embeddings can dramatically outperform it. I once benchmarked a general-purpose embedding model against a domain-fine-tuned version for a medical literature search task. The domain-specific model was roughly 40 percent more accurate at retrieving relevant papers. That difference matters when you're building something people rely on.

What This Technology Can't Do
Let's be clear about the limitations. AI models don't have persistent memory between conversations unless you build it. They don't have true reasoning — they simulate reasoning by recognizing patterns in how reasoning is expressed in text. They can't reliably verify facts without external tools. They struggle with arithmetic, especially multi-step calculations, despite what some marketing materials suggest. And they will confidently hallucinate when pushed beyond their training distribution. If you're building a production system, assume the model will fail in edge cases you haven't anticipated. Build fallbacks, validation layers, and human review gates where appropriate. The best AI systems I've worked with treat the model as one component in a larger pipeline, not as the entire solution. RAG (retrieval-augmented generation) helps with factuality by grounding responses in verified sources. Tool use lets the model call calculators, search engines, and databases instead of relying on its internal knowledge. Guardrails and output validation catch obvious failures before they reach users. The state of the field moves fast. New models and techniques emerge regularly. What works today might be outdated in six months. The most useful skill isn't memorizing current best practices — it's understanding the underlying mechanics well enough to evaluate new approaches critically. Spend time reading the papers. Experiment with different providers and architectures. Learn what each model does well and where it breaks down. The rest will follow.


