
Why Your Simulations Keep Breaking at 3am
I spent six months building a thermal model for a defense contractor. The geometry was simple enough—cylindrical sensor housing, three materials, steady-state with a pulsed load. I wrote the mesh refinement loop, set the convergence criteria to 1e-6, and hit run. The solver came back at 0314 hours saying it had "converged." The results were physically impossible. Temperature at the sensor core exceeded the melting point of the housing material by four hundred degrees, and the heat flux vector pointed into the cold boundary. The issue wasn't the code. It wasn't the physics either. The mesh was fine. The boundary conditions were correct. The problem was that I had set up the conjugate gradient solver without checking the preconditioner. The matrix was ill-conditioned because the thermal conductivity ratio between the copper leads and the polymer insulation spanned three orders of magnitude. The solver found a numerical solution to the linear system, but it wasn't the solution—it was some other solution that happened to satisfy the tolerance check. My convergence criterion was too tight for the solver's actual precision. I needed a preconditioner that could handle the scale disparity, or I needed to reformulate the problem in terms of dimensionless numbers from the start.
The Art Of Doing Science And Engineering
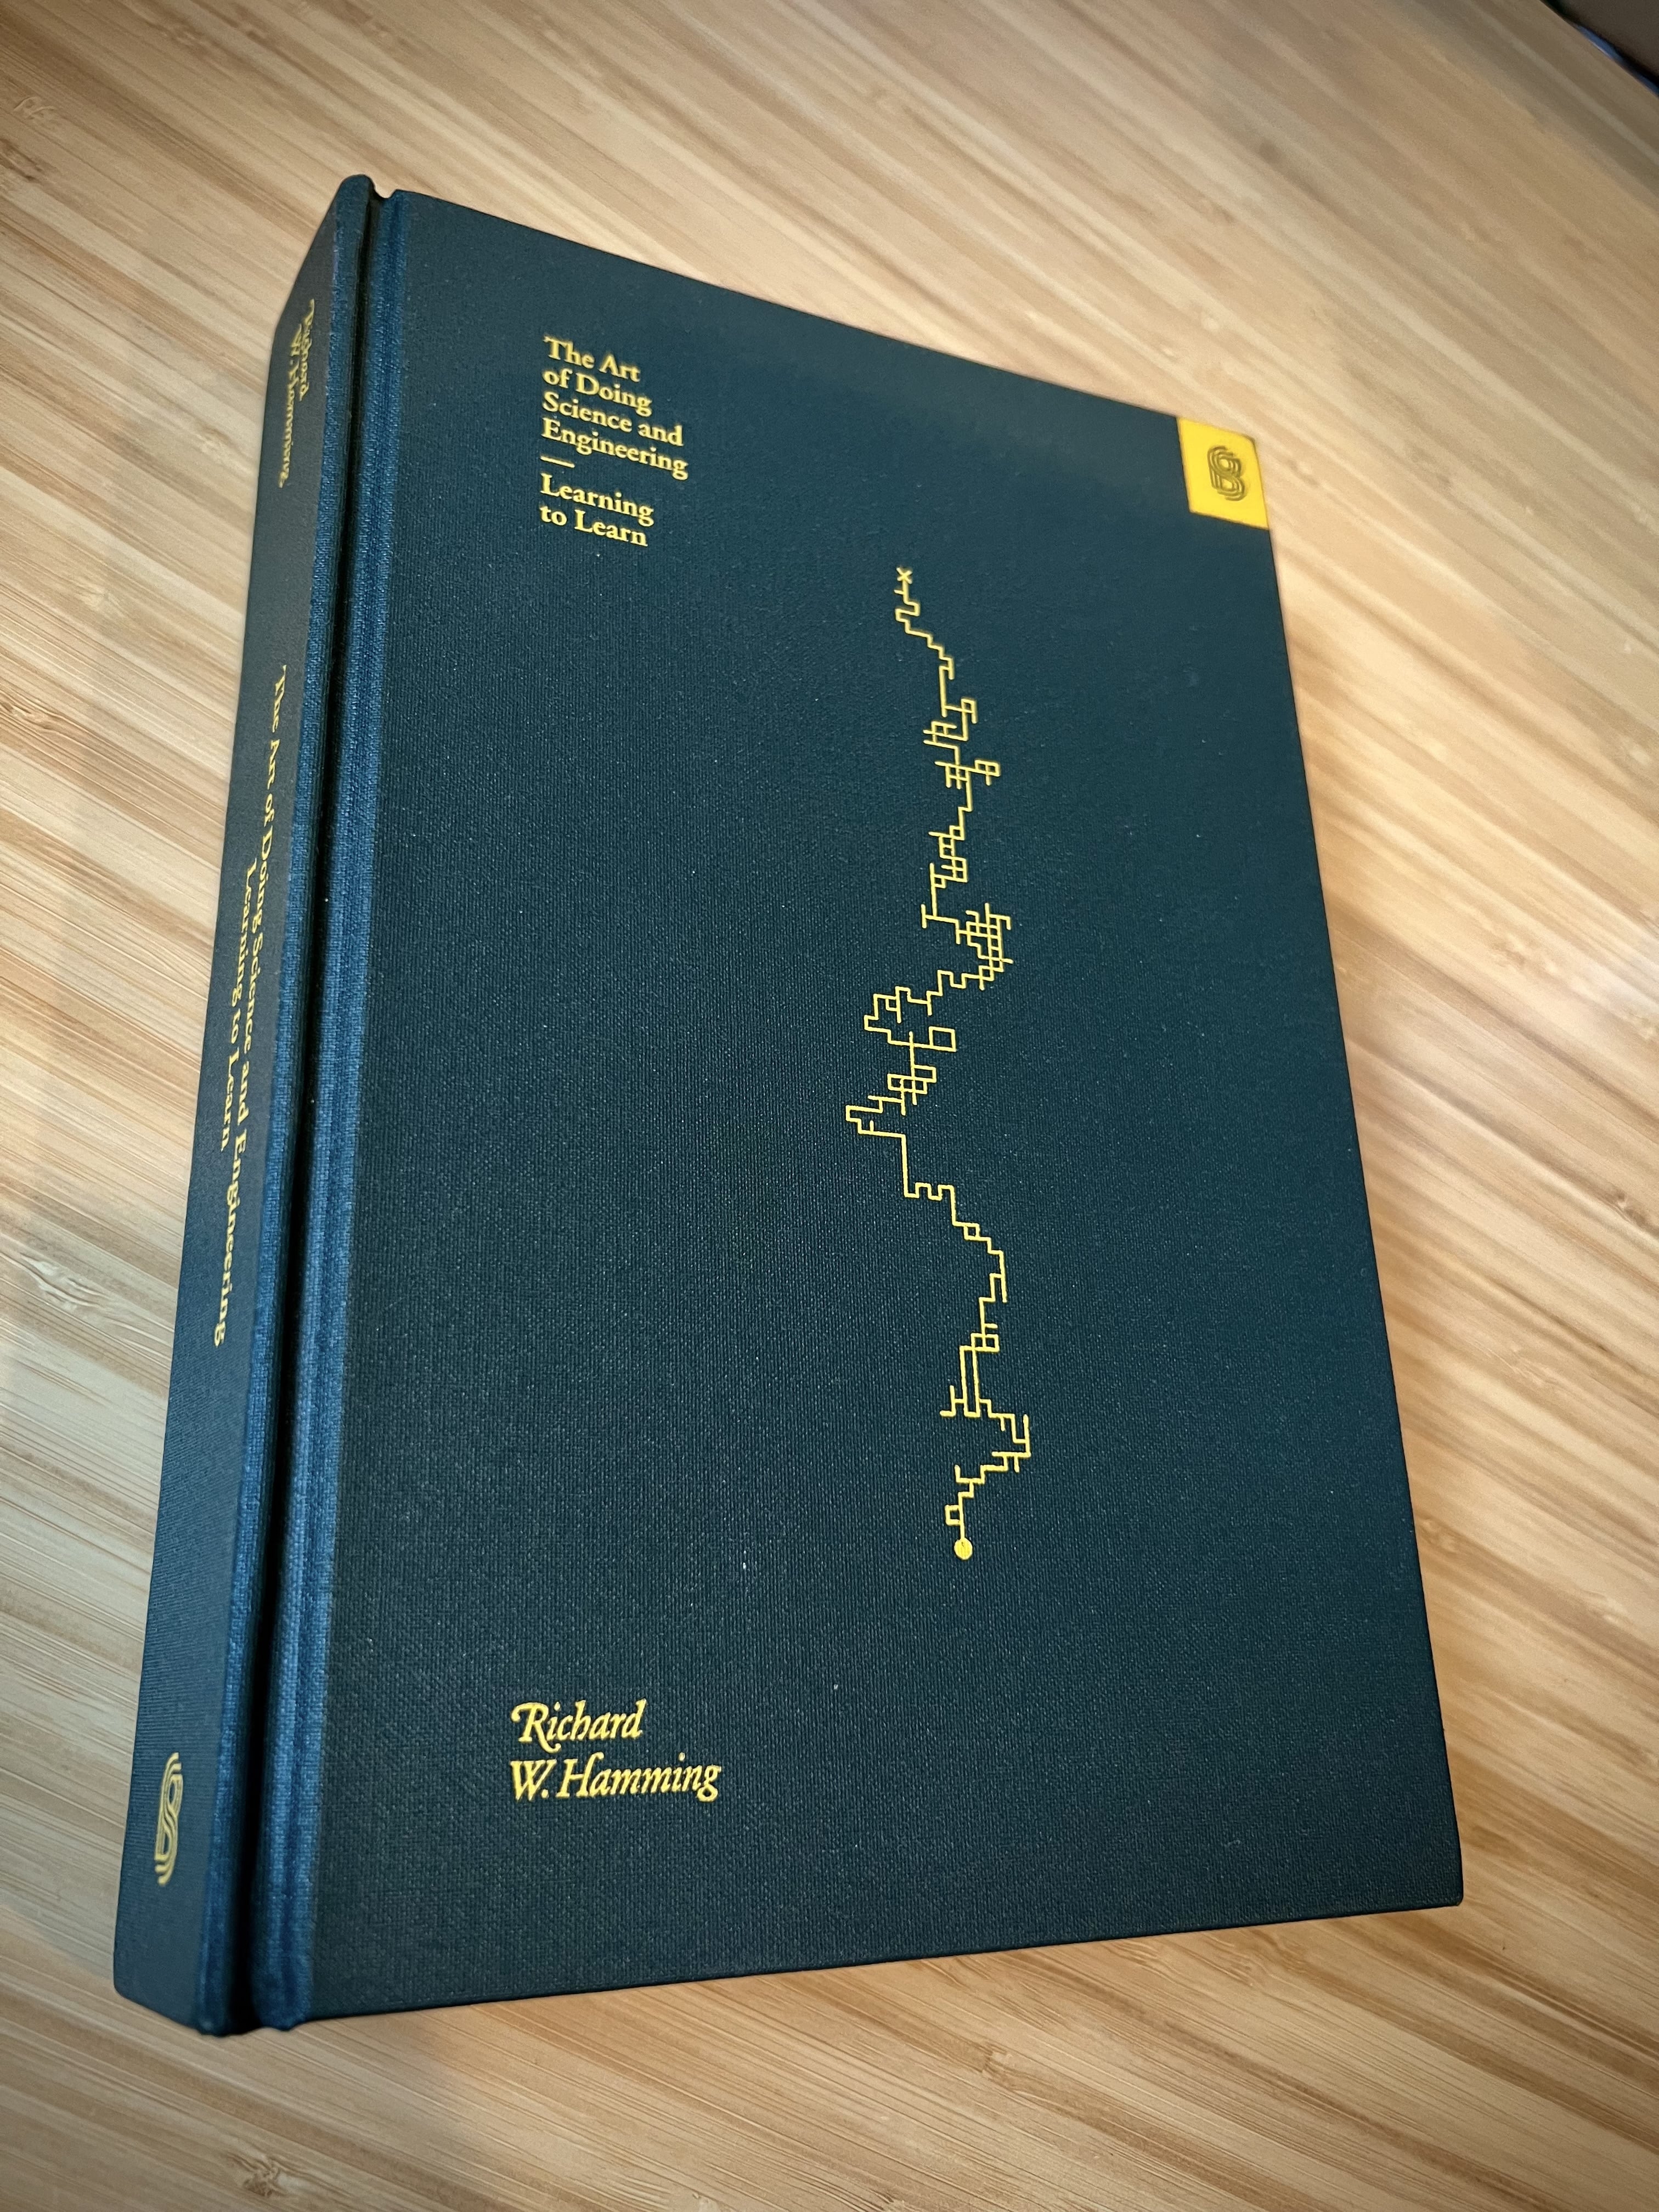
Richard Hamming wrote a short book about this. Not the math. Not the tools. The actual practice of figuring out what matters and then doing it. Most people who read it treat it as motivation. It isn't. It's a technical manual for dealing with the fact that 90 percent of your effort will produce results you discard, and the remaining 10 percent will still require another year of iteration before anyone considers it done. The central insight is deceptively simple: you have to think about thinking. Not in a self-help way. In a rigorous way. When you are setting up an experiment, writing a simulation, or deriving a model, you should be aware of the assumptions you are carrying and how each one could fail. Hamming calls this being "first" in your field. Being first doesn't mean being the fastest person to publish. It means being the person who actually solved the right problem, with the right level of rigor, before anyone else realized they needed to solve it. Here is what that looks like in practice, stripped of the inspirational packaging.
You communicate openly. This sounds like advice for social events. It isn't. Open communication is a correctness mechanism. When you share your methods, your failures, your questionable assumptions with people who can actually critique them, you compress the time it takes to discover that your approach is wrong. I worked with a structural engineer once who never showed his FE models to anyone until they were polished for a presentation. He spent fourteen months building a model of a wing attachment point. At the review, someone asked him how he had accounted for fatigue crack initiation at the weld toes. He hadn't. Not because he didn't know about fatigue, but because no one he talked to during the was working on fatigue. If he had shown the model to a materials person at week two, he would have saved eleven months. The cost of showing incomplete work is embarrassment. The cost of not showing it is wasted time. You know when to drop a problem. This is the part most people get wrong because they confuse persistence with stubbornness. There is a difference. Persistence is continuing with a problem because you have evidence it is solvable and you are making progress, even if slow. Stubbornness is continuing because you have already invested too much to admit it was the wrong direction. Hamming gives a practical rule: at regular intervals, ask yourself whether you would start this problem today if you didn't already know how much work you had put into it. If the answer is no, drop it. Move to a different problem. Come back in six months if something changes. I dropped a spectral analysis project after eight months because the noise floor of the experimental setup was systematically corrupting the high-frequency content I needed. Every workaround I tried introduced a new artifact. I switched to time-domain analysis, which was messier but more honest about what the data could support. Two years later, someone published a paper using a completely different sensor architecture that eliminated the noise problem entirely. I would have been first if I hadn't been stuck on the original approach. I wasn't last, but I was late, and in this field, late is functionally the same as wrong.
Get the Full Details

You write things down. Not for posterity. For yourself. Your brain is terrible at holding detailed intermediate states across days of work. I keep a running notebook for every active project. Not a polished log. Just dates, what I tried, what happened, what I think went wrong. Six months later, when I come back to a problem and think I am approaching it fresh, I open the notebook and see that I already tried the obvious solution and it failed for reason X. Without the notebook, I would have spent three weeks reproducing that failure before remembering to check. There is a tradeoff here. Writing everything down slows you down in the short term. You lose maybe twenty minutes a day to documentation. Over a year, that is roughly eight hours. The return is that you never waste a week re-deriving something you already derived. The net gain is substantial if you stay on a project long enough for the compounding to matter.
The Practical Mechanics
Setting up a computation or experiment properly requires three things: a clear question, a defensible method, and a realistic timeline. Most failures happen because one of these is weak. The question should be specific enough that you can tell when it is answered. "Improve the efficiency of the thermal management system" is not a question. "Reduce the peak temperature of the sensor housing by at least 30°C under the specified pulse cycle without exceeding the mass budget" is. You can measure the second one. You cannot measure the first. The method should be defensible not because it is the best available method, but because you can articulate its limitations. Every modeling choice has a failure mode. Finite element methods struggle with discontinuities. Analytical solutions struggle with complexity. Empirical correlations struggle outside their calibration range. Write down which category your method falls into and where it breaks. This isn't academic honesty. It's risk management. When your results look wrong, you need to know which assumption is most likely to be the culprit so you can test it efficiently.
The timeline should include buffer time for the things that always go wrong. A rule I use: multiply your best-case estimate by three. Best case is the scenario where the code compiles on the first try, the experimental setup works without modification, and the data comes back clean. This scenario does not exist. Threex is closer to reality. If you deliver early, you look good. If you deliver on the revised timeline, you look competent. If you deliver on the best-case estimate, you are either lying or you haven't done the work yet.
What Nobody Tells You About Iteration
Iteration is not progress if you are iterating in the same direction. I saw a graduate student spend nine months tuning a control algorithm for a robotics project. The performance improved marginally over each iteration, but the improvement came from compensating for a sensor calibration error that nobody caught. The algorithm got better at working around a broken measurement. Meanwhile, the actual dynamics of the system were underperforming because the controller was spending all its authority correcting for noise instead of tracking the trajectory. The fix was simple once someone noticed. recalibrate the sensor. But getting there required breaking out of the iteration loop and stepping back to ask whether the input data was trustworthy. This is harder than it sounds because iteration feels like work. Stopping to question your assumptions feels like laziness. It isn't. It is the difference between running faster on a wrong path and walking onto the right one. There is also a dimension to iteration that people miss: you should iterate on your methods as much as on your results. If you find yourself doing the same type of calculation three times, automate it. If you are running the same simulation with slightly different parameters, write a script that does it for you. The time you save on the third run pays for the time you spent writing the script on the first run, usually within two or three iterations. I wrote a Python script once that took forty minutes to generate. It automated a process that used to take me three hours per run. I broke even on the fourth run. Everything after that was pure gain.
Common Failure Modes
The most common failure mode is solving the wrong problem with high precision. This happens when the math is elegant and the question is vague. A clean equation is seductive. It makes you feel like you are making progress even if you are answering something nobody cares about. I spent two weeks deriving a closed-form expression for a heat transfer coefficient in a geometry that doesn't exist outside of textbook problems. The derivation was correct. The result was useless. I could have known this in thirty minutes if I had checked whether the geometry matched the actual hardware before investing the time. Another failure mode is overfitting your model to noise. This is especially dangerous in engineering because experimental data is never clean. If you tune your model parameters to match every fluctuation in your data, you are fitting the noise, not the physics. The model will look accurate for your current dataset and fail catastrophically on new data. Regularization helps, but the simplest check is to split your data. Train on one subset, validate on another. If the validation error is significantly higher than the training error, you have overfit. Cut the model complexity or get more data. A third failure mode is ignoring scale. Problems that look manageable at one scale can become intractable at another. A fluid dynamics simulation that runs fine on a single processor at laminar flow conditions will not transition to turbulence simply by changing the Reynolds number. The computational cost increases by orders of magnitude. I learned this the hard way when I tried to upscale a 2D laminar flow simulation to 3D turbulent flow without adjusting the mesh strategy or the solver. The runtime went from hours to weeks, and the results were no more accurate because the turbulence model was inappropriate for the grid resolution I was using. Switching to a RANS model with an appropriate wall function cut the runtime back to hours and gave results that matched the experimental data within five percent.
What This Approach Doesn't Do
The Art Of Doing Science And Engineering is not a method for guaranteeing success. It is a method for reducing the probability of wasting your time. You will still hit problems you can't solve. You will still choose the wrong direction at least once. The value is in recovering faster and making fewer repeated mistakes. It also doesn't replace technical skill. Knowing when to drop a problem is useful only if you have enough expertise to recognize that a problem is unsolvable with your current approach. A beginner might drop a problem prematurely because they don't understand the tools well enough to push through. An expert might persist too long because they can see a path that isn't obvious. Both errors are real. The framework helps you notice which error you are making, but it doesn't eliminate the need for judgment. There is also a social dimension that this approach underplays. Science and engineering are collaborative activities, even when the work is individual. The recommendations around communication and open sharing assume a culture that supports them. In environments where people hoard information or punish failures publicly, following these guidelines can make your career harder, not easier. I have seen this firsthand. The people who benefited most from open collaboration were in departments where senior researchers had built reputations for giving credit where it was due. In departments where credit was monopolized, sharing your work early meant someone else could take the idea and publish it before you finished your own version.

If you are in that situation, the practical workaround is selective sharing. Share the general approach, not the specific results. Describe the method without the data that proves it works. This gives you the benefit of external feedback on your reasoning while retaining the ability to publish the complete picture first. It is a compromise. It isn't ideal. But it is better than staying silent and finding out six months later that someone else solved the same problem using a slightly different approach and got the citation. The book itself is short. Maybe eighty pages in most editions. It doesn't contain equations or algorithms. It contains observations about how people actually work, distilled from Hamming's experience at Bell Labs over several decades. The observations are dated in places. Some of the examples reference technology that no longer exists. The core advice—think about thinking, communicate openly, know when to stop, write things down—still holds. What the book doesn't cover is the emotional side of this work. The frustration of a failed experiment. The anxiety of a deadline approaching with incomplete results. The loneliness of working on a problem that nobody else in your organization understands well enough to discuss. None of that is addressed. It should be. But it isn't, and the book is still worth reading because the technical advice is sound and the warnings are specific enough to be useful rather than vague enough to be dismissible.
I keep a copy on my desk. Not because I need to be reminded of these things regularly, but because I need to remember that I will forget them. The principles are obvious when you read them. They are easy to ignore when you are tired, behind schedule, and facing a problem that won't resolve no matter how hard you push. That is when the framework is most useful, and also when you are least likely to consult it. The workaround is to write the key points on a card and keep it next to your monitor. Not as inspiration. As a checklist. Checklist: What is the actual question? What are the limitations of my method? Would I start this today if I didn't already have invested time in it? Have I shown this to someone who can critique it? What is the fallback if this approach fails? Answering those five questions takes about ten minutes. It has saved me more time than any tool or technique I have learned.


