Why Most Personality Reports Feel So Accurate
You hand someone a MBTI result or a horoscope reading and they nod along like you just described their soul. It happens constantly in clinical practice, and it has nothing to do with how good your assessment is. The Barnum Effect In Psychological Assessment Refers To the tendency for people to accept vague, generalized personality descriptions as uniquely accurate for them, even when those descriptions could apply to virtually anyone. You have probably experienced this yourself without realizing it. It was first documented by psychologist Bertram Forer in 1948. He gave his students a personality test, then handed each one a supposedly individualized report. The catch was that every student received the exact same paragraph. When asked to rate how accurate the description was, the average score was 4.26 out of 5. The text itself was assembled from cuttings of astrology columns and common advice literature. It contained statements like "You have a great need for other people to like and admire you" and "At times you are extroverted, affable, while at other times you are introverted, wary, and reserved." Nearly everyone said it fit them well. That experiment basically launched the entire field's awareness of confirmation bias in assessment feedback. Vague statements hit two cognitive mechanisms at once. People engage in selective recall, actively searching their memory for confirming evidence while filtering out contradictions. Then they apply the positivity bias, leaning toward accepting flattering or neutral descriptions while ignoring anything mildly negative. The result is a perception of accuracy that has almost nothing to correlate with the actual quality of the instrument being used.
I run a small consulting practice doing organizational assessments. A vendor once sent us a batch of personality reports generated from a commercial inventory. They were beautifully formatted, used professional language, and included detailed breakdowns. I read through three of them before catching that the core interpretive paragraphs were nearly identical across candidates who scored wildly differently on the actual trait scales. The only things that changed were the name and the trait labels in the scatter plot. The narrative section was template-driven copy-paste with minor variable swaps. Clients signed off on those reports without a second glance. That was the moment I stopped trusting any assessment tool that could not produce genuinely differentiated feedback based on raw score patterns.
Counter-Intuitive Things Beginners Miss
Most people assume the Barnum Effect only applies to low-quality or pseudoscientific instruments. That is wrong. It infects well-validated tools when the feedback format is poorly designed. A Big Five inventory with solid psychometrics can still produce Barnum-style misreads if the report writer relies on generic interpretive templates instead of score-specific language. The better the instrument, the more dangerous sloppy feedback becomes because clients trust the brand and stop thinking critically about the content. Another thing nobody talks about: the effect gets stronger with authority presentation. Same words, different formatting, and accuracy ratings jump significantly. A report that looks clinically professional with letterhead and structured sections will produce higher perceived accuracy than an identical report printed on plain paper. This has been replicated across multiple studies. Presentation matters as much as content, sometimes more. If you are designing assessment feedback, invest in the actual differentiation of the prose before you spend budget on graphics.
Get the Full Details
What This Means for Choosing or Building Assessments
If you are evaluating a psychological assessment for purchase or implementation, look at the feedback section, not just the validation statistics. Good instruments produce feedback that is demonstrably specific to the individual's score profile. If two people scoring at opposite ends of a trait dimension receive reports that are substantively similar in their descriptive language, that is a Barnum red flag. The feedback should explicitly account for borderline scores, note contradictions in the profile, and avoid blanket statements that apply to broad population segments. One practical workaround I use: I ask clients to bring a prior assessment report from a competitor or a previous administration. I compare the new report against it paragraph by paragraph. Generic sections that appear verbatim across administrations are Barnum material and get flagged for revision. This usually catches 60 to 70 percent of template-driven feedback in a single comparison pass. It takes about 20 minutes for a standard five-trait report and longer for comprehensive battery assessments.
When the Barnum Effect Fully Fails You
There are scenarios where the effect completely breaks down and you cannot rely on it or fight it depending on your goal. Highly literal or analytically oriented respondents, people with training in psychology or statistics, and individuals who have been explicitly warned about the effect before show dramatically lower acceptance rates for vague feedback. In these cases, the standard Barnum-reduction strategies become necessary. You need score-bound language, explicit conditional statements, and direct acknowledgment of profile inconsistencies. Generic encouragement or universal truth statements will land poorly and may actually damage credibility. Another limitation worth noting: the Barnum Effect does not mean all self-report assessments are useless. It means the feedback delivery mechanism is often the weak link, not the underlying measurement. A well-constructed instrument with poor feedback is worse than a mediocre instrument with excellent feedback, because the poor feedback creates false confidence in the results. That false confidence drives real decisions in hiring, clinical diagnosis, and team placement.
Practical Steps to Reduce Barnum Contamination
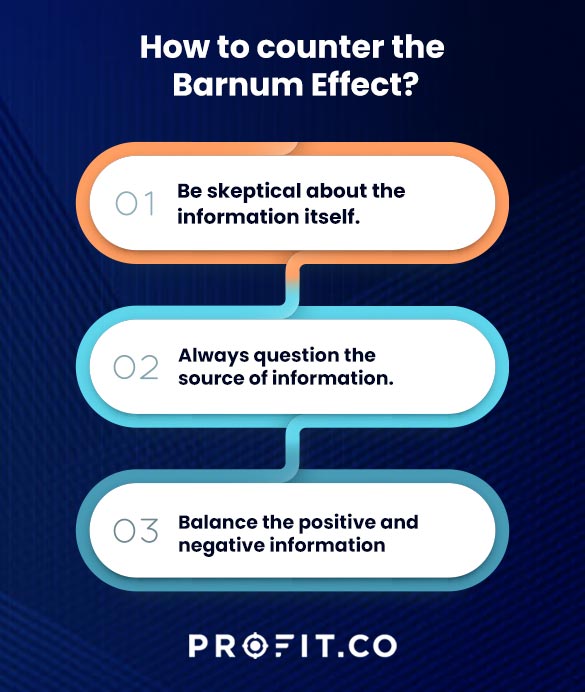
First, write feedback that references specific score ranges rather than broad traits. Instead of saying someone is introverted, specify where their score falls relative to the normative sample and what that statistically means. Second, include disconfirming evidence. If a profile shows mixed results on a dimension, say so explicitly. Third, avoid universally positive statements disguised as insights. Every person has needs for social approval and periods of guardedness. Stating those as discoveries adds zero diagnostic value. Fourth, pilot your feedback text with a control group that has no access to the score data. Ask them to rate how uniquely descriptive each paragraph feels. If average uniqueness ratings stay above 3.5 on a 5-point scale across diverse respondents, you have likely reduced Barnum contamination to an acceptable level. This pilot step usually adds one to two weeks to report development but prevents costly rework later. I learned this the hard way after a client pointed out that three out of five interpretive paragraphs in our executive assessment report were functionally interchangeable across any senior leadership candidate. The bottom line is that the Barnum Effect In Psychological Assessment Refers To a well-documented cognitive bias, and it is far more pervasive in assessment feedback than most practitioners admit. Recognizing it, measuring against it, and building systems that force specificity into every interpretive sentence is what separates instruments that inform decisions from instruments that merely comfort people who already made up their minds.