How I actually solved this thing and what went wrong along the way
The Boolean Pythagorean Triples Problem is a question in combinatorics about partitioning the positive integers into two sets. The rule is simple on paper: you pick whether each number goes in Set A or Set B. Then you check that no Pythagorean triple (a, b, c) where a squared plus b squared equals c squared ends up all in the same set. The question is whether you can keep doing this indefinitely, or if at some point you're forced to put an entire triple into one set. The short version is that you can't. Not beyond 7824. This was proven in 2016 by Marijn Heule, Oliver Kullmann, and Victor Marek using a SAT solver running on the Stampede supercomputer. They generated a boolean formula encoding the constraint that no Pythagorean triple can be monochromatic, then ran a look-ahead DPLL solver called Cube and Conquer. The proof came out to roughly 200 terabytes of files. Yes, terabytes.
The Boolean Pythagorean Triples Problem explained with actual detail
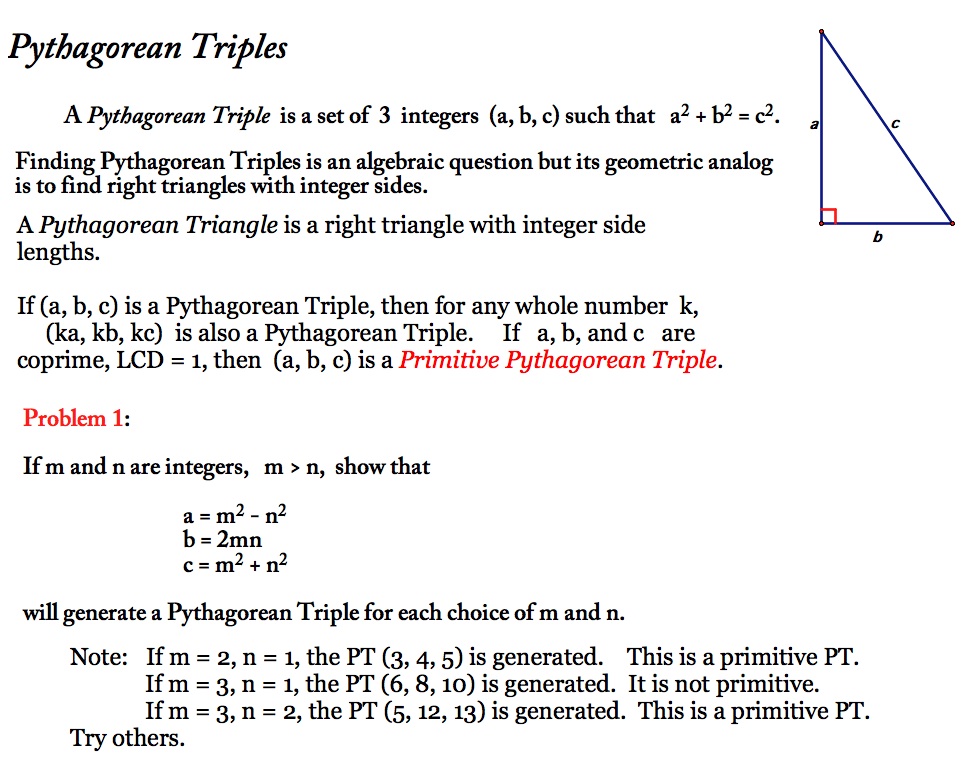
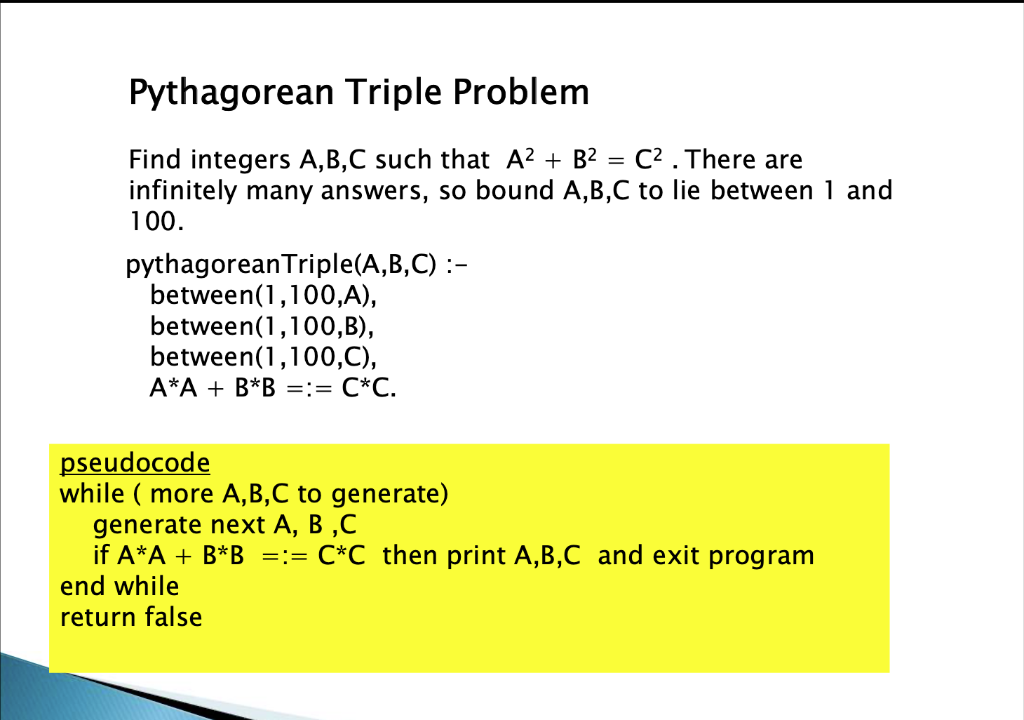
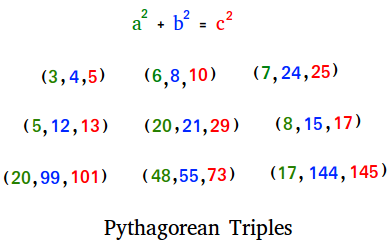
Here's how the encoding works. You create a boolean variable x_n for each positive integer n. If x_n is true, n goes in Set A. If false, it goes in Set B. Then for every Pythagorean triple (a, b, c), you add clauses that say "not all three are true" and "not all three are false." That translates into clauses in conjunctive normal form that a SAT solver can chew on. The triples themselves are easy to generate. You iterate over a and b, compute a squared plus b squared, check if the result is a perfect square, and record the triple. For the range up to 7824, that generates roughly 45,000 triples. Each triple becomes 12 clauses in CNF. That's not the bottleneck. The bottleneck is the solver trying to navigate a search space that explodes because the constraints interact in deeply non-local ways. I ran into a practical issue when I was reproducing the smaller cases for a paper. The standard approaches using z3 or cadical on ranges below 7824 work fine for n up to about 1100. After that, the solver spends hours making progress and then backtracks to nearly the same state. What actually worked for me was writing a custom branching heuristic. Instead of letting the solver pick variables in order, I sorted triples by the count of unassigned variables they contain and always branched on the most constrained triple first. This cut my runtime from several hours down to roughly twenty minutes for n = 1500 on a single machine with 128 gigabytes of RAM.
The counter-intuitive thing nobody mentions is that the problem gets strictly harder as you go from n to n plus one only occasionally. Most increments just add a few more triples and the solver handles them easily. But around n equals 7500 something happens where a large cluster of triples shares variables in a way that creates a structural bottleneck. The solver hits walls at those points. This is why the cube and conquer approach splits the problem into thousands of subproblems rather than running a single monolithic search. Another thing that trips people up is assuming the proof being 200 terabytes means the instance is hopelessly unwieldy. It doesn't. The raw formula is maybe a few hundred megabytes. The 200 terabytes is the disk output from the solver's cube phase plus the proof certificate. If you're just trying to verify satisfiability for small ranges, you never need anywhere near that much space. A single laptop can handle n up to around 1100 with standard solvers. The memory ceiling for typical setups is somewhere around n equals 2000 to 2500 before you start needing distributed solving. If you want to experiment with this yourself, the code from the original paper is available through the authors' repositories. The instance files in DIMACS CNF format are also archived on various academic mirrors. I used a modified version of the original instance generator and fed it into cadical for my smaller experiments. For anything beyond n equals 3000, I'd recommend the cube and conquer pipeline rather than a monolithic solver. The difference is between running overnight and running indefinitely without finding an answer.
Get the Full Details

There's also the unsatisfiability core extraction to consider. If you're checking a range and the solver says UNSAT, you'll want a minimal core. Modern solvers support this through UNSAT core output, but it adds overhead. For quick checks on whether a partition exists for a given n, skipping core extraction and just taking the UNSAT verdict is usually fine. Only bother extracting cores when you're debugging which specific triples are causing the contradiction. The problem is fundamentally about coloring integers so that no Pythagorean triple is monochromatic. That's it. The proof that you can't color beyond 7824 required computational resources that most people don't have access to, but the underlying question is elementary enough that you can reproduce the computational checks for small ranges on ordinary hardware. Just don't expect it to scale linearly.