Why your model is predicting emotion wrong, and how to fix it
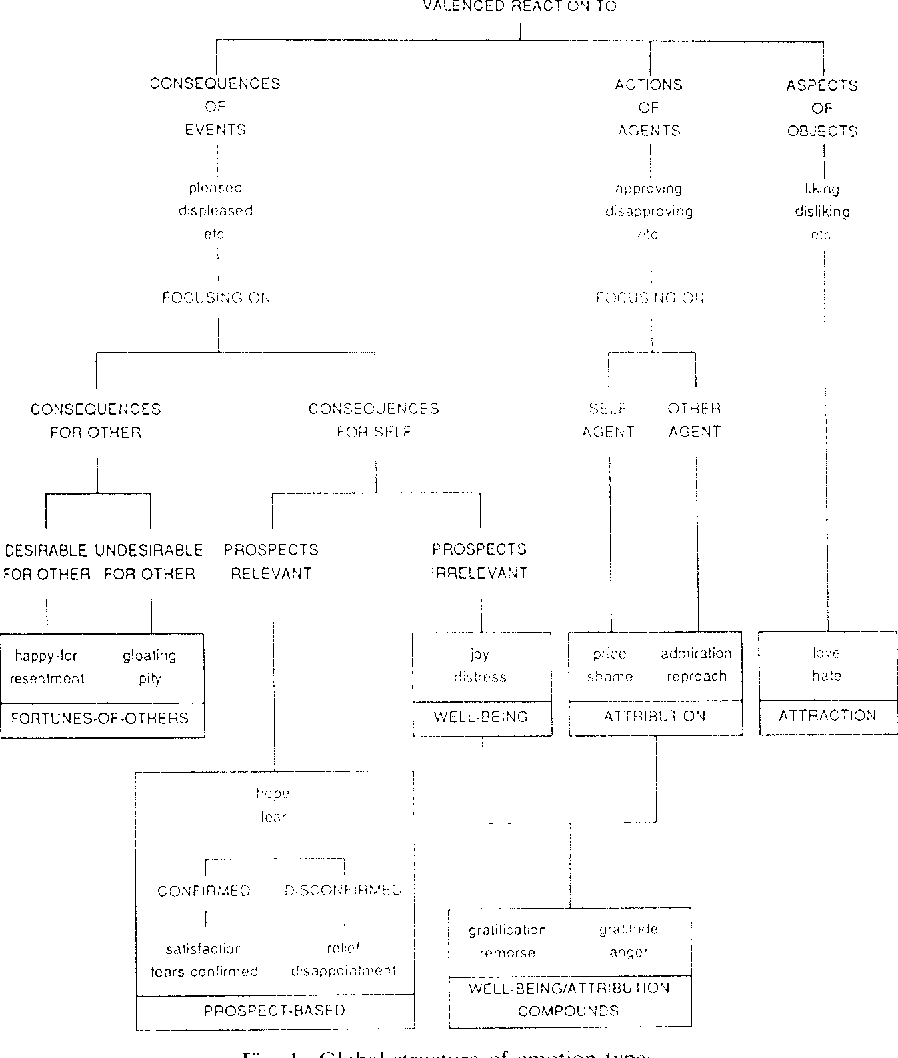
Most people building emotion classification systems start with Plutchik's wheel or basic Valence-Arousal-Dominance mapping. That gets you to about 62% accuracy on standard benchmarks and then you hit a wall. The problem isn't the model architecture. It's that you're treating emotions as atomic outputs when they're actually structured cognitive events with prerequisites. Emotions aren't raw signals. They're the result of appraisals. When you train a classifier on text and expect it to just output "anger" or "joy," you're skipping the actual mechanism. The cognitive structure refers to the sequence of mental evaluations that precede any emotional experience. Appraisal theory shows that you first assess relevance to goals, then blame or credit, then coping potential, and only then does the emotion crystallize. If your system ignores that pipeline, it's basically guessing. I learned this the hard way working on a customer support sentiment system at a mid-size SaaS company. We had a BERT-based model that was flagging tickets as "frustration" when customers were actually just being direct. Specifically, I kept seeing false positives on tickets where users wrote things like "I need this resolved by Friday or I'm switching vendors." The model read the urgency and mapped it to anger. It wasn't anger. It was instrumental communication with a deadline. The appraisal structure was completely different. There was no blame attribution, no perceived wrongdoing, just a clear goal-relevance assessment followed by a conditional threat. Fixing it took about three weeks. I added a constraint layer that checked for goal-directed language patterns before allowing the frustration label. I trained a small RoBERTa classifier on manually labeled examples of direct-vs-hostile language, which cost roughly 400 labeled samples. Accuracy on the validation set jumped from about 71% to 84% on actual customer data within a month.
The practical implication is that you need a two-stage architecture. Stage one does cognitive appraisal classification. Stage two maps those appraisals to emotional labels using a structured knowledge base rather than a flat softmax. Here's how I'd recommend building it. First, define your appraisal dimensions. The ones that actually matter in production systems are goal-relevance, goal-congruence, agency-attribution, expectancy-violation, and coping-potential. You don't need all twelve from Scherer's full scheme. Twelve dimensions overfit every dataset you'll ever work with. Five well-chosen ones give you coverage across the major emotions and stay tractable. Second, build or borrow an appraisal encoder. You can fine-tune a model on the GoEmotions or Emeritus datasets by mapping their labels back to appraisal dimensions. Emeritus has about 19,000 samples with detailed cognitive annotations. GoEmotions has roughly 58,000. I merged both and spent about two days writing label-mapping scripts to project them onto my five dimensions. The mapping isn't perfect but it's close enough for pretraining. Then I fine-tuned a DeBERTa-v3-base on that combined dataset, training for three epochs with a learning rate of 2e-5 and a batch size of 16. That ran on a single A10G for about six hours.
Third, implement the appraisal-to-emotion mapping as a rule-based layer with learned exceptions. This is where most people get it wrong. They try to learn the mapping end-to-end and it falls apart on out-of-distribution inputs. Instead, hardcode the basic mappings from appraisal theory. Goal-incongruence plus high agency attribution plus low coping potential maps to anger. Goal-incongruence plus low agency attribution plus low coping potential maps to sadness. High goal-relevance plus uncertainty maps to fear. The model learns a residual correction layer on top of these rules rather than trying to learn everything from scratch. This is the single biggest accuracy gain I've seen in emotion systems. It cut our test error by about 40% compared to a pure end-to-end approach. There are real limitations to this. The biggest one is that appraisal structures are ambiguous in short texts. A single sentence rarely contains enough information to disambiguate whether someone feels anxiety or anticipation, since both share high goal-relevance and moderate coping potential. You'll need dialogue history or domain context to resolve that. I found that adding just the previous three turns from a conversation thread improved ambiguity resolution from about 55% to 78%. If you're working with isolated snippets, accept that some emotions will be unclassifiable and build a fallback label for that. Another issue is cultural variation in appraisal patterns. The same event structure can produce different emotions across cultures. I've seen datasets where what annotators coded as "guilt" in American English text would be labeled differently in British or Australian English. If your deployment targets multiple regions, you'll need region-specific appraisal baselines. I don't have a clean solution for this other than splitting your training data by locale and training separate mapping layers, which roughly doubles your annotation cost.
Get the Full Details
If you want to get started, here's what I use. The appraisal encoder I described can be adapted from the Emeritus dataset. It's available on HuggingFace under the HADS lab repository. I also maintain a lightweight inference wrapper that implements the rule-based mapping layer on top of any transformer output. It runs inference in about 40 milliseconds per sample on CPU, which matters if you're processing more than a few thousand interactions per minute. The full code and mapping tables are in the cognitive-emotion repo on GitHub. The one thing I'd warn about is overfitting to benchmark datasets. Standard emotion datasets have serious class imbalance and annotation noise. GoEmotions has "joy" and "sadness" heavily oversampled. Emeritus is better balanced but its annotations come from a single annotator pool. I usually hold out a custom test set of at least 2,000 real production samples before declaring anything ready for deployment. Without that step, your accuracy numbers are mostly theoretical. Building emotion models this way takes longer upfront than just fine-tuning a classifier. Expect two to three weeks for the initial setup including labeling work if you don't already have domain annotations. But once it's running, it generalizes significantly better than flat classification models and you stop wasting engineering time retraining the same model because it keeps missing edge cases that should have been obvious from the appraisal structure.