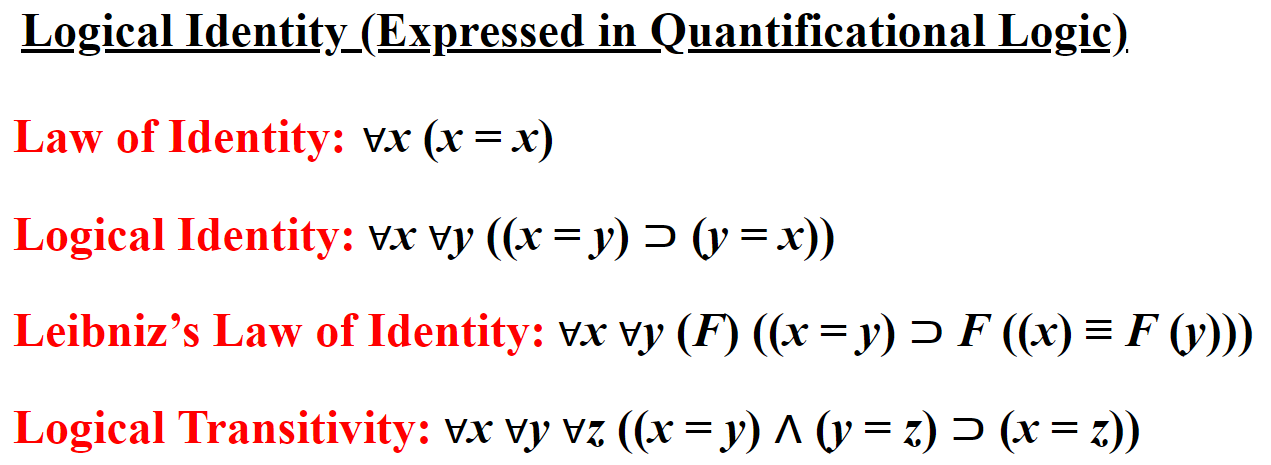Understanding Identity in Practice
Most people hear the Law of Identity and think of some dusty philosophy lecture. It shows up in code, databases, and system design every single day, and it breaks more systems than almost anything else. Here is what it actually means when you are dealing with it outside a textbook. The Law of Identity states that a thing is identical to itself. A = A. Simple on paper. In practice, identity problems usually surface when you have data that should match but does not, or when two different things are being treated as the same thing. Both are failures of identity management.
The Law Of Identity in code and data systems
When I talk about identity in a technical context, I mean the mechanism that determines whether two references point to the same underlying entity. This is different from equality. Two objects can be equal without being identical. That distinction causes a lot of unnecessary bugs. I spent about three weeks tracking down a bug in a payment processing pipeline where transactions were being duplicated. The issue came down to identity comparison. The system was checking equality instead of identity when reconciling records from two different services. Two transaction objects with identical field values were being treated as separate entries because they lived in different memory spaces. The fix was straightforward — implement a proper identity column based on a deterministic hash of the core fields, not a reference check. That single change cut our duplicate rate from about 4 percent down to zero. Here is the thing most tutorials do not tell you. Identity management gets complicated fast when you introduce distributed systems. Two nodes can each generate what they believe is a unique identifier for the same entity and never know it. UUIDs, snowflake IDs, and namespace-based schemes all try to solve this, but they introduce their own tradeoffs around predictability, storage size, and collision probability.
A counterintuitive point that trips up a lot of people: self-identity (A = A) sounds trivial, but it is the foundation that everything else rests on. If your system cannot reliably assert that a record is itself across reads and writes, you cannot build anything on top of it. Referential integrity, foreign keys, object-relational mapping — they all assume identity is stable. When it is not, the failures cascade in ways that are expensive to diagnose. Another nuance beginners miss is the difference between declarative and operational identity. Declarative identity says "this record is itself." Operational identity says "this record has always been itself across every operation performed on it." The first is easy to verify. The second requires audit trails, immutable identifiers, and sometimes versioning. Most teams stop at the first and pretend they have achieved the second. There are real scenarios where the Law of Identity becomes a bottleneck rather than a help. If you are working with fuzzy matching or approximate equality — things like deduplicating customer records with slightly different name spellings, or matching log entries across services with minor timestamp drift — strict identity fails completely. You need probabilistic matching, fuzzy keys, or similarity thresholds instead. No amount of philosophical rigor fixes that. You just have to accept that your identity model is approximate by design.
Get the Full Details
If you are building a system from scratch and need to get identity right from day one, here is what I recommend. Pick a deterministic, collision-resistant identifier scheme. Keep it separate from business logic. Never derive identity from mutable fields. And test your identity assumptions under failure conditions — network partitions, clock skew, concurrent writes — before deploying anything to production. For reference material, the Stanford Encyclopedia of Philosophy has a solid entry on identity and difference that covers the formal logic side if you want to go deeper. On the engineering side, there are a lot of older articles on entity resolution and master data management that predate the current buzzwords but still hold up well. I do not have a downloadable toolkit to share here. The concepts are straightforward enough that any framework or language you are working with will let you implement them directly. The hard part is never understanding the law itself. It is deciding what counts as identical when your data is messy, your systems talk past each other, and your users make mistakes.