Unintended Consequences in Software Architecture
Most engineers hear the Law Of Unintended Consequences as a moral lesson rather than a practical warning. It is both. I have watched teams implement features that worked perfectly in isolation and still managed to break production, cost three times what was forecast, or create security holes they were actively trying to close. The pattern repeats across domains. I will focus here on software systems because that is where I have seen it most clearly, and where the fix is also the most concrete. The Law Of Unintended Consequences simply states that actions in complex systems produce outcomes that were not anticipated by the actors. That sounds obvious until you see it destroy a rollout. In software, the usual catalyst is optimization. You optimize for one metric, the system adjusts, and other metrics drift in directions nobody measured. This is not failure of execution. This is the property of complex adaptive systems: they compensate. I spent two weeks debugging a production outage in 2022 that traced back to a cache invalidation fix for a pricing service. The fix reduced latency by 40 percent. It also introduced a window where stale prices could serve during traffic spikes. Customers got cheaper prices, support tickets dropped, revenue dropped too. The incident took 11 hours to contain and cost roughly 840 thousand dollars in lost sales and engineering burn. The root cause was a retry storm triggered by cascading cache misses across three microservices. We had optimized for read latency and ignored failure-mode behavior under burst load. The workaround was to add circuit breakers on the pricing cache layer and enforce a soft-fail path that returned cached-but-stale prices with a metadata flag indicating low confidence. It cut containment time from hours to minutes on the next incident of the same type. The lesson was boring. Optimize the failure mode, not just the happy path.
How to think about it without panic
There is a useful way to approach this that does not require becoming paranoid. You treat every change as an experiment with measured boundaries. You define which metrics matter, which secondary metrics you will monitor, and what threshold triggers a rollback. You also accept that some consequences will remain hidden until scale arrives. That is unavoidable. The goal is not to predict everything. The goal is to make the unexpected discoverable sooner. I use a small checklist before any deployment that touches a core data path. It takes about five minutes and usually catches the things that become incidents later.
- Identify the primary metric being improved and how it is measured.
- List at least two secondary metrics that could degrade, even slightly.
- Define a rollback trigger with a quantitative threshold, not a gut feeling.
- Write a one-paragraph incident hypothesis: if this breaks, what is the most likely first symptom?
- Verify the hypothesis can actually be observed in your monitoring stack before you ship.
The last item is the part most teams skip. You can have great dashboards and still miss the signal because the right metric is not instrumented. I once shipped a latency improvement that looked good in synthetic tests but created tail-latency spikes visible only in customer-facing requests. The Synthetic health check passed. The real request distribution showed a long tail that did not exist before. Adding a p99 observer on the outer edge of the service cut that blind spot. People often conflate correlation with causation when they look at post-incident data. They see that a deploy happened near an outage and assume causation. Sometimes that is true. Sometimes the deploy was coincidental. The difference matters because the fix is different. If the deploy caused the issue, you patch the deploy. If it was coincidental, you patch the underlying condition, which is usually a dependency or a data quality problem. I have spent months chasing deployment processes that were not the problem while a flaky DNS resolver ate our day. Another frequent error is treating unintended consequences as purely technical. They are also organizational. A policy change in one team can create perverse incentives in another. When we introduced a strict SLO on error rates for our payment service, the support team started classifying legitimate failures as transient errors to keep the number down. The metric stayed green. The business kept losing money on bad transactions. The fix required changing the definition of what counted as an error and aligning it with finance, not just engineering.
Get the Full Details
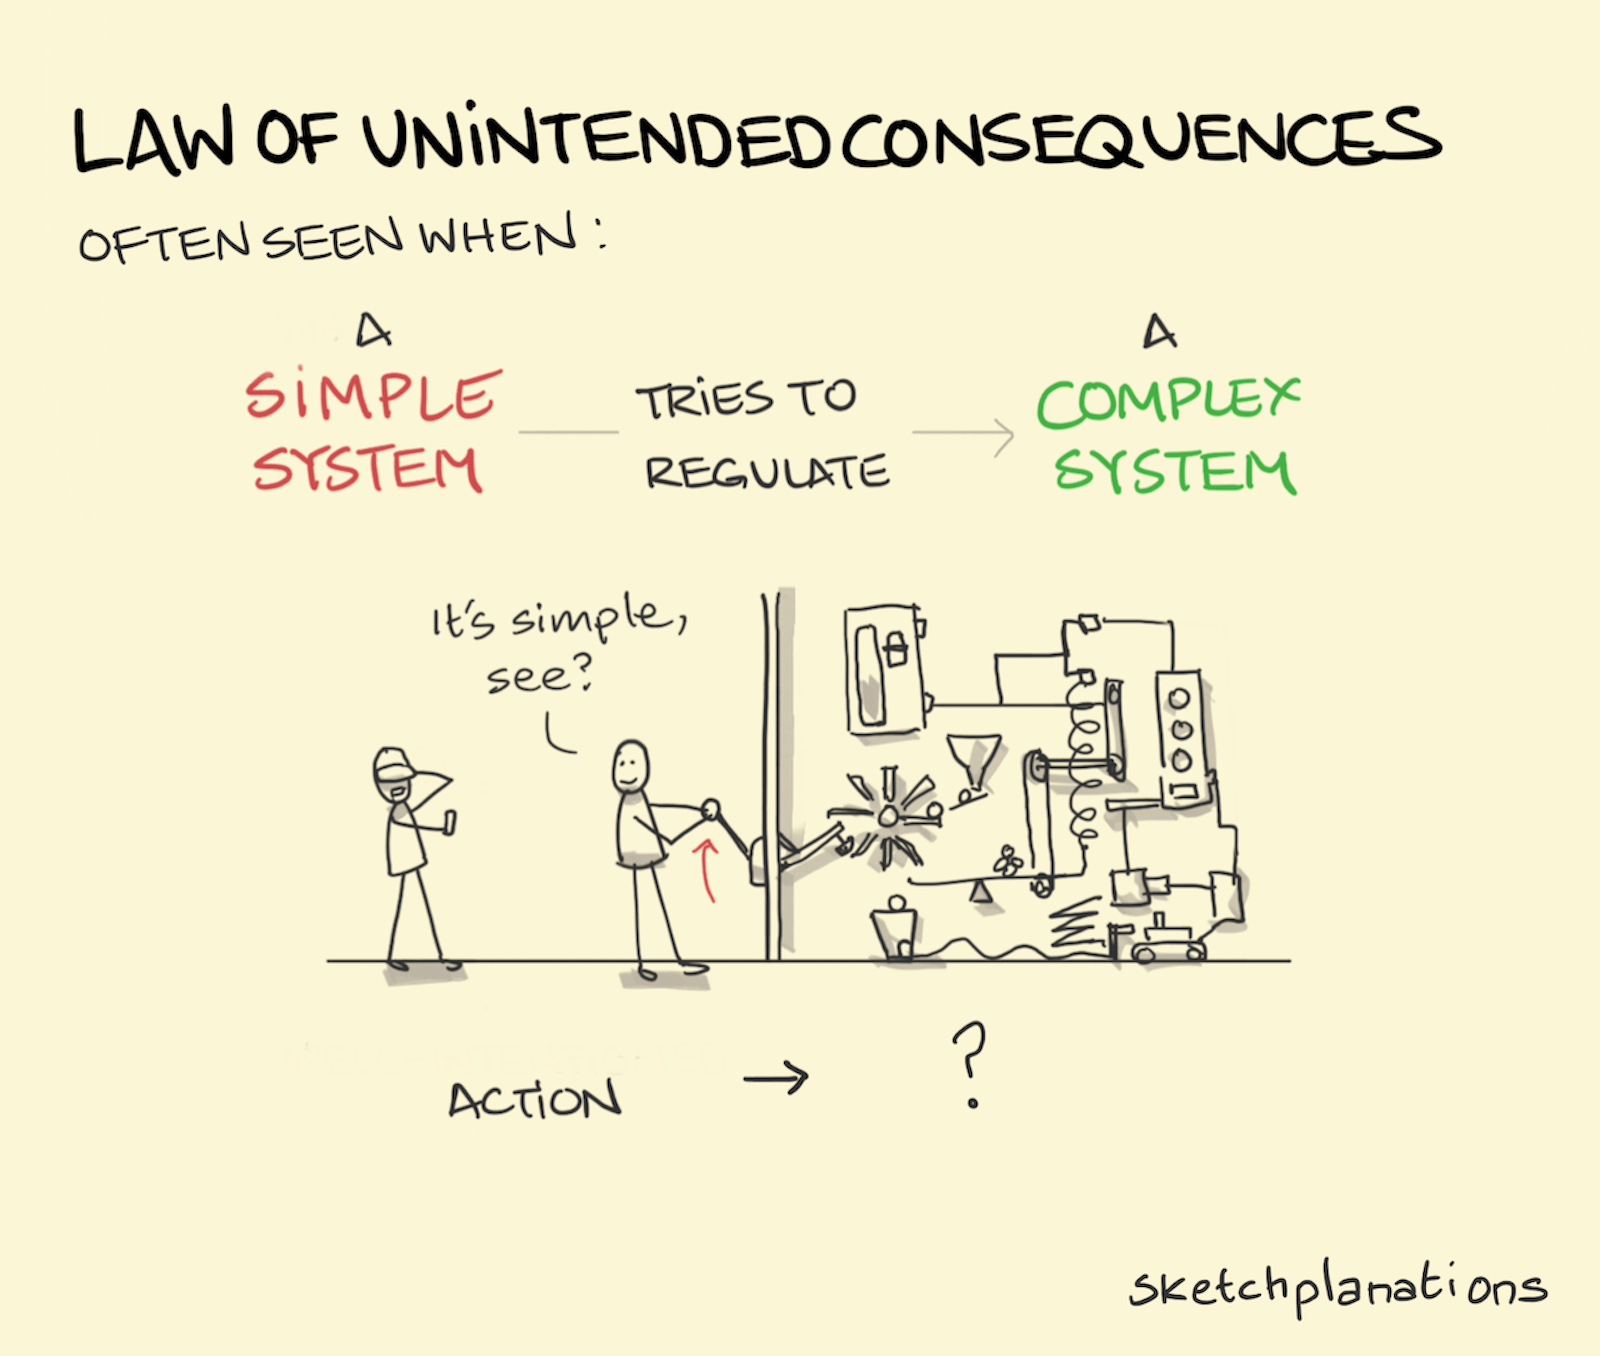
This is not a new problem. The Law Of Unintended Consequences appears in policy, medicine, and infrastructure, and the pattern is the same: optimize a single variable in a connected system and watch the connections react. The practical takeaway is not to stop optimizing. It is to measure the connections too.
When this framework fails
It fails when the system is too opaque to instrument. Some legacy stacks have data paths you cannot observe without invasive changes that introduce their own risks. In those cases, the checklist becomes less useful and you need a different strategy: narrow blast radius, aggressive canarying, and manual spot checks. There is no substitute for looking at a small sample of real traffic after a change when automated signals are unreliable. It is slow and it is not scalable, but it catches things dashboards miss. I usually allocate 30 minutes per high-risk deploy for manual log review on a subset of requests. It beats an all-night pager rotation. The method also struggles in environments with long feedback loops. If a change affects revenue or churn, those signals arrive weeks later. By then, the deploy is forgotten and attribution is messy. The mitigation is to build leading indicators, proxies that move earlier. For revenue impact, look at conversion funnels, cart abandonment, or support ticket classification trends. These are noisy. They are better than waiting for the quarterly report.
A practical workflow you can start today
Start small. Pick one service that has caused pain recently. Run the checklist. Instrument two secondary metrics you were not tracking. Define a rollback threshold. Ship a small change. Watch. Repeat. You do not need a perfect system. You need a feedback loop that is faster than your incident response. Most teams I work with reduce their mean time to detect from several hours to under 20 minutes within a month of doing this consistently. The reductions come from catching regressions in canary rather than in production. If you want a simple template to standardize the checklist across teams, I have used a compact form that fits on one page. It lists the primary metric, secondary metrics, rollback thresholds, and the incident hypothesis field. It is not proprietary. It is just a structure that forces you to confront what you are ignoring. I can share a text version if anyone needs it.
Why this matters beyond code
The Law Of Unintended Consequences is not unique to engineering. It shows up in product decisions, hiring practices, and cost-cutting initiatives. Any time you change a rule in a system with feedback loops, you should expect compensation. The skill is learning to see those loops early. That skill comes from reviewing incidents without blame, from tracking secondary metrics as rigorously as primary ones, and from accepting that no amount of planning eliminates surprise. It only reduces the distance between surprise and discovery.