Working with Enzyme Kinetics When the Data Does Not Fit Your Assumptions
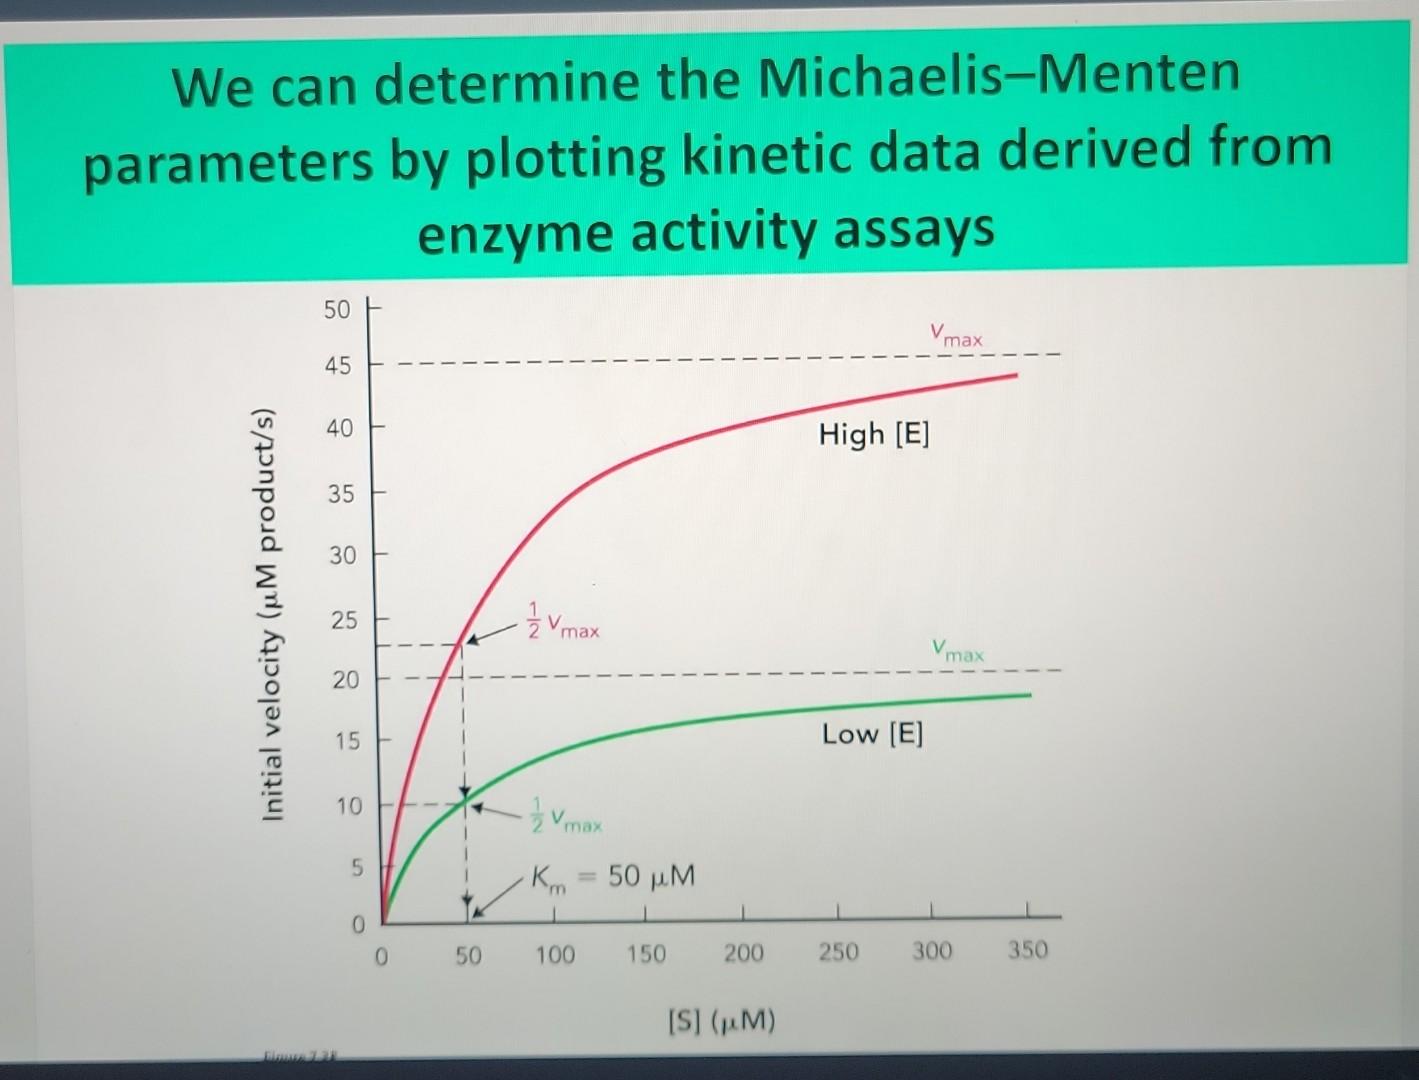
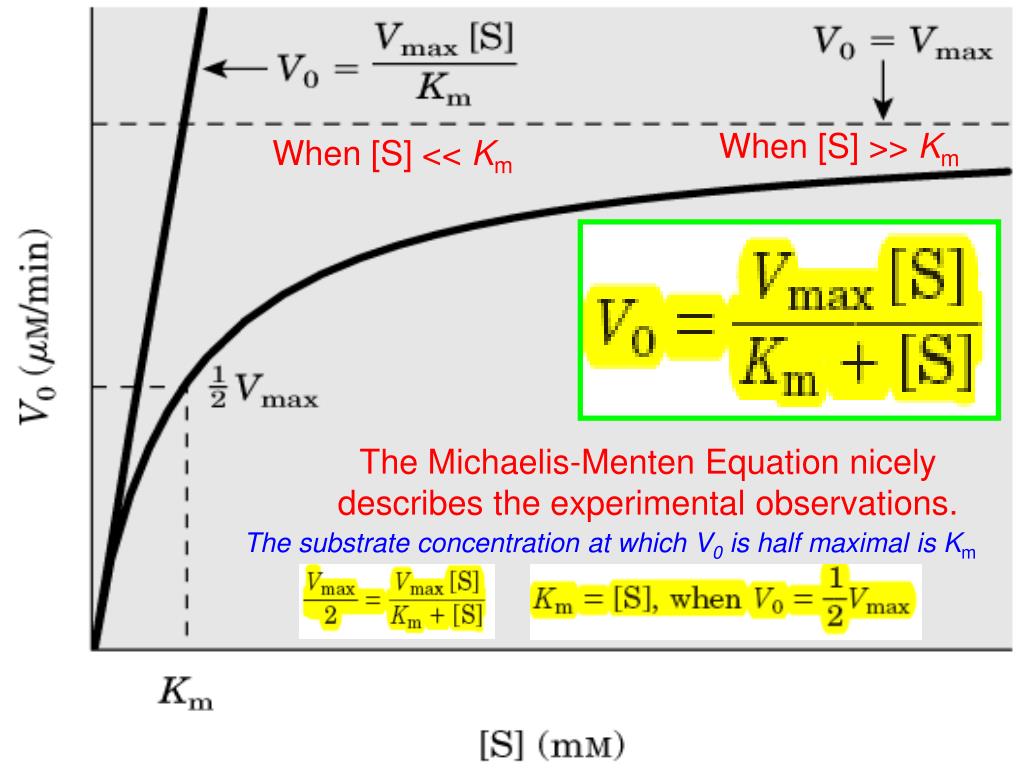
The Michaelis-Menten framework is the default model for any enzyme kinetics paper. You measure initial velocities at different substrate concentrations, fit a curve, and extract Km and Vmax. Most people treat this as a straightforward exercise. It rarely is. The real work happens when you try to break Vmax down into its constituent rate constants — K1, K-1, and Kcat — and realize the math does not always cooperate. I want to talk about what those three constants actually represent and how to get reliable values out of them. I also want to cover the situations where this approach breaks down, because that tends to be where most people lose hours or weeks of work.
The Michaelis Menten K1 K 1 Kcat
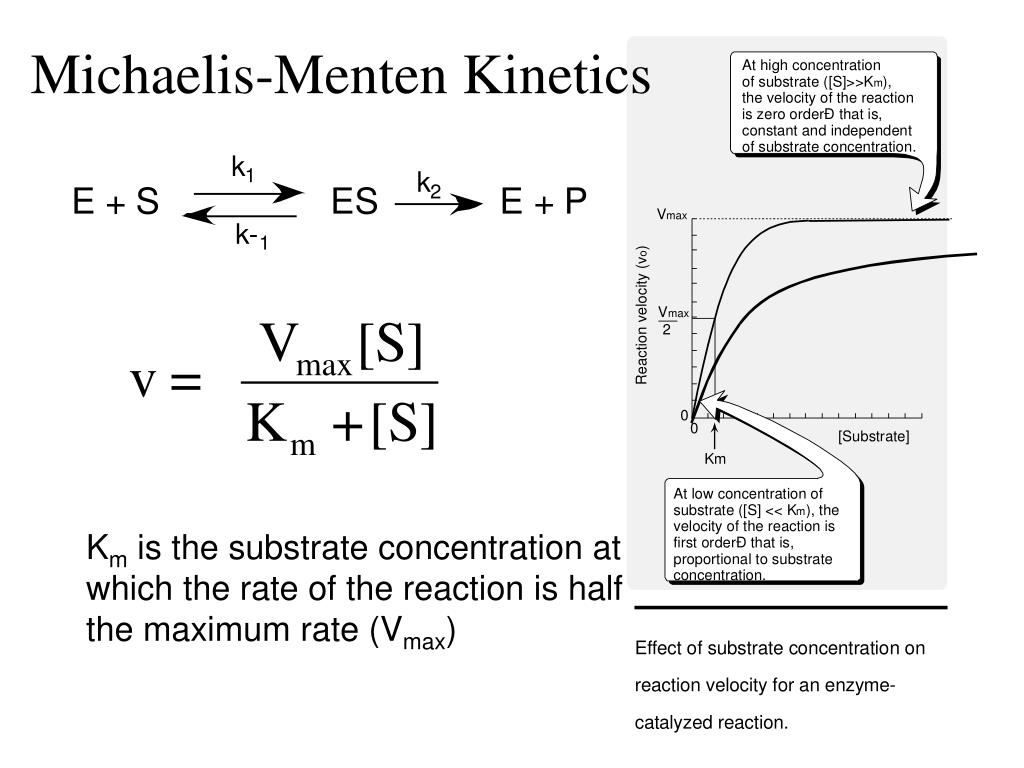
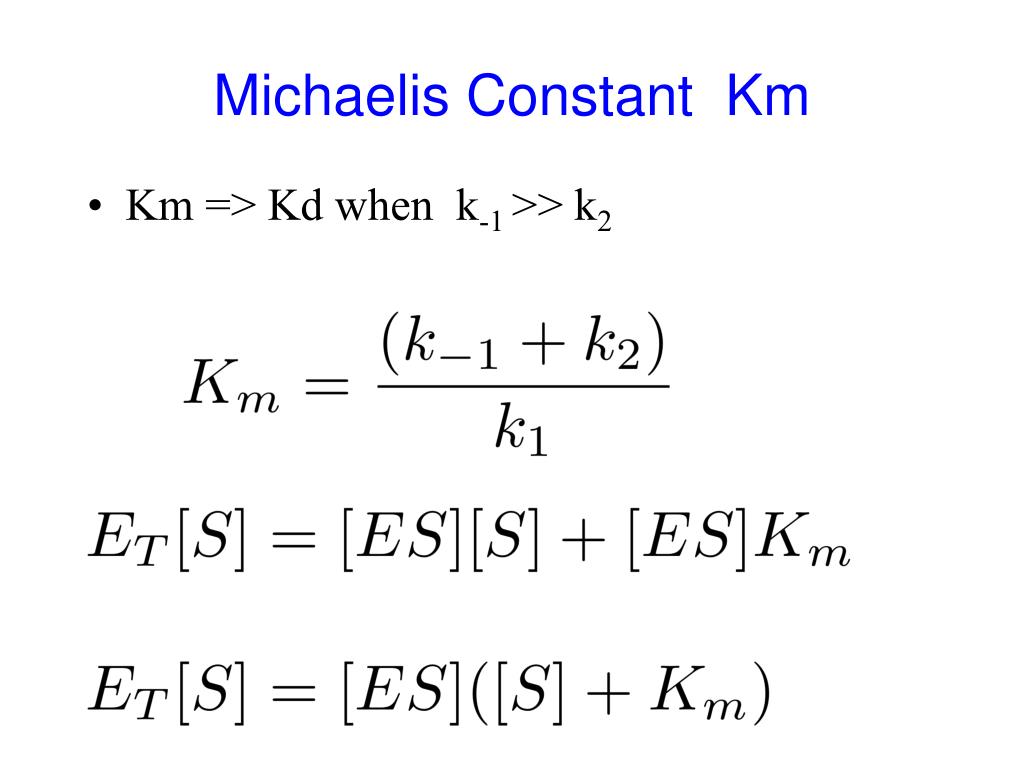
The standard mechanism underlies everything here. An enzyme E binds substrate S to form a complex ES with forward rate constant K1 (often written kon, with units of M¹s¹). The complex can dissociate back to E plus S with rate constant K-1 (koff, units of s¹). It can also proceed forward to release product P and regenerate free enzyme, with rate constant Kcat (k2, units of s¹). The familiar Michaelis constant Km equals (K-1 + Kcat) / K1. This is not an approximation. It is the steady-state derivation. The confusion starts when people conflate Km with the dissociation constant Kd. Kd is simply K-1 / K1. Km includes Kcat in the numerator. If Kcat is small relative to K-1, then Km approximates Kd. If Kcat is comparable to or larger than K-1, Km significantly exceeds Kd, and treating Km as a binding affinity constant gives you wrong conclusions about the enzyme's actual substrate affinity. Here is how I usually approach extracting these parameters in practice. I start with a standard progress-curve assay, measuring initial rates across a range of substrate concentrations. I fit the data to the Michaelis-Menten equation using nonlinear least squares, not a Lineweaver-Burk plot. Linear transformations distort error structure and overweight low-concentration points. NLLS on the raw v versus [S] data gives you Vmax and Km directly. From there, if you know the total enzyme concentration [E]t, you can compute Kcat using Kcat = Vmax / [E]t.
Getting K1 and K-1 separately requires a different experimental handle. Steady-state kinetics alone cannot disentangle them. You need either pre-steady-state kinetic data from a stopped-flow instrument, or an independent measurement of substrate binding, typically by fluorescence quenching, surface plasmon resonance, or isothermal titration calorimetry. When I have access to stopped-flow, I observe the burst phase. The initial rapid formation of ES gives you K-1 and K1 directly from the exponential phases. Kcat appears as the slower steady turnover phase after the burst. I encountered a specific problem last year with a phosphatase that appeared to follow standard Michaelis-Menten behavior in steady-state assays. The fitted Km was around 45 µM and Kcat was 12 s¹. Everything looked normal on paper. When I attempted pre-steady-state experiments to separate K1 and K-1, the burst amplitude was essentially zero. No observable burst phase at all. This meant Kcat was not much smaller than K-1, which implied the chemical step and the dissociation step were competing on similar timescales. The apparent Km was not reflecting substrate binding affinity at all. It was dominated by the catalytic step. I ended up reporting the kinetic parameters as steady-state values only, with a note that individual rate constants could not be resolved without additional structural constraints. This was more honest than pretending I had a complete mechanistic picture. There is a common pitfall worth mentioning explicitly. Many labs report Kcat/Km as a measure of catalytic efficiency and treat it as if it equals K1. This is only true in the limiting case where K-1 is much larger than Kcat. The ratio Kcat/Km is sometimes called the specificity constant, and it has units of M¹s¹ like a second-order rate constant. But it is not K1. It is Kcat × K1 / (K-1 + Kcat). Assuming they are identical will lead to incorrect interpretations, especially when comparing mutants or engineered variants. A mutant might show improved Kcat/Km simply because it slows down product release, not because it binds substrate more tightly.
Get the Full Details

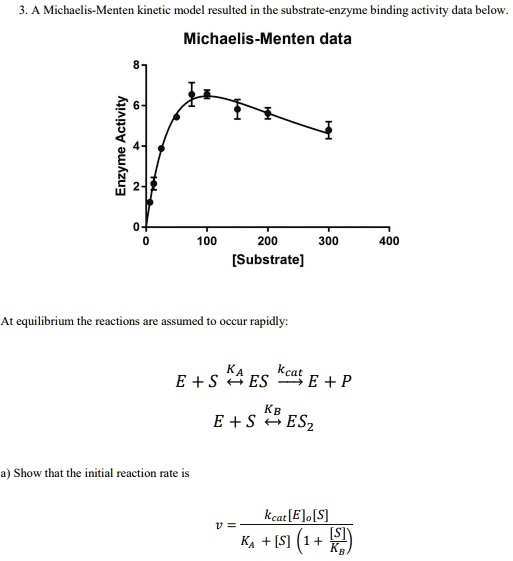
Another limitation that people do not always acknowledge is that the Michaelis-Menten model assumes a single substrate-binding site and rapid equilibrium or steady-state conditions. Real enzymes frequently violate both assumptions. Allosteric enzymes show sigmoidal velocity curves. Membrane-bound enzymes have substrate availability constraints that steady-state equations ignore. Multi-substrate reactions require ordered or random bi-bi mechanisms, not a simple MM equation. If your data fits a Hill coefficient significantly different from one, you should not be forcing a Michaelis-Menten fit. It gives you numbers, but they are not mechanistically meaningful. For practical fitting, I use the software package KinTek Explorer for complex mechanisms and simple nonlinear regression in Python or GraphPad Prism for standard MM analysis. When fitting K1 and K-1 from stopped-flow data, global fitting across multiple wavelengths or conditions significantly improves parameter confidence intervals. Single-curve fits often yield correlated parameters where K1 and K-1 trade off against each other, producing wide confidence intervals even when the residuals look good. If you cannot perform pre-steady-state experiments, you can sometimes estimate K1 and K-1 from equilibrium binding measurements combined with Kcat. Measuring Kd independently gives you K-1/K1. With Km and Kcat in hand, you have two equations and two unknowns. Solve for K1 and K-1 algebraically. The result will carry propagated uncertainty from all three measurements, but it is better than reporting nothing. The algebra works like this: K-1 = K1 × Kd, and Km = (K1 × Kd + Kcat) / K1. Rearranging gives K1 = Kcat / (Km - Kd), then K-1 = K1 × Kd. This only works when Km is measurably larger than Kd. If they are indistinguishable within error, the system is underdetermined and you cannot reliably extract individual constants.
I have seen people try to fit K1, K-1, and Kcat simultaneously to steady-state data alone. It does not work. The model is not identifiable. You will get a fitted curve that looks correct, but the parameter estimates will drift depending on initial guesses and noise. The confidence intervals will be enormous. Do not report individual rate constants derived from steady-state data alone without acknowledging that they are not uniquely determined. The main takeaways are straightforward. Use nonlinear regression on raw velocity data. Distinguish Km from Kd explicitly. Obtain K1 and K-1 from independent binding or pre-steady-state measurements. Report Kcat/Km as a specificity constant, not as a proxy for K1. Check whether your enzyme actually follows Michaelis-Menten kinetics before applying the model. And when the data cannot support the level of detail you want, say so clearly rather than pushing a fit that is more assumption than evidence.