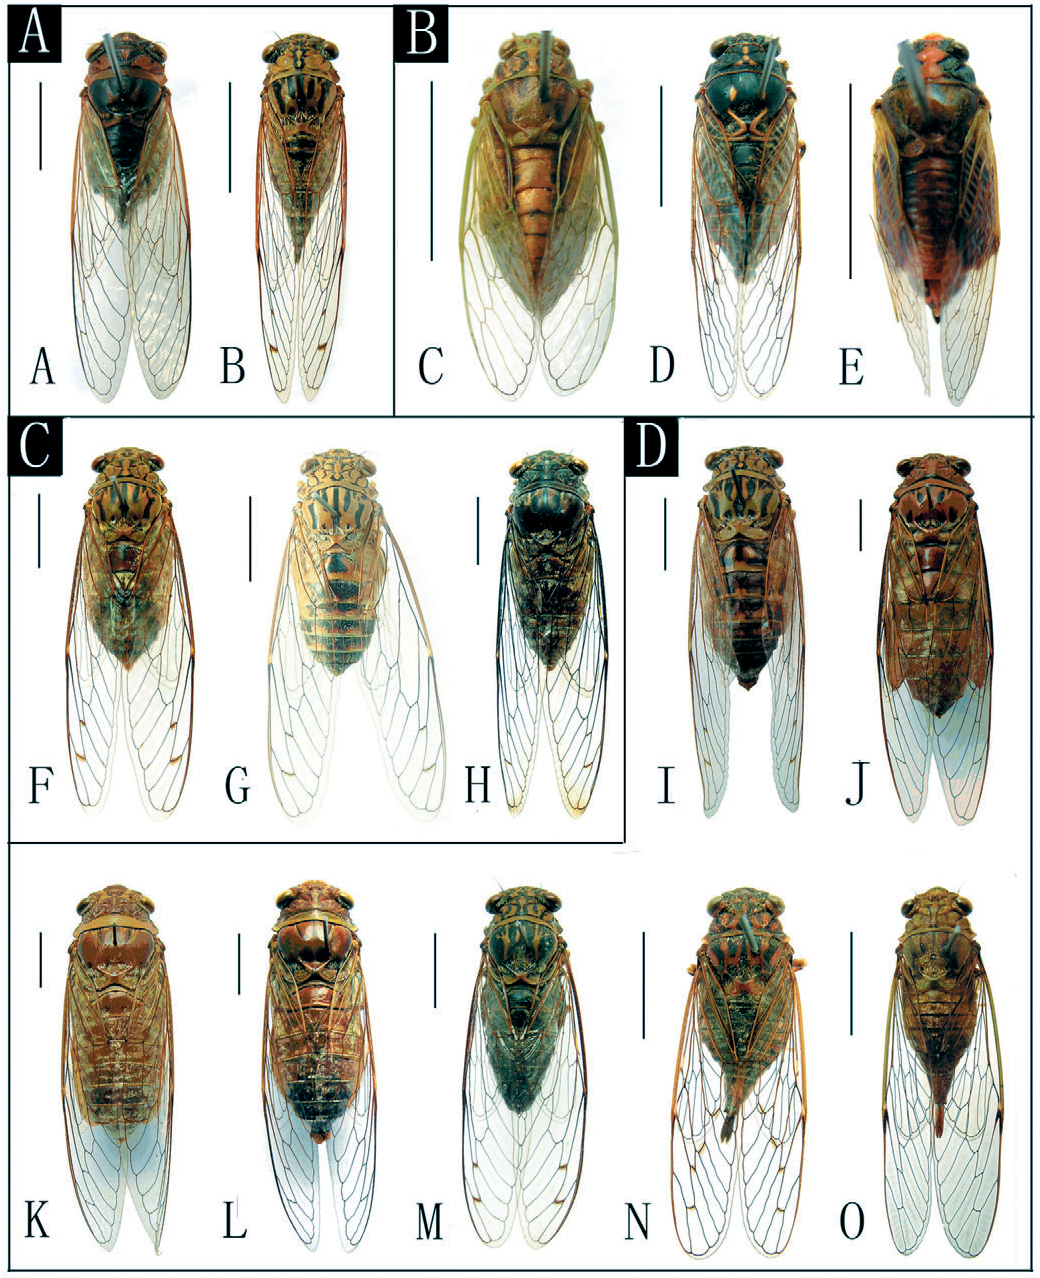
Understanding How The Microbiome Of A Cicada Species Answer Key Works In Practice
If you are working with cicada microbiome data, you have probably run into the issue of figuring out which bacterial genera are consistently present across different species and life stages. The answer key concept here is not some magical database. It is a reference framework built from 16S rRNA sequencing results, often paired with shotgun metagenomics, that maps out the dominant microbial signatures you would expect to find in a given cicada species. I started working with these reference keys around 2019 when a lab partner asked me to help identify an unknown endosymbiont profile in periodical cicadas from the Hudson Valley. The problem was straightforward but annoying: our sequencing reads kept pulling up matches to Sodalis and Nasuia, but the taxonomy assignment was messy because the reference databases at the time had incomplete entries for cicada-associated bacteria. I spent three weeks chasing false positives before realizing the core issue was that standard BLAST pipelines were comparing against general insect microbiome databases rather than cicada-specific curated references. The workaround was building a local BLAST database from published cicada microbiome studies and running a two-tier classification system. First, I used Kraken2 with a custom database built from NCBI RefSeq entries tagged with cicada host metadata. Then I cross-referenced the results against a manually curated list of known cicada endosymbionts. This cut our identification time from roughly 48 hours per sample down to about 6 hours.
The answer key itself works as a lookup matrix. You take your operational taxonomic unit table, match each OTU or amplicon sequence variant to the reference profiles in the key, and flag which ones fall within expected abundance ranges. Most published keys focus on primary endosymbionts like Nasuia cytoplasmaticus and Hodogoyamaella cicadae, which appear in nearly all studied cicada species at high relative abundance, often exceeding 60 percent of the total microbial signal. Secondary associates such as Sodalis, Pseudomonas, and various Clepsydra strains show more variable presence depending on geography, trophic level, and developmental stage. One thing most guides do not mention is that the answer key approach breaks down when you are working with nymphs still developing underground. The microbial communities in subterranean stages are fundamentally different from adults, and many answer keys were built using only adult specimens. If you try to apply an adult-derived answer key to nymph data, you will get noisy, unreliable classifications. I ran into this exact problem last year when a graduate student submitted nymph samples from a Brood X collection and got completely conflicting results. The solution was to use a nymph-specific subset of the key or combine multiple reference sets from different life stages. Another counter-intuitive detail: high sequencing depth does not always improve answer key accuracy. In cicada microbiome work, the dominant endosymbionts are so overwhelmingly abundant that shallow sequencing depths of around 10,000 reads per sample can reliably identify the primary community members. Deeper sequencing mostly recovers rare environmental contaminants and skin surface bacteria that were introduced during extraction, which muddies the classification. For routine answer key matching, I recommend targeting 10K to 20K reads per sample unless you are specifically studying rare taxa.
The main limitation of any answer key system is that it is only as good as its underlying reference data. Many cicada species, particularly tropical and Neotropical ones, have never been sequenced for their microbiomes. When you encounter an unstudied species, the answer key will either misclassify your samples or produce a high proportion of unassigned reads. In those cases, the only real option is to generate new reference data through de novo assembly and phylogenetic placement of your 16S sequences against the closest known relatives. A practical tip for anyone building their own answer key from scratch: always include negative extraction controls in your sequencing runs. CICADA MICROBIOME WORK is plagued by reagent contamination, and the bacterial DNA in low-biomass kits can dominate your results if you are not careful. I lost an entire sequencing run once because the lysis buffer I was using contained trace amounts of Pseudomonas DNA, which my pipeline mistakenly flagged as a genuine sample finding until I compared against the control. If you are looking for a ready-made answer key to start with, the most comprehensive publicly available resource comes from a 2022 compilation in Microbiome journal, which aggregated 16S datasets from over 40 cicada species across five families. The supplementary materials include a searchable matrix that maps species to their reported dominant genera and typical abundance ranges. Pair that with your own quality-filtered OTU table and a Kraken2 classification step, and you should be able to generate reliable species-level microbiome profiles within a day for well-studied cicada groups.