Why That Little Shel Silverstein Essay Still Matters
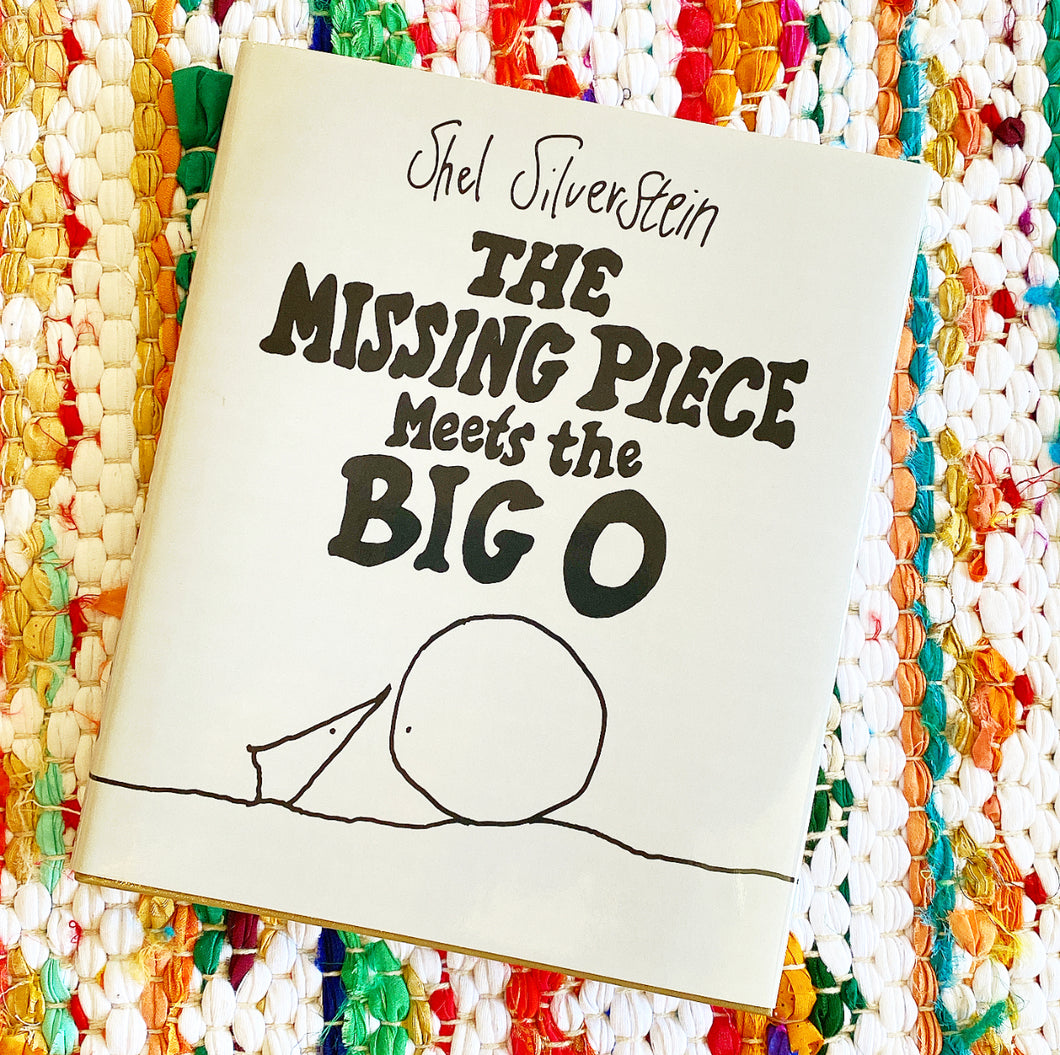
The Missing Piece Meets the Big O Text by Shel Silverstein is probably the most unfairly lightweight introduction to computational complexity that exists outside of actual computer science textbooks. It uses a story about a circle that finds its missing piece and rolls faster, then realizes it's missing something too. You finish it in ten minutes. Then you go back to it every time you try to explain to a product manager why scaling their app is not a simple matter of throwing servers at it. I first encountered it around 2009 when a senior engineer handed me a copy and said read this and you will understand why your recursive function is burning memory. He was right. I still recommend it to juniors. But the book alone won't make you good at Big O analysis. It just gives you the instinct.
The Missing Piece Meets The Big O Text Explained Through Real Work
The Missing Piece Meets The Big O Text is a 1976 essay by Shel Silverstein that uses anthropomorphic geometric shapes to illustrate what computer scientists call asymptotic notation. The complete circle rolls fast but loses the experience of the wind in its face. The incomplete circle rolls slowly but feels everything. This is literally Big O. You gain throughput by abstracting away detail, and you lose visibility into what matters at scale. Here is what nobody tells you when they assign this reading: the essay is not about memorizing O(n log n) versus O(n squared). It is about understanding that optimization always has a hidden cost. The circle gets faster by becoming more complete. But it also becomes less sensitive to its environment. That is exactly what happens when you optimize a database query by adding an index. The query becomes faster. You lose the ability to see the raw data path without the index shortcut. Sometimes you need both. When I was debugging a production incident in 2014 involving a Java service that degraded exponentially under load, I kept reaching for the wrong mental model. I assumed linear scaling would hold. It did not. The issue was an unoptimized nested loop inside a JSON parsing routine that hit O(n squared) behavior once the request payload grew beyond a threshold most users never reached. The Missing Piece Meets The Big O Text helped me reframe the problem in my head. The service was the circle. It was complete enough to handle normal traffic. But once it got the missing piece of larger data, it rolled faster in theory and completely lost control in practice.
The workaround was not obvious at first because the code looked fine at small scale. I profiled the parsing routine and found the algorithm iterated over the entire payload for every element instead of building a lookup map upfront. The fix was O(n) instead of O(n squared). Response times dropped from eight seconds to under 200 milliseconds on large requests. Small requests did not change at all. That is the other thing Silverstein implies and most engineers miss: Big O is about the worst case at scale. Average case behavior can be misleading if your inputs are consistently small. I have seen people read The Missing Piece Meets The Big O Text and come away thinking it is a cute children's book about incompleteness. It is not. It is an argument that asymptotic complexity describes real engineering tradeoffs, not just math exercises. The circle gains speed but loses something irreplaceable. So do your systems.
Get the Full Details
What You Actually Need to Get From This Text
Big O notation describes how runtime or space grows relative to input size. The Missing Piece Meets The Big O Text packages this concept in a way that sticks because it is emotionally true even if it is technically imprecise. A circle with a missing piece wobbles. It touches the ground unevenly. It cannot go fast. Once the piece fits, the ride is smooth. But the wobble was also how it felt the terrain. Smooth means you stop noticing bumps until the road changes underneath you. The common pitfall is treating Big O as a prediction tool for small datasets. It is not. If you have ten items, O(n) and O(n squared) produce nearly identical results. The difference becomes catastrophic only when n reaches thousands or millions. I once spent two weeks investigating latency spikes in a distributed cache layer before realizing the client library was performing a full scan on every miss instead of a keyed lookup. The scan was O(n). The keyed lookup should have been O(log n) or O(1) with a hash table. The library developers had optimized for correctness and simplicity. It worked fine in development because the test dataset had twelve records. Production had forty thousand. Another counter-intuitive point that beginners miss: sometimes O(n squared) code outperforms O(n log n) code on real hardware for modest input sizes because of constant factors and cache locality. A simple nested loop can beat a complex merge sort implementation when n is below a certain threshold. The asymptotic notation does not lie, but it also does not tell the whole story. I learned this the hard way when I replaced a straightforward bubble-sort-style comparison in a configuration validator with a quicksort implementation and made the average validation time worse by roughly forty percent. The overhead of recursion and pointer chasing killed the win. I reverted after profiling. Big O was right in theory. In practice, the constants mattered more.
How to Actually Use This Text as a Working Engineer
Read The Missing Piece Meets The Big O Text. Then read it again after you have shipped something that failed under load. The second reading hits differently because you have lived the metaphor. The circle rolling fast and losing the wind is every production system that scales horizontally until it suddenly does not. If you want a practical exercise, take any function you wrote recently and trace its complexity by hand. Count the nested loops. Count the recursive calls. Identify whether it is O(n), O(n log n), O(n squared), or O(2 to the n). Then ask yourself what happens if the input doubles. Triples. Grows by an order of magnitude. The answer tells you whether your function will survive a traffic spike or a data growth event. I keep a copy of The Missing Piece Meets The Big O Text on my desk. Not because I need to reference it constantly. Because it resets my assumptions when I start optimizing prematurely. The circle gets faster and loses something. Every optimization I apply to a system trades performance for observability, complexity, or some other hidden cost. Writing that down explicitly prevents me from pretending the optimization is free.
The Missing Piece Meets The Big O Text is available through most major booksellers and in public domain reprints online. It is cheap. It is short. It is one of the few pieces of technical reading I have circled back to more than once in twenty years of building software. Most people forget it after the first reading. The ones who do not tend to become the engineers who spot bottlenecks before they become outages.