What You Actually Run Into When You Try To Predict Anything
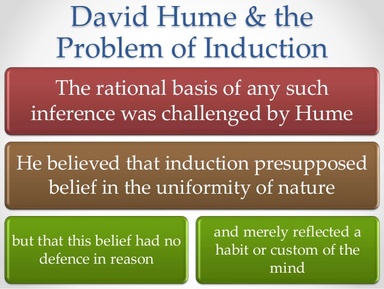
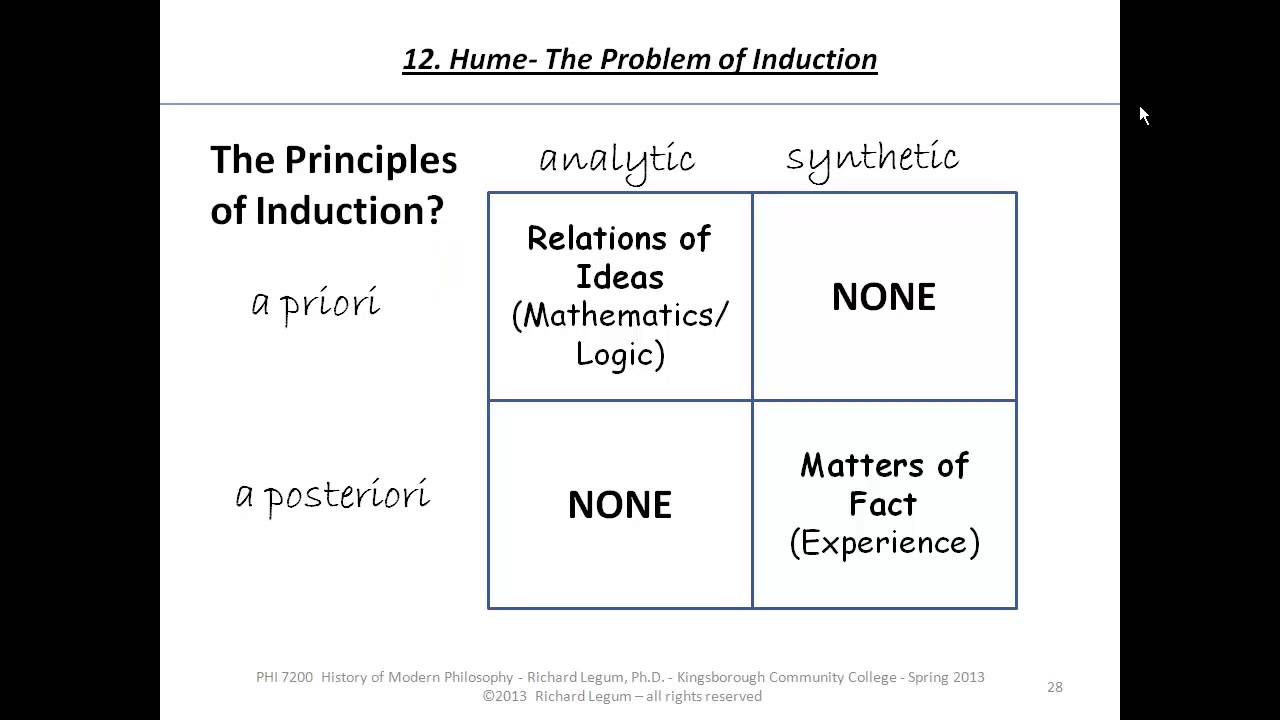
I spent about six months building a recommendation system that relied entirely on pattern matching from historical data. It looked good in the training split. It failed completely on the first real traffic spike we saw, because the assumption that past behavior reliably predicts future behavior turned out to be exactly wrong for that use case. This is The Problem Of Induction in a practical setting, not the version you read about in a philosophy textbook. The basic idea is straightforward enough. You observe a bunch of instances where event A has been followed by event B. You conclude that A will probably be followed by B again next time. David Hume wrote about this in the 1700s and essentially said there is no logical guarantee that the future will resemble the past. Every time someone says "it worked before so it will work again," they are making a leap that cannot be proven deductively. That is the core of the problem.
The Problem Of Induction And Why Your Model Will Miss It Until It Is Too Late
When you are actually working with this, the issue shows up as overconfidence in inductive generalizations. You fit a model. You check your accuracy metric. You ship it. Then the distribution shifts and your nice 94 percent accuracy drops to something closer to random guessing because the underlying pattern your model learned was not stable. Here is a specific example from my own work. We were building a fraud detection pipeline for payment transactions. We had about 18 months of labeled transaction data. The model picked up on several strong signals: certain merchant categories, transaction amounts above a threshold, geographic mismatches between billing and shipping. It performed well enough that we deployed it without much hesitation. Within three weeks, fraudsters changed their behavior. They started running smaller transactions across multiple new merchant categories that had never appeared in our training data at meaningful volume. Our model missed most of them because it had inductively learned that high-value transactions in known categories were the primary signal. It had no mechanism for recognizing that the underlying generative process had changed. The workaround was not fancy. We introduced a sliding window retraining schedule with a strict freshness constraint on the training data, kept recent data points weighted heavier, and layered in a simple anomaly detector that flagged transactions falling outside the support of the training distribution. That anomaly layer caught the shifted patterns. It did not prevent the initial miss, but it reduced the window of vulnerability from several weeks to about four days.
There are a few things beginners consistently get wrong when they encounter this problem. The first is treating inductive inference as if it needs to be deductively justified before it can be useful. It does not. You can use inductive methods and get good results without solving Hume's original philosophical objection. The second mistake is thinking that more data solves the problem. It often makes it worse by reinforcing stale patterns. More data amplifies whatever biases and structures are already in your sample. If your sample is drawn from a non-stationary process, more of the same data just gives you a more precise estimate of the wrong thing. Another nuance that people miss is the difference between enumerative induction and inference to the best explanation. Enumerative induction is the naive version: observed A followed by B many times, therefore A will be followed by B. Inference to the best explanation, sometimes called abductive reasoning, is what practitioners actually use when they build systems. You generate competing hypotheses about why the data looks the way it does, then pick the hypothesis that best accounts for the observations given your background knowledge. It is still inductive. It is still vulnerable to the same fundamental problem. But it tends to produce more robust models because you are not just counting co-occurrences. If you want to work with inductive reasoning practically, there are established techniques that address parts of the problem without solving it completely. Cross-validation is the most basic one. You hold out data your model has not seen during training and measure performance there. This does not guarantee future performance, but it gives you a realistic estimate of how much your model has overfit to inductive patterns in the training set. Nested cross-validation is better when you are doing hyperparameter tuning. You prevent information leakage between the tuning step and the evaluation step.
Get the Full Details
Regularization is another tool. L1 and L2 regularization penalize model complexity, which indirectly addresses inductive overreach by discouraging the model from fitting noise in the training data. Dropouts in neural networks serve a similar purpose by randomly disabling units during training and forcing the network to develop more distributed representations. Ensemble methods combine multiple models trained on different subsets or with different architectures. The idea is that individual models may each make different inductive errors, and averaging them reduces variance. Bagging, boosting, and stacking are all variations on this theme. They do not eliminate the problem of induction. They reduce the impact of any single inductive generalization being wrong. Bayesian methods approach the problem differently. Instead of producing a single point estimate, they maintain a probability distribution over hypotheses and update it as new data arrives. This makes the uncertainty explicit. You can see when your posterior distribution is still very wide, which tells you that your inductive conclusions are fragile. The computational cost can be significant. Variational inference and Markov chain Monte Carlo sampling are standard tools, but even those have limitations. MCMC can take a long time to converge, and variational approximations can miss important structure in the posterior.
Structural causal models represent a more recent direction. Rather than just learning correlations from data, you encode assumptions about the causal structure generating the data. Judea Pearl's work on do-calculus and causal diagrams is the reference here. Causal models are more robust to distributional shifts because they attempt to capture the mechanism rather than the surface statistics. They also require stronger assumptions. You need domain knowledge to specify the causal graph correctly, and if your graph is wrong, your inferences can be confidently incorrect, which is worse than being uncertain. I should be clear about what these methods do not do. None of them solve The Problem Of Induction. They manage it. They reduce risk, quantify uncertainty, and improve robustness. They do not provide a logical justification for believing that the future will resemble the past. Any claim otherwise is either philosophical hand-waving or marketing. There are scenarios where inductive approaches fail completely and no amount of cross-validation or regularization will help. Regime changes are the main one. Financial markets during a crash. Supply chains during a pandemic. Recommendation systems when a new product category goes viral. In these cases, the generative process changes in a way that is not captured by any extrapolation from past data. The only thing that helps is rapid detection and response, not better inductive inference.
Another failure mode is when your data is not independently and identically distributed. Time series violate independence. Spatial data violates identical distribution. Both are common in practice. Standard inductive methods assume i.i.d. data. When that assumption is violated, your confidence intervals are wrong, your error estimates are biased, and your model will likely underperform relative to what your validation metrics promised. If you are starting a project where inductive inference is central, here is a practical sequence that has worked for me. Define the prediction task and the time horizon clearly. Inductive models are only as good as the assumption that the future resembles the past within that time horizon. A model predicting next-second stock movements has a very different induction problem than one predicting monthly churn. Fit your initial model. Run thorough cross-validation with time-aware splits if you have temporal data. Monitor the stability of your feature importance and model weights over time. Set up alerting on distribution shift detection using something like population stability index or Kolmogorov-Smirnov tests on your input features. Define a retraining trigger based on performance decay rather than a fixed schedule. Keep a shadow model running in production that you can swap in if the primary model degrades. The cost of this process is real. It typically adds two to three weeks to a project timeline compared to a naive train-and-deploy approach. It requires ongoing monitoring infrastructure that most teams do not have initially. But it prevents the kind of silent degradation that ruins models months after deployment when nobody is actively watching.
The deeper lesson from working with induction in practice is that the problem is not something you solve. It is something you live with. You acknowledge that every prediction you make rests on an unprovable assumption about the continuity of the world, and you build systems that degrade gracefully when that assumption turns out to be wrong rather than systems that appear to work until they do not.