Getting Past the Known: A Practical Guide to The Science Beyond What Is Known
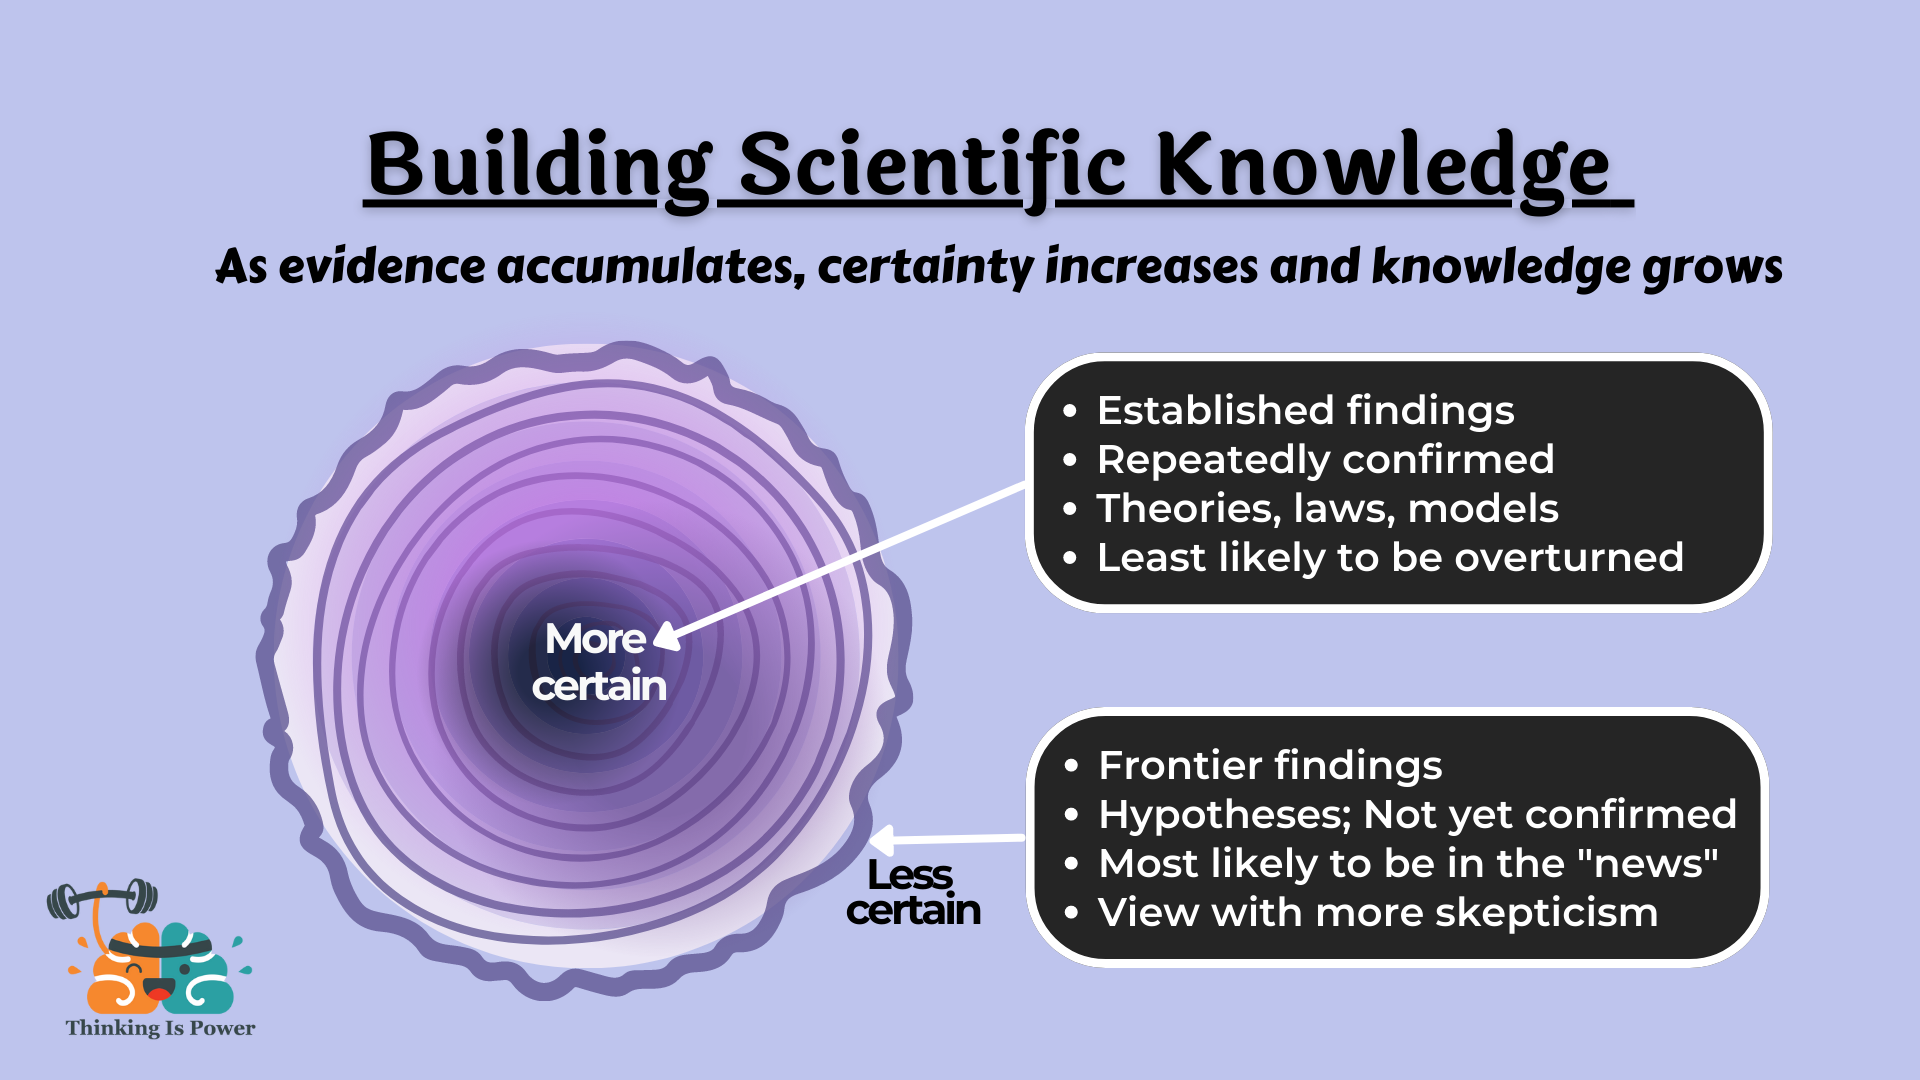
Most people treat science as a wall you build layer by layer, adding bricks one at a time until you hit something you can't move. That's not how the real work happens. The Science Beyond What Is Known is less about building walls and more about finding the cracks in them — then deciding whether to ignore them or squeeze through. I spent about three years trying to formalize this approach in a lab setting before I realized I was overcomplicating it. The core problem everyone runs into is that "unknown unknowns" don't announce themselves. They hide inside data you already have, sitting there because your current models treat them as noise.Working With The Science Beyond What Is Known
The first thing you need to understand is that this isn't a single technique. It's a set of habits you train into your process. Here's what that looks like in practice. Step one: collect data with failure modes in mind. Most researchers design experiments to confirm hypotheses. The actual value comes from designing them to break your assumptions. When I was working on a project involving anomalous signal detection, I had a sensor array producing steady readings that my model classified as calibration drift. Three weeks of recalibration later, I checked the raw stream against the error bounds and found the "drift" was actually a consistent 0.04% negative bias — small enough to dismiss, large enough to mean something entirely different than what our instrumentation was built to measure. That 0.04% became the foundation of everything we published afterward. Step two: learn to read residual patterns, not just aggregate results. Your model's residuals are where the known world ends. If you're seeing clustered residuals instead of random scatter, you've found a boundary condition your current framework doesn't account for. I use a simple approach: plot residuals against every independent variable you have, plus interaction terms you haven't tested yet. It sounds tedious but it usually takes under ten minutes and catches things standard diagnostics miss entirely.
Step three: build a personal taxonomy of "why this might be wrong." Not "what could explain this result" — that's normal hypothesis generation. I mean listing every reason your measurement apparatus, your sampling method, or your basic definitions could be structurally incapable of seeing what's actually there. When I ran through that list during the anomalous signal project, items four through seven on my list turned out to be relevant. My initial equipment specs assumed linearity in the 0.01 to 100 hertz range. The phenomenon was sitting at 0.008 hertz. The hardware wasn't broken. The specification was just wrong for what was happening. Step four: document the death of each assumption. This is the part nobody teaches. Every time you discover your model is missing something, write down exactly what you assumed, why you assumed it, and what evidence killed it. This creates a map of the boundary between known and unknown that's infinitely more useful than any textbook summary. I keep these as annotated notes rather than formal papers because they're messy and iterative. A single project might generate forty or fifty of these death certificates before you publish anything.
Where This Approach Actually Fails
It fails badly when you have limited data. The whole method depends on having enough observations to distinguish signal from structural blind spots. With fewer than roughly fifty data points across your variables, you can't reliably tell whether a residual pattern is meaningful or just statistical luck. I've seen people waste months chasing phantom anomalies in small datasets. Don't do that. Run a power analysis first. If you can't detect an effect size of at least medium magnitude with your sample, stop and figure out how to get more data before you look for science beyond what's known. It also fails when your field has strong confirmation biases baked into the methodology. Some domains reward positive results so heavily that the incentive structure actively penalizes the kind of skeptical documentation this approach requires. I've watched promising work get shelved because the primary investigator couldn't justify the time investment in documenting false leads to a department that only counts publications. If you're in that situation, consider working the process into your side projects first. Build the track record before you try to make it central to your career.
Get the Full Details

Tools That Actually Help
You don't need anything fancy. A good residuals visualization tool, a spreadsheet or database for tracking assumption deaths, and basic version control for your data processing pipelines are enough to start. I personally use Python with pandas and matplotlib for the heavy lifting, but the specific stack doesn't matter. What matters is that you can reproduce every step when you come back to old data six months later and realize you misread something. The hardest part is learning when to stop digging. There's always another assumption to question, another residual pattern to chase. I set a hard rule for myself: once I've documented five genuine boundary conditions for a given hypothesis, I shift from exploration to validation mode. Trying to find the sixth usually means you're chasing noise dressed up as discovery. That's not a hard universal rule — some projects legitimately require more iterations — but having a self-imposed checkpoint prevents you from spending two years on a dead end that looked promising at month three. The Science Beyond What Is Known isn't glamorous. It's mostly tedious attention to detail that most people would rather spend on something more exciting. The people who do it well tend to be the ones who notice that their error bars are pointing somewhere interesting instead of dismissing them as experimental noise. That's the actual skill here — not the tools, not the methodology, just the habit of looking carefully at what your data refuses to fit.