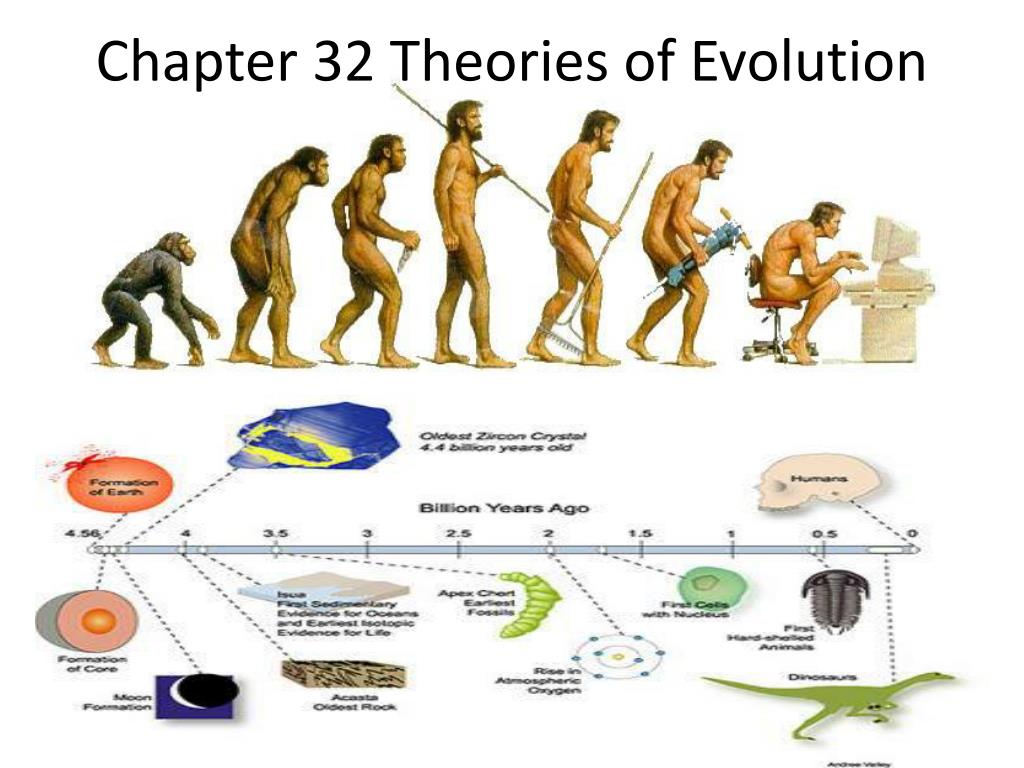
What Actually Moves Allele Frequencies Around
Evolution is just change in allele frequencies over time. That's the whole thing stripped down. The math works out cleanly enough, but the messy part is actually observing it and knowing which mechanism did the work when multiple forces are pulling at the same time. I spent a few years watching microbial populations under controlled conditions before I stopped treating the theory like a textbook diagram and started treating it like a system with friction. Most people learn evolution as natural selection first. That's backwards from how it actually plays out in the lab or in the wild. Mutation and gene flow introduce variation first, and selection sort of happens on top of whatever material is available. You can't get adaptive change without that raw material, and the raw material comes from random errors in replication and from migrants arriving with different genetic baggage. The five mechanisms — mutation, gene flow, genetic drift, non-random mating, and selection — rarely operate independently. That's the first thing that trips people up. In practice you're always looking at overlapping forces. A population might be experiencing directional selection for heat tolerance while also getting gene flow from a cooler-climate population introducing alleles that work against that direction. Your job is to untangle which force is winning where.
Here's a detail that doesn't get enough attention: the effective population size, Ne, almost never equals the census population size. In many vertebrate populations Ne is somewhere between ten and thirty percent of the head count. That means drift is stronger than your raw numbers suggest, and selection is less efficient at purging slightly deleterious mutations. If you're running a quantitative genetics analysis on a species with skewed sex ratios or high variance in reproductive success, your predictions will be off by a wide margin unless you account for Ne properly. I ran into this explicitly while working with a isolated island bird population. Census count was roughly two thousand birds, which should have meant drift was negligible and selection could operate efficiently. But when I calculated Ne from pedigree data and found it closer to three hundred, everything changed. The slightly deleterious variants we were seeing at moderate frequency weren't due to relaxed selection from a recent bottleneck. They were maintained by drift because the effective size was small enough that selection couldn't overcome the random sampling error each generation. We had been misattributing drift to selection for about six months before the Ne calculation corrected our interpretation. The workaround was switching from phenotype-only models to individual-based simulations that incorporated the estimated Ne and the actual variance in offspring number per adult.
Reading the Signals Without Confusing Correlation With Mechanism
The hard part isn't stating that evolution happens. It's determining what shaped a particular trait or allele frequency pattern, and how fast. Different mechanisms produce overlapping signatures, so you need multiple lines of evidence rather than relying on any single test. When I'm looking at genomic data for signatures of selection, I start with Fst outliers to flag regions with unusually high differentiation between populations. That points me toward local adaptation, but Fst outliers can also arise from demographic history, so I follow up with Tajima's D and nucleotide diversity comparisons. A region showing high Fst combined with negative Tajima's D and reduced diversity within the selected population is a much stronger candidate for a recent selective sweep than any one metric alone. The combination matters because drift and bottlenecks can produce some of the same patterns without adaptive change. Phylogenetic comparative methods come in handy when you're trying to reconstruct trait evolution across species. You fit models of Brownian motion, Ornstein-Uhlenbeck, and early-burst processes to trait data on a known phylogeny, then use AIC weights to see which model fits best. Brownian motion assumes traits drift randomly along branches. OU models assume selection pulls traits toward an optimum. Early-burst models assume rapid diversification early in a clade's history that slows over time. The trick is that these models make different predictions about trait variance at the tips of the tree, and model choice changes how you interpret the underlying process. I've seen people present OU fits as proof of stabilizing selection without checking whether the Brownian motion model was adequately rejected or whether the optimal values were biologically realistic. That's a common mistake worth watching for.
Get the Full Details
Quantitative trait locus mapping is another tool that gets overstated in introductory courses. Finding a QTL doesn't tell you the effect size, the number of loci involved, or whether the alleles are standing variation or new mutations. In my experience, most traits of evolutionary interest are controlled by dozens to hundreds of small-effect loci, and mapping studies with modest sample sizes only detect the largest contributors. If you want a realistic picture of the genetic architecture, you need larger samples, dense markers, and ideally validation in independent populations. A mapping study with two hundred individuals and a sparse marker set is going to miss most of the relevant variation.
Common Pitfalls That Waste Time
The most expensive mistake I see repeatedly is treating neutral markers as if they are unlinked to selected loci when testing for selection. Linkage disequilibrium means a neutral site near a selected allele will hitchhike along, and that distorts demographic inference if you use those sites to calibrate your null model. The fix is straightforward but often skipped: either exclude regions with excess LD from the neutral baseline, or use coalescent simulations that incorporate the recombination map you've estimated from the data. Skipping this step inflates false positives in selection scans because your null distribution is wrong. Another pitfall is assuming that observed adaptation proves selection is the dominant force. An adaptive trait could have arisen through genetic constraints, developmental bias, or pleiotropic side effects rather than direct selection on that trait. I worked on a project where a morphological shift in a fish population appeared to be a classic example of directional selection for body depth in faster-flowing water. After controlling for correlated growth trajectories and developmental constraints, the signal weakened substantially. The trait was partly adaptive, but the original interpretation overstated the role of selection and understated the contribution of genetic covariiation guiding the response. Time scale matters enormously. Microevolutionary changes happen measurably in a few generations in microbes and some insects. Macroevolutionary patterns, like the origin of new body plans, involve deep time, lineage sorting, and extinction filtering that distorts what we see in the fossil record. Mixing inferences across these scales without acknowledging the difference leads to sloppy reasoning. You can observe selection acting on beak size in a single season. You cannot infer the same mechanistic simplicity from the fossil record over millions of years, where preservation bias and incomplete sampling dominate the observable signal.
The measurement error problem is also real and underappreciated. Phenotypic plasticity can mimic evolutionary change if you sample across environments without controlling for it. A common garden experiment or reciprocal transplant is the standard fix, but it requires resources many researchers don't have. When I don't have the luxury of common garden rearing, I fall back on reaction norm estimation across environmental gradients and use genome-wide association data to separate genetic from environmental covariance. It's less clean than a proper common garden, but it keeps you from publishing plasticity as adaptation.

Practical Steps for Estimating Evolutionary Change in Your Own Data
If you're starting from raw population data, begin with allele frequency estimation using a tool like GATK or PLINK, depending on whether you're working with variant calls or summary genotypes. Filter aggressively for missingness and Hardy-Weinberg deviations before running anything else. Bad input data makes every downstream test unreliable, and no correction method fully recovers from poor quality starts. For selection scans, run a population differentiation analysis with BayeScan or PCAdapt. BayeScan uses a Bayesian framework to identify loci under selection while accounting for population structure. PCAdapt is faster and doesn't require a pre-specified population model, which helps when structure is continuous rather than discrete. Either way, report q-values, not raw p-values, and be transparent about how many loci you call significant relative to the total tested. The false discovery rate in genomic scans is notoriously sensitive to population structure, and uncorrected tests will exaggerate the number of selected loci substantially. For quantitative traits, estimate heritability with a numerator relationship matrix from genomic data rather than from pedigrees when pedigrees are incomplete. Genomic relatedness matrices capture recent coancestry more accurately and reduce bias in heritability estimates for outbred or admixed populations. If you're working with a wild population and can't genotype every individual, imputation from a reference panel can fill gaps, but the accuracy depends heavily on reference panel size and divergence from your study population. I typically require a reference panel of at least five hundred unrelated individuals from a closely related population for imputation to stay above ninety percent accuracy at common variants. Below that, the error inflates your heritability confidence intervals enough that conclusions become shaky.
Simulation-based validation is worth the investment of time. I use SLiM for forward simulations when I need to model selection, demography, and recombination simultaneously. It's more computationally intensive than coalescent simulators, but it handles complex life histories and spatial structure better. If your empirical results sit outside the 95% envelope of your simulated null distributions, you have stronger evidence for a specific evolutionary mechanism than from any single statistical test alone.
Where The Framework Breaks Down
The modern synthesis and its extensions work well for traits controlled by additive genetic variation in large, panmictic populations. They break down when epistatic interactions dominate, when horizontal gene transfer is a primary route of variation like in many prokaryotes, or when cultural transmission in humans and some animals decouples phenotypic change from genetic change. Extended evolutionary synthesis ideas — developmental bias, niche construction, epigenetic inheritance — aren't replacements for population genetics. They're complements that address cases where the standard framework is insufficient. Treating them as either fully integrated or completely irrelevant misses the practical middle ground where most empirical work actually happens. The honest limit is that we can rarely prove the exact selective pressure behind a historical adaptation. We can build strong circumstantial cases with genomic scans, functional assays, and comparative evidence, but correlation persists. The fossil record gives us snapshots, not movies. Most papers overstate causal confidence because the alternative explanations are harder to test than the preferred one. I try to keep language proportional to the evidence — suggestive, consistent with, not ruled out — rather than claiming demonstrated adaptation unless I have independent functional validation backing it up.