How Thematic Analysis Actually Works When You Are Doing It
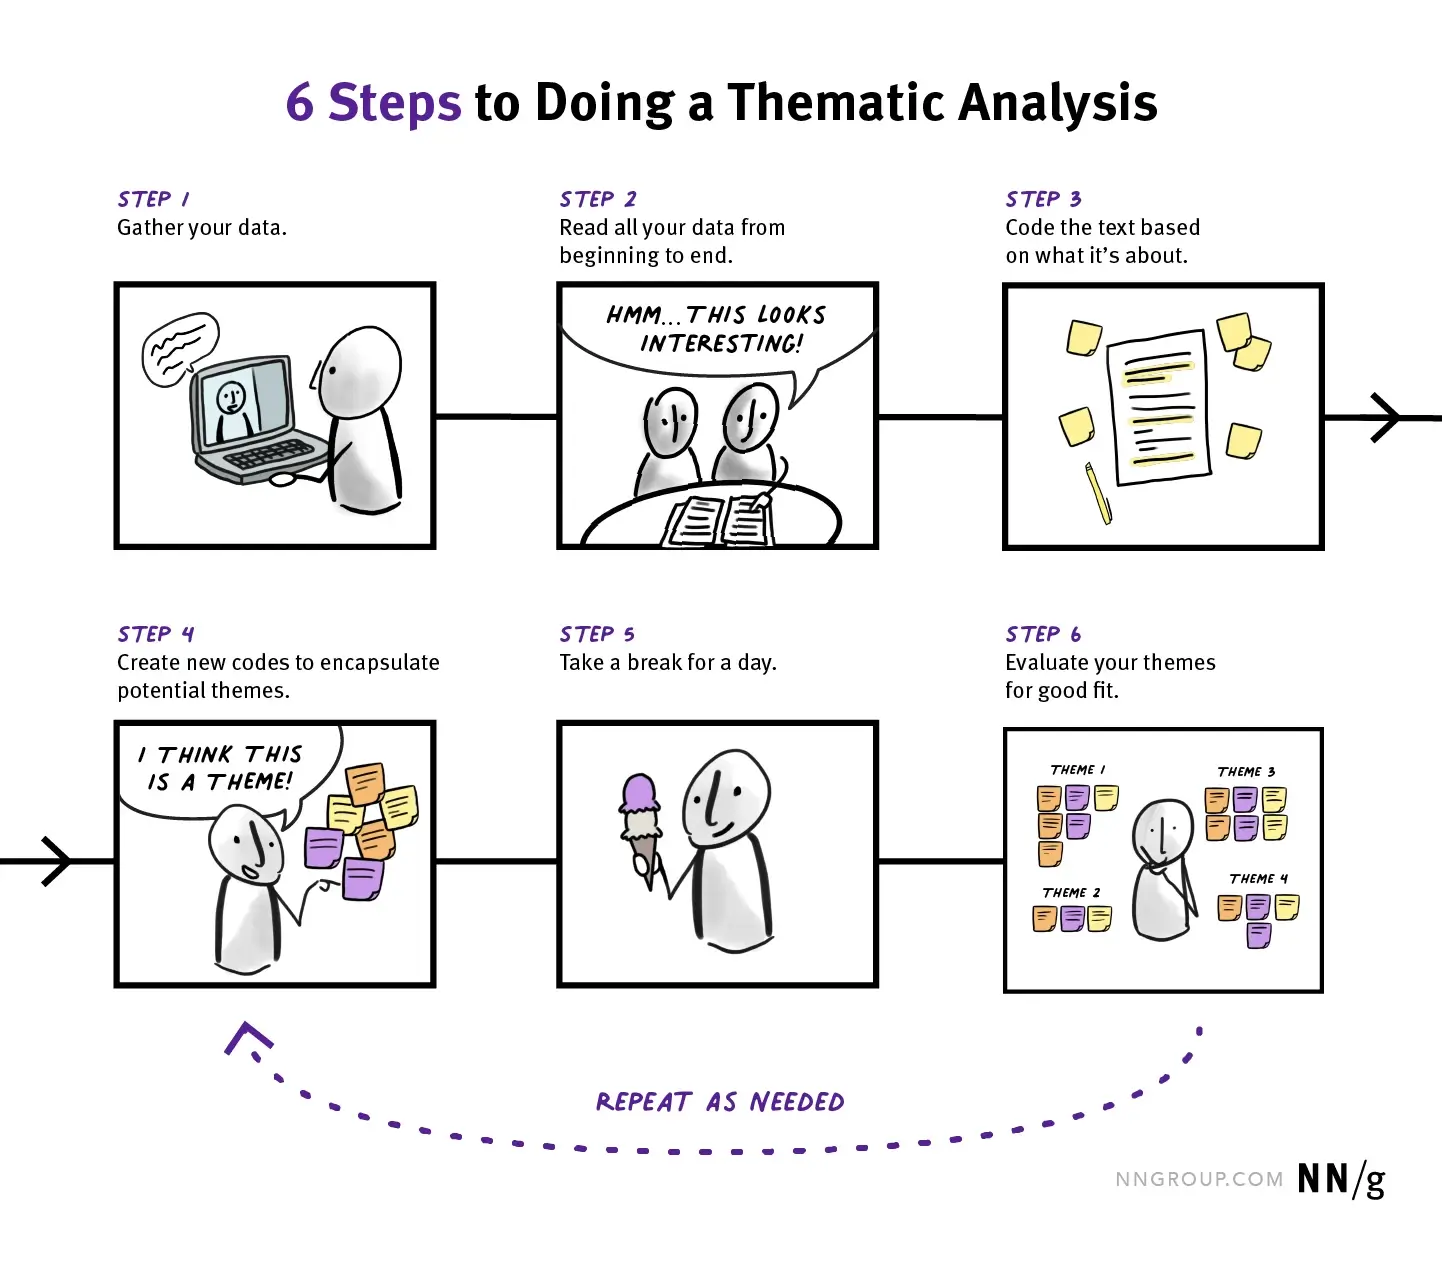
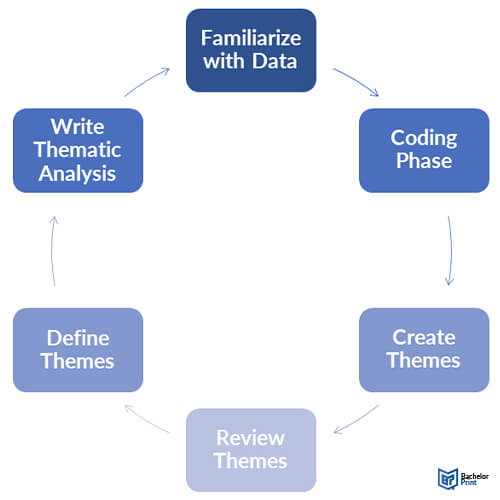
Most people learn thematic analysis from a textbook that makes it look like a clean five-step process. In practice it is messy, iterative, and requires a lot of repeated re-reading of the same transcript. I used to get frustrated with this early in my career. I would finish coding a full dataset and then realize my codes didn't actually answer the research question anymore. That happened because I had gone straight into thematic development without spending enough time on the preliminary familiarization phase. This is a fairly common mistake and one that costs people several days of wasted work. A thematic analysis example in practice usually starts with something like interview transcripts from a study on workplace remote culture. You are not looking for patterns that confirm your hypothesis. You are looking for what the data actually contains. The Braun and Clarke framework has six phases, and I will describe them in the order I actually use them rather than the textbook order. Phase one is familiarization. This means reading or listening to every piece of data without taking notes. I typically read each transcript twice before writing a single code. Some researchers skip this step because it feels unproductive, but it is the single most important quality control measure you have. When you skip familiarization, your codes become shallow summaries rather than meaningful interpretations.
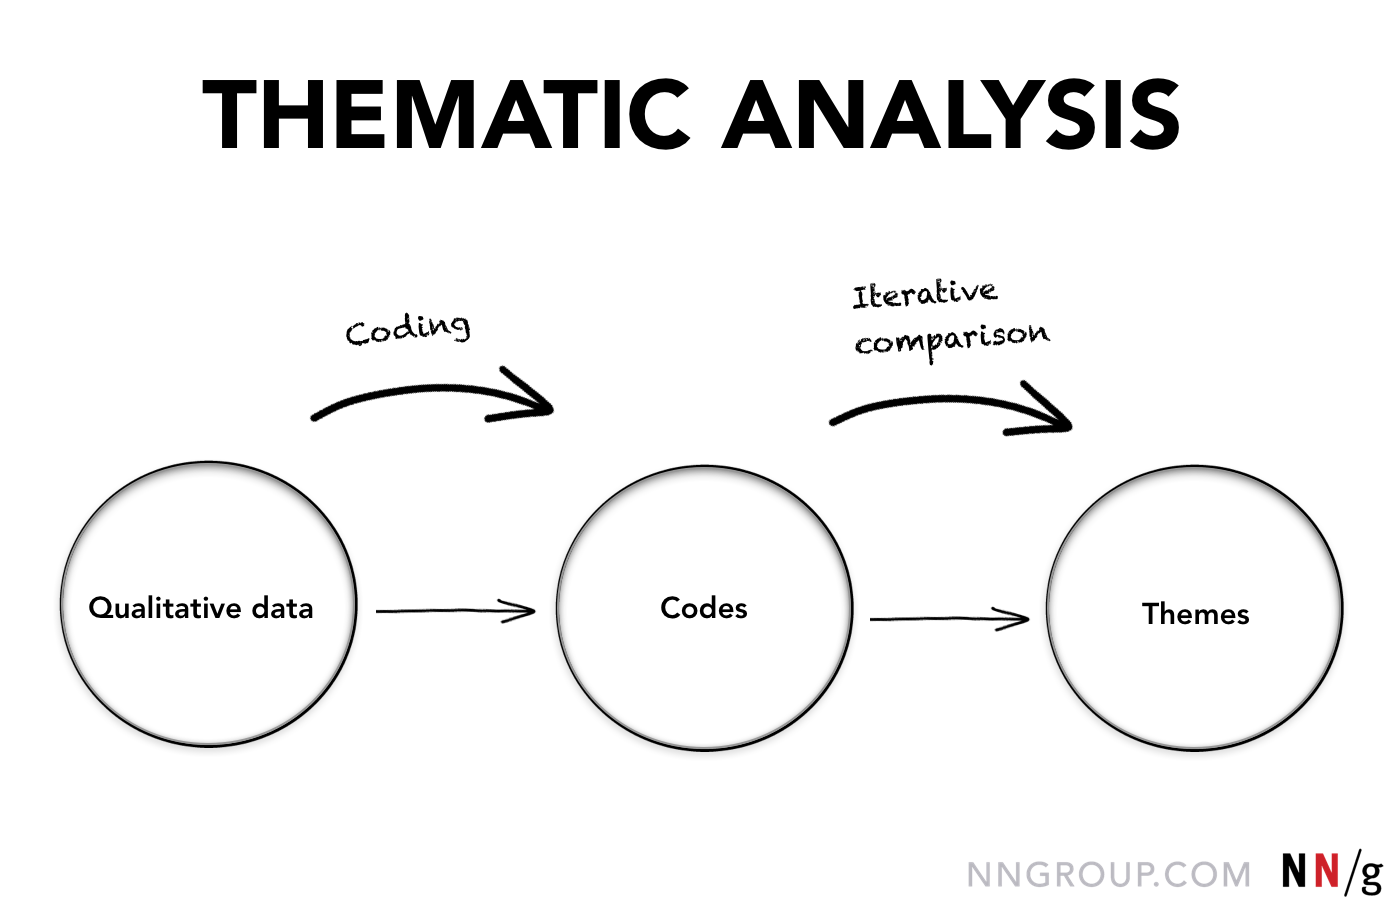
Phase two is generating initial codes. A code is simply a label that captures a meaningful feature of the data. The key word here is feature. You are not summarizing. You are labeling something specific that interests you. For example, in a dataset about remote work adaptation, one participant said, "I feel like I am always on call, even when I am off the clock." The code here might be "blurred work-home boundaries" rather than a vague label like "work stress." Specificity in coding makes the entire downstream process dramatically easier. Phase three is searching for themes. This is where you collect your codes and look for patterns that cluster together. A theme is not just a frequent topic. It is a pattern that means something significant about your research question. In my experience, the easiest mistake here is creating themes that are simply topics, like "technology problems" or "social isolation." Those are subjects, not themes. A theme requires an interpretive claim about the data. I once worked on a project where we had over two hundred initial codes across forty-five interview transcripts. The dataset was enormous and I spent roughly a week just sorting codes into potential theme groupings on a corkboard. I had about twelve potential themes at that stage. By the end of the week I had narrowed it down to four because three of the original themes overlapped significantly and two others had insufficient supporting data. This is a normal outcome and not a failure.
Phase four is reviewing themes. This phase has two levels. At the first level you check whether the themes work in relation to the coded extracts. At the second level you check whether the themes work in relation to the entire dataset. The second level is where most people discover that a theme looks good on paper but falls apart when you read all the data again. I have lost entire themes during this phase before. It is frustrating but necessary. Phase five is defining and naming themes. This is where you write a clear definition for each theme that explains what it covers and what it does not cover. A good theme definition includes the scope, the boundary conditions, and the relationship to the research question. Without this step your analysis becomes impossible for readers to evaluate. Phase six is producing the report. This is not a separate phase but rather the writing process. You are selecting vivid extract examples, relating them back to the research question, and constructing a coherent narrative. Most academic journals expect you to present your themes as a structured argument, not as a list of findings.
Get the Full Details
The Practical Problems Nobody Warns You About
One issue that comes up repeatedly is the temptation to code too granularly. Early in my career I produced over eight hundred codes for a dataset that ultimately yielded only six themes. The codes were so fine-grained that they lost their analytic utility. A practical rule of thumb is that if you cannot articulate what a code means in one sentence, it is probably too granular or too broad. I now aim for roughly fifty to one hundred codes per twenty transcripts, which gives me enough material to develop themes without drowning in detail. Another problem is researcher bias sneaking into the coding process. This is not the kind of bias that ethical review boards worry about. It is the much more mundane problem of coding data in a way that supports your preconceived notions. The standard workaround is reflexive journaling, which is simply a written record of your analytical decisions and assumptions. I keep a separate document where I note every time I moved a code from one theme to another and why. This creates an audit trail that reviewers and collaborators can examine. The most counter-intuitive thing about thematic analysis is that it is not inherently qualitative in the way people assume. You can quantify your themes by counting code frequency. Some researchers do this without issues. Others find that the quantification undermines the interpretive nature of the analysis. I tend to count codes after the analysis is complete, primarily to check whether a theme is underrepresented in the data. The numbers do not replace the qualitative interpretation. They flag potential gaps.
I should also mention the software question because people always ask about it. NVivo, Atlas.ti, and Dedoose all handle thematic analysis competently. I use NVivo as my primary tool because it handles large datasets well and the query functions are useful for checking code overlap. However, I have seen researchers produce excellent thematic analyses using only spreadsheets and highlighters. The tool matters less than the rigor of the coding process.
When Thematic Analysis Is the Wrong Tool
Thematic analysis works well for exploratory research, for studies with multiple datasets, and for research questions that ask what people think, feel, or experience. It does not work well when you need to account for power dynamics, when the data is highly structured like policy documents with explicit hierarchies, or when you need to track how meaning changes over time within the same dataset. In those cases you should consider discursive psychology, critical discourse analysis, or narrative analysis instead. These methods are more appropriate because they treat language as a form of social action rather than as a transparent window into participants' beliefs. There is also a practical limitation that is easy to overlook. Thematic analysis assumes that the researcher can reliably identify themes in their own data. This breaks down when you are analyzing large community datasets with hundreds or thousands of participants. The process becomes impractical beyond roughly fifty in-depth interviews or equivalent document volume. In those situations you would need to combine thematic analysis with other methods or shift to a different analytical approach entirely. If you are new to this method, the most efficient path is to watch someone code a dataset in real time before you attempt it yourself. Reading six papers on thematic analysis will not teach you the practical judgment that comes from seeing where someone puts a borderline code and whether they keep it or discard it. There are several free sample datasets available on university research websites that include both the raw transcripts and the coded versions. Comparing the raw data to the final coded output is probably the fastest way to understand what good thematic analysis looks like in practice.