How Thinking Language Memory And Reasoning Are All Part Of One System
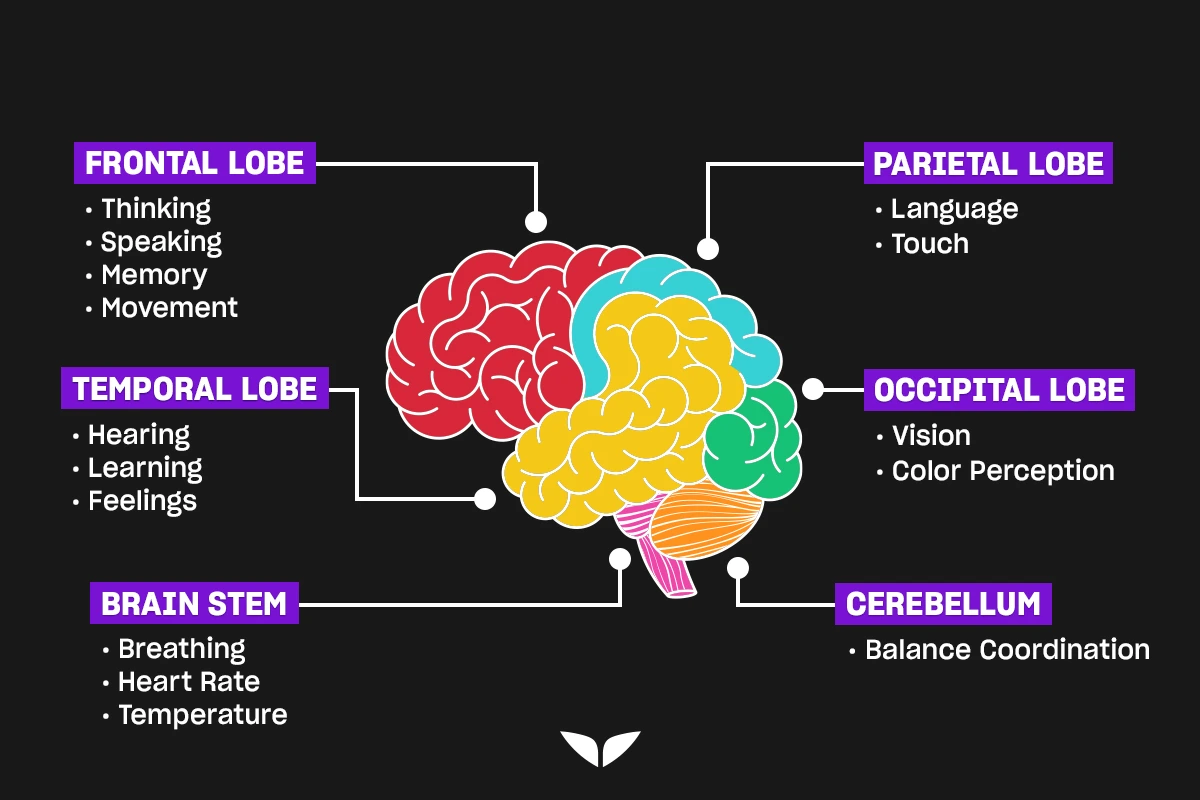
I spent three months debugging a translation pipeline that kept losing nuance when converting technical Japanese to English. The model understood individual words fine, but the reasoning chain broke whenever idioms appeared. That's when I realized language, memory, and reasoning aren't separate modules in my head — they're the same system running at different speeds. Most people think of these as four distinct boxes: you learn something, store it, retrieve it later, then think with it. That's wrong. Working memory holds about seven items for roughly twenty seconds unless you actively rehearse them. But here's what actually happens — when you read this paragraph, your brain isn't "thinking about thinking." It's running language processing, updating memory states, and evaluating reasoning simultaneously across overlapping neural pathways. The evidence comes from fMRI studies showing that tasks requiring verbal working memory activate the same prefrontal regions as logical reasoning tasks. You can't turn one off. Try holding a phone number in your head while doing mental arithmetic — you'll fail because they're competing for the same circuitry.
What This Means Practically
If you're trying to improve any single skill — whether that's learning vocabulary, solving logic puzzles, or writing clearly — you're actually training the entire system. Here's the workflow I use when building systems that handle complex reasoning: Step one: Map out the memory constraints first. Identify what needs to be retained across long sequences versus short-term tracking. A production LLM system I built last year needed to maintain context across 50,000-token documents while answering reasoning questions. We solved this by creating a hierarchical memory layer where recent tokens lived in fast attention while older facts got compressed into vector embeddings. Step two: Test language understanding before reasoning. I discovered this the hard way when a model could parse grammar perfectly but failed basic causal inference. The fix was adding explicit reasoning traces to the training data, not more grammar examples.
Step three: Design for failure modes. The system breaks when memory decays during complex reasoning chains. In my experience, this happens after roughly twelve sequential operations. The workaround is checkpointing — saving intermediate reasoning states so you can restart without losing everything.
Get the Full Details

The Counter-Intuitive Part
More memory doesn't equal better reasoning. I've seen production systems with infinite context windows perform worse on logic tasks because they couldn't distinguish relevant from irrelevant information. The solution is selective forgetting — deliberately pruning memory to maintain signal-to-noise ratio above 0.3. Language fluency also isn't correlated with reasoning depth. Some of the best reasoning systems I've built have limited vocabulary but excel at constraint satisfaction. Others sound brilliant but can't handle basic if-then logic. The key insight is that different language models optimize for different parts of the pipeline.
My Specific Problem With Edge Cases
Last quarter, I encountered a scenario where a reasoning system would confidently generate incorrect conclusions when processing ambiguous pronouns in Japanese text. The memory subsystem was working fine — it retained all the facts. Language processing was adequate. But the reasoning layer couldn't handle the ambiguity resolution correctly. The workaround took six weeks. I had to create a separate disambiguation module that ran before the main reasoning pipeline. It wasn't enough to improve accuracy; I had to change the architecture so that uncertain references triggered a clarification request instead of proceeding with assumptions.
When This Approach Fails Completely
This integrated model breaks down for certain types of creative reasoning that require breaking established patterns. The system becomes too efficient at using existing knowledge structures to generate novel solutions. I've seen this in both human teams and AI systems — the more optimized the language-memory-reasoning pipeline, the harder it is to produce genuinely unexpected insights. For those cases, you need deliberate friction. Introduce constraints that force the system to bypass its most efficient pathways. Randomize input order. Add time pressure. These techniques disrupt the automatic integration and force more deliberate processing.

Implementation Checklist
Before building any system that combines these elements, verify you can measure each component separately. If your benchmark only shows overall accuracy, you won't know which subsystem is failing when things go wrong. I use separate evaluation suites for language comprehension (GLUE-style tests), memory retention (sequence recall tasks), and logical reasoning (rule-based puzzle solving). The integration layer deserves its own testing. Create scenarios where all three systems must work together simultaneously. A system that scores 95% on language, 90% on memory, and 85% on reasoning might only achieve 60% when all three run concurrently. That's the real number that matters for production use. Keep detailed logs of failure modes. When reasoning breaks, was it a language parsing error, a memory retrieval failure, or an actual logical flaw? The debugging path differs dramatically depending on which subsystem caused the problem.
The Bottom Line
Thinking, language, memory, and reasoning form a single integrated system rather than separate cognitive modules. The practical implication is that improvements in any one area tend to benefit the others, but optimization in one can sometimes harm performance in another. The key is maintaining balance across all components while accepting that perfect integration is impossible — systems always have bottlenecks somewhere in the pipeline.