Why Most Threat Hunting Fails Before It Starts
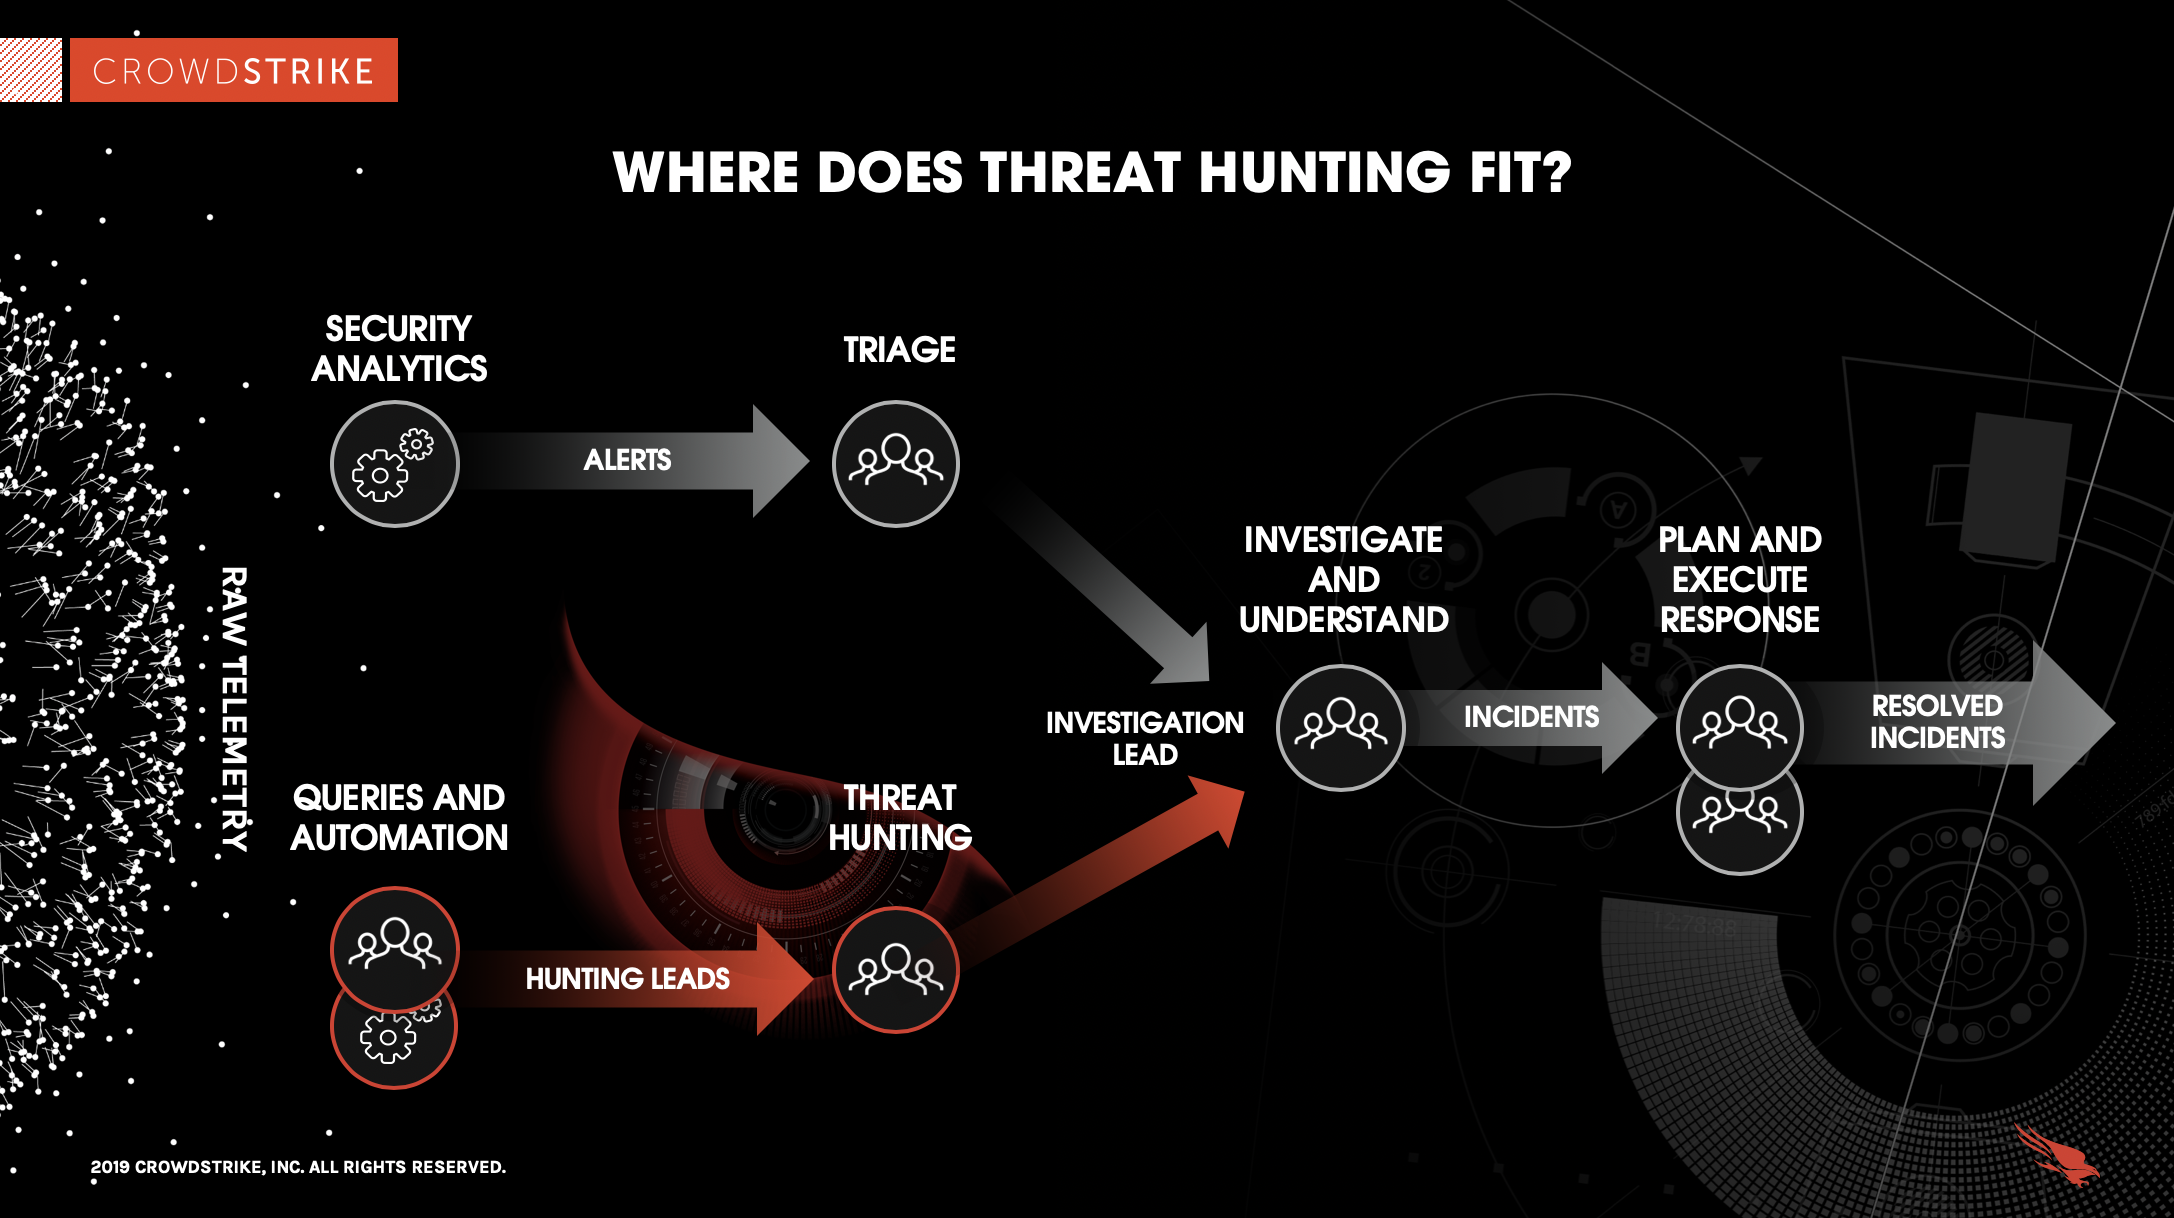
I spent about three years running threat hunting programs at two different organizations. Both had decent SIEM tooling, both had SOC analysts who could actually read logs, and both programs stalled out within twelve months. The problem wasn't the tools or the people. It was the approach. Let me explain what I learned, starting with the thing nobody talks about: threat hunting is mostly a noise reduction problem, not a detection problem. You can write a hundred sophisticated hypotheses about adversary TTPs, but if your data pipeline can't reliably surface the signals you care about, those hypotheses are just exercises in disappointment. The first organization I worked with was running threat hunting on CrowdStrike and Sentinel. We had telemetry from endpoints, network flows, cloud logs, and DNS data. Good setup on paper. What went wrong was that we started with the "we should look for APT patterns" mindset instead of starting with the question: what does normal look like in this environment, and where are the gaps?
Getting Started With Threat Hunting
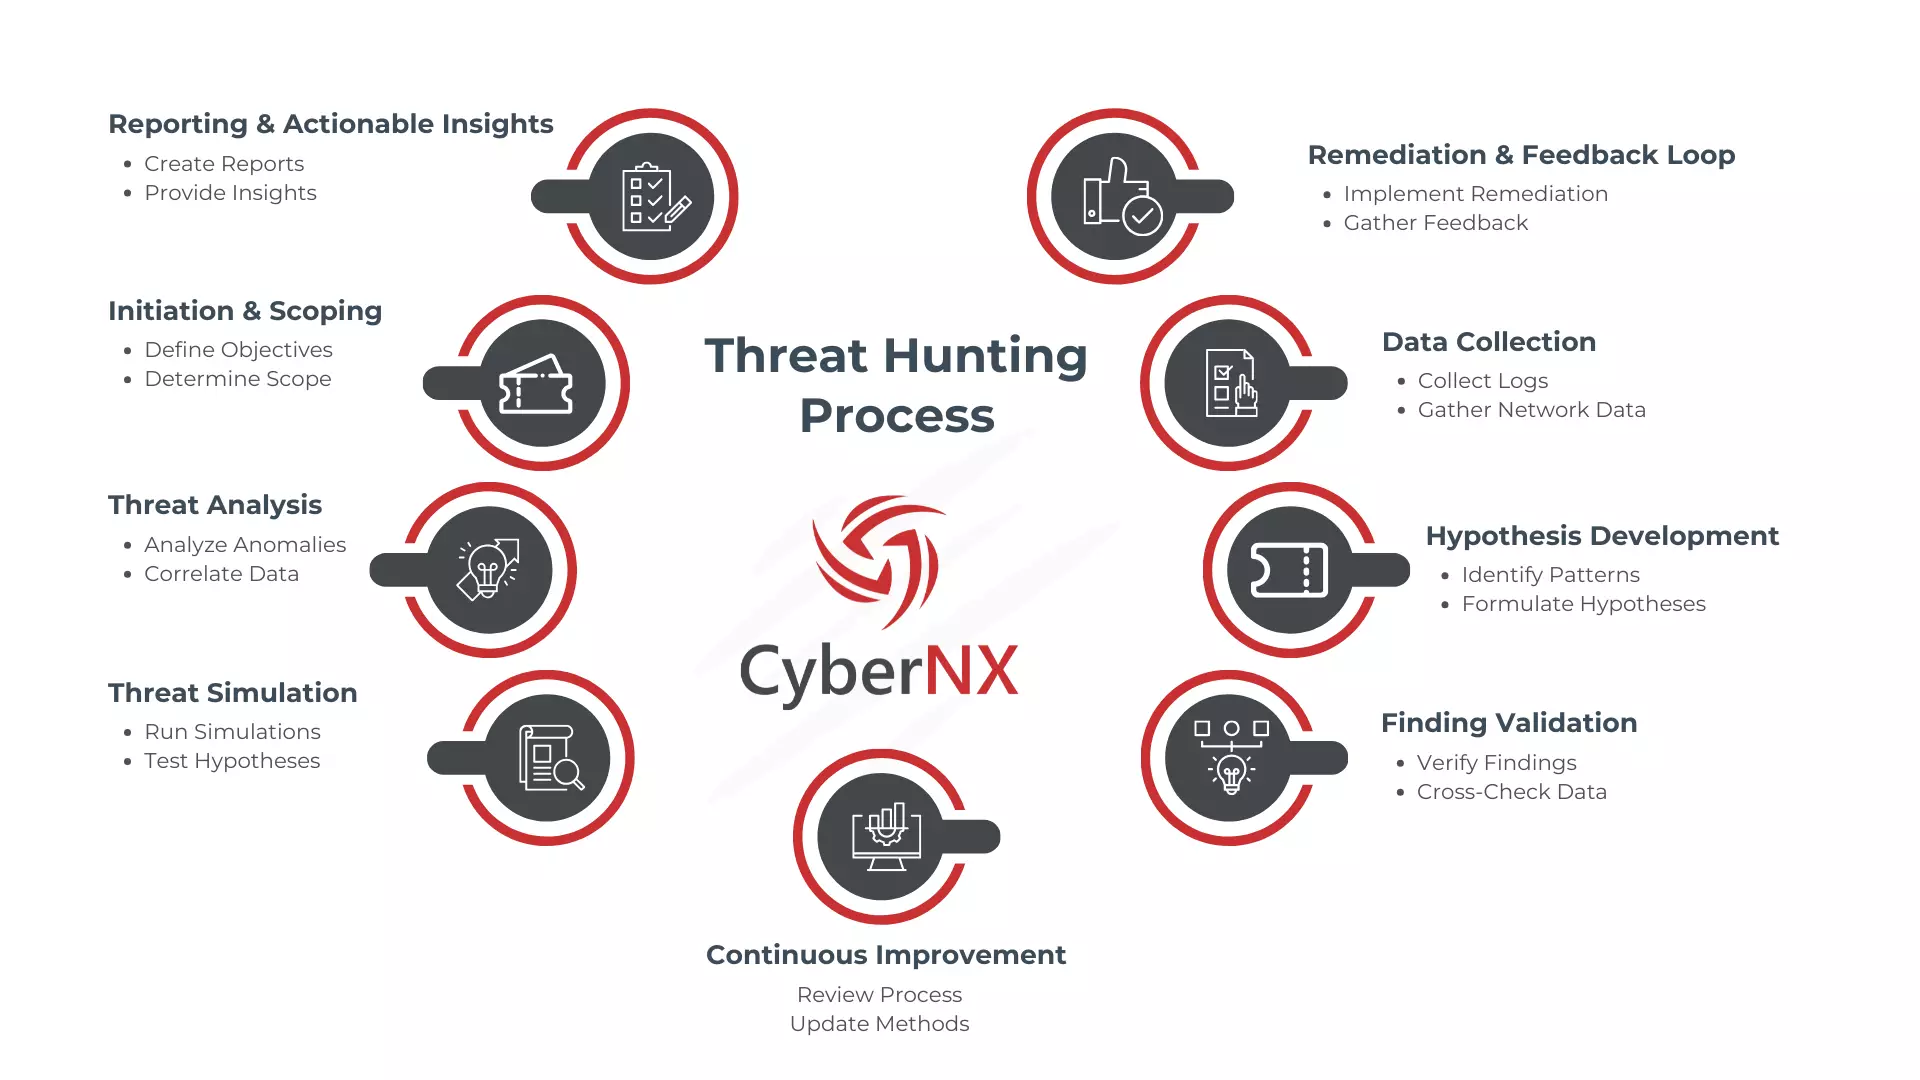
Before you write a single hunt query or hypothesis, you need to answer three questions. First, what data do you actually have, and how complete is it? Second, what are your highest-value assets and the likely paths an attacker would use to reach them. Third, what do you already know about your own environment that could confuse a hunt result? That third one matters more than people admit. I once spent two weeks investigating what looked like a credential harvesting campaign, only to realize we were looking at a legitimate software update process from a vendor that happened to use the same command-line flags as Cobalt Strike's implant runner. The logs told the truth. My interpretation was wrong because I didn't talk to the application team first. Here's a practical workflow that actually works:
Map your environment's data sources and understand their coverage gaps. This usually takes a week if you're organized, longer if your logging is scattered across teams who don't talk to each other. Document what you can see, what you can't, and where the blind spots are. The blind spots are where threats hide, so knowing them is valuable even if you never hunt there. Define your initial hypotheses based on the MITRE ATT&CK framework, but keep them narrow. Instead of "look for lateral movement," start with "check for PsExec-style SMB connections between workstations that shouldn't be talking to each other." Narrow hypotheses produce cleaner results and teach your team how to think about the data. Build a baseline of normal activity before you try to find anomalies. This doesn't mean months of data collection. Two to four weeks of focused observation on a small set of behaviors gives you enough context to spot genuine outliers without burning half your quarter on telemetry gathering.
Get the Full Details

Run hunts on a schedule, not ad hoc. I preferred biweekly sessions where the team reviewed open hypotheses, ran queries, and documented findings together. The session format matters less than the consistency. Ad hoc hunting gets deprioritized every time something louder comes up, and you end up with no pattern and no progress. Document everything. Findings, false positives, hypotheses that led nowhere, and especially the ones that did lead somewhere. Your documentation is the only reason anyone remembers how to do this when you're not in the room.
The Data Problem Nobody Admits To
Most threat hunting programs fail because of bad data, not bad methodology. I've seen this repeatedly. A team will have excellent hypothesis frameworks and deep knowledge of adversary behavior, then realize halfway through their first productive hunt that their endpoint agent isn't actually capturing command-line arguments, or their firewall logs are being truncated at 256 characters, or their DNS logs only go back fourteen days. This is why the data audit at the beginning isn't optional. You need to verify, with actual sample queries, that the logs you think you're getting are real and complete. Check the field lengths, the timestamps, the completeness rates. Most organizations discover at least one gap this way, and fixing it before hunting starts saves weeks of frustration later. The hardest gap to fix is usually application-level telemetry. Network and endpoint logs are relatively standardized now. Application logs vary wildly depending on what the dev team chose to capture, and they rarely capture what security needs. I've had to negotiate with three different engineering teams just to get meaningful authentication failure logs from a custom CRM system. None of them considered that anyone outside their squad might need to read those logs.
If you're working with a SIEM that supports it, build lookup tables for assets, users, and normal service relationships. When you can join a login event to a CMDB record showing that the source IP is a known jump host, or that the target system handles PCI data, your signal-to-noise ratio improves dramatically. Without these lookups, you're just reading raw events and hoping to notice patterns by eye.
Hypothesis Development That Actually Works
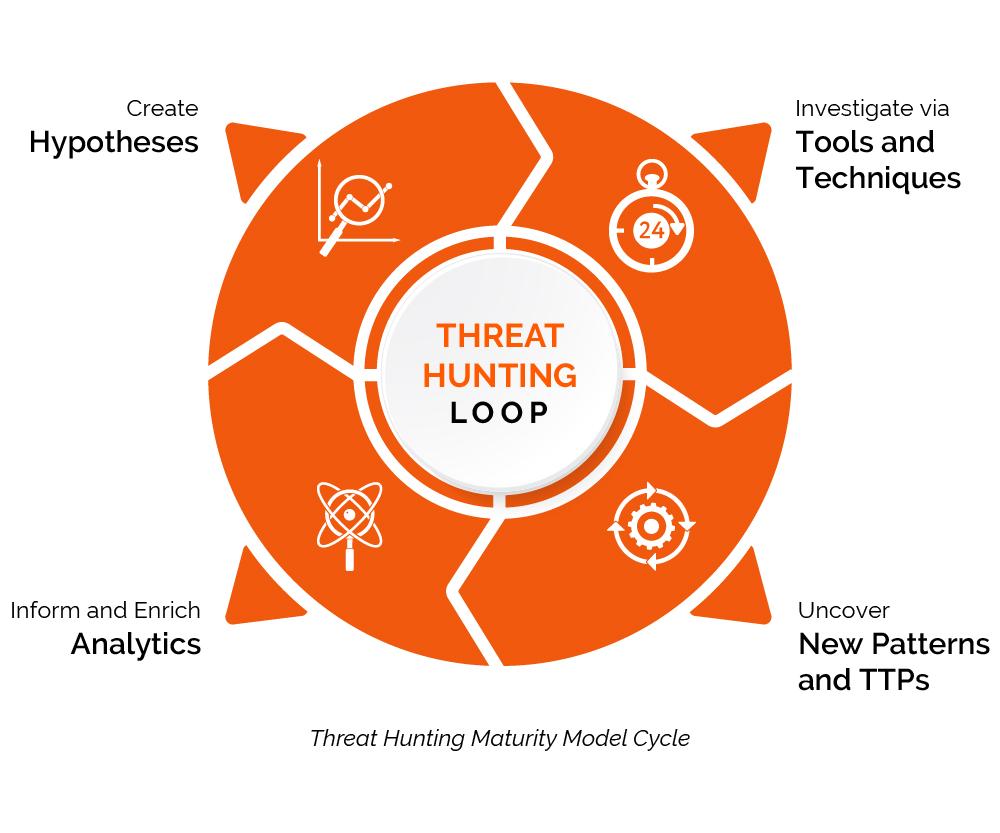
The biggest mistake I see with beginners is writing hypotheses that are too broad or too speculative. "Look for signs of an intruder" is not a hypothesis. It's a wish. A proper hypothesis needs a specific behavior, a specific data source, and a condition that filters out most normal activity. Here's what a good hypothesis looks like in practice: We expect to find instances where a workstation on the engineering VLAN initiates PowerShell sessions to systems outside the VLAN within thirty minutes of a successful RDP session from an external VPN address. This would indicate potential credential use for lateral movement after initial access.
That's testable. You know exactly which data sources to query, what the time window is, and what constitutes a match. You also know what to expect in the normal case: engineers might RDP to one or two systems on their own VLAN, but they don't typically go further, and they don't typically use PowerShell over the network this way. Another common pattern to hunt for involves scheduled task abuse. Many defenders focus on PowerShell and WMI for persistence detection, but scheduled tasks are far more common in real compromises because they don't require dropping executables and they survive reboots automatically. I found a persistence mechanism this way that evaded every other detection rule because the implant was a legitimate script file calling PowerShell with encoded arguments, registered as a scheduled task under the SYSTEM context. When developing hypotheses, always ask: what would a legitimate process look like that produces similar signals? The credential harvesting and scheduled task examples above both have legitimate counterparts. Your hunt should be able to distinguish between them, or at least flag the ambiguous cases for manual review. If your hypothesis can't account for normal activity, you'll drown in false positives and stop running it after the third round.
Tools and Techniques
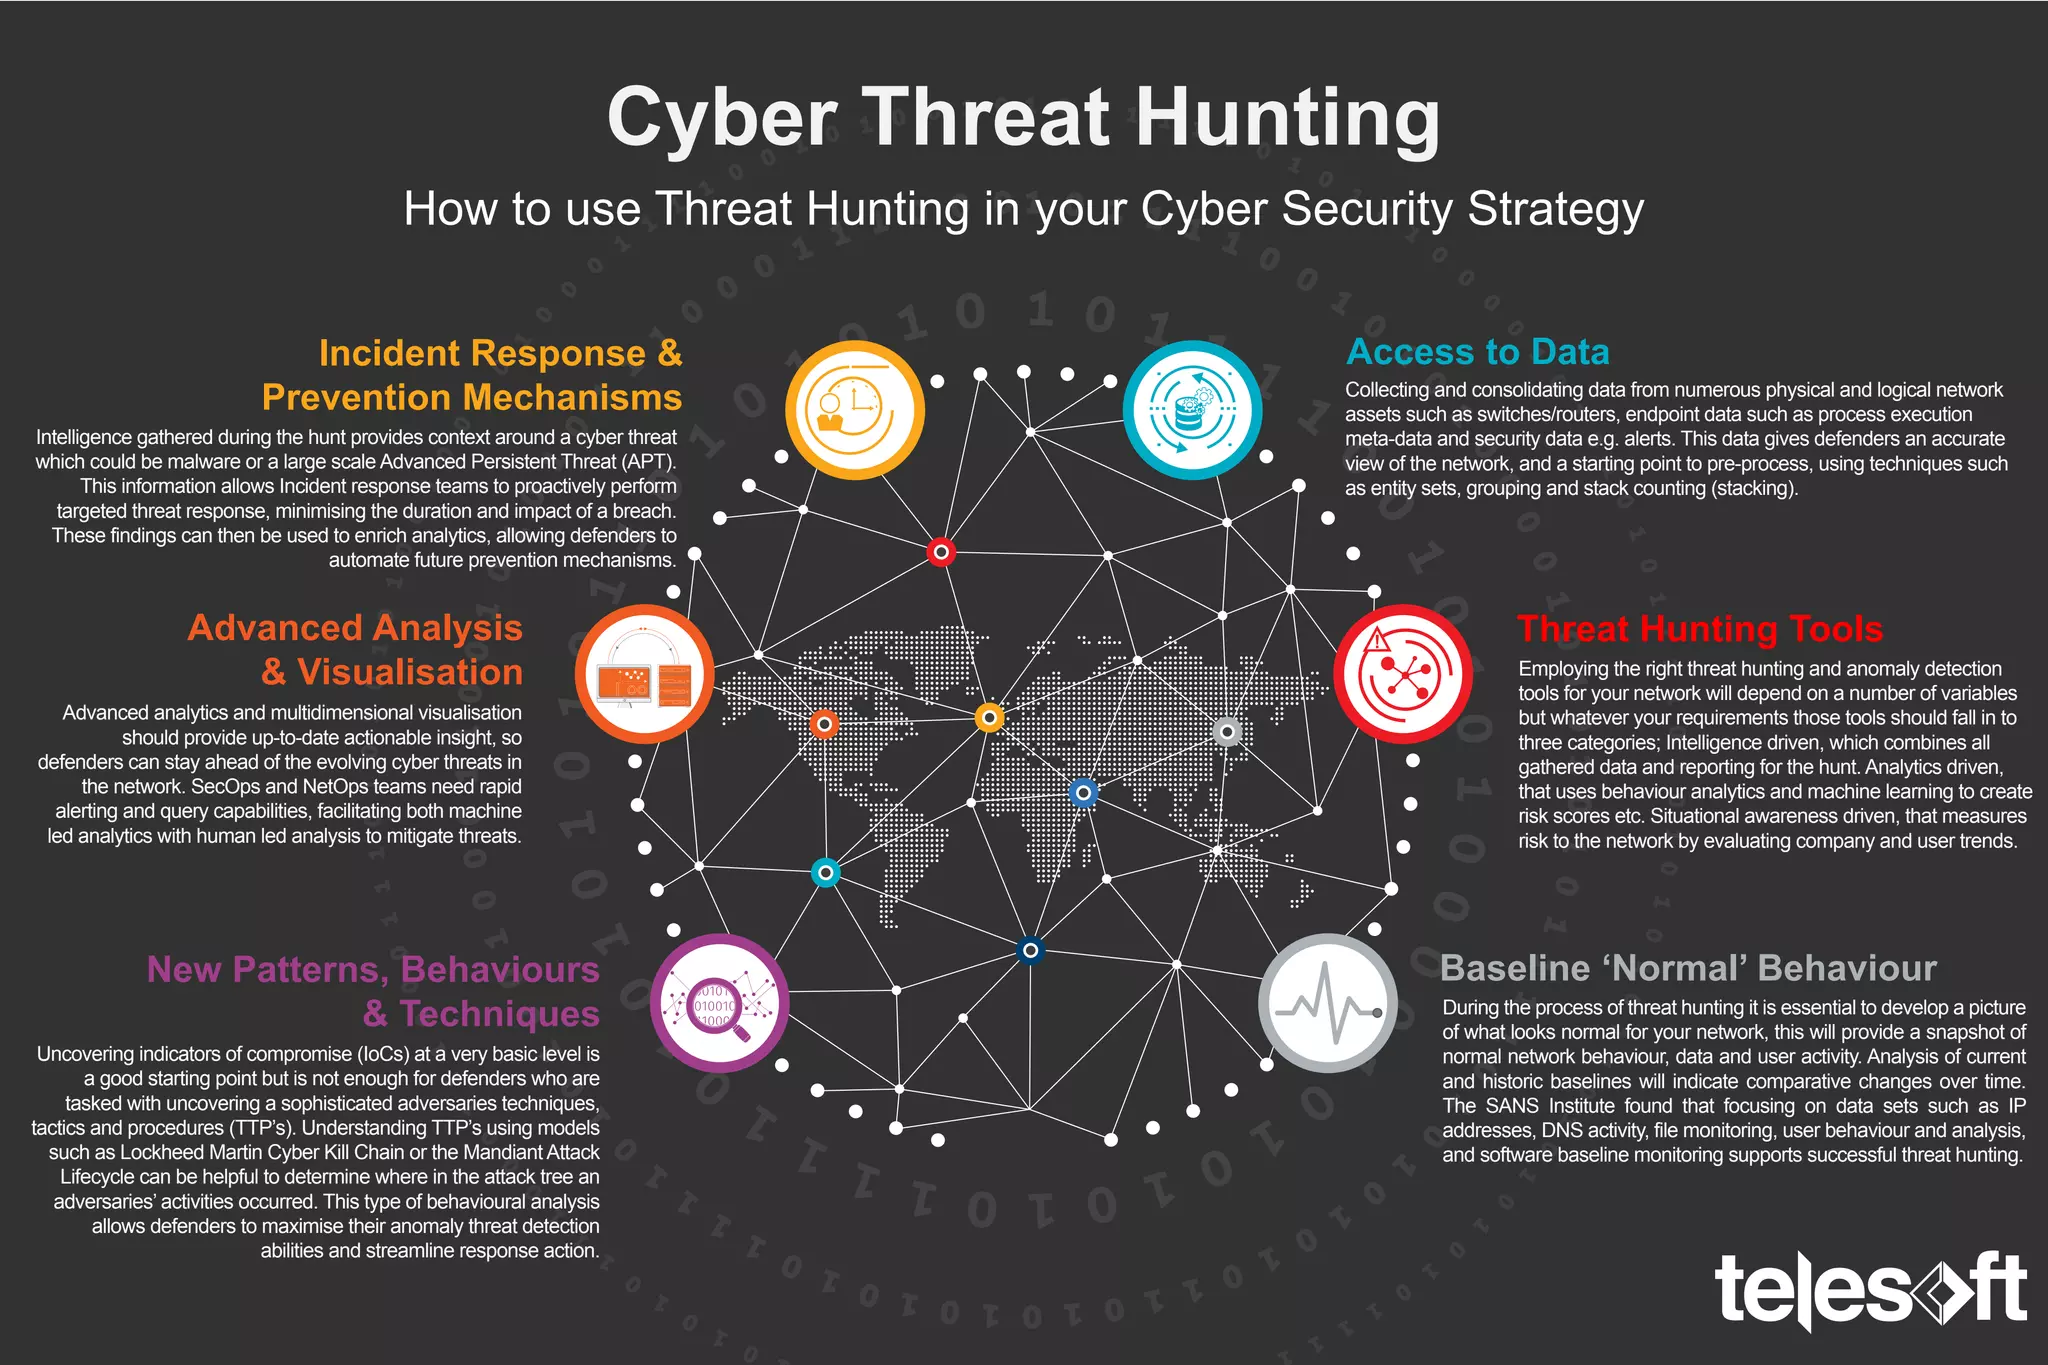
The tool choice matters less than people think, but some choices make life genuinely easier. KQL for Sentinel, Sigma for vendor-neutral detection logic, and Python or PowerShell for anything that requires custom logic. You don't need exotic tools. You need consistency in how you query and a way to version your hunt logic so you can reproduce results. For the actual hunting, I used a combination of SIEM search languages and direct log analysis. When a hypothesis was complex or required joining multiple data sources that the SIEM didn't handle well, I'd pull raw events and process them in Python. This was faster than trying to build elaborate SIEM workflows for one-off investigations. Network-based hunting requires packet captures or NetFlow data. If you have full packet capture, use Bro/Zeek or similar to generate structured logs before you search them. Searching PCAPs directly is slow and error-prone. If you only have NetFlow, you can still find anomalies in connection patterns, but you lose the ability to inspect payload content, which limits what you can detect.

Cloud environments add complexity because the telemetry model is different from on-premises. AWS CloudTrail, Azure Activity Log, and GCP Audit Logs each have their own quirks around retention, field naming, and what they capture by default. You need to verify that your org-level logging is enabled for the right API calls, particularly for IAM changes and storage bucket access. These are the signals that matter most in cloud environments, and they're often disabled by default or buried in optional settings.
Common Pitfalls and How to Avoid Them
The first pitfall is confirmation bias. You develop a hypothesis, run it, find something interesting-looking, and then spend days confirming your suspicion without seriously testing whether there's an innocent explanation. I caught myself doing this after finding a suspicious process execution on a dev server. It looked like a reverse shell pattern, and I was ready to declare a compromise. The innocent explanation was a routine monitoring agent that pushed shell commands to collect disk metrics, using a similar command structure to known malicious tools. Avoid this by actively seeking disconfirming evidence. For every finding, ask: what would prove this is legitimate? If you can't find that explanation, escalate it. If you can, document it and move on. Either way, you should be able to explain your reasoning to someone who wasn't involved in the investigation. The second pitfall is alert fatigue from poor hypothesis tuning. When you run a hunt that produces fifty hits, most of them will be noise. The team loses confidence in the process, and the hunt gets dropped. The fix is to tighten your hypothesis iteratively. Start broad to understand the landscape, then narrow based on what you learn. After three or four iterations, you should be down to a manageable number of hits that warrant manual review.
A related problem is not closing loops. When a hunt returns a finding, someone needs to investigate it and document the outcome. Too many teams run hunts, generate a report, and never follow up on individual findings. This creates a cycle where the same hypotheses produce the same uninvestigated hits month after month, and nobody learns anything. The third pitfall is treating threat hunting as a standalone activity instead of feeding it into your overall security program. Hunt findings should inform detection engineering, incident response playbooks, and defensive controls. If you run a hunt that reveals a gap in your logging and don't fix the logging, you've wasted the opportunity. The hunt is only as valuable as the actions it triggers.
A Specific Edge Case From Experience
Here's a scenario I dealt with that illustrates why context matters more than any tool. We were hunting for data exfiltration via DNS tunneling, which is a relatively uncommon technique. Our hypothesis was solid: look for abnormally long subdomain labels, high query frequencies from single hosts, and unusual TXT or CNAME record types. We found one host generating thousands of DNS queries per hour with long subdomain labels. It matched every criterion in our hypothesis. The initial reaction was strong suspicion. But before escalating, I checked the hostname against our asset database and discovered it was a CI/CD build server that deployed to a CDN with a domain structure requiring long DNS names. The queries weren't tunneling traffic. They were legitimate CDN cache lookups. The workaround was straightforward but easy to miss without that step: correlate every hunting finding with asset inventory before declaring it suspicious. I added a mandatory CMDB lookup to our hunt workflow after this incident, and it saved us from at least two other false alarms in the following months. The lesson isn't that DNS tunneling detection doesn't work. It's that any detection technique will produce false positives if you don't account for your environment's unique normal.
Measuring Whether Your Program Works
Most teams measure threat hunting success by the number of hunts run or findings produced. These are vanity metrics. A better measure is time to detect specific attack chains, and whether your hunt findings led to actual improvements in detection coverage or defensive controls. Track how many of your hunt findings result in new detection rules, changed configurations, or identified gaps in monitoring. If you run twenty hunts in a quarter and none of them produce actionable improvements, you're doing the activity without the outcome. That's not a hunting problem. It's a program design problem. The other measure is false positive rate per hunt. If your average hunt produces more than ten actionable findings per session, your hypothesis is probably too narrow or your environment is unusually hostile. If it produces zero actionable findings consistently, your hypothesis might be too broad, or you might not have the right data. Both cases need adjustment.
Where This Approach Breaks Down
Threat hunting is not a replacement for monitoring and alerting. It's a complementary activity that fills gaps in automated detection. If your organization has no baseline monitoring, no alert triage process, and no incident response capability, threat hunting will overwhelm you. You'll find things you can't respond to, and the findings will gather dust while the underlying problems persist. It also doesn't scale well for small teams without dedicated time. If your analysts are spending seventy percent of their time on tickets and alerts, squeezing in hunting on Fridays won't produce results. The activity needs protected time and executive support, or it becomes just another checklist item that gets abandoned when something urgent arrives. Finally, threat hunting has diminishing returns in mature detection environments. If you already have robust EDR coverage, comprehensive logging, and automated detection rules for the attack techniques you're most concerned about, the incremental value of manual hunting decreases. In those environments, focus your hunting energy on the techniques that are hardest to automate: social engineering indicators, insider threat patterns, and novel attack methods that haven't been characterized yet.
The best threat hunting programs I saw were humble about their scope. They admitted what they couldn't detect, focused on the gaps that mattered, and treated every finding as information rather than victory. That attitude makes a bigger difference than any specific tool or technique.
