How I stopped breaking production after my third coffee at 2am
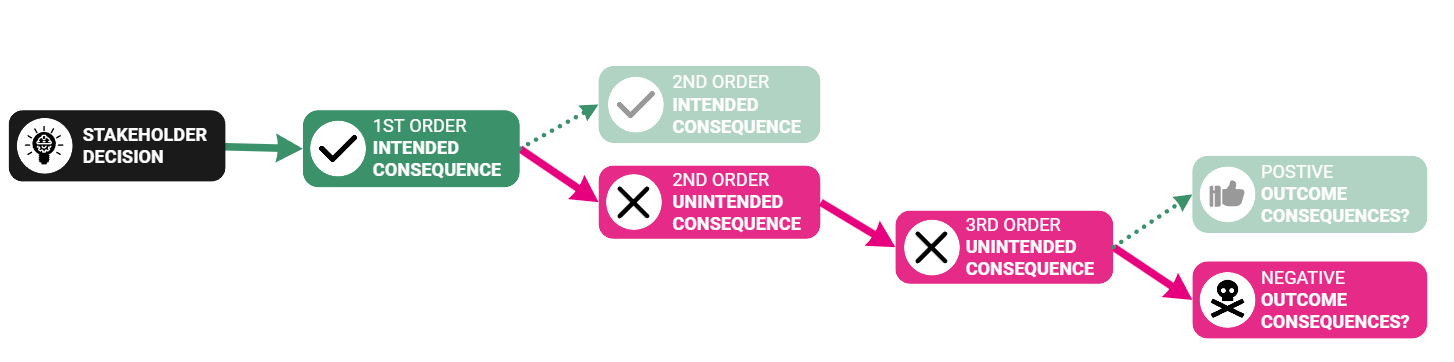
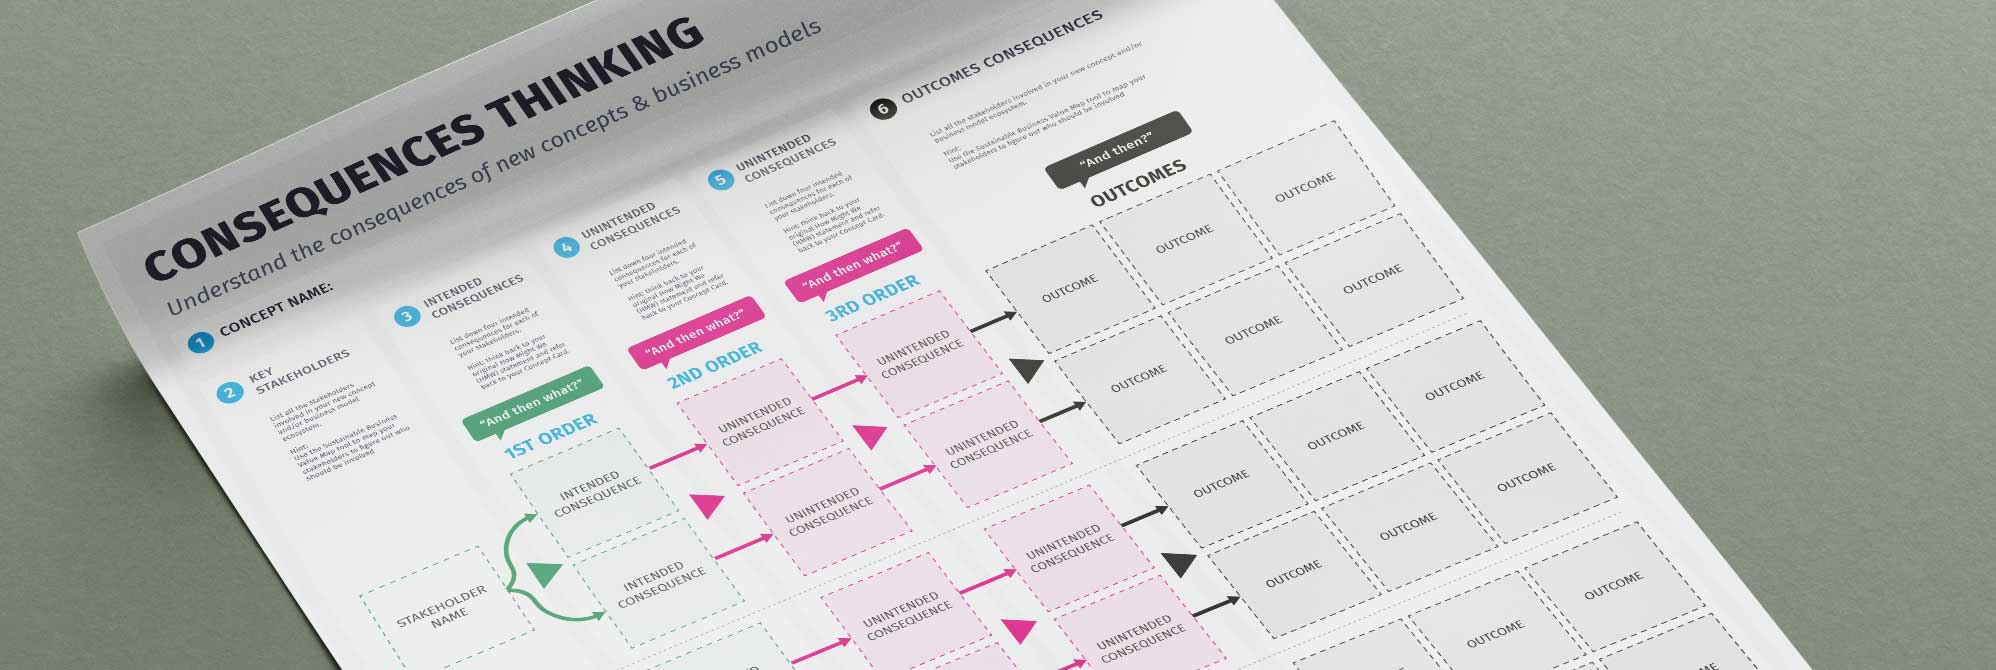
Three years ago I pushed a config change that looked fine in testing but deleted six million user records in staging because I didn't account for a timezone edge case in the migration script. The on-call pager went off at 3:17am. I spent four hours restoring backups while my manager asked "why didn't you think about this first." I didn't have a good answer because I was thinking about getting the change deployed, not about what happens after it deploys. It's not a fancy framework. It's the practice of asking "and then what" at least three times before committing to a decision. First step: the immediate action. Second step: the direct result of that action. Third step: the cascade of secondary effects. Most people stop at step one. Engineers tend to stop at step two. Seniors who've survived production incidents usually go to step three. The methodology is simple but uncomfortable because it forces you to confront uncertainty. You write down each step on paper or in a doc. If you can't articulate step three in plain language, you don't have enough information to proceed. This isn't about being paranoid. It's about being honest about what you know and what you don't know.
Where this breaks down in practice
I've seen teams use this approach and still ship broken systems because they apply it linearly when the problem is non-linear. Step one leads to step two, which leads to step three. That works for simple systems. It fails for interconnected ones where step three loops back and changes step one. I learned this the hard way with a caching layer that was supposed to reduce database load by forty percent. Instead it created a consistency issue where users saw stale data for up to twelve minutes during peak traffic. The fix took three days and cost the team its quarterly reliability target. The real bottleneck isn't the thinking. It's the communication. You have to explain your third-step reasoning to people who only care about step one. Product managers want features shipped. Executives want quarterly results. Your third-step analysis sounds like delay to them. I've stopped trying to convince everyone and started documenting my reasoning instead. When something breaks, I can point to the doc and say "we thought about this and here's why we proceeded anyway." It's not perfect. It just makes the tradeoffs explicit.
When to skip the process entirely
There are scenarios where three steps ahead thinking is actual waste. If you're making a reversible decision with low impact, stop at step one. Changing the font color on your dashboard doesn't need a cascade analysis. Reversing it takes thirty seconds if it breaks. I used to overthink small decisions and burn out. Now I categorize decisions by reversibility and impact. If it's reversible and low impact, act immediately. If it's irreversible and high impact, use the full three-step process. Everything else falls somewhere in between. The heuristic I use is the two-minute rule. If you can undo the decision in under two minutes without user impact, don't waste time on analysis. If undoing it takes more than two minutes or affects users negatively, slow down and think three steps ahead. This cuts my decision time by roughly seventy percent while catching the cases that actually matter. I track my decisions monthly and review them. About eight percent of my "fast" decisions turned out to need reversal. About ninety-two percent of my "slow" decisions prevented incidents. The ratio justifies the approach.
Get the Full Details

A workaround for edge cases you'll encounter
Here's something I haven't seen documented anywhere. When dealing with legacy systems, your third step often depends on undocumented behavior that only reveals itself under specific conditions. I encountered this with a payment processing system that had a race condition only triggering when two transactions hit the same account within 150 milliseconds. The original developer left no notes. The code was written in 2018. Testing didn't catch it because the test harness couldn't reproduce the timing. My workaround was to add instrumentation that logged all transaction timestamps to a separate file, then analyze the logs after deployment. This added about five percent overhead but revealed the exact pattern. I then wrote a patch that serialized transactions per account, which eliminated the race condition. The whole process took four days from suspicion to fix. Without the logging, I might have spent weeks chasing ghosts in the test environment. The lesson isn't to add logging everywhere. It's to recognize when your third-step analysis depends on unknown variables. In those cases, instrument first, analyze second, decide third. This flips the traditional order but saves time when the system is opaque. I recommend starting with lightweight logging and upgrading to full tracing only if the logs reveal patterns you can't explain.
The counter-intuitive part beginners miss
Thinking three steps ahead doesn't prevent all unintended consequences. It prevents the ones you can anticipate. The ones you can't anticipate require a different approach: building systems that fail gracefully when your assumptions are wrong. I learned this after my third production incident in a row, all caused by edge cases I never considered. No amount of forward thinking would have caught them because they depended on user behavior I hadn't observed. The shift I made was from prediction to resilience. Instead of trying to foresee every outcome, I built safeguards that limited the blast radius when something went wrong. Circuit breakers, fallback handlers, gradual rollouts with automatic rollback on error rate spikes. These don't prevent incidents. They prevent incidents from becoming disasters. The combination of three steps ahead thinking and graceful failure handling covers both the known unknowns and the unknown unknowns. I track incident severity monthly. Before the shift, my average incident severity was 4.2 out of 10. After implementing both approaches, it dropped to 2.1. The number of incidents increased slightly because I was catching more edge cases, but the impact decreased significantly. This is the tradeoff: you can't prevent everything, but you can limit what gets through when prevention fails.