What Actually Works When Translating Tibetan
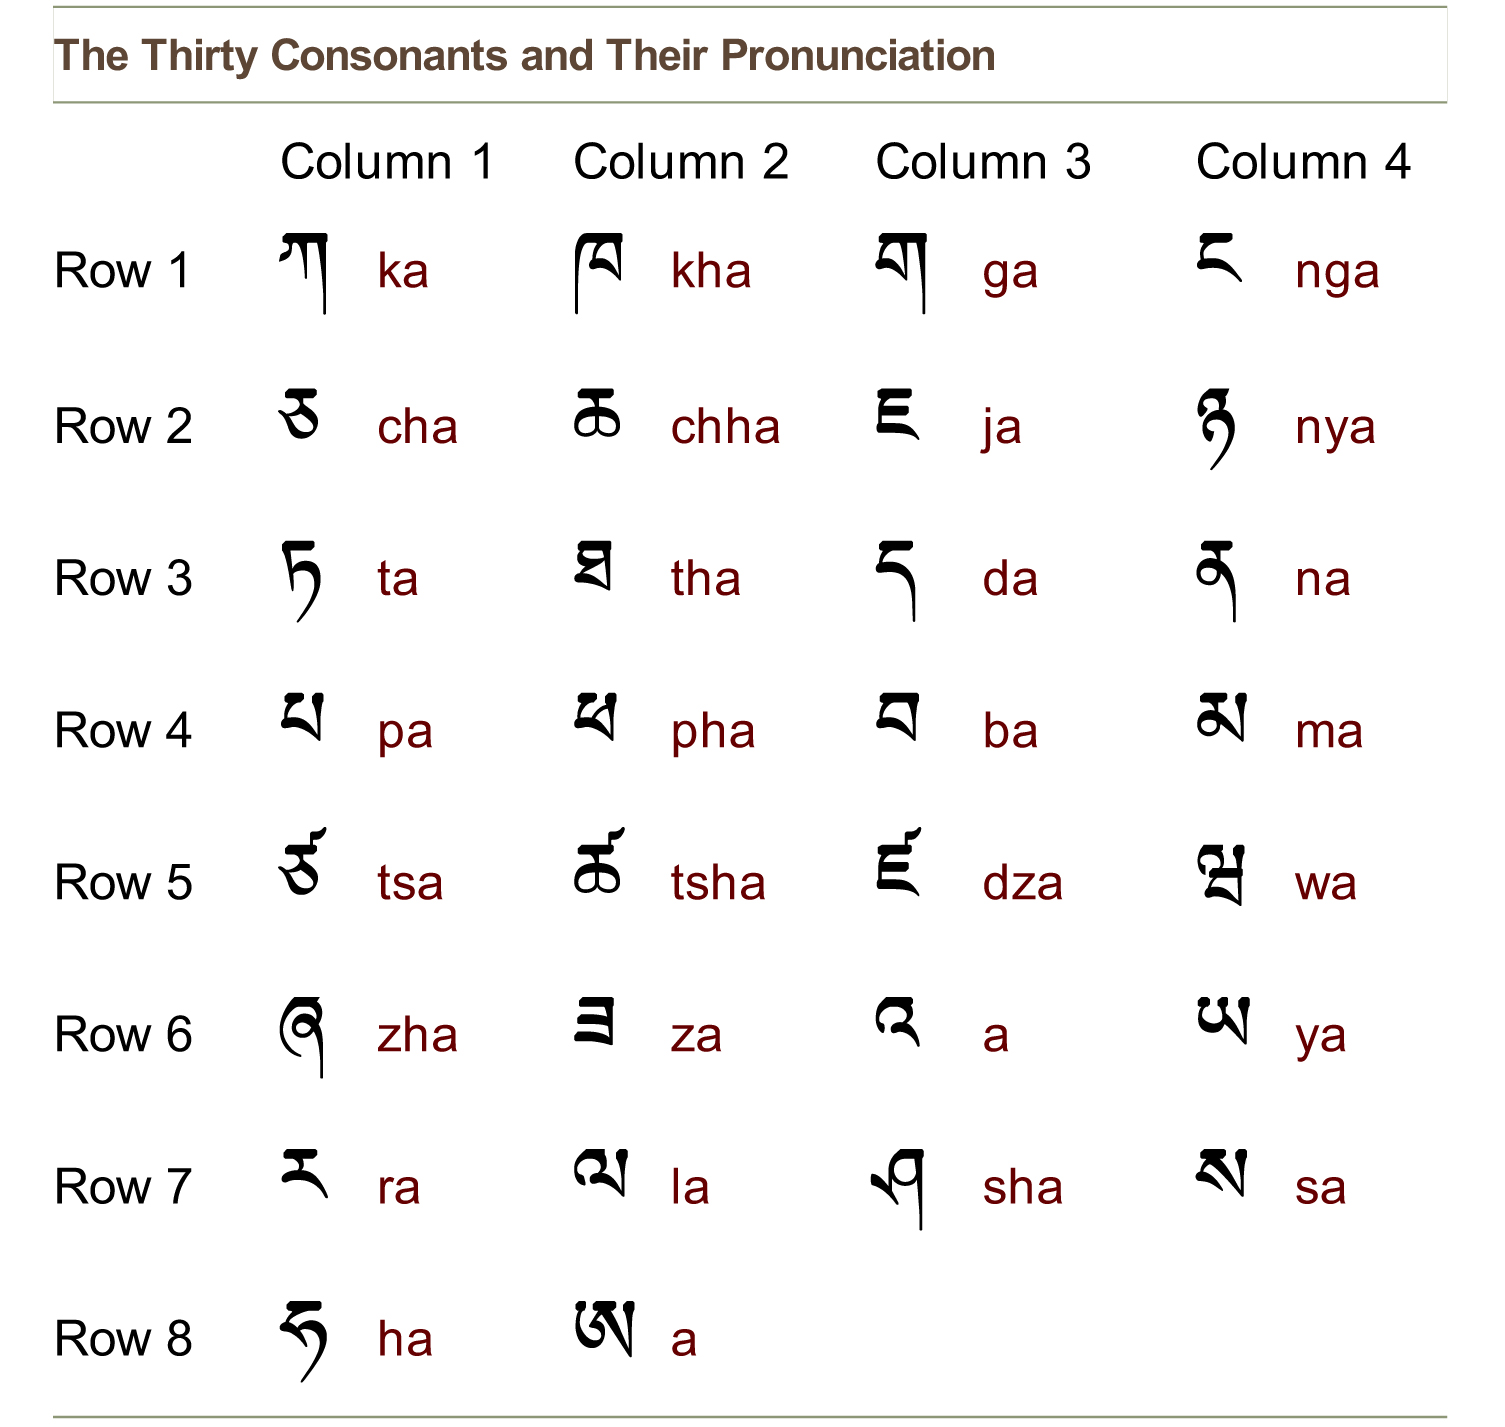
Tibetan is a tonal language with its own script, and getting a machine translator to handle it without producing garbage requires understanding what the tool can and can't do. Most free online options will give you something readable for basic phrases but will fail on anything involving classical Tibetan, religious texts, or dialect differences between Lhasa Tibetan and Amdo Tibetan. The script uses 30 consonants and four vowels, with tone implied rather than marked in writing. That alone causes translators to miss critical meaning because the same spelling can map to different pronunciations depending on the dialect. I've used several of these tools over the years, mostly for quick reference when I needed a word or two translated for documentation or correspondence. Google Translate supports Tibetan, but it's built on neural machine translation trained primarily on modern standard Tibetan from Lhasa. If you're working with Western Tibetan dialects or classical literary Tibetan, the output will be wrong in ways that aren't obvious until you check with a native speaker. I learned that the hard way once when I was translating a community health document and the tool rendered "medicine" as something closer to "herb" because the source text used a formal register that the model hadn't seen much of in training data. The fix was to break the sentence into smaller chunks and compare the outputs from at least two different platforms before committing to a translation. DeepL does not support Tibetan at all, which you would discover only after pasting your text and watching it fail silently. Saylang and other regional tools tend to perform better on colloquial phrases but struggle with complex grammar. The Tibetan phrase structure is subject-object-verb, which is the opposite of English, and most translators attempt a direct word-for-word swap rather than reordering the syntax properly. This means you'll often get a sentence that contains the right words but reads like it was translated by someone who doesn't understand how either language works.
How to Get Usable Results
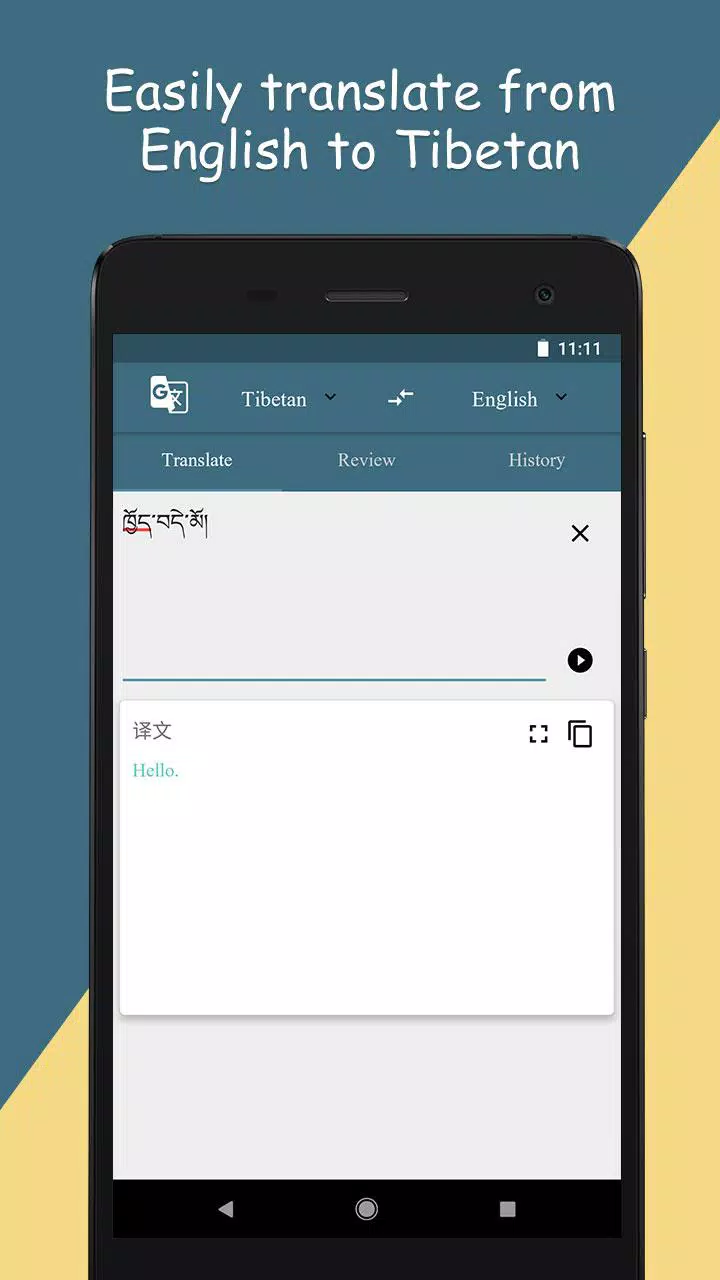
The practical approach is to treat any online translator as a rough draft generator, not a final answer. Start by typing your text into Google Translate, then copy the output into a second tool like Saylang or the University of Hawaii's Tibetan dictionary if you need to verify specific vocabulary. Cross-referencing two systems catches about half the errors before they reach your eyes. For longer documents, translate section by section rather than feeding the whole thing in at once. Neural models handle context better when the input is under 500 characters, and Tibetan texts with mixed registers or technical terms degrade quickly when the full passage exceeds that threshold. Another thing people don't account for is the difference between Unicode Tibetan and older encoding standards. Some older websites and forms still expect Wylie transliteration or the old Tibetan Unicode subset, and pasting modern Unicode text into those systems will produce corrupted output. I spent an afternoon debugging a form submission that looked perfect on screen but arrived garbled on the backend. The issue turned out to be a font rendering mismatch between the translator output and the server's text processor. The solution was to paste through a plain text intermediary first, then copy from there.
When Online Translators Fail Completely
Religious and literary Tibetan is where these tools break down entirely. Classical Tibetan uses a writing system that preserves pronunciations from over a thousand years ago, so the spoken language and the written language are almost completely disconnected. A translator trained on modern speech has no way to parse archaic verb forms, sandhi combinations, or the massive amount of Sanskrit loan vocabulary in Buddhist texts. If you're working with anything from the Kangyur or Tengyur, or even contemporary commentaries that use classical grammar, you need a human translator who specializes in that register. No online tool will get you close. Dialect variation is another hard boundary. Lhasa Tibetan, Amdo Tibetan, and Kham Tibetan are mutually unintelligible in spoken form, and the written standard is based on Lhasa. If your source text is in Amdo or Kham, the translator will render it as Lhasa Tibetan at best, which is misleading and sometimes offensive depending on the context. I've seen this cause real problems in community settings where people assumed a translation was accurate because it used correct Tibetan script, not realizing the dialect had been flattened into something the original speaker wouldn't naturally use.
Get the Full Details
Practical Workarounds That Actually Help
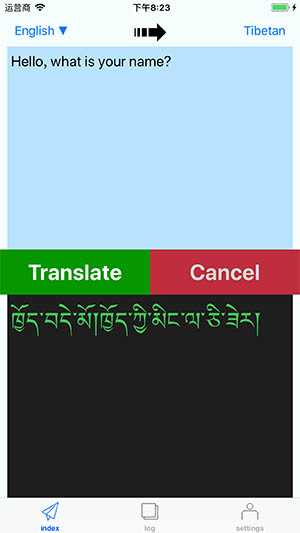
If you need to work with Tibetan regularly, the most reliable setup I've found combines a few specific resources rather than relying on a single translator. Keep the Tibetan-English dictionary from the Institute of Buddhist Dialectical Traditions bookmarked for vocabulary checks. Use Google Translate for quick phrase lookups and structural sense-checking. For anything beyond a sentence or two, run the text through a translation memory tool or archive your own previously verified translations so you have a reference baseline. This cuts revision time roughly in half compared to starting from scratch every time. Another useful technique is to translate into English first, then from English into Tibetan. It sounds backwards, but for texts that contain a lot of technical or modern terminology, the English intermediate step often produces cleaner Tibetan output than a direct translation attempt. The model understands the English phrasing better, and the Tibetan side can reconstruct the meaning more accurately from a clearer source. It's slower, but the error rate drops significantly for specialized content. Character encoding matters more than most people realize. Always save your Tibetan text as UTF-8 before pasting it anywhere. If you're copying from a PDF or a scanned document, run it through an OCR tool that supports Tibetan first. The built-in scanners on most devices will misrecognize Tibetan characters at a high rate, and feeding that corrupted text into a translator compounds the problem. I've lost count of how many times a translator produced nonsense that turned out to be an OCR error, not a translation error. Check your source text against the original character by character before you trust the output.
There is no perfect automated solution for Tibetan translation yet. The tools available can handle simple conversational text and basic reading comprehension if you verify the results. Anything involving formal registers, multiple dialects, classical sources, or cultural nuance will require human review. Budget for that time upfront instead of discovering it after you've already distributed incorrect information.