Getting Started with Instruction Fine-Tuning
Tier 1 Instruction Best Practices is about the foundational layer of getting supervised fine-tuning to actually work on your model. You pick a base model, you curate instructions, you format the data, and then you train. That sounds simple until you try it. Most people fail at the data step. They don't realize that the quality of your instruction-response pairs determines everything downstream. I spent about three weeks last year trying to fine-tune a 7B parameter model for a customer support chatbot. We had decent hardware, good prompts, and absolutely terrible results. The model would generate plausible-sounding but factually wrong answers with high confidence. Turns out our training data had systematic biases toward overly formal language that didn't match our deployment environment. I ended up rewriting about 60% of the instruction pairs manually because the model had learned to replicate the style of the original authors instead of learning the actual task. That was the most expensive lesson of my career.
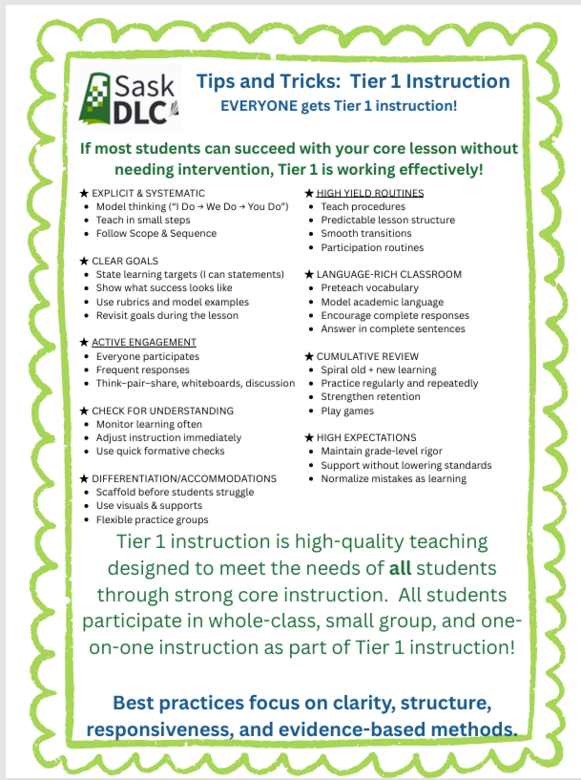
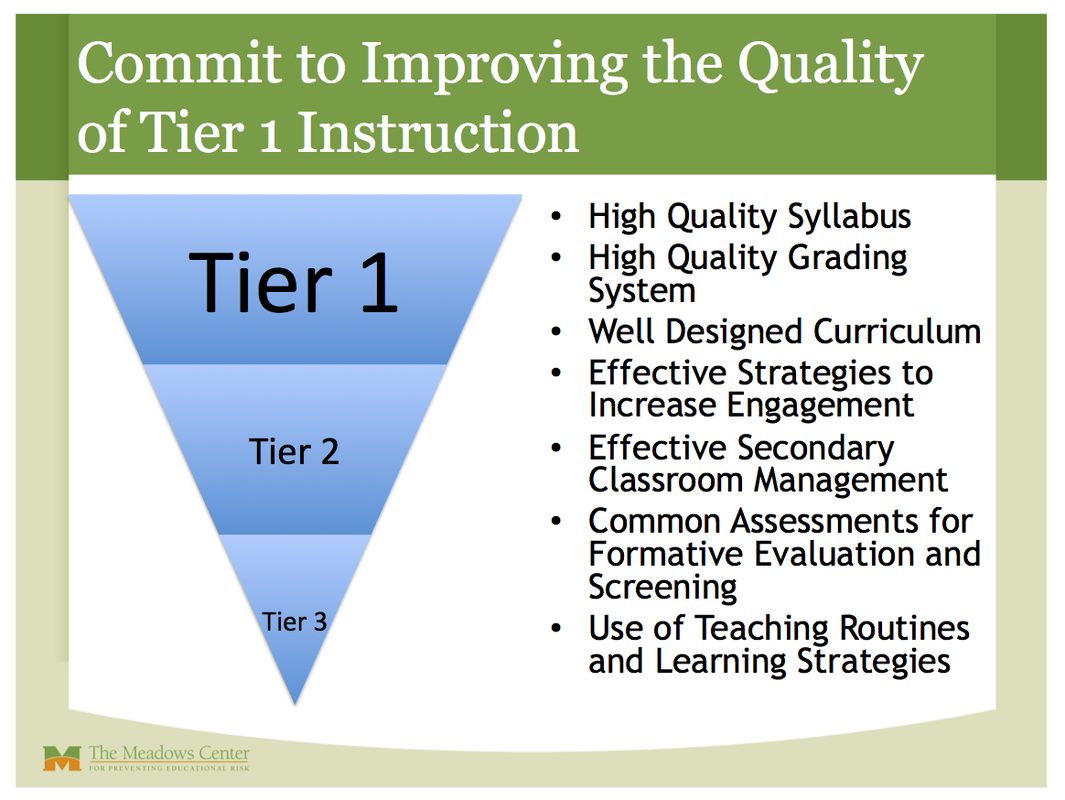
Tier 1 Instruction Best Practices for SFT
Let me walk through what actually works. The first thing you need to understand is that your instruction format matters more than you think. The standard Alpaca-style format works, but it's not a universal solution. If your use case involves multi-turn conversations, code generation, or math reasoning, the format needs to reflect that structure explicitly. A simple two-field instruction-response pair will confuse models trained on conversational data. Your dataset should have between 1,000 and 10,000 high-quality examples for a starter project. Anything less and the model won't learn the pattern. Anything more and you're probably duplicating effort rather than adding value. I've seen people dump 50,000 instructions into a fine-tuning job and get worse results than with 2,000 carefully written ones. The difference isn't volume. It's distribution coverage and correctness. Here's a specific technique that catches most beginners off guard: instruction diversity. Your instructions shouldn't all follow the same syntactic pattern. If 80% of your instructions start with "Write a..." or "Explain how to...", the model will default to that template even when the task doesn't call for it. I once had a model that couldn't answer a direct factual question because every training example was a command format. It would respond with a generated title and bullet points instead of just answering. We fixed it by adding a balanced set of question-answer pairs at a 1:1 ratio with the command pairs.
Another detail people skip: input fields. Not every instruction needs an input field, but every instruction that does should have realistic examples of what that input looks like. I've seen training data where the input was just empty strings because the author assumed the model would understand context from the instruction alone. The model doesn't. It learns from patterns in your data, not from your intentions. When it comes to formatting, stick to a consistent schema. JSONL is the standard. Each line is one training example with clearly labeled fields. Don't mix formats within a single dataset. Don't include extra fields that your fine-tuning script doesn't use. Clean, minimal data outperforms elaborate data with unnecessary metadata every time. The training process itself has a few critical parameters. Learning rate between 1e-5 and 5e-5 is the typical range. If you're using LoRA, rank between 16 and 64 works for most cases. Higher ranks don't necessarily help and can overfit quickly. Batch size should be as large as your GPU memory allows. Gradient accumulation steps can compensate if you're short on memory. epochs between 2 and 4 is usually sufficient. Going beyond 4 epochs on instruction data almost always causes memorization, not improvement.
Get the Full Details

Here's a hard truth about Tier 1 Instruction Best Practices that most guides won't tell you: evaluation is where the real work happens, and it's usually done poorly. Accuracy on a held-out test set is necessary but not sufficient. You need to test edge cases specifically. What happens when the instruction is vague? What happens with adversarial prompts? What happens when the user includes irrelevant information? These aren't edge cases in production. They happen constantly. I evaluate by creating a small set of 50 deliberately difficult prompts that mirror real user behavior, not benchmark benchmarks. A model that scores 90% on MMLU but fails on your custom evaluation set is worse than a model that scores 75% on MMLU but handles your edge cases correctly. The biggest bottleneck I encounter repeatedly is data curation time. For every hour of training, you should expect to spend 10 to 20 hours preparing and cleaning your instruction dataset. That's not a suggestion. That's the actual ratio I've observed across multiple projects. If you're spending less time on data than on training, you're probably going to be disappointed with the outcome. Automated data generation using a stronger model can help, but you still need a human review pass. Models hallucinate in ways that are subtle and convincing, and those hallucinations get baked into your fine-tuned model. If your goal is something standard like general chat or basic Q&A, using a pre-packaged dataset from the Hugging Face hub might be faster and more effective than building from scratch. But if you need domain-specific behavior, you need domain-specific data. There is no shortcut around that.