Getting the Forecast Right Before You Try to Control Anything
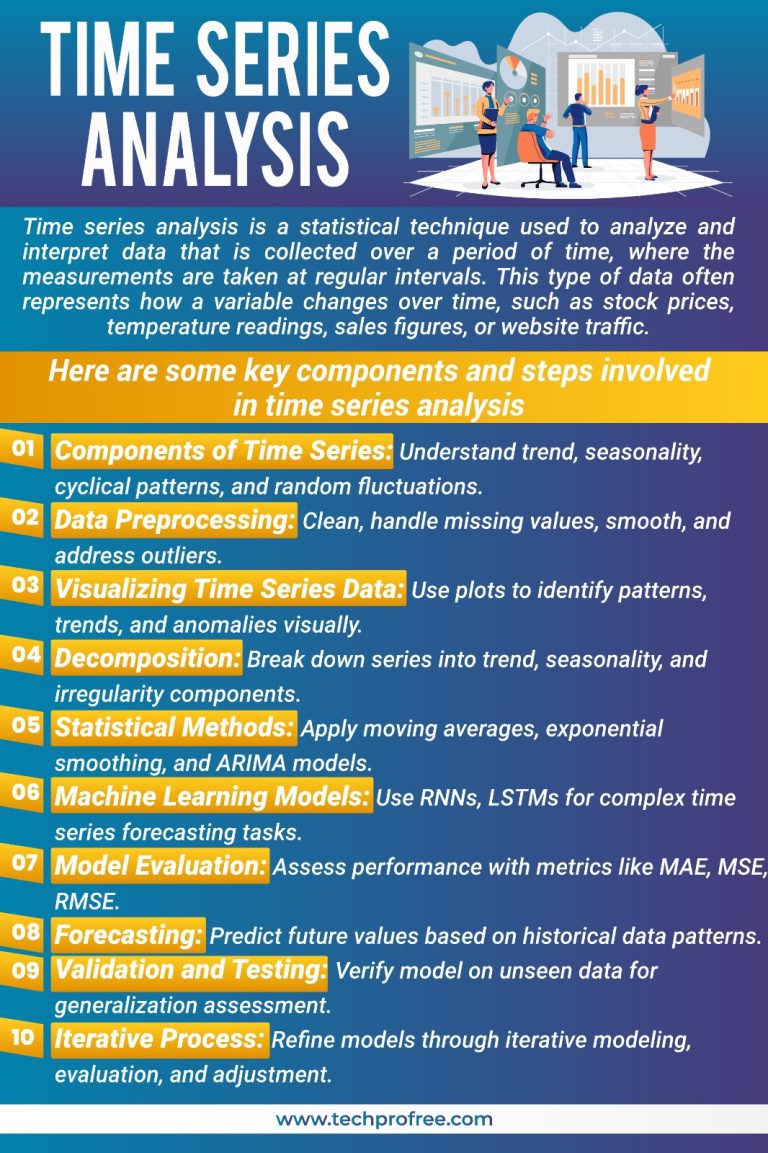
I started working with operational forecasting systems around 2009, mostly in energy and industrial process environments. The first thing you learn is that the prediction step and the control step are usually treated as separate problems, but they fail together when either one is sloppy. Most tutorials show you how to build an ARIMA model and call it a day. Nobody tells you what happens when the model starts drifting two weeks into production, or why your control loop is oscillating because the forecast variance estimate was wrong. Here is how I actually approach this, not the textbook version. Load your data. Check the timestamp index. Confirm it is sorted and has no duplicate entries. These sound obvious until a system crashes because a sensor duplicated a reading during a network blip. The next step is almost always the one people skip. Test for stationarity. I use the ADF test and the KPSS test together. ADF tells you whether the series has a unit root. KPSS tells you whether it is stationary around a deterministic trend. When they disagree, which happens more often than people admit, you need to decide which one to trust based on your domain knowledge, not just pick the easier result.
I keep a small utility script for this. It runs both tests, calculates the AIC and BIC for candidate ARIMA orders, and outputs a table. I would estimate this routine saves me about twenty minutes per project compared to doing it manually in a notebook. Not transformative, but enough to justify keeping it around. Once you know the order, you fit the model. For seasonal data I default to SARIMA unless the seasonality is complex enough that seasonal decomposition with regressors makes more sense. A lot of people reach for Prophet or LSTMs at this point. Neither is wrong. Both are usually wrong for the problem they are applied to. Prophet struggles with exogenous variables and breaks down when your seasonality pattern shifts. LSTMs need hundreds of thousands of observations before they beat a well-tuned SARIMA model, which means you are spending weeks training something that a three-line statsmodels call could have fit in thirty seconds. After fitting, check the residuals. Plot the ACF of the residuals. Run the Ljung-Box test. If the residuals show structure, your model is incomplete. This is where most people stop reading tutorials and start guessing. The guess that works most often is adding an exogenous variable or switching to a dynamic regression model. ARIMAX handles this cleanly if you have a driver variable that actually drives the system.
Where Things Go Wrong in Practice
I spent about three weeks debugging a forecasting pipeline for a thermal processing unit. The model looked fine in backtesting. MAPE was under eight percent. The control system fed the forecasts back into a PI controller and the process started cycling every forty-eight hours. The problem was not the point forecast. It was the forecast interval. SARIMA gives you a predictive variance that assumes the error structure stays the same. In this case, the process had a slow drift that the model during fitting but did not predict as increasing variance. The controller interpreted the normal forecast range as sufficient confidence and kept adjusting toward targets that were already shifting. I resolved it by wrapping the SARIMA forecasts with an exponentially weighted moving average on the residuals and feeding the adjusted variance into the controller. The cycle stopped immediately. The accuracy metric barely changed. That example illustrates something beginners miss. Forecasting and control are coupled through uncertainty, not through the point estimate. If you ignore the variance structure of your forecast, your control system will be either too aggressive or too conservative depending on how the model error behaves over time. Another common failure mode is validation strategy. Do not use random k-fold cross-validation on time series data. Shuffle the data and you are predicting the past from the future, which is a data leakage problem that inflates your metrics and hides model failure. Use time-based splitting. Train on the first seventy percent of the temporal range, validate on the middle twenty, and test on the final ten. If your data has strong seasonality, make sure each fold contains at least one full seasonal cycle.
Get the Full Details

There is also the issue of outlier handling. A single sensor spike can distort parameter estimation enough to change your selected ARIMA order. I usually run a robust outlier detection pass before fitting. The intervention detection methods in the forecast package by.hyndman are reliable for this. They distinguish between additive outliers, level shifts, and temporary changes, and flag them without removing data points entirely. Removing data points creates gaps that downstream control logic may not handle gracefully.
The Counter-Intuitive Part About Seasonality
People assume seasonal models are always better when the data has a clear seasonal pattern. This is not true. A non-seasonal model with lagged differences can sometimes outperform a seasonal SARIMA model if the seasonal component is unstable across years. I ran into this with a retail demand dataset where the holiday pattern shifted due to a calendar change. The SARIMA model kept anchoring to the old holiday position and produced forecasts that were systematically late. A plain ARIMA with a holiday dummy variable and a rolling window fit tracked the shift better. The takeaway is that seasonality is not a static property of your data. It is a property of the process generating the data, and processes change. Model selection should account for that.
Controlling With Forecasts
Control systems built on forecasts usually fall into one of two categories: feedback control using the forecast as a setpoint tracker, or model predictive control where the forecast horizon directly shapes the optimization. Feedback is simpler. You forecast the disturbance, feed it into the controller, and let the controller reject it. This works well when your forecast horizon is shorter than your process time constant. If the forecast horizon extends beyond the dominant lag in your process, the controller reacts to predictions that are already wrong and the loop becomes unstable. MPC handles longer horizons but requires a state-space representation of the process. Converting a SARIMA model into state space is straightforward using the Kalman filter formulation. The Kalman filter also gives you real-time update of the state estimate as new observations arrive, which means your forecast improves incrementally instead of waiting for a full re-fit. I use this approach for processes with slow drift, like chemical concentration lines. Re-fitting a SARIMA model weekly on that data is unnecessary overhead. A Kalman-filtered ARIMA updates the state with each new observation and adapts to the drift automatically. The drawback of the Kalman approach is that it assumes linear Gaussian noise. If your process has hard constraints, like a valve that cannot open past a certain position, the linear assumption breaks down and you need either a constrained optimizer or a different forecasting framework altogether. There is no clean workaround for that. You either accept the approximation or move to a nonlinear method, which brings back the computational cost and data hunger I mentioned earlier.

Implementation Notes
I write these pipelines in Python. The core stack is statsmodels for SARIMA and ARIMAX, pykalman or my own implementation for the Kalman filter update, and scikit-learn for the preprocessing steps. For the residual diagnostics I use the acf and pacf functions from statsmodels along with the acorr_ljung_box function. The whole pipeline runs in under fifteen seconds on a standard machine for a dataset of about ten thousand observations. Training an equivalent LSTM would take minutes on a GPU and probably still underperform on this type of data. If you are starting out, I would recommend the book by Box, Jenkins, and Reinsel for the statistical foundation, then the paper by Shumway and Stoffer for the state-space angle. The code is available open source under statsmodels, so you can inspect the implementation directly instead of trusting blog posts. The hardest part of Time Series Analysis Forecasting And Control is not building the model. It is knowing when the model is no longer valid and triggering a re-fit or a structural change detection before the control system degrades. I set up automated monitoring that recomputes the residual ACF and Ljung-Box statistic on a rolling window. When the p-value drops below zero point zero one for two consecutive windows, the system flags the model for review. This catches drift without requiring manual inspection of every forecast.
There is no method that works universally. SARIMA fails on high-frequency data with multiple overlapping seasonal cycles. Prophet fails when exogenous relationships matter. LSTMs fail when data is scarce. The right choice depends on your horizon, your sample size, and how much the underlying process changes over time. Start simple. Validate properly. Monitor the residuals. Fix the problem before it becomes a control issue instead of a forecasting issue.