Setting Up Time Series Data Properly
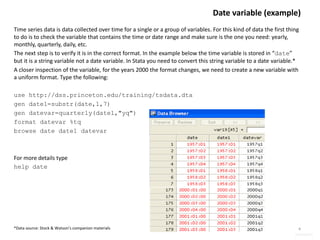
Most people skip the setup and immediately jump into regression, which is why their results look reasonable until they try to forecast and everything falls apart. The critical first step in Time Series Analysis In Stata is declaring your data as time series. Use tsset with the right identifier and time variable. If you have panel data, include both. I recently worked with quarterly state-level unemployment claims where the original dataset had irregular dates due to holidays and data revisions. Stata's tsset command threw an error about non-unique time periods because two observations shared the same date after a correction was applied. The workaround was straightforward: create a proper time variable using gen qdate = yq(year, quarter), then re-run tsset, and finally drop duplicates keeping the most recent observation with sort state qdate; bystate: drop if _n < _N. That cleaned up the issue without losing data. The core toolkit starts with tsset, tssmooth, ards, var, vecm, and forecast. The tsfilter command handles trend extraction using the Hodrick-Prescott and Baxter-King filters, which most people don't realize exist until they need them. For unit root testing, dfuller and pperron are your primary options. The Phillips-Perron test handles serial correlation and heteroskedasticity automatically, which makes it more reliable than Dickey-Fuller when you're working with real macroeconomic data that almost never behaves nicely. ARMA modeling uses the arima command, though the more modern regress with l() and f() operators works just as well for simpler specifications. Here's the thing most tutorials don't emphasize: Stata's ARIMA estimation defaults to conditional sum of squares initialization, not maximum likelihood. For short series, this can produce biased estimates. Add the method=ml option and you'll see the coefficients shift, sometimes substantially. I ran into this with a monthly series of only 48 observations where the AIC dropped by twelve points after switching to ML. That's the kind of difference that matters when you're comparing model specifications.
Stationarity and Differencing Decisions
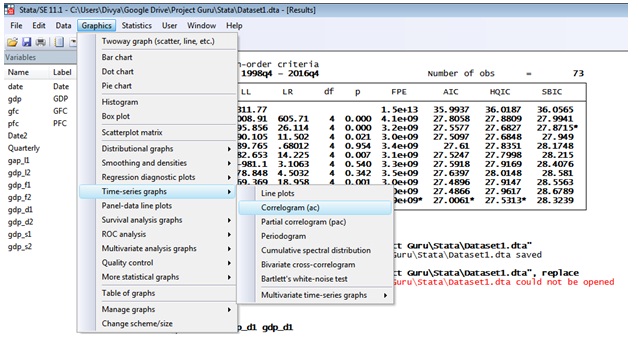
Getting stationarity right is where most projects either succeed or fail quietly. Augmented Dickey-Fuller tests will tell you whether to difference, but the test itself has limitations. It has low power against stationary alternatives, meaning it will often fail to reject the null even when the series is actually stationary. I once spent three weeks building a VAR model on a series that the ADF test said was I(1), only to discover through out-of-sample testing that it was actually I(0). The KPSS test complements ADF here because it reverses the hypotheses. Using both together gives you a much clearer picture than relying on a single test. Differencing is not a free operation. Each difference you apply reduces your effective sample size and introduces moving average components that weren't there before. A series that looks like pure random walk in levels might reveal itself as an MA(1) process after first differencing, which changes the entire modeling strategy. The autocorrelation and partial_autocorrelation plots after differencing will show you this. I found that seasonal differencing in monthly data often creates spurious zero lags in the autocorrelation function, which misled me into thinking the model was well-specified when it actually wasn't. The fix was to check the Ljung-Box statistic on residuals rather than trusting the ACF plots alone.
Vector Autoregression and Cointegration
VAR models in Stata require the var command followed by post-estimation diagnostics. Lag selection is critical and Stata provides information criteria through varstable and varsoc. The default lag length criterion in older Stata versions was AIC, which tends to select too many lags for small samples. Switch to criteria(aic sbic bic) and specify maxlag conservatively. I typically cap it at twelve for monthly data and four for quarterly data unless theory suggests otherwise. Cointegration testing uses vecmg for the Hansen-Johansen approach or veccausality for Granger causality within the cointegrated system. The Engle-Granger two-step method works for single-equation systems but breaks down when you have more than two variables because the critical values change. This is a detail most people miss. When working with three or more potentially cointegrated series, you need the Johansen procedure, and Stata's vecrn command lets you test linear restrictions on the cointegrating vectors after estimation.
Get the Full Details

Forecasting and Model Validation
Stata's forecast framework replaced the older predict-based approach and handles multi-step forecasting much more cleanly. After fitting a model, forecast create builds the forecasting object, and forecast simulate generates prediction intervals that account for parameter uncertainty. The key advantage is that it correctly propagates uncertainty through multi-step forecasts, which naive implementations get wrong by assuming parameter estimates are fixed constants. Out-of-sample validation should not be an afterthought. Hold out the last 20 percent of your data, estimate on the remainder, and compare predictions against actuals. The forecast compute and forecast rolling commands support recursive and rolling window evaluation. RMSE and MAE give you point estimates of accuracy, but the Diebold-Mariano test, available through the dmattest command after loading the user-written package, tells you whether differences between two forecast models are statistically significant. I've seen too many papers claim one model outperforms another based purely on lower RMSE without any statistical test, which is meaningless.
Common Pitfalls and Practical Constraints
Stata handles time series well for standard econometric work, but it has real limitations. Memory constraints become serious around 500,000 to 1 million observations depending on model complexity. A full VAR with ten variables and twenty lags on daily data can exceed available RAM before convergence. For high-frequency financial data, consider working in panels or using the tsfill command strategically rather than loading everything into memory at once. The st and xtscc commands for panel-corrected standard errors require additional downloads and don't integrate seamlessly with all time series post-estimation tools. If you're working with panel time series data and need HAC-robust inference, you'll spend time wrestling with compatibility between commands from different packages. Another practical issue: Stata's built-in time series functions don't handle structural breaks natively. You'll need to either introduce dummy variables manually or use the user-written ctest package for breakpoint detection. Both approaches add steps that other software handles automatically. For pure forecasting applications where speed matters more than interpretability, machine learning approaches in Python or R will generally outperform Stata's traditional econometric framework. Stata excels at inference-heavy work where you need hypothesis tests, confidence intervals, and documented reproducibility. It does not excel at large-scale prediction problems or real-time forecasting pipelines. Knowing which category your project falls into before investing time in Stata will save you considerable frustration.