So you want to get into machine learning without losing your mind
I spent three years building models that barely worked and wondering why. The field is full of people making it look harder than it actually is, mostly because they're trying to sound smart. Here's the truth: the barrier to entry is lower now than it was five years ago, but the noise level is higher. You can build something functional on a Sunday afternoon if you ignore most of what the internet tells you. The first thing you need to understand is that machine learning is not magic. It's applied statistics with a better marketing team. When someone says "the neural network learned to recognize cats," what they really mean is "we fed this model forty thousand cat images and twenty thousand non-cat images, adjusted the weights through gradient descent, and got eighty-seven percent accuracy on the test set." That's it. No mysticism involved.
Practical Tips For Machine Learning Easy
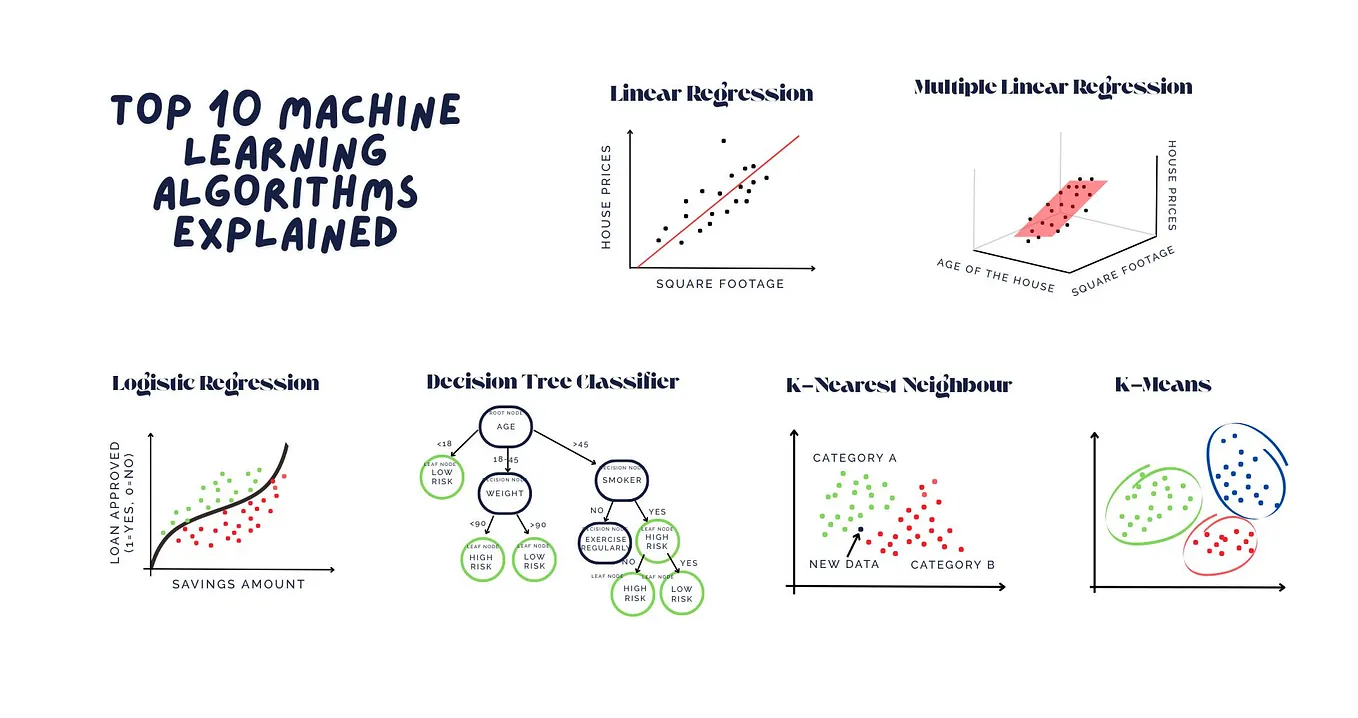
Start with scikit-learn. Don't touch PyTorch or TensorFlow until you've spent at least two weeks building linear regressions and decision trees by hand in sklearn. There's a reason the docs are written the way they are, and there's a reason every introductory tutorial uses it. It forces you to understand the pipeline before you add the complexity of a deep learning framework. The pipeline is more important than the algorithm. I can't stress this enough. Most people jump straight into trying different models because they think that's what matters. It doesn't. A mediocre model with clean data and a solid pipeline will beat a fancy model fed garbage every time. I learned this the hard way during my second month. I had built what I thought was an impressive random forest classifier for a customer churn problem. It showed ninety-four percent accuracy on my training data. When I deployed it, the real-world accuracy dropped to sixty-one percent. The problem wasn't the model. I'd fit it on the entire dataset before splitting into train and test, so the model had seen the answers during training. Data leakage. Simple, devastating, and completely preventable if you structure your pipeline correctly. Here's what your pipeline should look like, roughly: load your data, split it into training and testing sets, apply your preprocessing only to the training set (like standardization or encoding), then transform the test set using the parameters learned from training. Never let the test set influence any part of your preprocessing. If you do, you've contaminated your evaluation and your numbers mean nothing.
Use Jupyter notebooks for exploration but switch to Python scripts for anything that needs to run reliably more than once. Notebooks encourage a certain kind of sloppy thinking where you just keep running cells without tracking state, and it works fine until it doesn't. I once had a model break in production because some cell somewhere in a notebook had been re-executed out of order and changed a variable that three other cells depended on. Debugging that took me six hours. When you're choosing your first datasets, don't go looking for something massive or impressive. The Iris dataset and the Boston Housing dataset are classics for a reason, even if they're boring. Get comfortable with the workflow first. You should be able to load a CSV, clean it, split it, train a model, evaluate it, and save it without looking up how to do any of those steps. Until that feels automatic, the advanced stuff will overwhelm you. Feature engineering matters more than model selection. This is the single biggest counter-intuitive insight for beginners. Everyone wants to experiment with hyperparameters and try transformer architectures. The person who spends a week thinking about which features to include, how to handle missing values, and whether to log-transform a skewed variable will consistently outperform the person spending a week tuning learning rates. A logistic regression with good features beats a gradient boosting machine with bad features. I've seen it happen repeatedly.
Get the Full Details

Here's an edge case that caught me off guard. I was working with a dataset where one of the categorical variables had nearly a thousand unique values. Encoding it with one-hot encoding blew up my memory usage and made the training time go from about four minutes to roughly twenty-seven minutes. The workaround was target encoding instead, where you replace each category with the mean value of the target variable for that category. It's less interpretable but dramatically faster and uses far less memory. Just make sure you compute those means from the training set only, or you'll reintroduce the same leakage problem I described earlier. Learn to read the error, not just the accuracy number. If you're doing classification, look at the confusion matrix. Accuracy is useless if your classes are imbalanced. I once evaluated a fraud detection model that had ninety-nine point two percent accuracy. It achieved this by predicting that every single transaction was legitimate. Since only about eight percent of transactions were fraudulent, the model was wrong most of the time and had learned absolutely nothing. Precision, recall, and F1-score tell you what accuracy hides. Cross-validation is not optional. If you're only doing a single train-test split, your performance estimate has high variance. Use k-fold cross-validation, typically with five or ten folds. It takes slightly longer to run, maybe twenty to thirty percent more time depending on your dataset size, but the performance estimate is significantly more reliable. I used to skip it because I thought it was overkill. That changed after I spent a week celebrating a great model only to find it performed poorly on a different random split of the same data.
Documentation is important, but not the kind you're probably thinking about. I'm talking about documenting your experiments. Track which preprocessing steps you tried, which models you evaluated, what the results were, and why you moved on from one approach to the next. Not because you need to impress anyone, but because you will forget. I keep a simple spreadsheet with columns for date, dataset, preprocessing approach, model type, hyperparameters, train score, test score, and notes. Six months later I can look back and see exactly what I tried and why it didn't work. Without that, you end up repeating the same dead ends. Don't optimize for accuracy alone. In most real applications, the cost of a false positive and the cost of a false negative are different. A spam filter that blocks legitimate emails is annoying. A medical diagnosis model that misses a disease is catastrophic. Think about what kind of errors your specific application can tolerate before you start building anything. Deployment is where most beginner projects die. You have a great model sitting in a Jupyter notebook and you're excited. Then you realize you don't know how to serve it. You don't need a complex microservice architecture when you're starting out. A simple Flask API that loads your saved model and returns predictions is enough. Save your model with joblib or pickle, build a minimal endpoint, and get it running locally before you think about Docker or cloud infrastructure.
The ecosystem around machine learning changes constantly. New papers come out every week claiming to be better than everything that came before. Ignore most of it. The fundamentals haven't changed much in the last decade. Gradient descent, regularization, cross-validation, bias-variance tradeoff. These concepts are stable. The tools change, but the underlying math doesn't. Understanding the math means you won't panic when a new framework drops and claim to solve everything. If you hit a wall with your model, the problem is almost always in the data, not the algorithm. I've seen people spend days tuning a neural network only to realize the dataset had a column with inconsistent date formats or duplicated rows that skewed the results. Clean your data first. Really clean it. Check for missing values, check for outliers, check for duplicates. It's boring work, but it's the work that actually moves the needle. Start smaller than you think you should. Build a model that predicts something simple. Predict house prices. Predict whether an email is spam. Predict whether a customer will churn. The goal isn't to build the next great product. The goal is to complete the full cycle: data to model to evaluation to deployment. Each cycle teaches you something the previous one didn't. Three small completed projects will teach you more than one half-finished ambitious one.

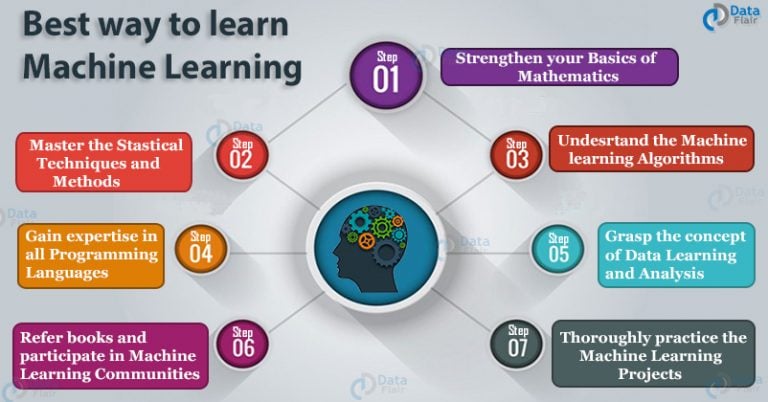
Resources matter less than you think. There are good free courses, decent books, and plenty of YouTube channels. Pick one and stick with it long enough to finish it. Switching between three different tutorials at different paces is a common way to feel like you're making progress when you're actually learning nothing deeply. Finish one course, build one small project using what you learned, then move on.
What happens when things go wrong
They will. Models overfit. Data has gaps. Your assumptions turn out to be wrong. This is normal. Overfitting is the most common problem, and it shows up when your model learns the training data too well and performs poorly on new data. The fix is usually one of: more data, simpler model, or regularization. Try those in order before you start looking for exotic solutions. Underfitting is the opposite problem and rarer than people think. It means your model is too simple to capture the patterns in the data. Again, the solution is usually straightforward: add features, reduce regularization, or use a more expressive model. But here's the thing most tutorials don't tell you clearly: adding more features can sometimes make things worse. If you add irrelevant features, you're just giving the model more noise to work with. Feature selection matters. Sometimes the right answer is to not use machine learning at all. If you can solve a problem with a rule-based system or a simple heuristic, do that. ML introduces complexity, debugging difficulty, and maintenance overhead. I've seen people build a classification model for a problem that could have been solved with a dozen if-statements. The model worked fine, but it took three weeks to build and the team had no idea why it made specific predictions. The rule-based version took two hours and was trivially debuggable.
When your model fails in production, don't immediately blame the algorithm. Check the data pipeline first. Is the data arriving in the same format you trained on? Are there new values in categorical columns that your model has never seen? Are there missing values that weren't present in the training data? I spent an entire day debugging a model that had stopped making predictions after a minor schema change in the database it pulled from. The model didn't crash. It just started producing empty predictions because the input shape had changed by one column. There's also the issue of data drift. Your model might have been perfect when you trained it, but the underlying distribution of the data changes over time. A model trained on pre-pandemic shopping behavior would perform poorly on post-pandemic data without retraining. Monitor your model's performance over time, not just at launch. Set up a simple dashboard that tracks prediction accuracy on incoming data compared to a rolling baseline. When it degrades, that's your signal to retrain. One thing I wish someone had told me early: computational cost is real. Training a large model on a big dataset takes time and money. If you're doing this on your own hardware without a GPU, some experiments will take hours. Plan your experiments accordingly. Start with smaller subsets of your data to validate your approach, then scale up. Don't throw your entire dataset at a model on day one and wait two days to find out your preprocessing pipeline has a bug.

The field rewards patience more than raw intelligence. You will sit with a problem for days and make no progress. Then you'll fix one small thing and everything clicks. That's how it works. Don't mistake the slow periods for failure. They're just part of the process.