What You Actually Need When You Open a Stats Project at 11pm
I spent last Tuesday trying to remember whether the formula for weighted mean variance used n or n-1 in the denominator, and honestly it was not worth the stress. Most people who work with data regularly end up collecting these things. A reference sheet that captures the formulas you actually reach for, not the ones your textbook asks you to derive on a midterm. A Top 10 Statistics Cheat Sheet is just that: a compact collection of the most commonly used statistical formulas, arranged so you can find them without reading through forty pages of explanations. The name sounds like something you'd hand to an undergraduate, but professionals use them too, especially when you are switching between different types of analyses and need to keep straight which variation of t-test applies to your dataset.
Top 10 Statistics Cheat Sheet
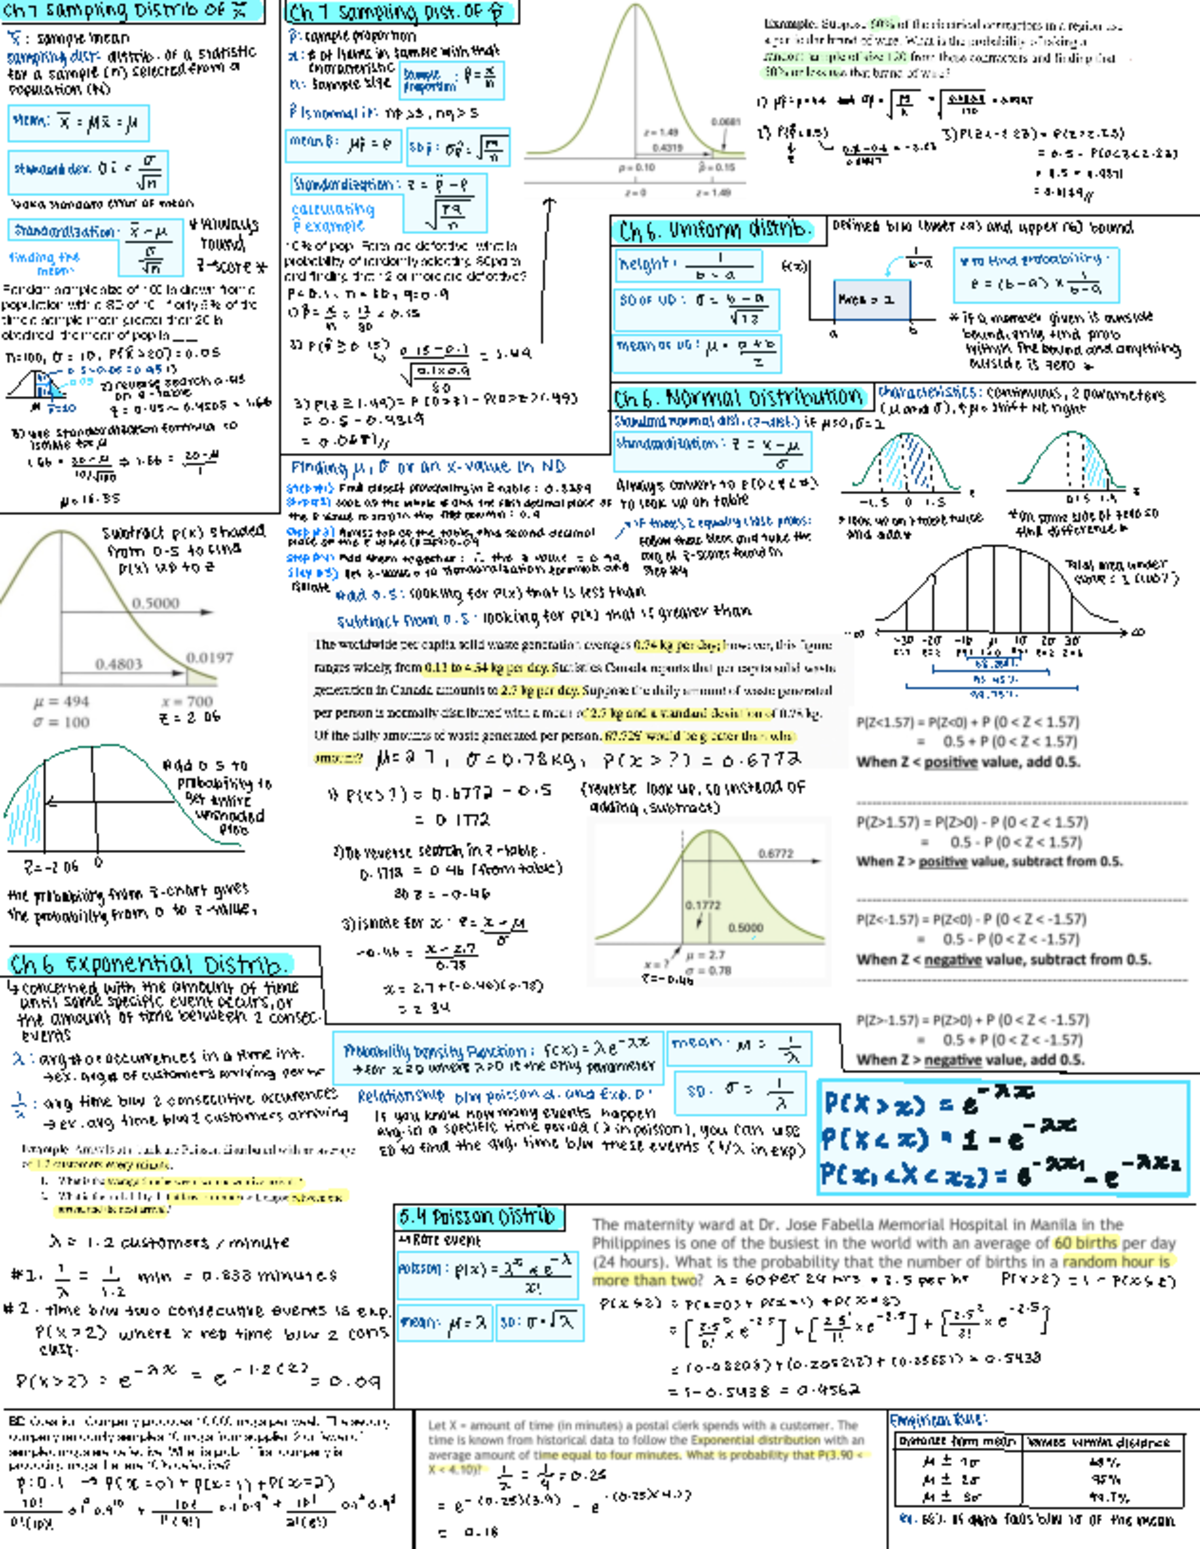
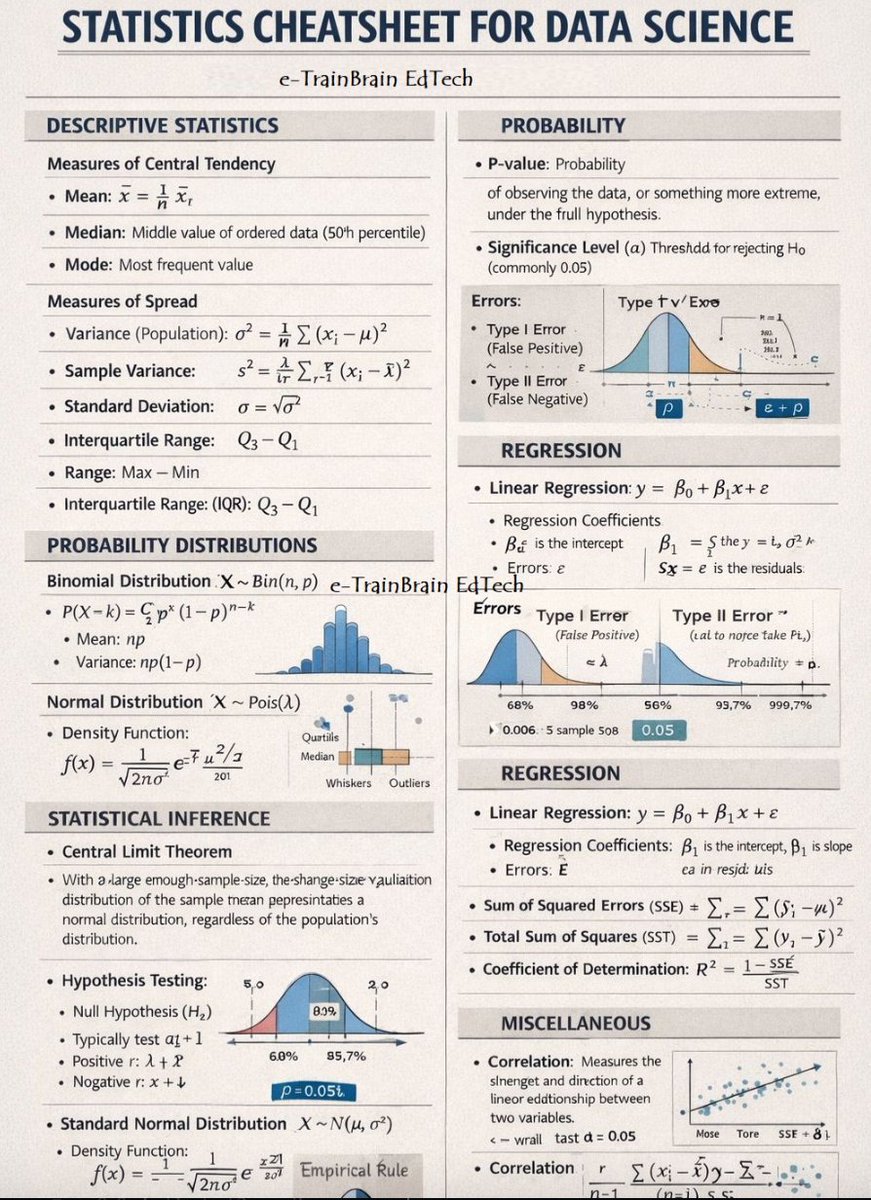
Here is what belongs on one and what mine looks like after three years of use. 1. Measures of central tendency. Mean, median, mode. Simple, yes, but the median is the one people forget when their data has outliers, and then they report a mean that makes the story look completely different than it should. I had a client once who was presenting revenue growth and I used the median instead because three enterprises in the sample were ten times larger than everyone else. The mean suggested 40 percent growth. The median said 7 percent. Different boardroom conversation entirely. 2. Measures of dispersion. Range, interquartile range, variance, standard deviation. Variance is the average of squared deviations from the mean. Standard deviation is its square root. You will use both constantly. If someone asks for variance and you hand them standard deviation, nobody is going to correct you in real time, which is its own kind of risk.
3. Z-scores and standardization. z = (x - ) / . This is how you compare values from different distributions. I once standardized test scores from two different exams so we could rank students on a common scale, and the process took about twelve minutes once you know the formula rather than digging it up each time. 4. Probability rules. Addition rule, multiplication rule, Bayes theorem. P(A|B) = P(B|A) * P(A) / P(B). Bayes keeps tripping people up because the notation hides what is actually a simple ratio of joint probability to marginal probability. The workaround I use now is writing out the full sentence version before plugging numbers in. It takes longer but it prevents the inversion error that shows up on every first pass. 5. Expected value and variance of discrete random variables. E[X] = x * P(x). Var(X) = E[X²] - (E[X])². The second form is usually faster to compute by hand than summing squared deviations directly, though calculators make that distinction irrelevant these days.
Get the Full Details

6. Common distributions. Binomial, Poisson, normal, exponential. Know the parameters, know when each one fits. Binomial needs fixed trials and constant probability. Poisson handles counts over an interval. Normal is the default assumption and also the wrong one more often than people admit. Exponential models waiting times between events. 7. Confidence intervals. For a mean with known : x ± z* (/n). For unknown : x ± t* (s/n). The shift from z to t is not cosmetic, it matters when n is small, and I have seen analysts miss that distinction in reports that ended up getting pulled for reproducibility reasons. 8. Hypothesis testing fundamentals. Null and alternative hypotheses, test statistics, p-values, rejection regions. The mechanics are straightforward. The part that gets people is interpreting the p-value as the probability the null is true, which it is not. It is the probability of observing data this extreme given the null is true. Directionally opposite, even though the words sound identical.
9. Common test statistics. One-sample z-test, one-sample t-test, two-sample t-test (pooled and unpooled), paired t-test, chi-square test of independence, ANOVA F-statistic. Pooled variance: s²p = [(n-1)s² + (n-1)s²] / (n+n-2). Use the pooled version only when equal variances is a reasonable assumption, otherwise go with Welch's correction. I learned that the hard way during a regression audit where the pooled assumption was quietly violated across four subgroups. 10. Correlation and regression. Pearson correlation r = (x-x)(y-ȳ) / [(x-x)² (y-ȳ)²]. Linear regression line: ŷ = b + bx, where b = r * (s/s) and b = ȳ - bx. R-squared is the proportion of variance explained. None of these are hard to remember if you write them down once in a place you actually look at.
How to Build Your Own Without Losing Your Mind
The best cheat sheet is the one you update. Mine started as a printed A4 from a university resource center and got annotated until the paper itself was illegible, so I moved it to a notes file and then to a proper document. The format matters less than the habit of adding a formula the first time you reach for it and cannot recall it immediately. I keep three sections: core formulas, assumptions and when to break them, and the edge cases that cost me time. The third section is where the real value sits. For example, Pearson correlation assumes linearity and homoscedasticity, and it is sensitive to outliers in a way that Spearman's rho is not. I added a one-line note about that after spending an afternoon wondering why my correlation coefficient looked wrong on a dataset with a single leverage point.
Where People Go Wrong
The most common mistake is treating a cheat sheet as a substitute for understanding the assumptions behind each formula. A z-test formula on paper does not tell you that your data need to be approximately normal and that your sample should ideally exceed thirty observations before that assumption becomes defensible. Nobody writes that on a one-page reference, which is exactly why you need your own notes alongside the formulas. Another issue is memorizing formulas in isolation. Variance, standard deviation, and standard error are related but not interchangeable, and confusing them is easy when you are under time pressure. Standard error of the mean is /n, which shrinks as sample size grows, while standard deviation stays roughly constant for a stable population. I keep them side by side on my sheet now with a color code that makes the distinction visible without reading.
Download and Formats
There is no single canonical version, and honestly the best one is yours. That said, several community-maintained versions circulate as PDFs, and the Khan Academy and Stat Trek reference pages are reliable starting points if you want something structured before you annotate it into something useful. I export mine as a single-page PDF and keep it pinned in my browser sidebar during analysis work. Loading it takes about two seconds and saves whatever time I would otherwise spend searching documentation. If you are doing Bayesian inference, bootstrapping, or working with mixed-effects models, a Top 10 Statistics Cheat Sheet will cover maybe two formulas that apply to your actual problem. Those methods belong to a different reference layer. A beginner-friendly sheet is still useful as context, but you will outgrow it quickly if your work involves hierarchical models or Markov chain Monte Carlo sampling. In those cases I keep a separate document for likelihood functions and priors, because mixing them on the same page creates visual clutter that slows you down. The practical takeaway is that a well-organized reference sheet cuts lookup time from minutes to seconds and reduces the chance of using the wrong formula under pressure. It does not replace knowing when not to use a formula, and it will not help with methods that live outside the introductory curriculum. Building one takes a few hours the first time and ten minutes each month after that to keep it accurate.