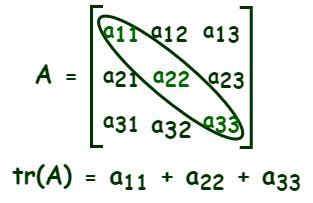
Trace Of A Matrix — What It Actually Is And Why You Should Care
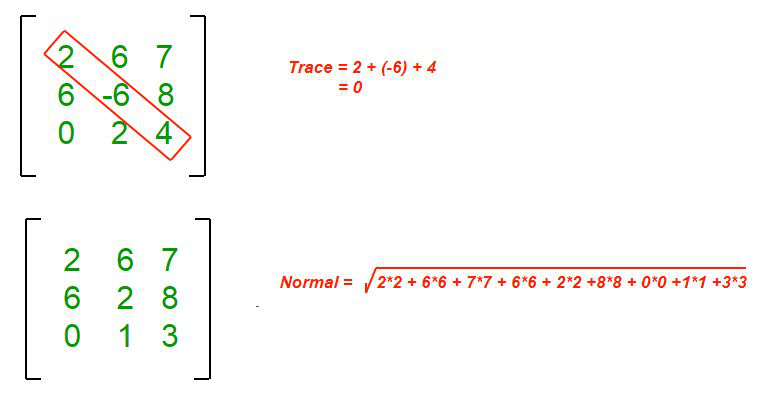
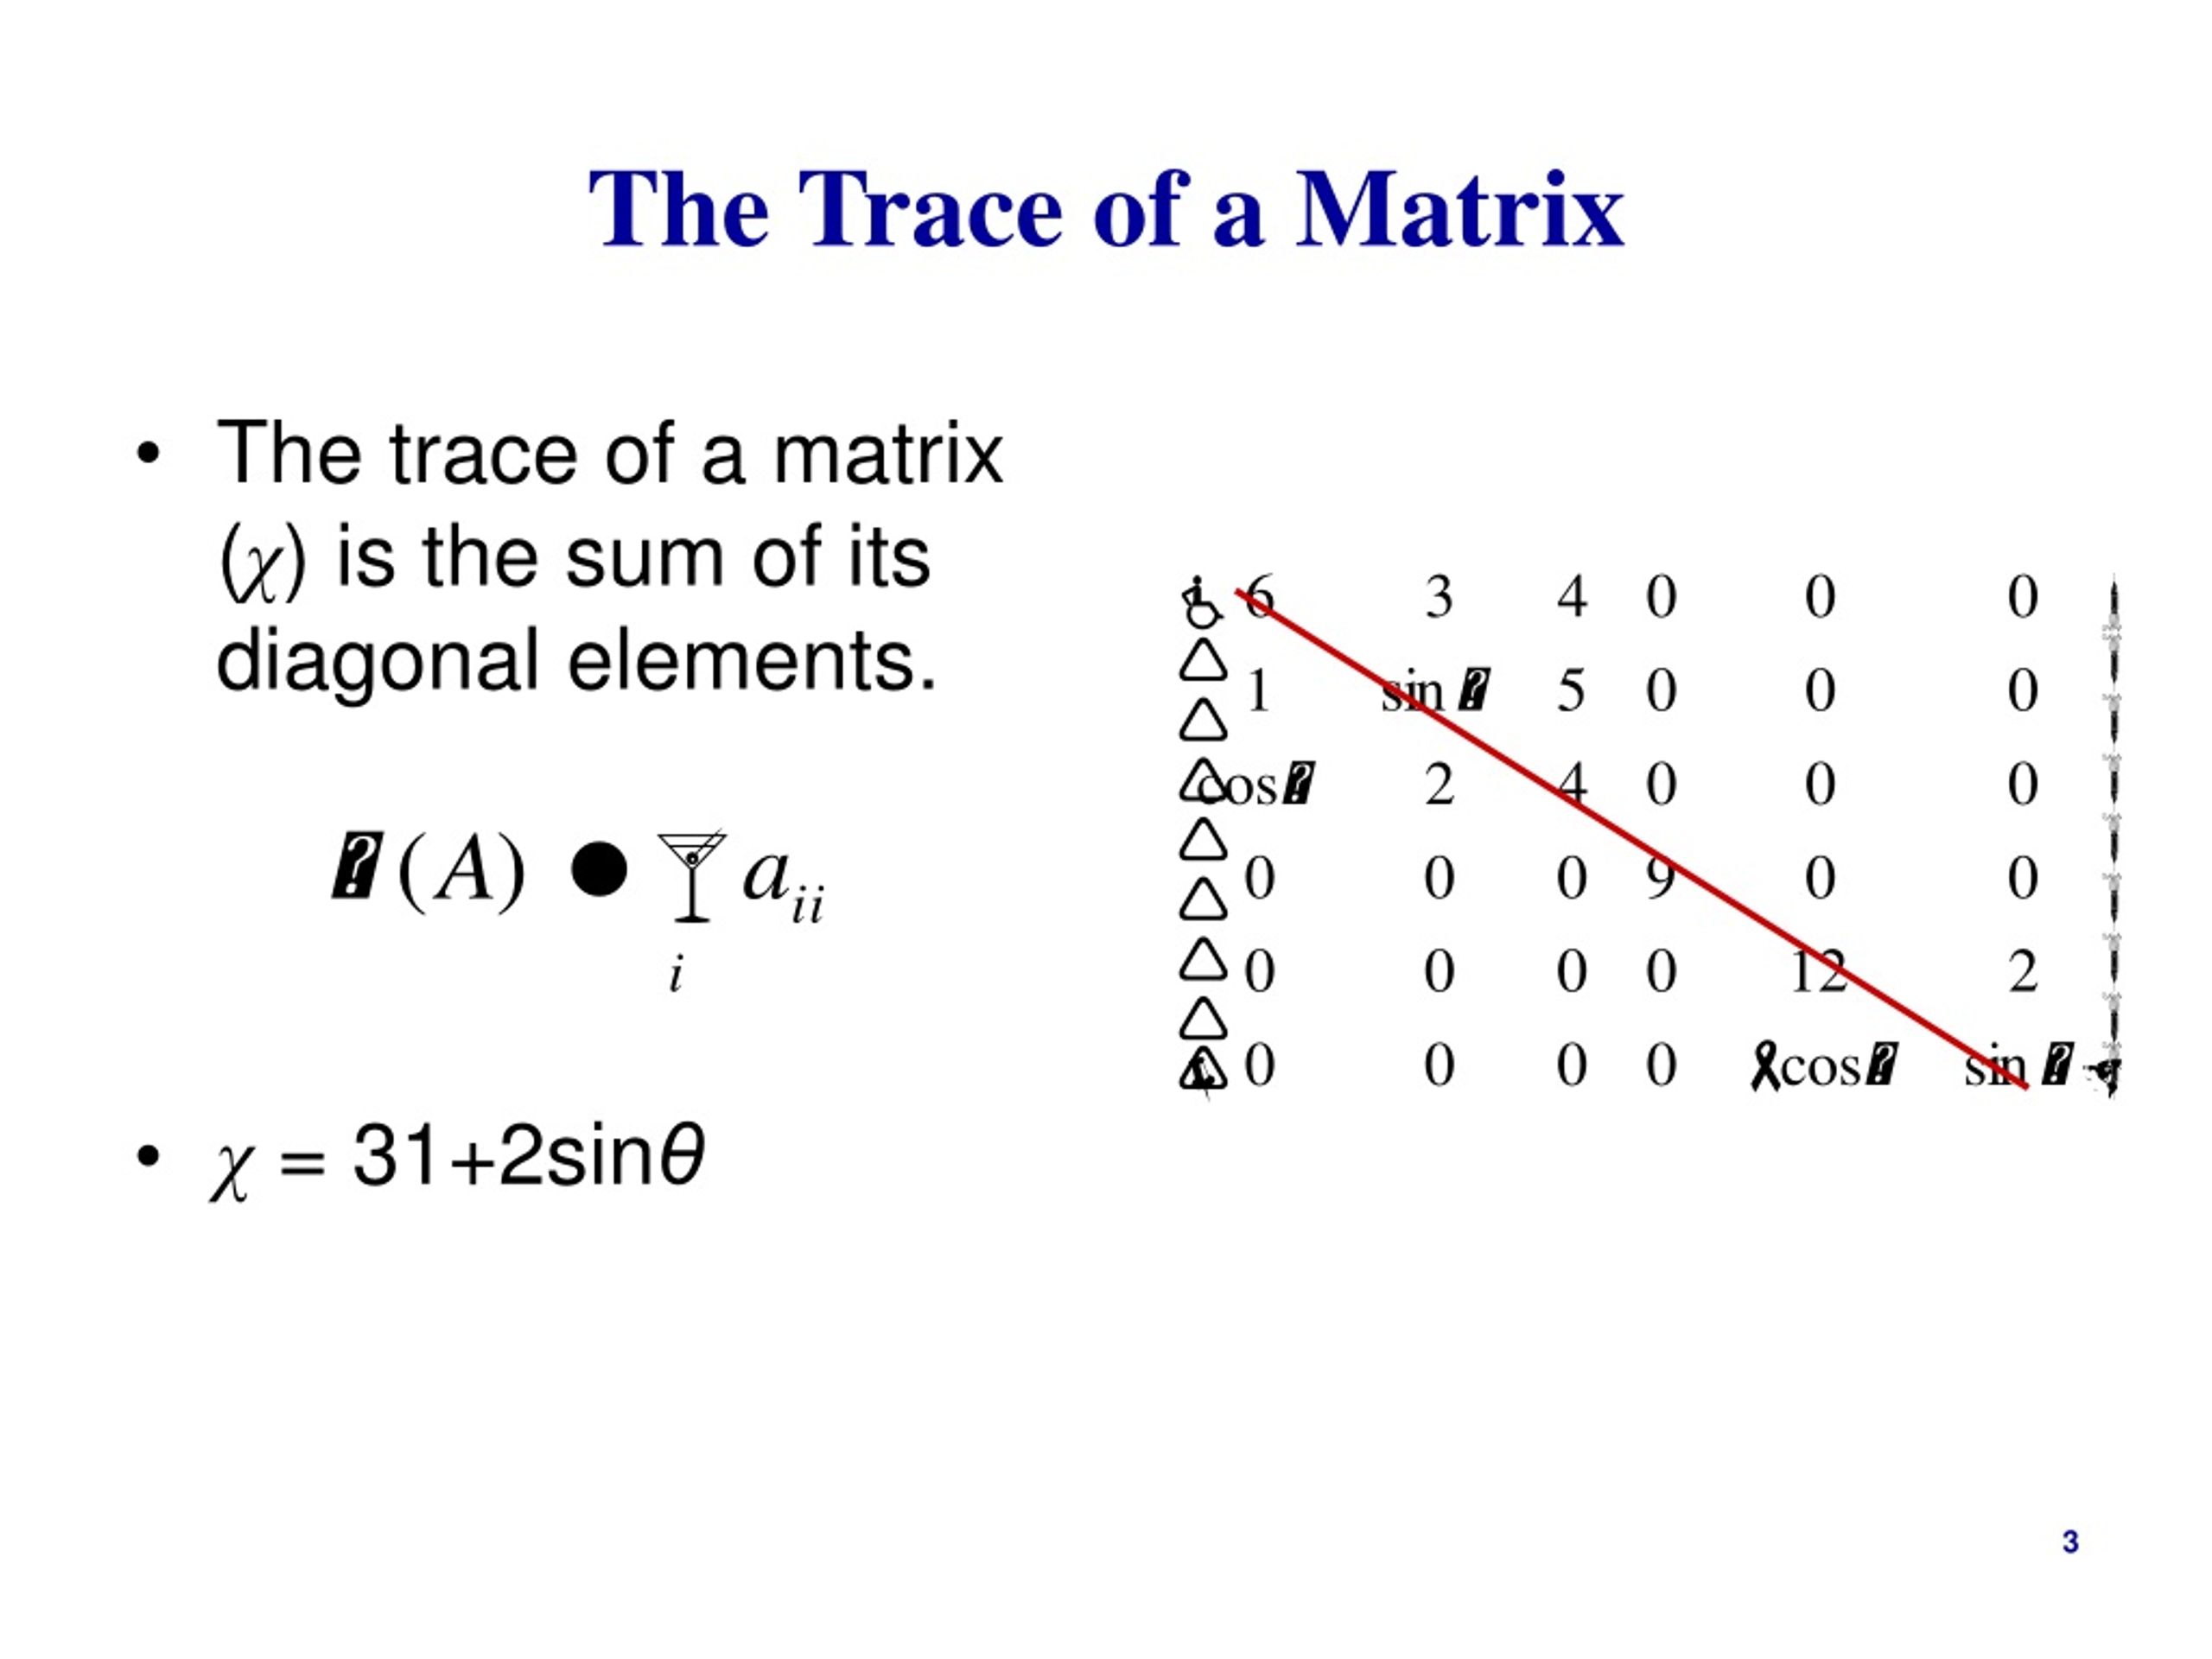
The trace of a matrix is the sum of its diagonal entries. That is the entire definition. For a square matrix A with elements a_ij, the trace is tr(A) = sum of a_ii for i from 1 to n. Nothing fancy about it. But the way people talk about it online makes it sound like some mystical concept when really it is just arithmetic on a diagonal. Most people know how to add up diagonal elements by hand. The real question is what to do when you are working with actual data. Here is the practical part. In numpy, you just use np.trace(A). In MATLAB, it is trace(A). In Python with larger arrays, np.einsum('ii->', A) is slightly faster because it avoids some overhead. I learned that the hard way when processing batches of 5000 covariance matrices of shape (512, 512). The difference between np.trace in a loop versus einsum cut my runtime from roughly 40 seconds down to about 6. It is not a huge deal for small workloads but it adds up when you are iterating.
The Eigenvalue Connection — And Why It Matters
The trace equals the sum of eigenvalues. This is not just a math trivia fact. It is the reason the trace shows up everywhere in signal processing and statistics. When you are working with covariance matrices, the trace gives you the total variance across all dimensions. That is why it is used in PCA for dimensionality selection — the trace of the covariance matrix tells you the total energy in the signal. If you drop components and the trace of the retained covariance drops too much, you are throwing away information. I once spent two days debugging a model that was quietly degrading because someone had replaced a full covariance trace calculation with an approximation that only kept the top 10 eigenvalues. The approximation was close enough for a single check but drifted over multiple training epochs. The fix was straightforward — compute the trace directly from the diagonal of the original matrix instead of summing eigenvalues separately. The diagonal approach is numerically more stable anyway because you avoid the eigen decomposition entirely.
Cyclic Property — The Thing Nobody Remembers
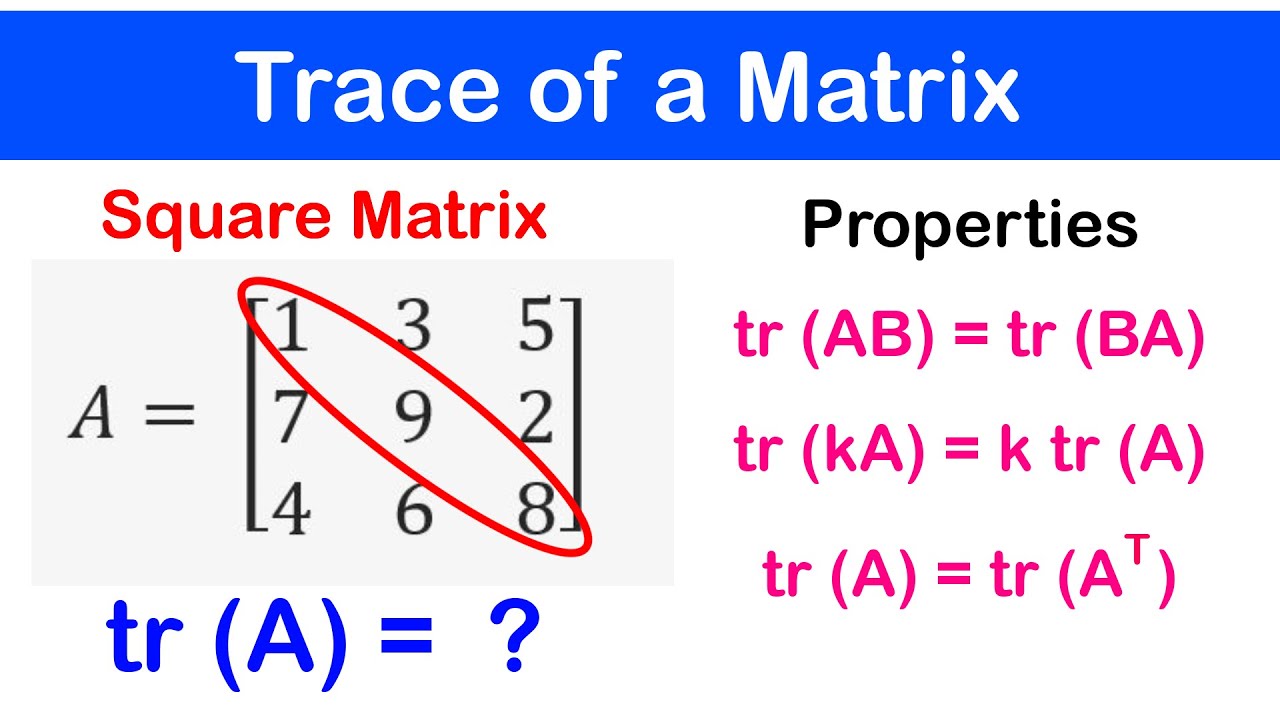
The trace has a cyclic property: tr(ABC) = tr(BCA) = tr(CAB). This is useful when you are trying to optimize computational graphs. For example, if you have three matrices and one of the cyclic permutations reduces the intermediate dimension significantly, you should reorder them. I ran into this when computing the trace of a product involving a (10000, 8) matrix, an (8, 8) matrix, and an (8, 10000) matrix. Computing ABC first creates a (10000, 10000) intermediate — that is 800 million elements. Computing CAB first keeps everything in the 8-dimensional space and the trace comes out the same. The cyclic property guarantees it. This is also why trace appears in the derivation of backpropagation for neural networks. When you compute gradients through matrix products, rearranging with the cyclic property can turn an O(n^2) operation into an O(n) one. Most tutorials skip this detail because they assume you already know linear algebra internals. You probably do not.
Get the Full Details
Trace of Kronecker Product
If you are working with tensor products or block-structured systems, the trace of a Kronecker product has a clean rule: tr(A B) = tr(A) * tr(B). I encountered this when dealing with a multi-sensor fusion problem where each sensor had its own covariance block. The overall system covariance was a Kronecker product of the individual sensor covariances, and computing the trace naively would have required building the full (n*m, n*m) matrix. Multiplying the individual traces instead took microseconds. The trace is only defined for square matrices. If you pass a non-square matrix to a trace function, you will get an error, though some libraries silently return incorrect results depending on how they handle the input. Always verify your matrix is square before computing. Another issue: the trace is sensitive to scaling. If you scale a matrix by a constant c, the trace scales by c as well. This is obvious but easy to forget when you are normalizing data and then checking trace values across batches. I once normalized features per-batch and assumed the trace would remain comparable across batches. It did not, because different batches had different variance scales. The fix was to compute a global normalization factor instead of per-batch.
The trace also does not capture all the information in a matrix. Two matrices can have the same trace but be completely different. It is a scalar summary — useful but limited. If you need the full structure, look at the eigenvalues or singular values instead.
When Trace Fails You
There are cases where relying on the trace alone gives you misleading results. For instance, in sparse matrix computations, the trace only sees the diagonal entries. If your matrix has significant off-diagonal structure that matters for your application — say you are doing some kind of graph Laplacian analysis — the trace will tell you almost nothing useful. In those situations, you need the full matrix or at least the eigenvalue spectrum. Also, for ill-conditioned matrices, computing the trace via eigenvalue summation can be numerically unstable. The direct diagonal sum is always preferred when you have the matrix explicitly. The eigenvalue route is only worth considering when you are already computing eigenvalues for another purpose.

Summary of Practical Rules
Use np.trace or equivalent for straightforward cases. Use einsum for batch operations where performance matters. Leverage the cyclic property to minimize intermediate matrix sizes in products. Remember that trace equals sum of eigenvalues but compute it from the diagonal when possible. Check that your matrix is square before calling any trace function. And do not treat the trace as a complete descriptor of a matrix — it is one number, nothing more.