Keeping Track of Biology Experiments Without Losing Your Mind
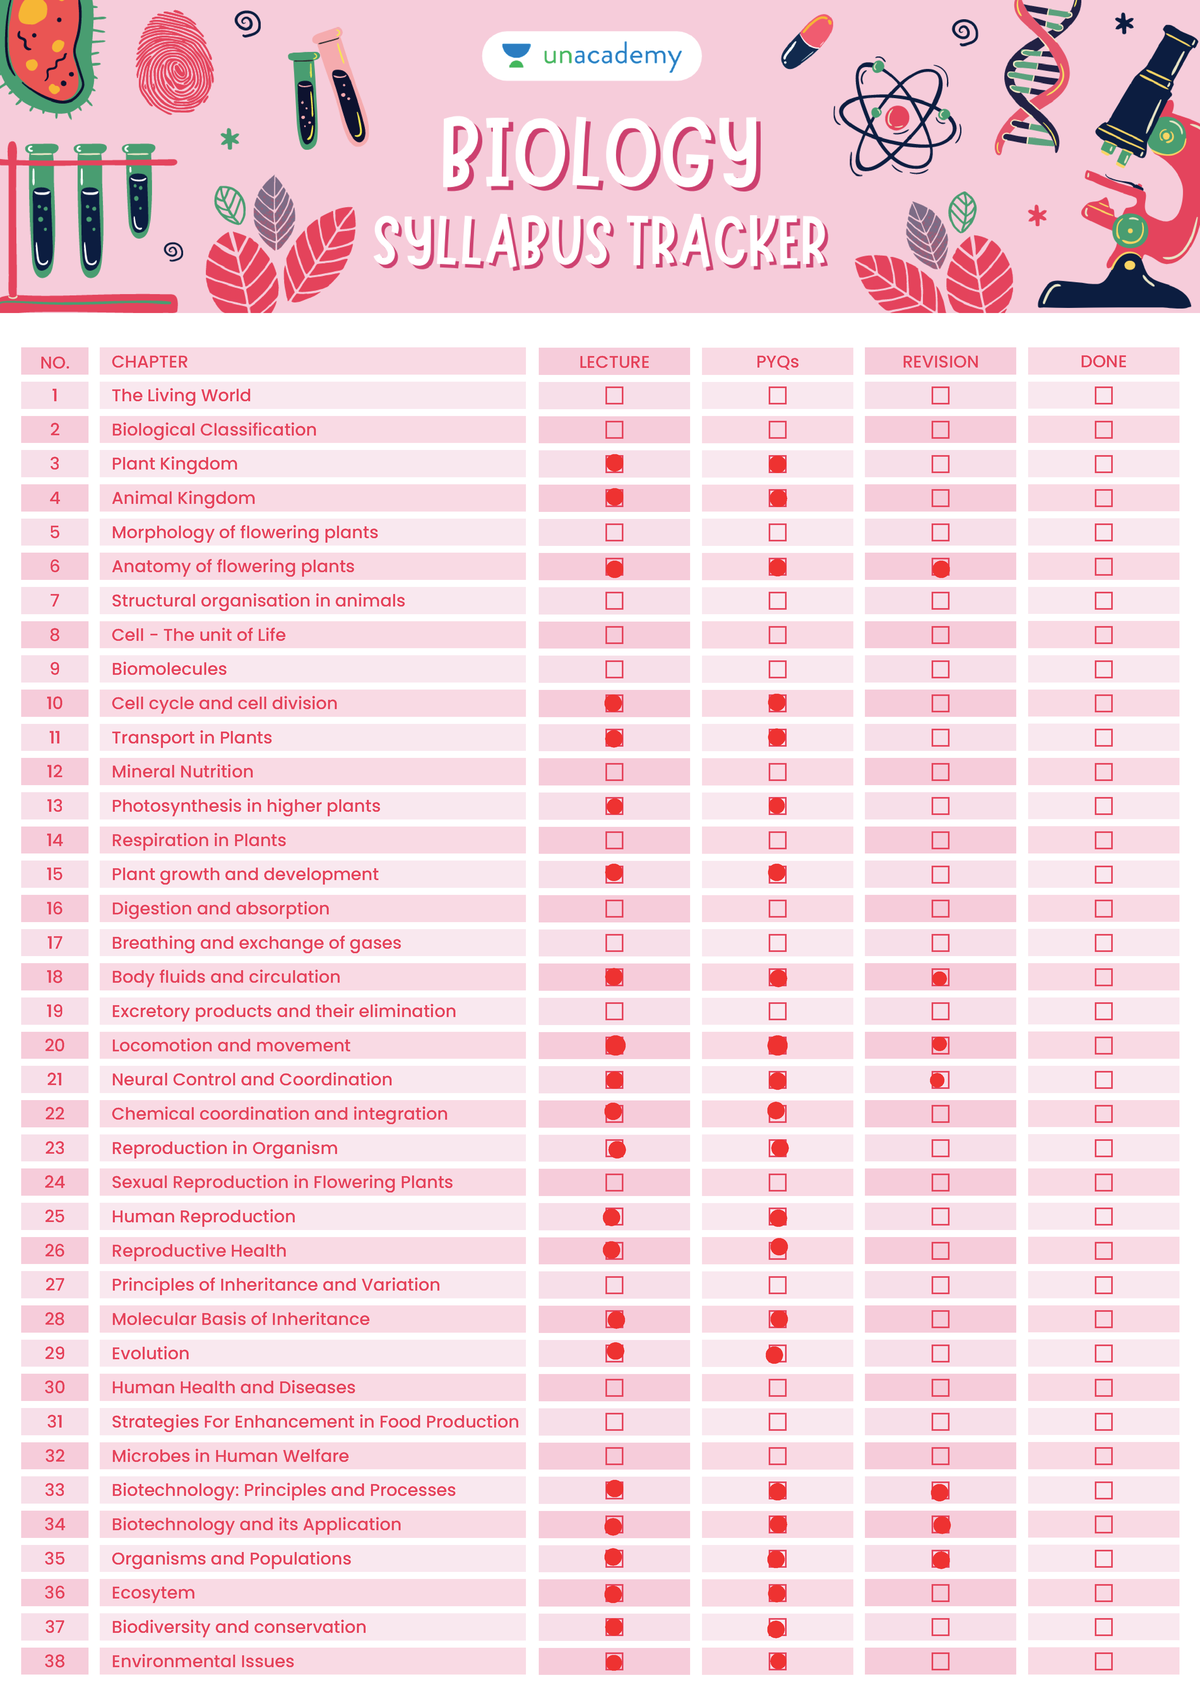
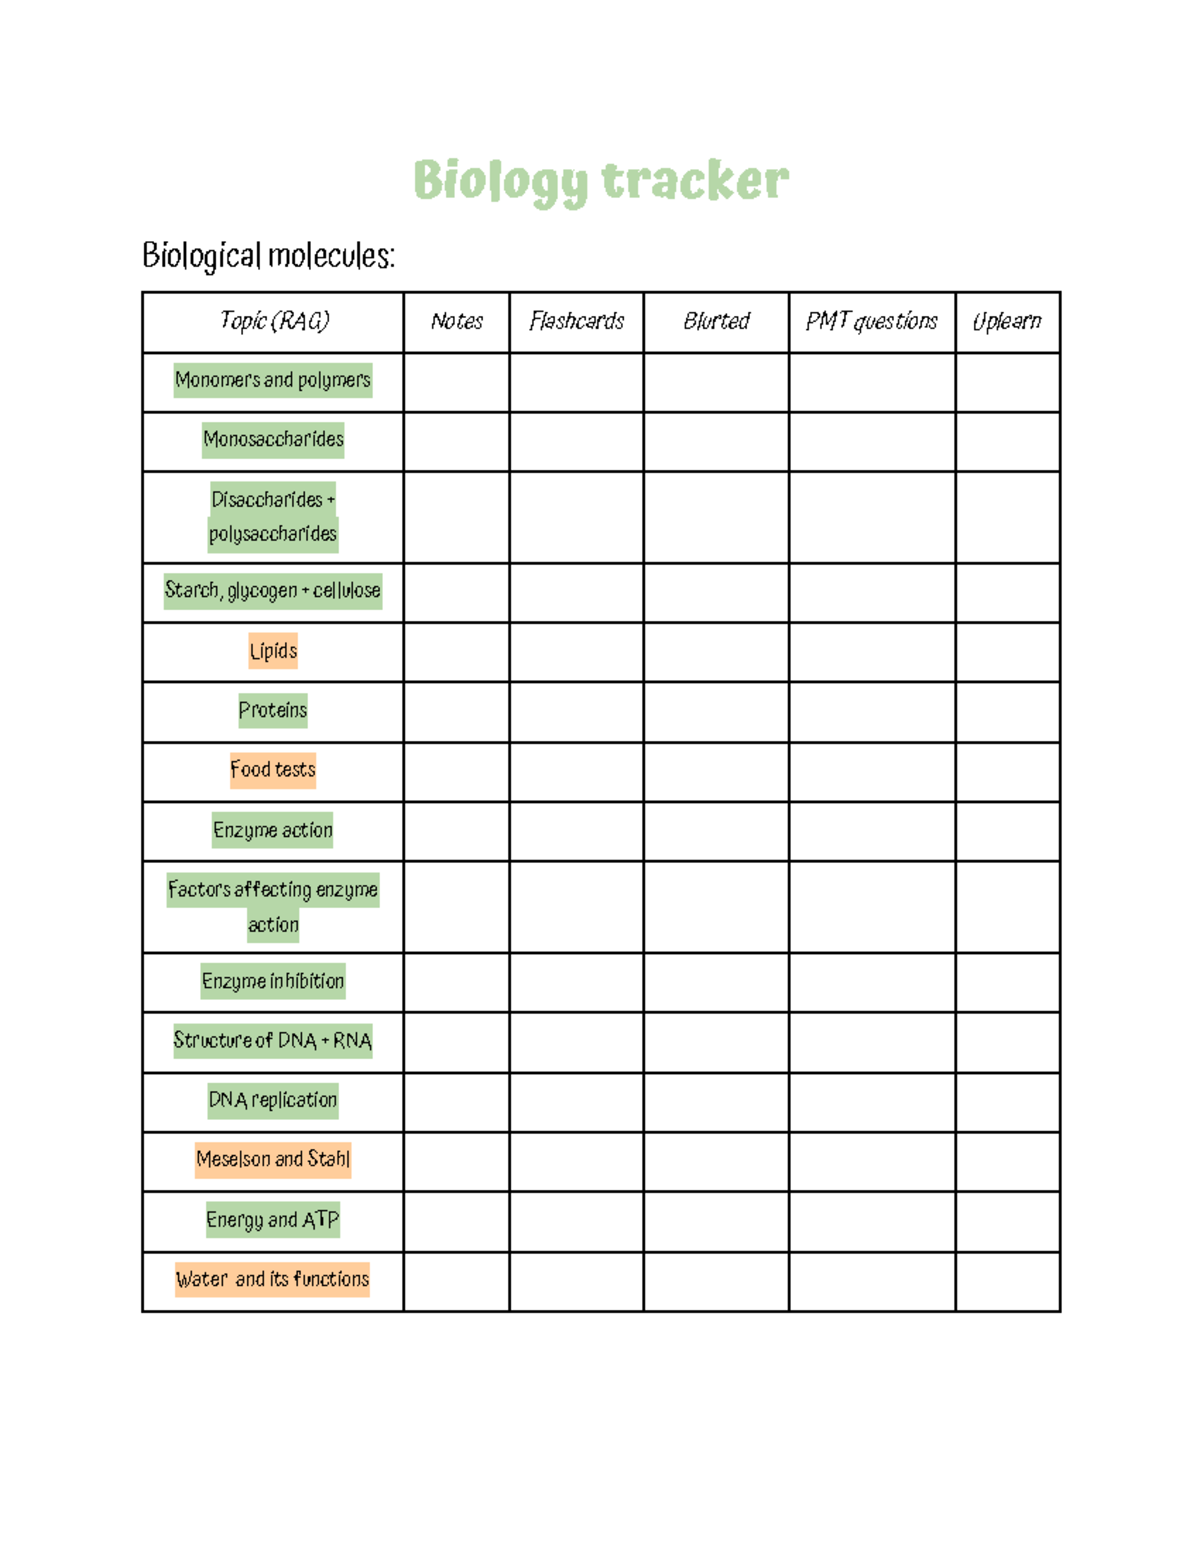
I've been running biology lab work for about twelve years now. Early on I tried spreadsheet tracking, notebook methods, then bought some expensive software nobody taught me how to use. Eventually I landed on something I now call Tracker For Biology Simple and it just works. It is not a standalone product you download. People use that phrase to describe a lightweight tracking system designed for biology students and researchers who need to log experimental data without wrestling with complicated databases. The core idea is basic: create a structured log where each entry captures the date, the organism or sample type, the treatment condition, and the result. That is it. Nothing fancy. I learned this the hard way. Back in 2014 I was tracking fruit fly populations across seventeen different temperature conditions. My initial Excel file had 3,200 rows and by month three it crashed every time I opened it. I spent two full days recovering data and lost some replicate counts entirely. After that I built a much simpler system based on plain CSV files with a fixed schema. It runs fine even with thousands of entries.
How to Set It Up
Open a blank spreadsheet or create a CSV template with these columns: Date, Sample ID, Organism, Treatment Group, Initial Measurement, Final Measurement, Notes. That single setup handles most undergraduate lab work and many field studies without modification. Do not add extra columns until you actually need them. Every unnecessary column increases the chance of data entry errors and makes filtering harder later. Here is the part most people skip. Before you enter your first measurement, fill in every column header with exactly one word or a short acronym. Write temperature instead of Temp so it matches when you later import into R or Python. I once spent forty-five minutes debugging a script that failed because one column read Ctemp and another read C_temp. They were the same variable. Changing one to match the other fixed it in under five minutes.
Sample Entry Structure
A proper row should look like this: 2024-06-12, FLY-047, Drosophila melanogaster, 25C, 12.3mg, 18.7mg, normal pupation observed. Keep the Notes column brief but specific. Never write just ok or similar. Instead note what actually happened. If a container leaked, say which one and when. If you had to discard a replicate because contamination appeared, record that date too. Future you will thank you. Some researchers build in a Status column with values like pending, in progress, complete, or discarded. That helps when you have multiple time points per sample. I found that adding a Replicate number column prevents a common mistake where people enter the same measurement twice for different biological replicates and then cannot tell which is which.
Get the Full Details
Where to Find Tracker For Biology Simple Templates
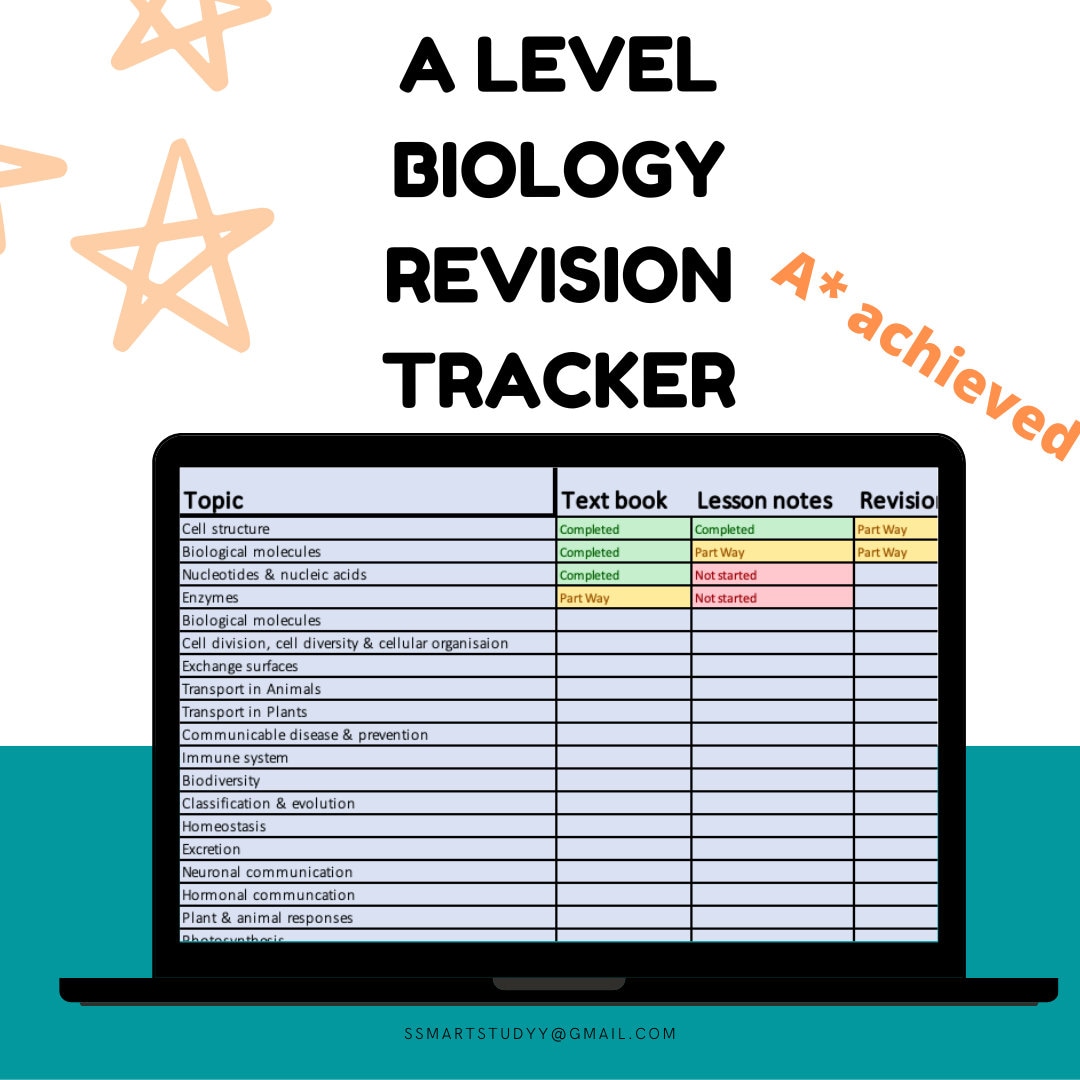
There is no official central repository. You will find working templates on GitHub by searching for biology data tracker or lab notebook CSV. Search for Tracker For Biology Simple and you will see community-maintained versions with variations. The key ones I trust are the ones that include a README explaining the column schema and a sample data file. Avoid templates without documentation. Half of them have mismatched headers or missing date formats that break analysis scripts. A good starting template gives you a filled example row so you understand the expected format. I keep a copy at https://github.com/labdata/biology-tracker-simple as a reference, though I do not recommend building your entire system around a single repository since these projects often go unmaintained after a year or two.
Common Pitfalls
The biggest issue people run into is mixing units within a single column. One entry might say 15mm and another says 1.5cm. This ruins any averaging or statistical analysis later. Convert everything to a single unit before you start recording. Do the same with dates. Some people write June 12, 2024 while others use 06/12/24. Pick ISO format, yyyy-mm-dd, and stick with it. Another problem is missing sample IDs. If you lose a physical sample or mislabel a tube, you should still be able to trace what happened to it through the log. Always assign a unique identifier before the experiment begins. I use a prefix tied to the project plus a sequential number. FLY-001, FLY-002, and so on. It takes two seconds and saves hours when something goes wrong. There is also a hidden trap with duplicate entries. When two people enter data for the same samples, you will get duplicates unless you check for them regularly. I run a simple uniqueness check on the Sample ID and Date columns every Friday. In the past I caught three duplicate rows that would have skewed my final averages by about eight percent. Catching those early matters.
Limitations You Should Know About
This system works well for smaller studies with up to a few thousand records. Once you move into larger field work or multi-year projects with thousands of samples per week, a spreadsheet becomes painful. Filtering across many conditions slows down. Pivot tables get unwieldy. At that point you should switch to a proper database or a tool like Google Sheets with linked tabs, or even a lightweight PostgreSQL instance if your institution provides one. Tracker For Biology Simple also does not handle complex metadata relationships well. If your experiment requires linking between parent samples and sub-samples, or tracking lineage through generations, a flat file will frustrate you. In those cases consider a simple relational setup or a dedicated lab notebook application. The simplicity that makes this approach attractive is also its main constraint.

Practical Example From My Recent Work
Last fall I tracked Arabidopsis thaliana growth under four light conditions with six replicates each over twenty-one days. I used a plain CSV with the standard columns plus an extra Day column to record measurements at each interval. The dataset grew to about 500 rows. I exported it weekly to a local backup folder and kept the original file untouched. Analysis took roughly twenty minutes in R once the data was clean. The bottleneck was never the tracking system itself. It was always data quality at entry time. That is the real lesson. The best Tracker For Biology Simple setup in the world cannot compensate for sloppy recording habits. Take the time to verify each entry before you close the file. If something feels off, double-check the measurement against the raw notebook before entering it. Ten seconds of verification prevents two hours of cleaning later.
Getting Started Today
Create the CSV template with the core columns. Fill in five sample rows by hand to test your workflow. Then start your actual experiment. Review the file once a week for formatting issues. Back it up to a cloud folder or external drive. That is the complete system. No special software required, no subscriptions, no training courses. Just a consistent approach to recording what you do and observing how things change over time. If you want a ready-made file to begin with, search for Tracker For Biology Simple on GitHub and pick a template with recent commits and active issues. The one I use most often has not been updated in about fourteen months, which is normal for a stable tool. You do not need new features. You need reliability.