What a Training Plan Template Actually Is
A Training Plan Template is just a structured document you use to outline how someone or something gets trained. In corporate settings, it's a form or sheet that captures the who, what, when, and how of a training initiative before any content is developed. In machine learning contexts, it's a configuration file that defines hyperparameters, dataset paths, training loops, and evaluation metrics so you can reproduce experiments without rewriting code every time. I'm going to cover both because people confuse them constantly. The corporate version helps HR and managers plan workshops, onboarding sequences, and skill development programs. The ML version helps data scientists track runs, compare model variants, and avoid the nightmare of forgetting which learning rate produced that good validation score last Tuesday.
Training Plan Template for Corporate Use
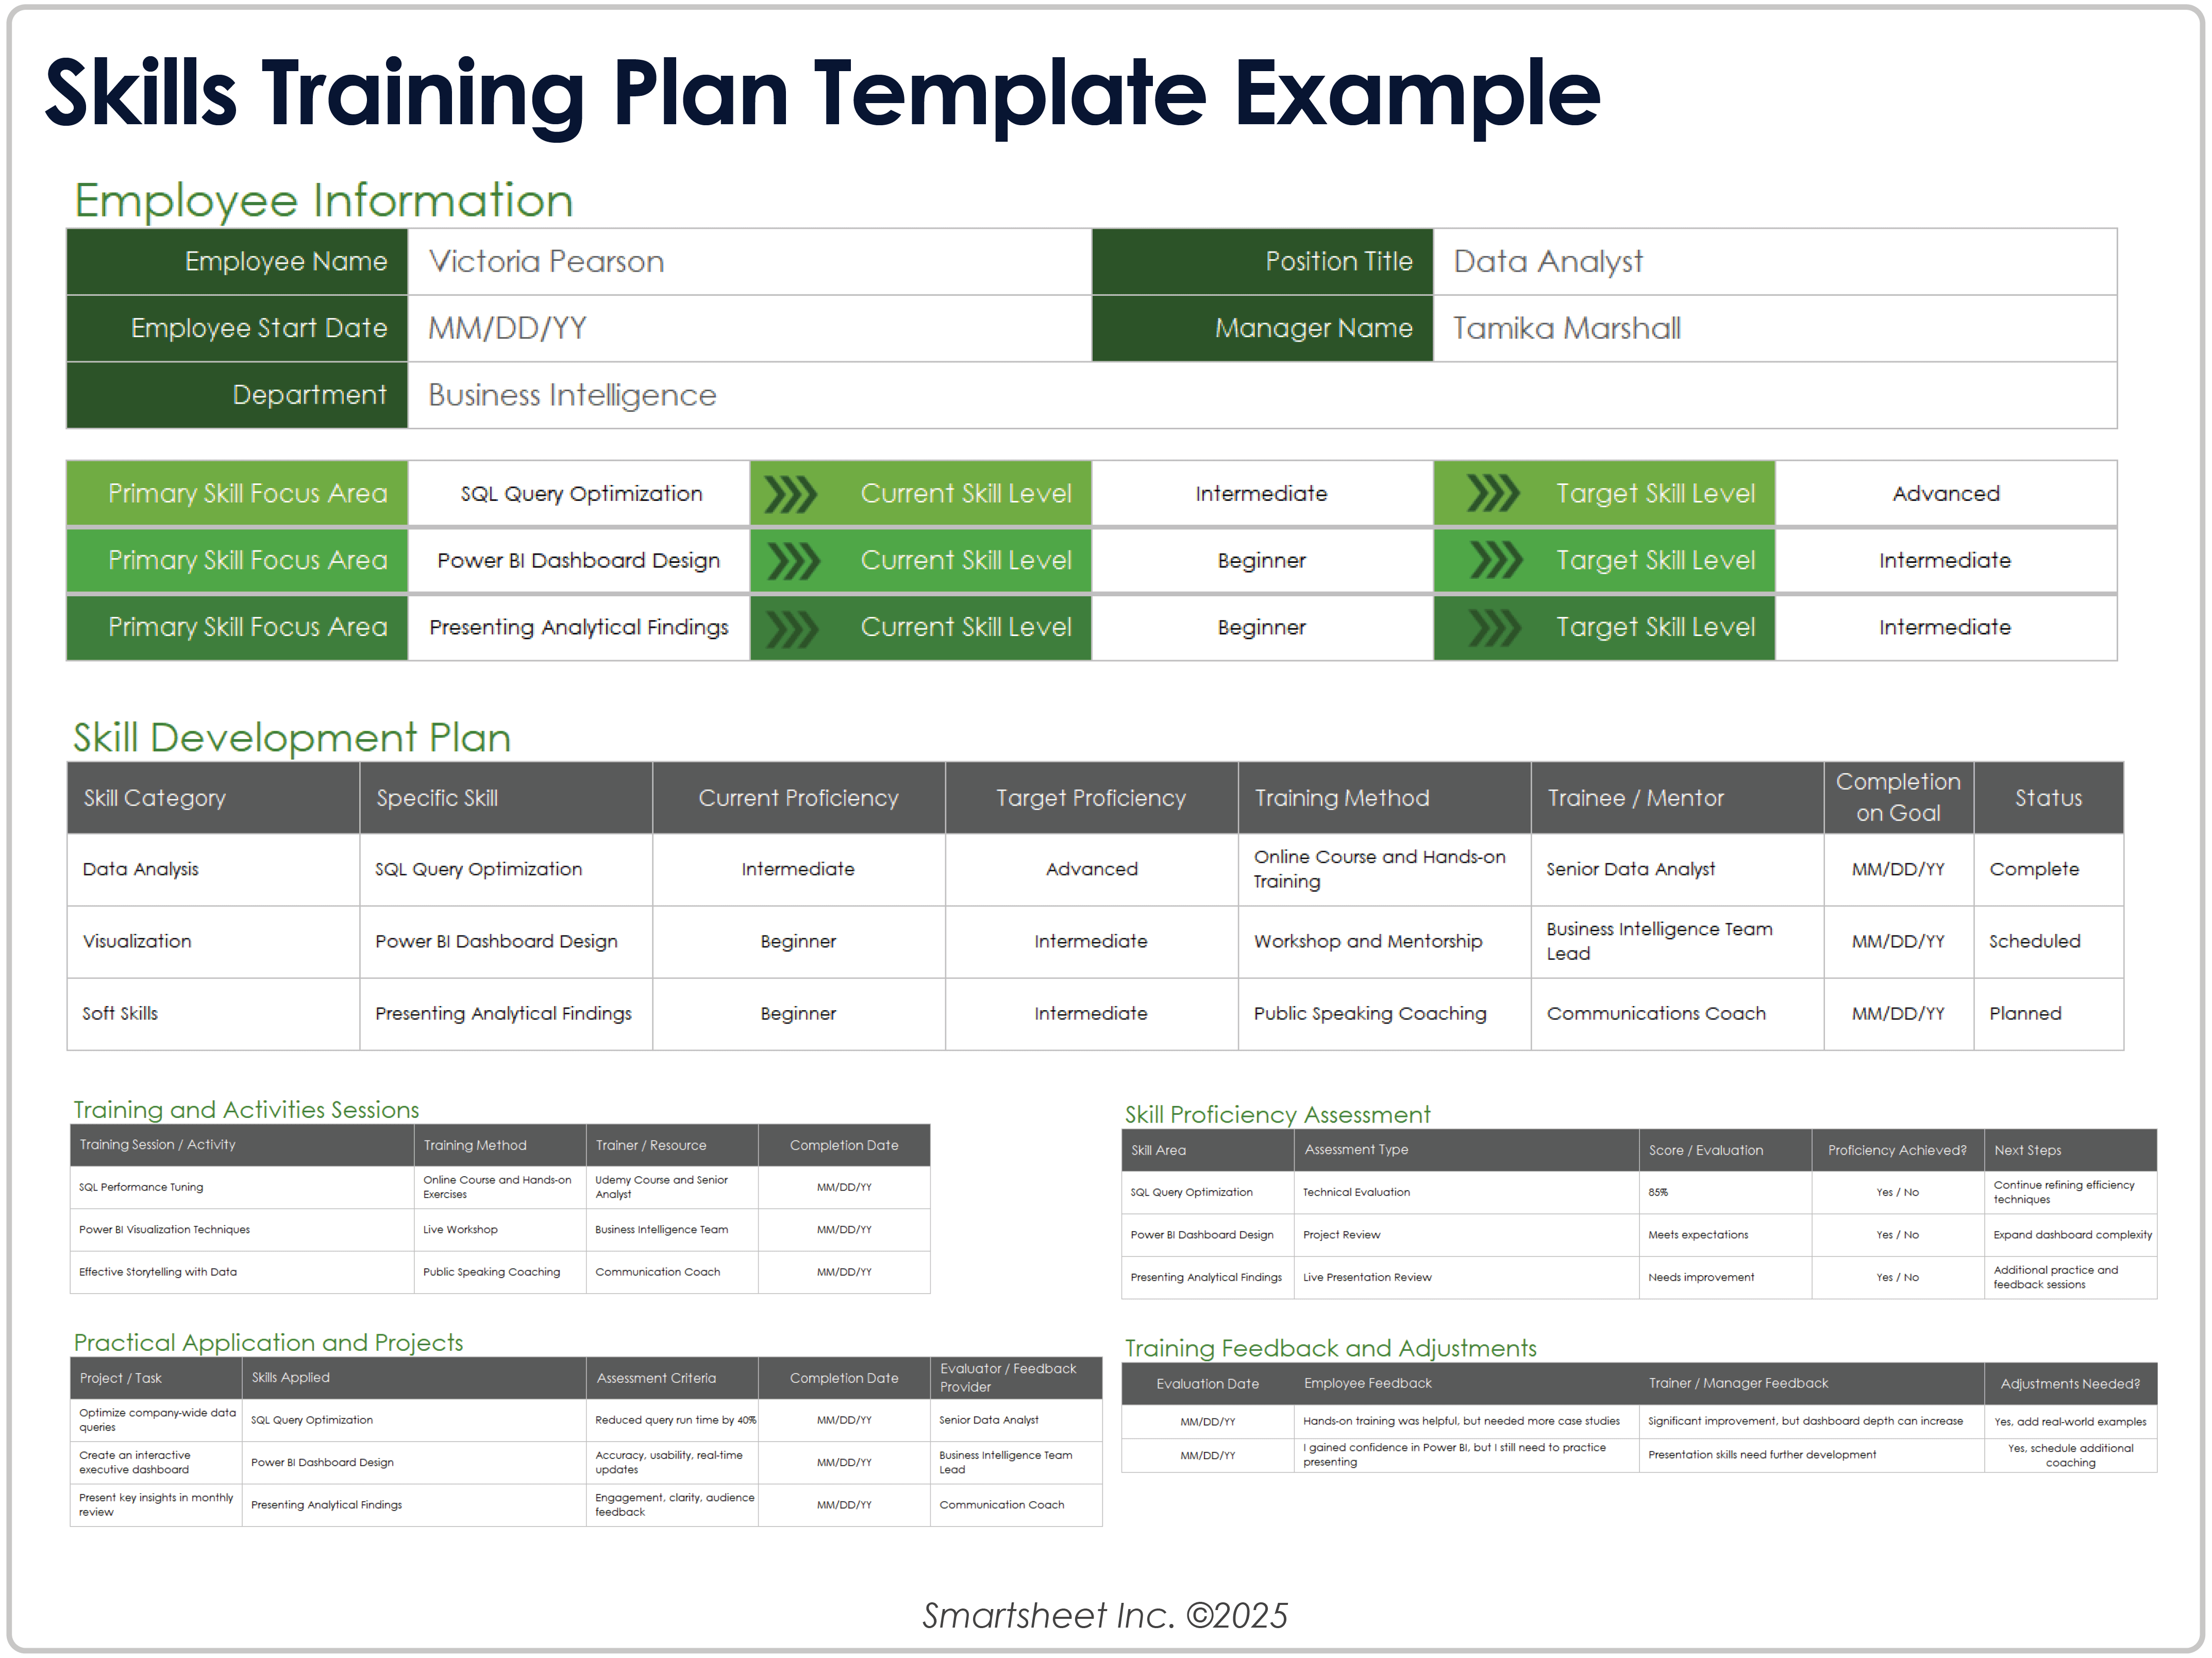
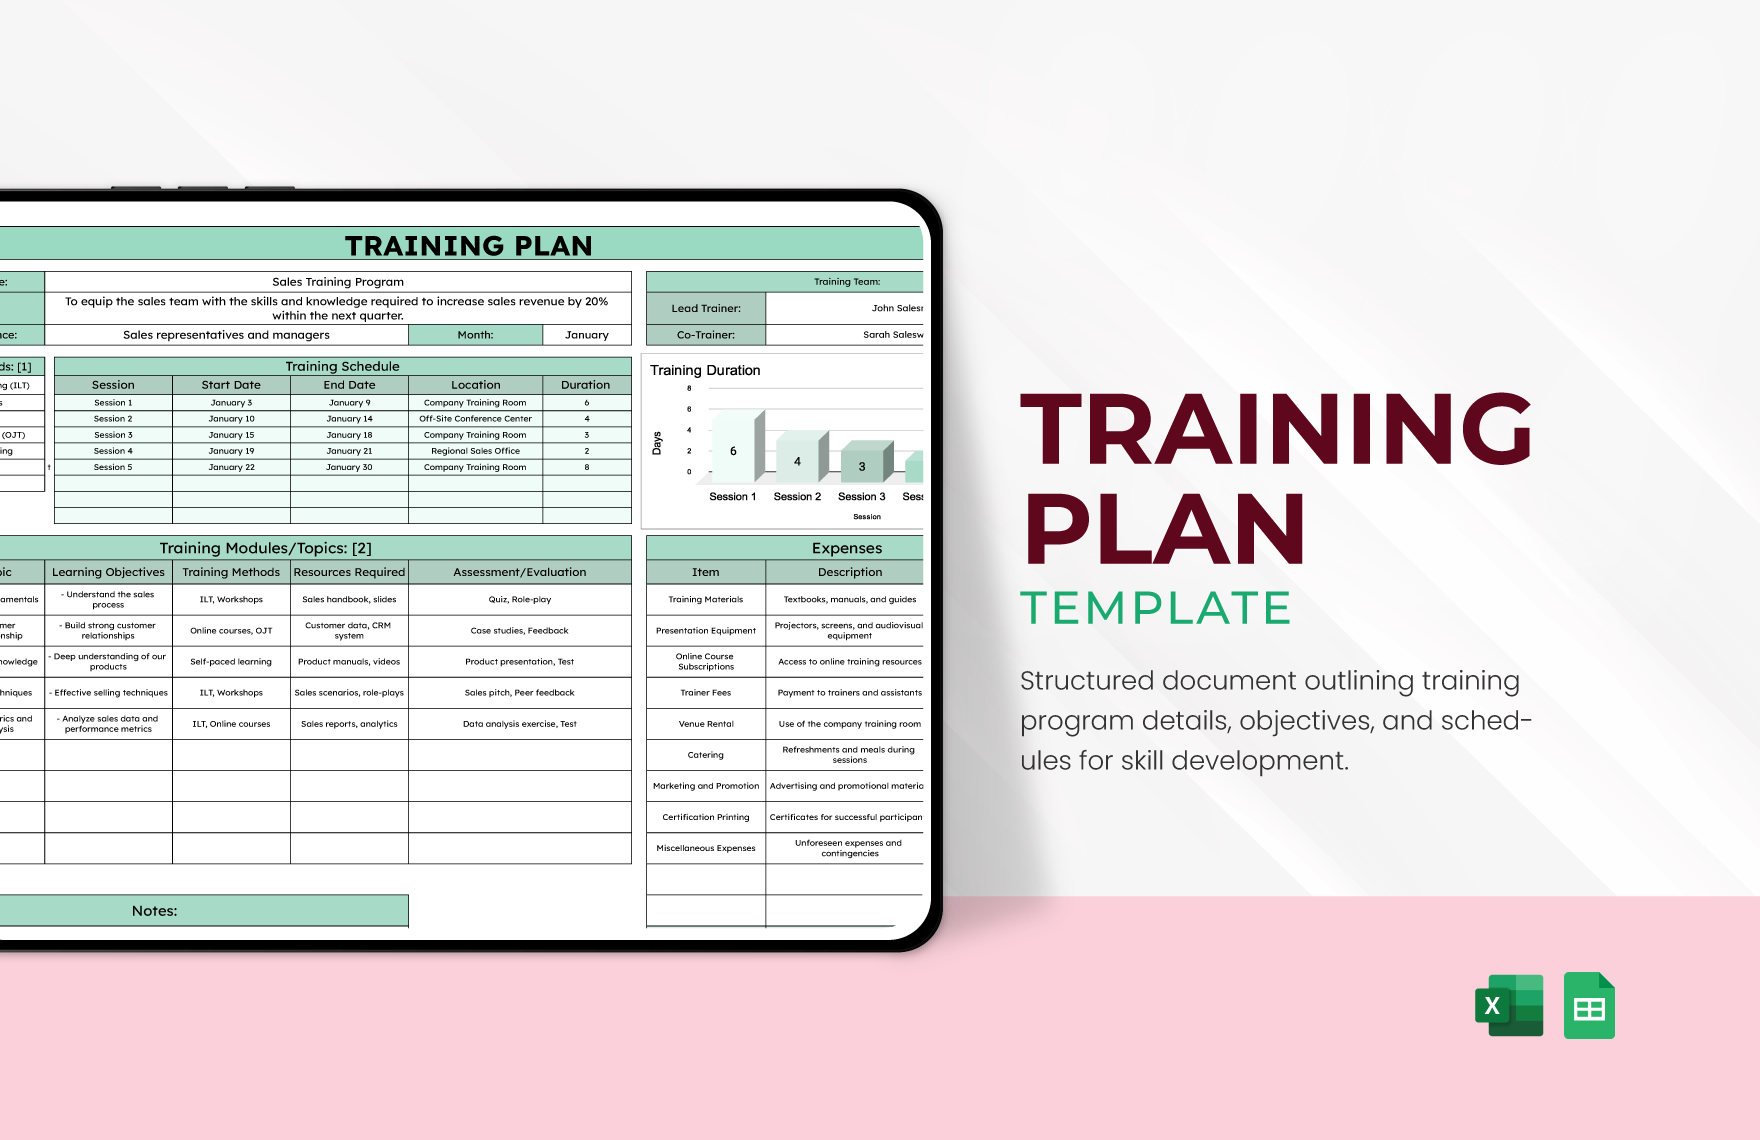
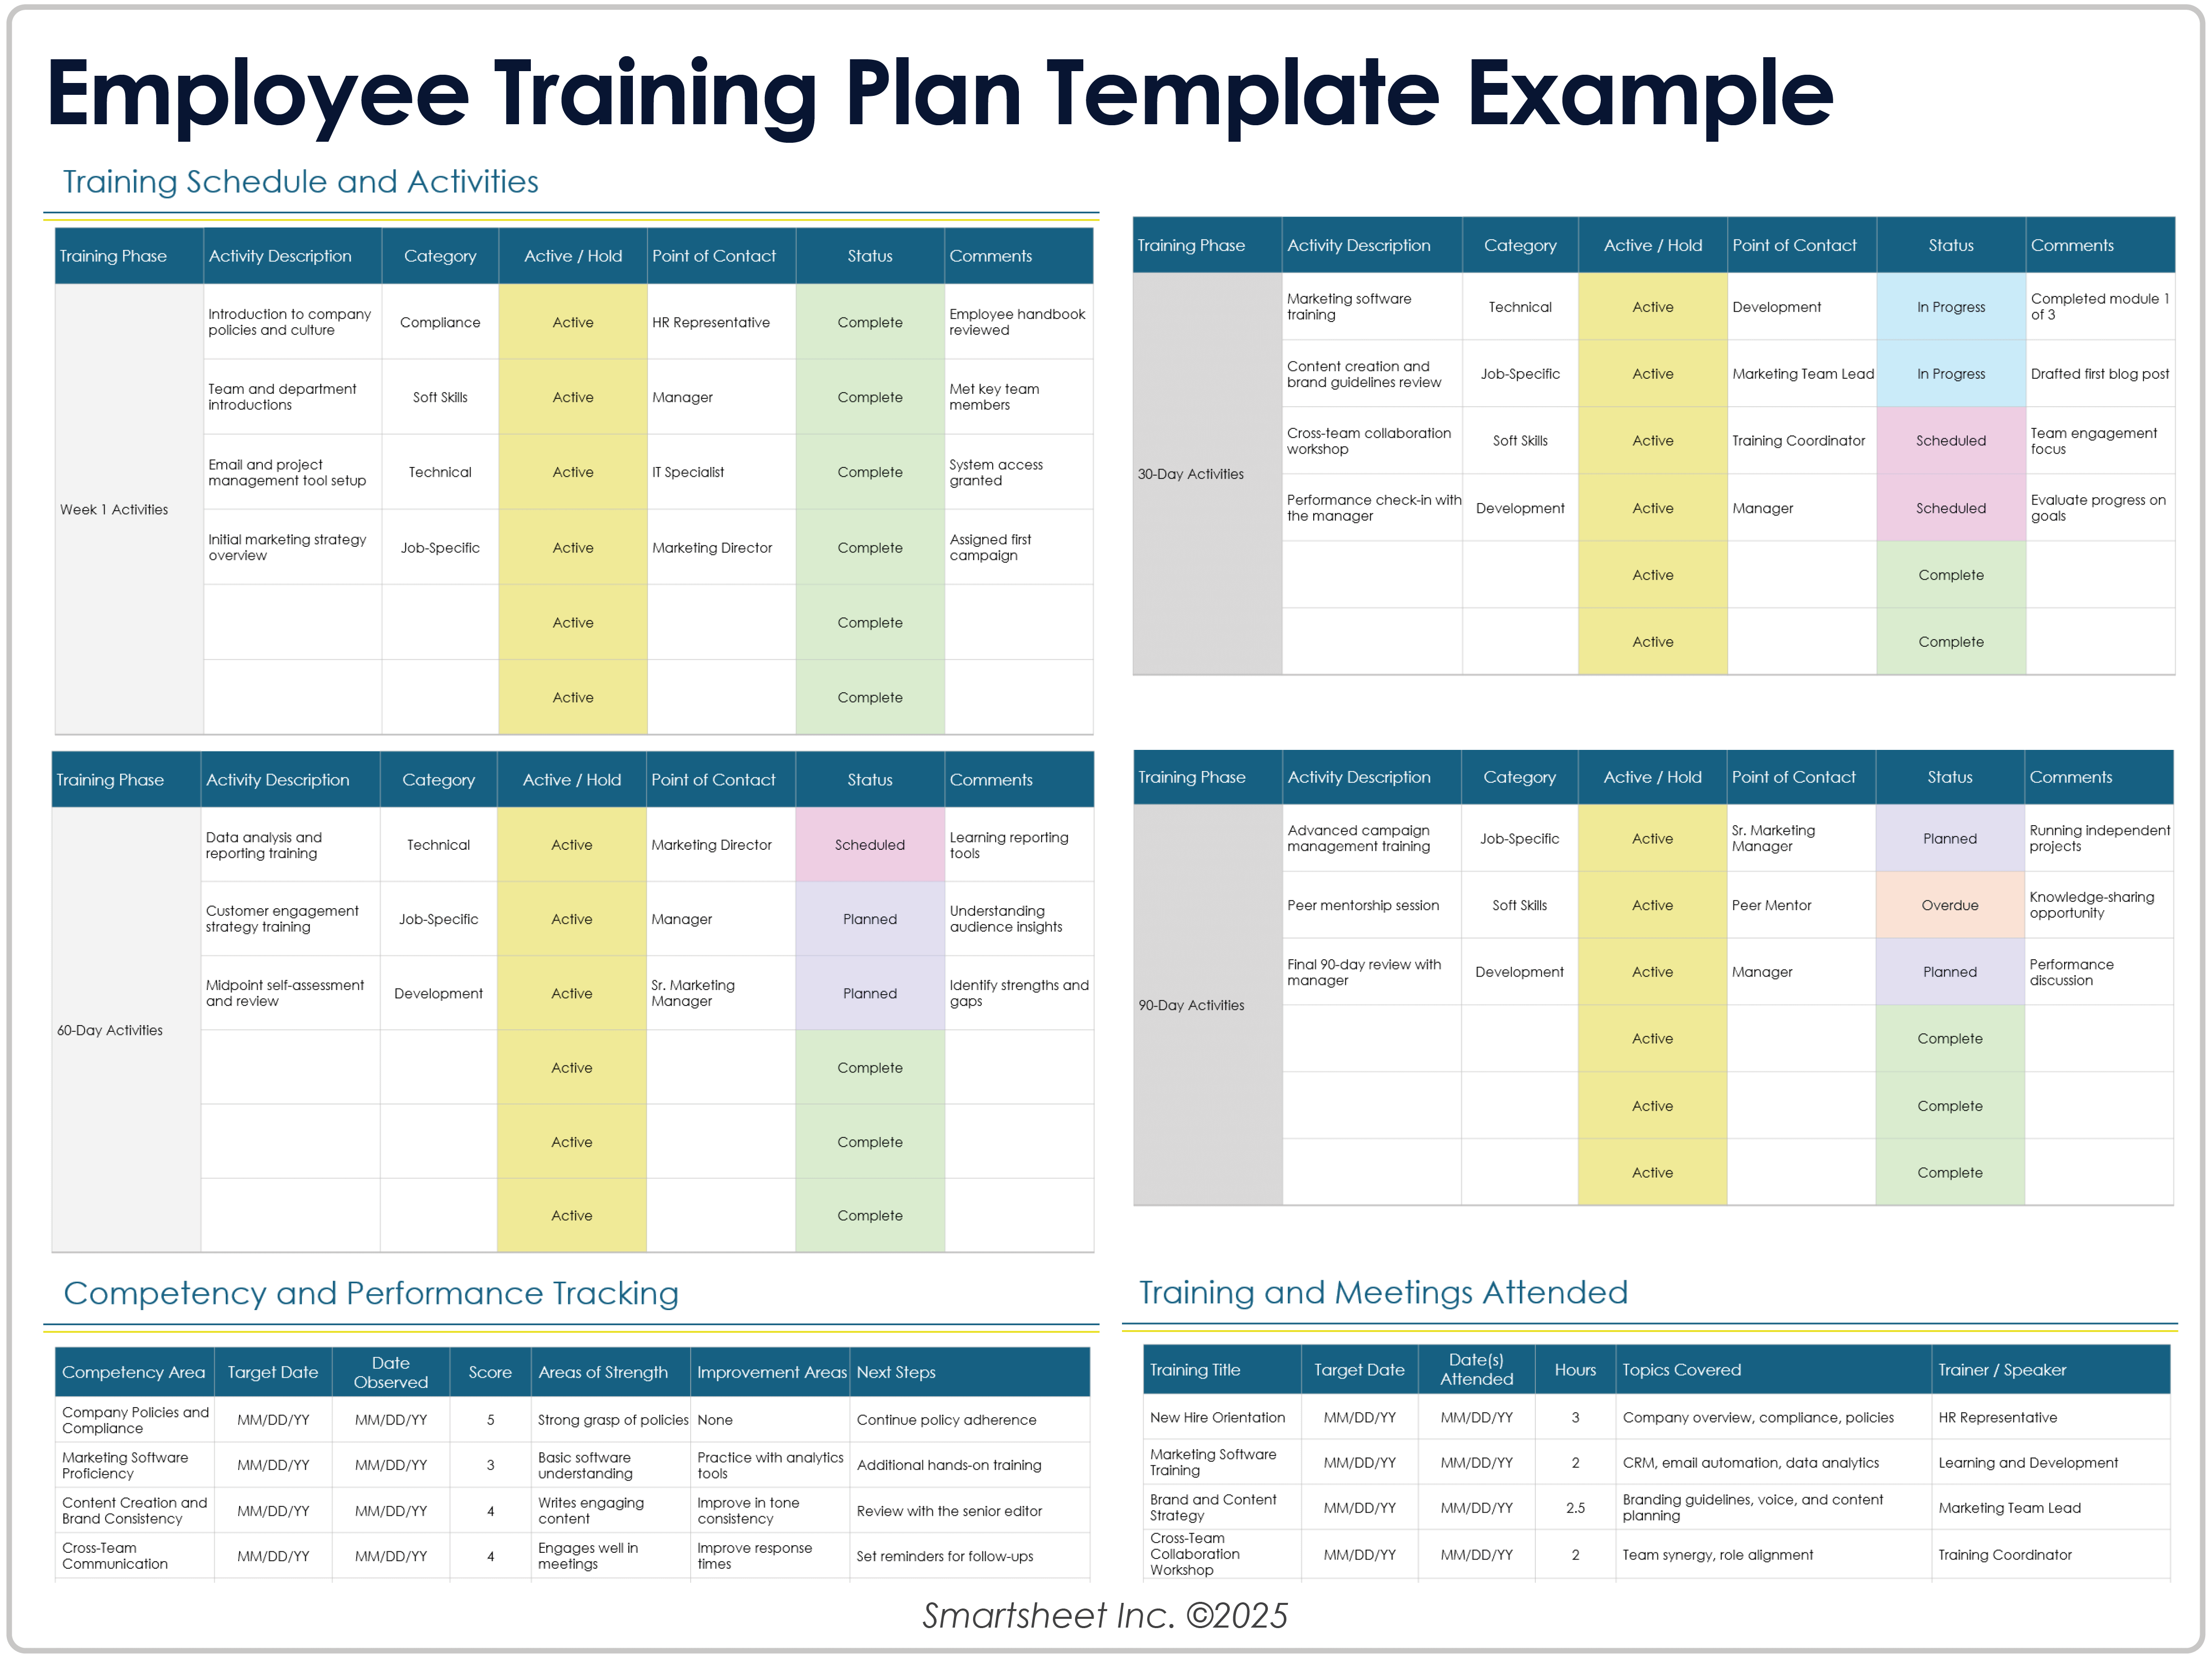
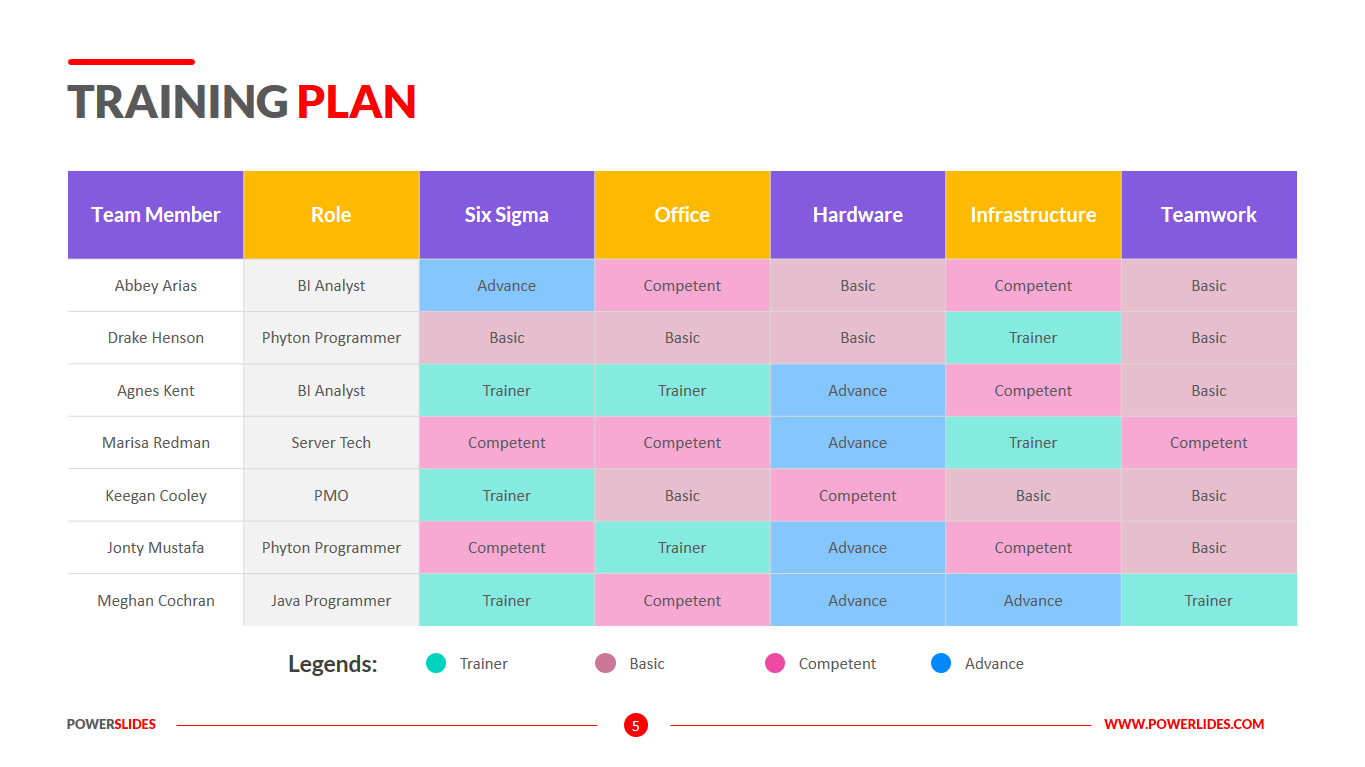
The most useful version I've built contains about twelve fields, no more. Anything beyond that tends to get abandoned because nobody wants to fill out a twelve-section form for every workshop request. Here's what actually matters: Objective — one sentence describing the measurable outcome. Not "employees will learn about cybersecurity" but "employees will identify phishing emails with at least 80% accuracy after completion." Specificity here prevents scope creep later. Target Audience — who this is for, broken down by role, not demographic. "All staff" is useless. "Junior developers and QA engineers who handle production code" tells you everything about how to design the content.
Duration and Format — hours of instruction, delivery method, and whether it's live, asynchronous, or hybrid. This field alone determines budget. A four-hour instructor-led workshop costs roughly eight times what a self-paced module does when you factor in facilitator time, room setup, and materials. Prerequisites — what participants need before showing up. Skipping this is the single most common mistake I see. I once watched a company run a Docker containerization workshop where half the attendees had never opened a terminal. The instructor spent the first two hours on basic command line navigation instead of the actual curriculum. Waste of everyone's time. Resources Needed — software licenses, room bookings, hardware, external trainers, reading materials. I learned to include a column for "cost per participant" because that number always surprises budget holders when they see it aggregated across a department.
Get the Full Details

Success Metrics — how you'll know it worked. Pre- and post-assessment scores, time-to-proficiency on the job, manager feedback surveys, certification pass rates. Pick one or two. Trying to measure five things means you'll measure zero things well. Revision History — a small table at the bottom tracking when the plan was created, last updated, and by whom. Corporate training materials rot faster than you'd think. I found a compliance training module last year that referenced a policy from 2019. The regulation had changed three times since. The template's revision log would have caught that immediately if someone had actually used it.
Training Plan Template for Machine Learning
The ML version lives in YAML or JSON files, usually checked into version control alongside your code. I store mine in a directory called configs/ with one file per experiment series. The key insight nobody tells you: the template should separate what you're training from how you're training it. That separation lets you swap a transformer for a random forest without rewriting your training loop. My templates contain these sections: model — architecture name, parameter count, and any architecture-specific hyperparameters. data — dataset paths, train/validation/test splits, augmentation pipelines, and preprocessing steps. training — optimizer choice, learning rate schedule, batch size, epochs, gradient clipping thresholds, mixed precision flags. evaluation — metrics to compute, validation frequency, early stopping criteria. output — experiment name, checkpoint directory, tensorboard logging path, artifact upload settings.
Here's a concrete example of what this looks like in practice: ```yaml experiment: name: sentiment-lstm-baseline seed: 42 model: type: lstm embedding_dim: 128 hidden_dim: 256 num_layers: 2 dropout: 0.3 data: train_path: data/train.csv val_path: data/val.csv max_seq_length: 256 vocab_size: 50000 augment: false training: optimizer: adam lr: 0.001 lr_schedule: cosine warmup_steps: 1000 batch_size: 64 epochs: 20 gradient_clip: 1.0 mixed_precision: true evaluation: metrics: [accuracy, f1_macro, roc_auc] val_frequency: 1 early_stop_patience: 5 best_model_metric: f1_macro output: checkpoint_dir: outputs/sentiment-lstm/checkpoints log_dir: outputs/sentiment-lstm/tensorboard save_top_k: 3 ``` This template cut my experiment setup time from roughly twenty minutes per run to about three. The biggest win isn't the time savings though. It's that I can now compare six different model configurations side by side because they all reference the same data pipeline and evaluation framework. Before I had this system, I'd forget which configuration had dropout at 0.2 versus 0.3 and spend hours trying to reproduce results.

How to Build and Maintain One
Start small. Your first template should be slightly incomplete. Add fields only when you encounter a situation where missing information caused a problem. I added the environment section to my ML templates after a colleague cloned my repo, ran the training script, and got CUDA errors because I'd never documented that the experiment required GPU driver version 535 or higher. That was a painful two-hour debugging session that could have been avoided with three lines in a config file. For corporate templates, distribute a blank version first and collect feedback after three people have tried using it. You'll learn things like "nobody reads the prerequisites section" or "the success metrics field is too vague to fill out honestly." Both of those require different fixes. The first needs a UI change — move prerequisites above the objective. The second needs a dropdown or predefined options rather than a free text field. Version your templates. Not just the training content they describe, but the template structure itself. When I changed my ML template to support multi-GPU training, the old configuration files still worked because I maintained backward compatibility in the loader, but I kept the old template format documented so nobody would try to use it for a new experiment and wonder why the distributed section was missing.
Common Pitfalls and What to Do Instead
Pitfall one: over-engineering the template. I've seen corporate training plans with forty fields and machine learning configs with nested dictionaries three levels deep. The result is the same — people stop filling it out completely. If a field takes more than ten seconds to complete, question whether it's necessary. Most of the time it isn't. Pitfall two: treating the template as a one-time document. Training plans need revision cycles. A corporate workshop plan should be updated after each delivery based on participant feedback and facilitator notes. An ML training config should be updated when you discover a better hyperparameter range or when the dataset changes. I keep a running changelog for mine. It's usually seven or eight lines per experiment series documenting what changed and why. Pitfall three: not sharing templates across teams. This creates duplicate effort and inconsistent standards. The marketing team's training plan format should not look completely different from engineering's. There's no reason for that. A shared template library with team-specific overrides works better. I suggested this at my last company and spent six weeks getting buy-in because everyone was attached to their own format. We ended up with a base template and optional extension sections. It works, but the politics were exhausting.
Pitfall four: using templates for situations they weren't designed for. I once saw someone use a corporate training plan template for a machine learning experiment and vice versa. The corporate template had no field for GPU requirements or dataset versioning. The ML template had no field for stakeholder sign-off or budget approval. Matching the template to the context matters more than the template itself.
When a Template Won't Help
Training Plan Templates fail in two specific scenarios. First, highly experimental work where the training approach is unknown. If you're doing novel architecture research and you're not sure whether you'll need gradient accumulation, mixed precision, or a custom data pipeline, a rigid template becomes a constraint rather than a help. In those cases, keep a minimal log file instead — just dates, what you tried, and what happened. The structure comes later when patterns emerge. Second, one-off training sessions with no possibility of reuse. If you're running a single compliance workshop next month and it will never be repeated, a template is overhead. Use a checklist. Checklists are templates stripped of everything except the actions you need to take. They're faster to create and just as effective for unique events. The bottom line is that a Training Plan Template is a tool, not a goal. It saves time when you run similar training operations repeatedly. It adds bureaucracy when you force it into situations that don't fit. Judge each one by whether it reduced the time between "I need to organize training" and "the training is running," not by how many fields it contains.