Getting a Model to Actually Learn Your Content
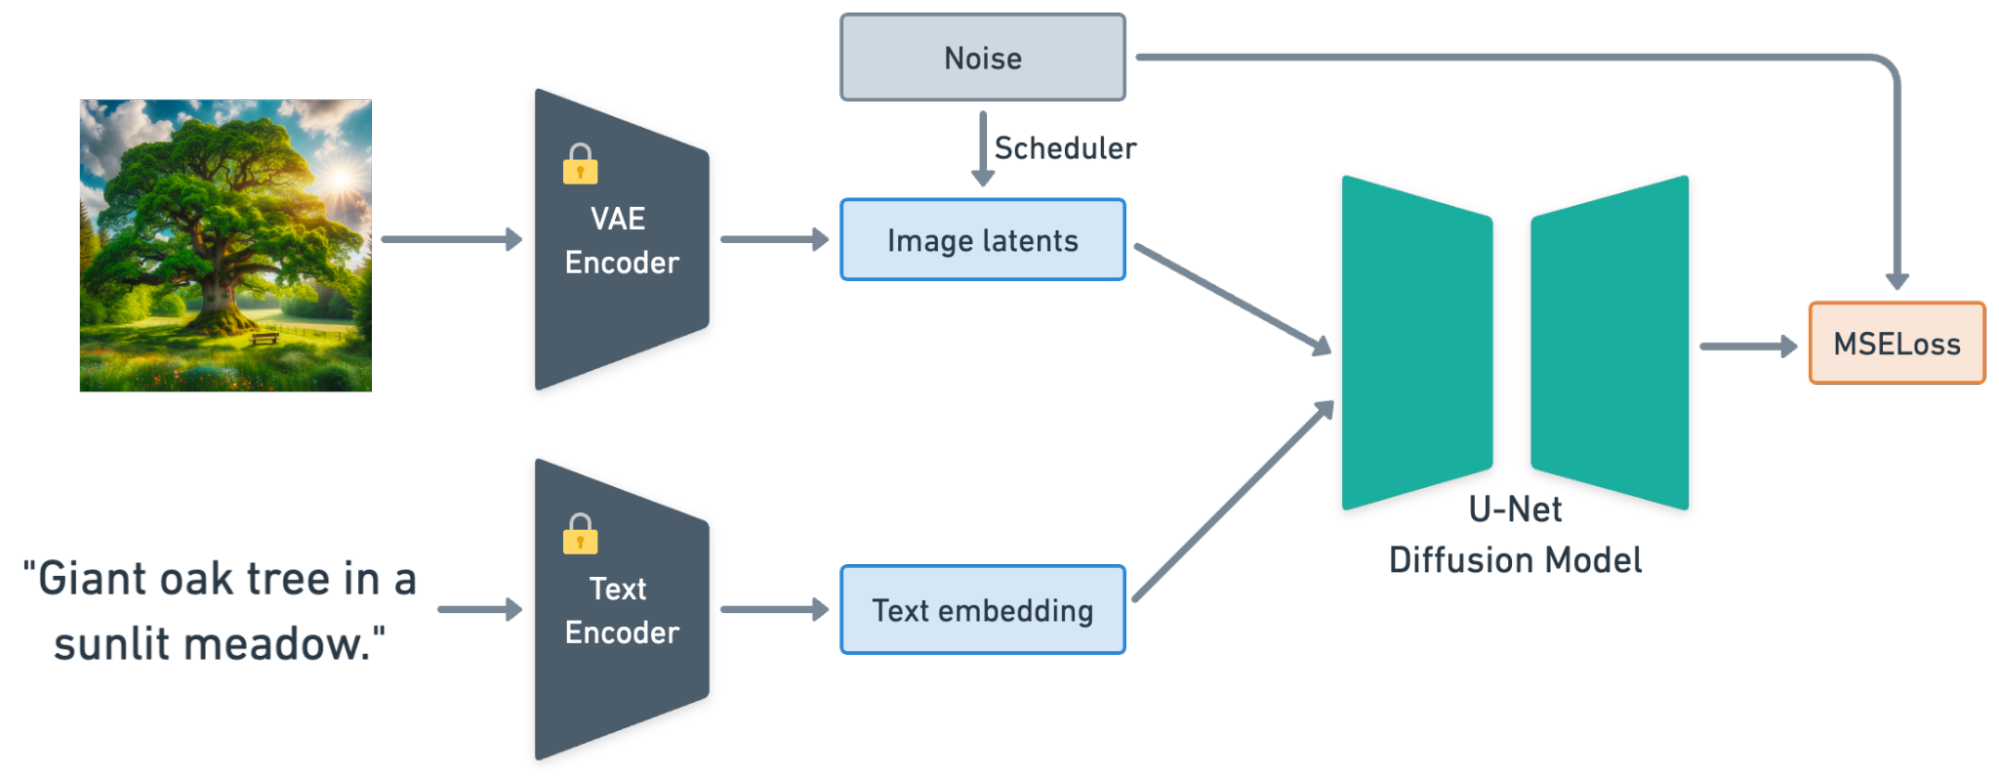
Training Stable Diffusion With Custom Images is one of those topics where every tutorial you find assumes you already know the pitfalls. I spent months working through this after my first dozen attempts produced garbage. The basics are straightforward in theory, but the execution has enough moving parts that most people hit a wall somewhere around epoch 15 and have no idea why their output looks like wet paint. You need a dataset, a training script, and a base model. That's the absolute minimum. In practice, you need roughly 15 to 30 images of whatever you're trying to teach the model, properly captioned. The captions matter more than almost anything else, which is the first thing nobody tells you. A model trained on images without captions learns the visual patterns but has no textual anchor. You'll get good images, but you won't be able to prompt for them reliably. I started with Kohya_ss because it's the most documented option, but if you're comfortable with Python and command line, llama-factory or diffusers from Hugging Face give you more control over the pipeline. The actual command structure varies depending on your setup, but the core components are always the same: base model path, dataset directory, output directory, network type, and training steps.
Network type is where people make their first mistake. LoRA is the standard choice for most use cases, and it should be. Full fine-tuning a SDXL model eats 80 gigabytes of VRAM and produces files so large they're impractical for daily use. LoRA trains a lightweight adapter on top of the base model. You get a file around 200 megabytes instead of 13 gigabytes, and it works in most interfaces without any special setup.
Dataset Preparation
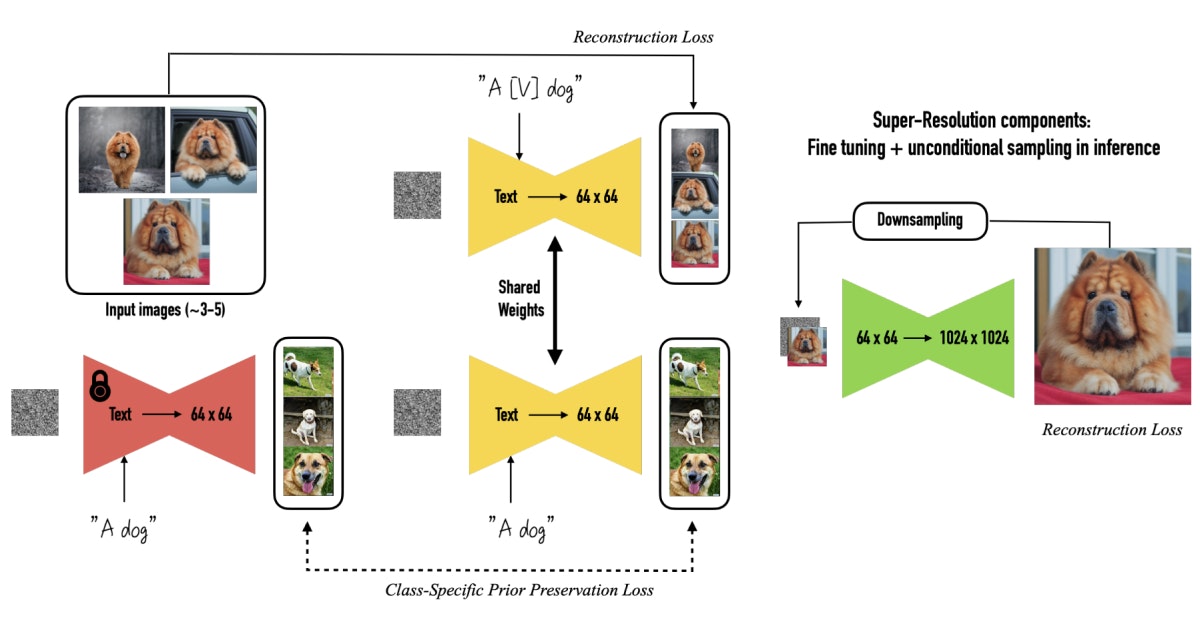
This is where most training jobs fail before they even start. Your images need to be consistent. Not in subject matter, but in resolution and quality. If you throw together 20 images at 512x512, 1024x768, and one at 1920x1080 because you grabbed them from different sources, the model gets confused about what resolution it should expect. Crop everything to the same aspect ratio. SDXL handles 1024x1024 fine. For SD 1.5, stick with 512x512 or 768x768. Square crops aren't mandatory, but they remove a variable. For captioning, use BLIP or WD14 Tagger as a starting point, then manually fix the obvious errors. These tools will describe background elements, watermarks, and junk you don't care about. They also miss key identifiers. I had a case where the tagger labeled a specific character reference as "anime girl drawing" across all 23 images. The model learned the generic aesthetic instead of the specific reference. You have to read every caption and remove the noise. Here's a detail that isn't widely discussed: caption one keyword per concept. If you're training a specific character, use a trigger word like "ohwx" or "skzr" consistently in every caption. This becomes your anchor. The model learns to associate that token with the visual concept you're teaching. Without it, you're just getting better at generating whatever random thing happens to be in the training images.
Get the Full Details
Training Parameters That Actually Matter
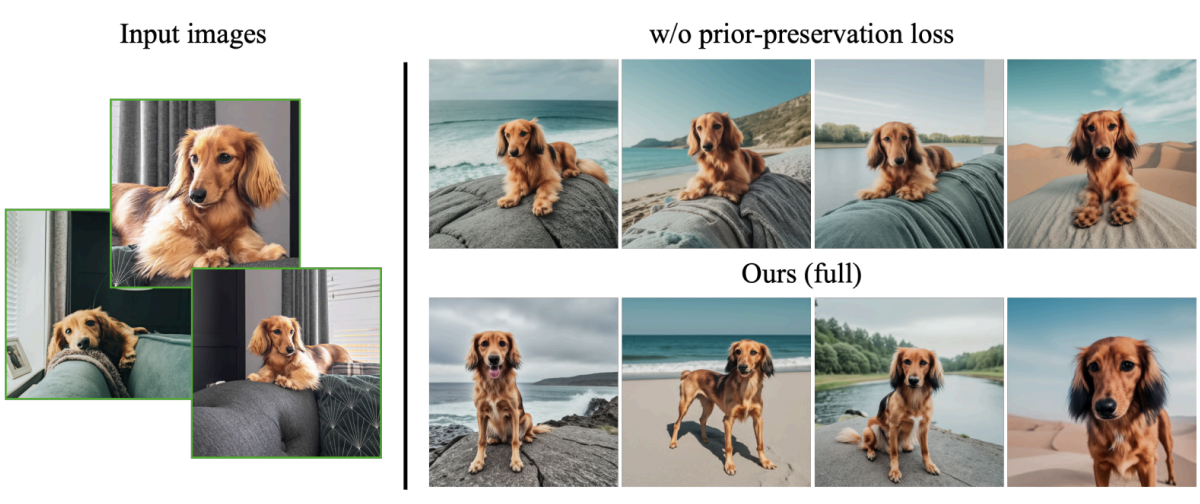
Learning rate is the most sensitive parameter. Start at 1e-4 for LoRA. Going higher causes immediate overfitting. Going lower makes training take three times longer with marginal quality gains. Batch size depends on your VRAM, but a batch size of 1 or 2 is standard for most consumer GPUs. Epoch count is where people waste time. Training for 10 epochs is almost always insufficient. 20 to 30 epochs is the sweet spot for a well-prepared dataset of 15 to 30 images. Beyond 40 epochs and you're memorizing, not learning. The validation images will start looking worse, not better. This is the single most common failure mode I see in people's work. Network dim and alpha are related settings that control the capacity of your LoRA. Dim 32 with alpha 16 is a solid default. Higher dim values give the model more room to learn complex features but require more training data to avoid overfitting. If you have fewer than 15 images, drop dim to 16 or even 8. It sounds counterintuitive, but a smaller network trains faster and generalizes better on small datasets.
A Problem I Hit and How I Fixed It
Midway through a training run for a specific illustration style, I noticed the model was generating excellent renders but completely ignoring the prompt modifiers. I'd type anything and get the same output. The model had learned the style but had no textual conditioning on it. I spent two days troubleshooting before I realized the captions were all identical. Every single image had the same descriptive text, so the model never learned to associate different words with different visual variations within the style. The fix was rewriting all 24 captions to include varied descriptors alongside the trigger word. Instead of repeating the same style description, I added different lighting conditions, poses, and composition notes to each caption. Retraining with the same parameters took the same amount of time but produced a model I could actually prompt. It's a subtle point, but it's the difference between a model that generates on demand and one that just makes pretty pictures randomly.
Validation During Training
Don't skip validation images. Set up 3 to 5 reference images in your training config and generate them at regular intervals. This is how you catch overfitting before it ruins your run. If the validation outputs at epoch 25 look identical to the training images, you're already overfitted. Stop there. Saving at epoch 15 would have given you better generalization. The trade-off is that more frequent validation saves time but slows each epoch. Checking every 50 steps versus every 200 steps makes a noticeable difference in total wall clock time on longer runs. I validate every 100 steps. It's a reasonable middle ground.
Limitations and When This Approach Fails
Training Stable Diffusion With Custom Images does not work well for photorealistic human faces unless you have a very large dataset. The model will generalize skin texture and lighting poorly with fewer than 50 images. It also struggles with complex anatomical consistency. You can train a model to produce a specific character, but it may not maintain correct hand anatomy or consistent facial features across different poses without an extremely large and varied dataset. Another hard limitation: style transfer models trained on a small dataset will collapse into a single aesthetic. If you train on 20 images of watercolor paintings, you're not building a tool that generates watercolor images in different styles. You're building a tool that generates those exact 20 images with minor variations. This is fine if that's what you want, but it's not what most people expect when they start. If you need photorealistic faces or highly variable outputs, consider alternative approaches like ControlNet fine-tuning or using an existing checkpoint as a stronger starting point rather than training from scratch.
Where to Get the Tools
Kohya_ss is available on GitHub under Kayowoo's repository. The diffusers library from Hugging Face includes training examples in their documentation. Both are free. There's no paid software required to train your own models, though the hardware cost is the real barrier. An RTX 3090 with 24 gigabytes of VRAM handles most LoRA training comfortably. Anything less requires careful optimization and longer training times. The community resources are decent but scattered. The Stable Diffusion Discord and the Kohya_ss documentation cover most common questions, but the deeper issues like caption strategy and overfitting detection aren't well documented anywhere. You figure those out by breaking things repeatedly.