Getting Transformers Working Without Losing Your Mind
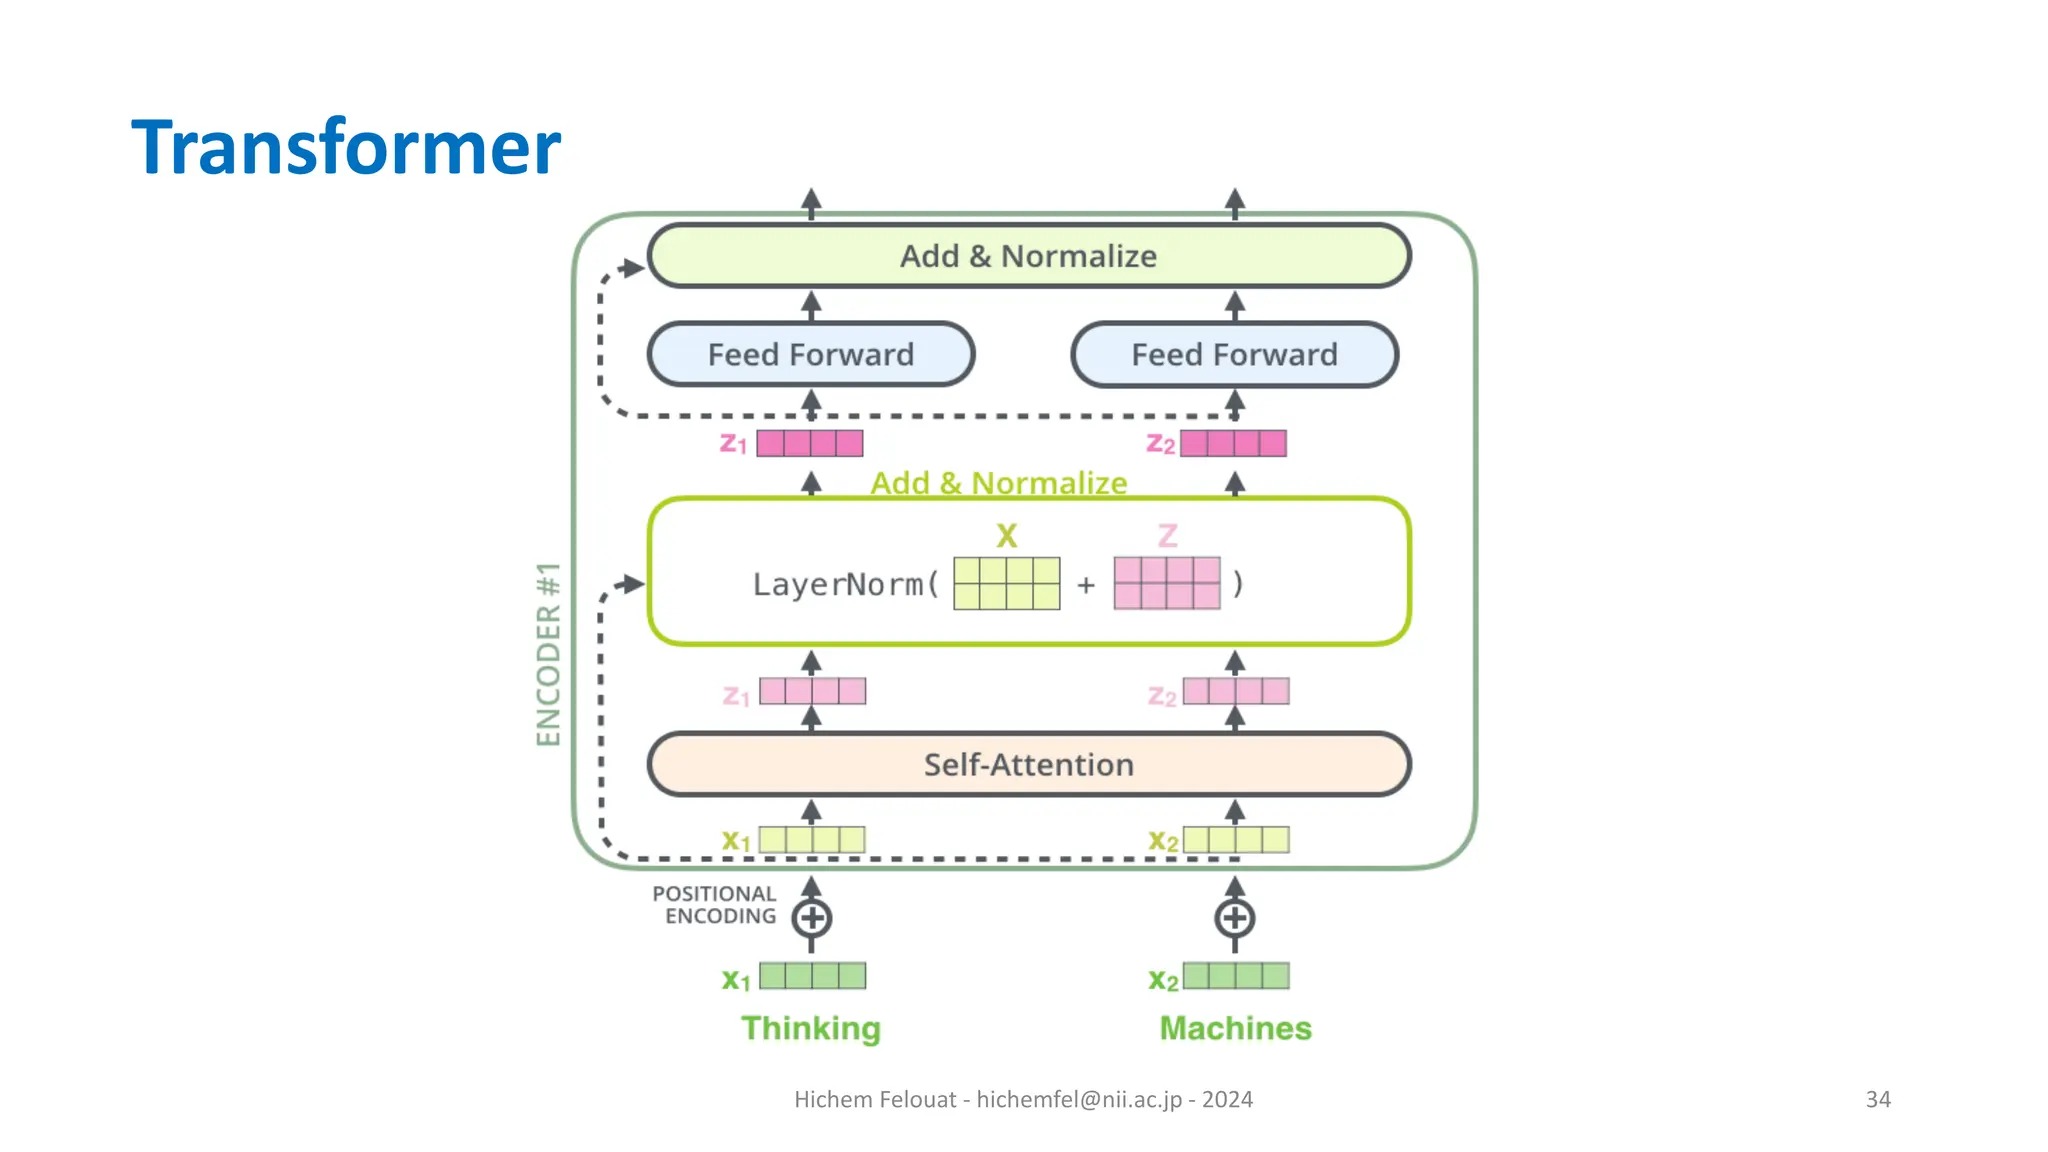
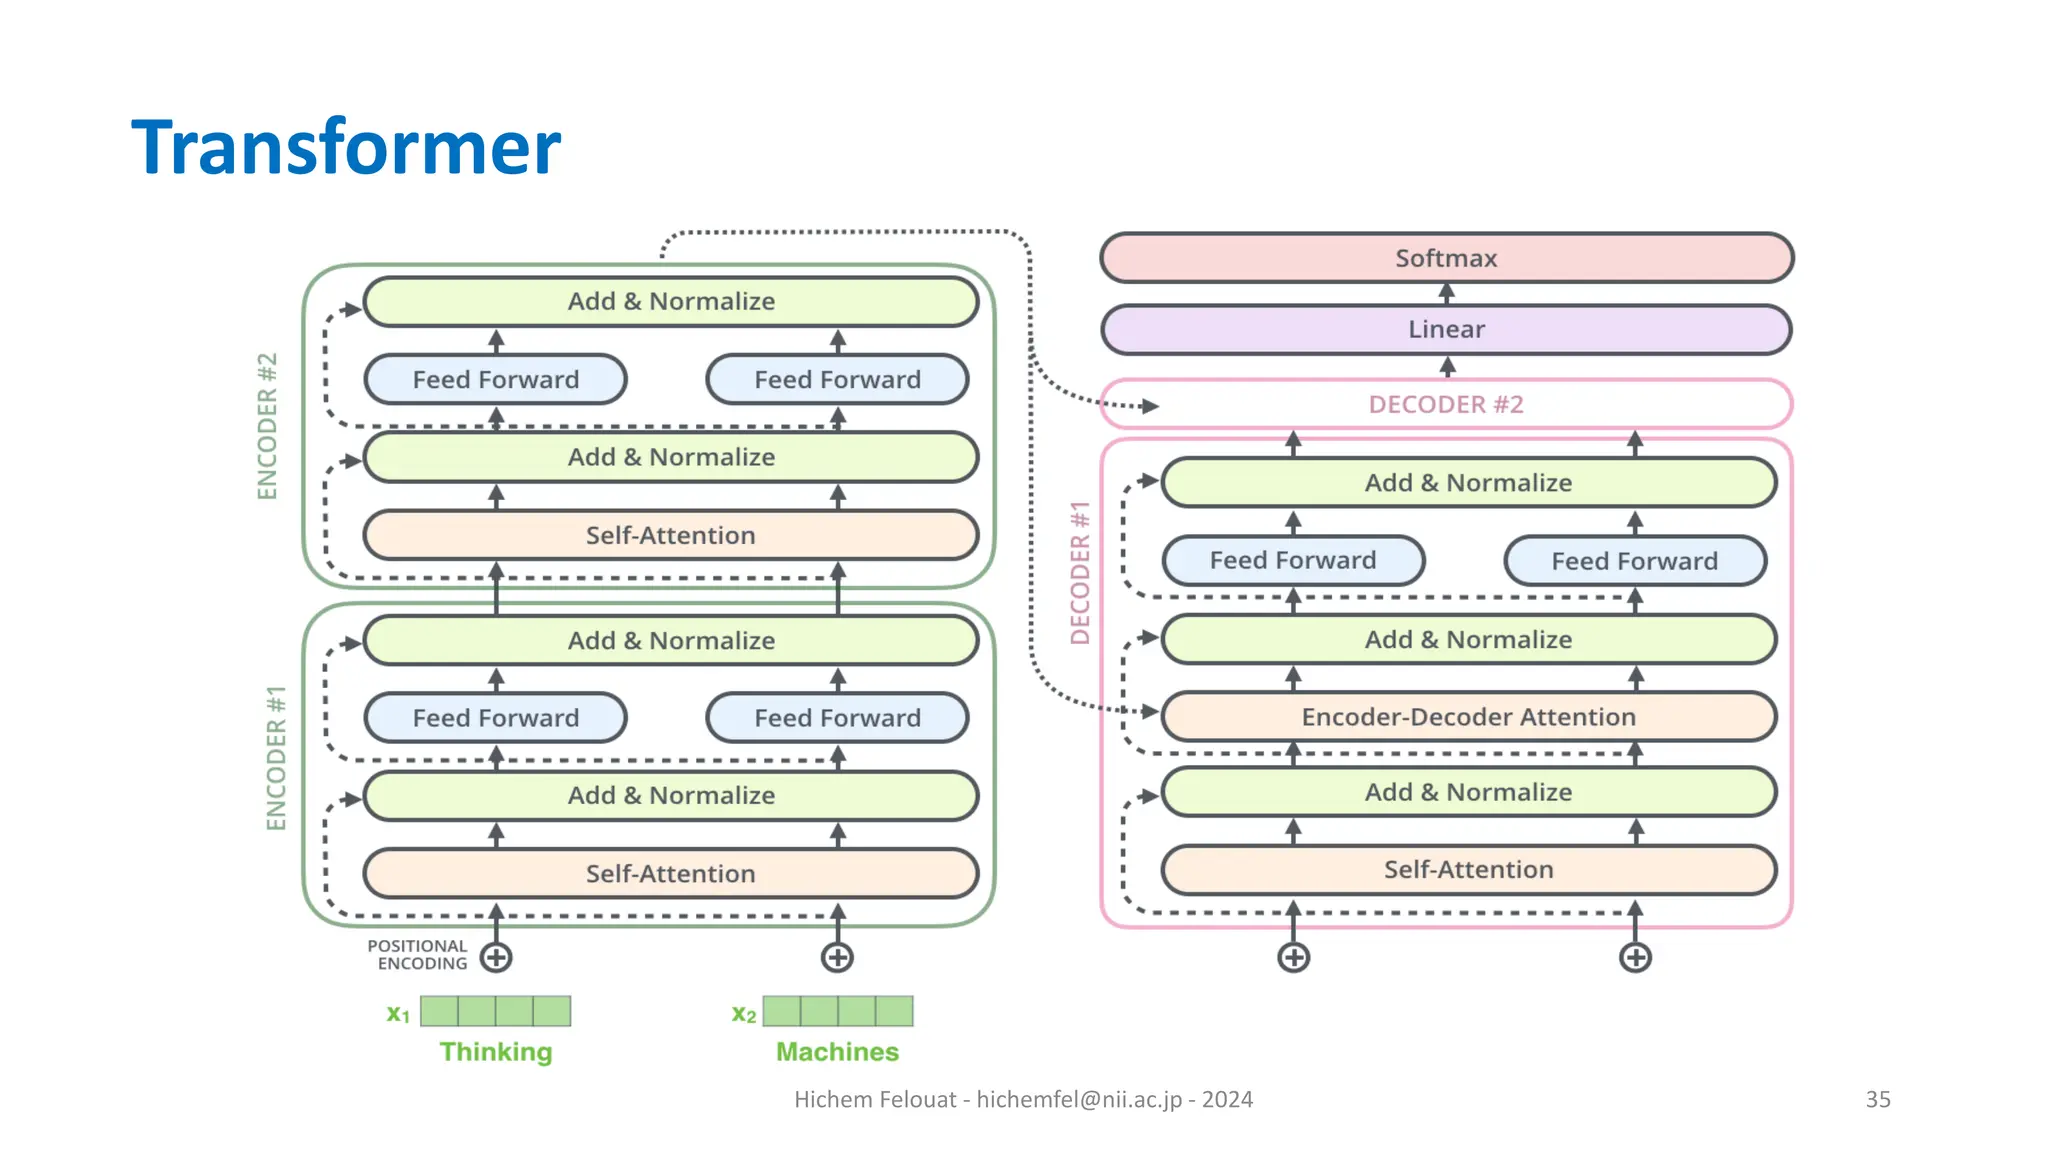
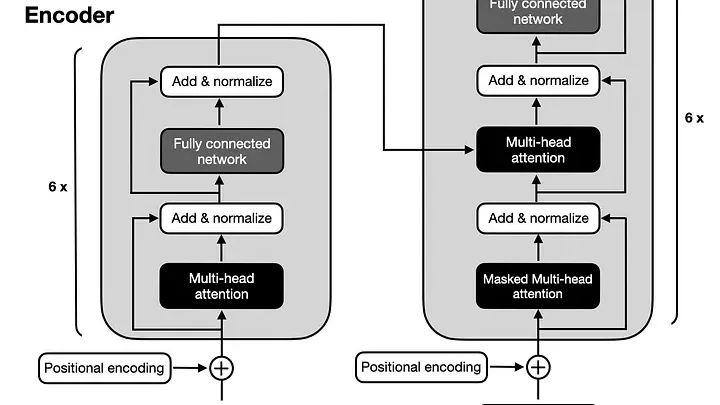
The transformer architecture took over natural language processing around 2018 with the original paper, and the ecosystem has been expanding ever since. The Hugging Face transformers library is what most people actually use to interact with these models. It abstracts away a lot of the underlying math so you can load a pre-trained model and run inference in roughly a dozen lines of code. That convenience comes with tradeoffs, which I will get to later. A transformer processes text through self-attention mechanisms. Instead of reading sequentially like older recurrent models, it computes relationships between every token in a sequence simultaneously. The attention score between two tokens tells you how much information should flow from one to the other when generating a representation. Multi-head attention runs several of these calculations in parallel, each head learning different types of relationships. Feed-forward networks then process each position independently after the attention layer has done its work. Positional encoding is critical here because the architecture itself has no notion of order. Without injecting position information, a sentence like "the cat chased the dog" would be treated the same as "the dog chased the cat." Early implementations used sinusoidal functions, but most modern models like BERT and GPT embed positions as learned parameters instead.
A Practical Walkthrough Using the Transformers Library
Here is how I actually set up a working pipeline for text classification. Start by installing the library and the necessary dependencies, ideally inside a virtual environment since the dependency tree pulls in quite a bit. The transformers package itself is around 30 megabytes, but PyTorch or TensorFlow add another couple of gigabytes on top. pip install transformers torch From there, loading a model and running inference looks something like this:
from transformers import pipeline classifier = pipeline("sentiment-analysis", model="distilbert-base-uncased-finetuned-sst-2-english") result = classifier("I actually found this approach useful despite the hype") print(result) That outputs something like [{"label": "POSITIVE", "score": 0.9947}]. The pipeline helper handles tokenization, model loading, and output formatting automatically. Under the hood it instantiates a DistilBERT model, applies the special tokens, converts your input to tensor format, runs it through the network, and applies the softmax to the final hidden state. For tasks that the pipeline does not cover directly, you work with the tokenizer and model classes separately. Tokenization in transformers is not simple whitespace splitting. These models use subword tokenization, typically Byte-Pair Encoding or WordPiece, which breaks uncommon words into meaningful fragments. "Unfamiliar" might become ["un", "familiar"] or ["un", "fam", "iliar"] depending on the vocabulary. This matters because it affects your sequence length limits and memory usage.
Get the Full Details
Working With Transformers Natural Language Processing at Scale
Batch processing introduces complications that tutorial posts rarely mention. When you pad sequences to the same length within a batch, shorter sequences consume GPU memory proportional to the longest sequence in that batch. A batch of ten documents where nine are short and one is long wastes most of that compute cycle. The solution is dynamic padding, which groups sequences by length before batching. The transformers library supports this through the DataCollatorWithPadding class, but it adds overhead that is not negligible on CPU-only setups. I ran into a specific problem last year while fine-tuning a model on a medical question-answering dataset. The model kept producing garbled outputs when the input exceeded 256 tokens. I had set max_length=512 in my tokenizer call, but the model's positional embedding was sized for 512 tokens and the training data mostly contained much shorter sequences. When longer inputs appeared during inference, the attention patterns degraded because the model had never learned to handle those distances during training. The fix was to use a sliding window approach where I split long documents into overlapping chunks and aggregated the predictions, combined with adjusting the model's positional interpolation strategy. RoPE-based models like Llama handle longer contexts more gracefully through techniques like NTK-aware interpolation, but BERT-style models do not have that option built in. This is one of those things that is not obvious from the documentation. The max_length parameter controls tokenization, not the model's actual context window. Those are two different constraints that need to be aligned manually.
Model Selection Strategies
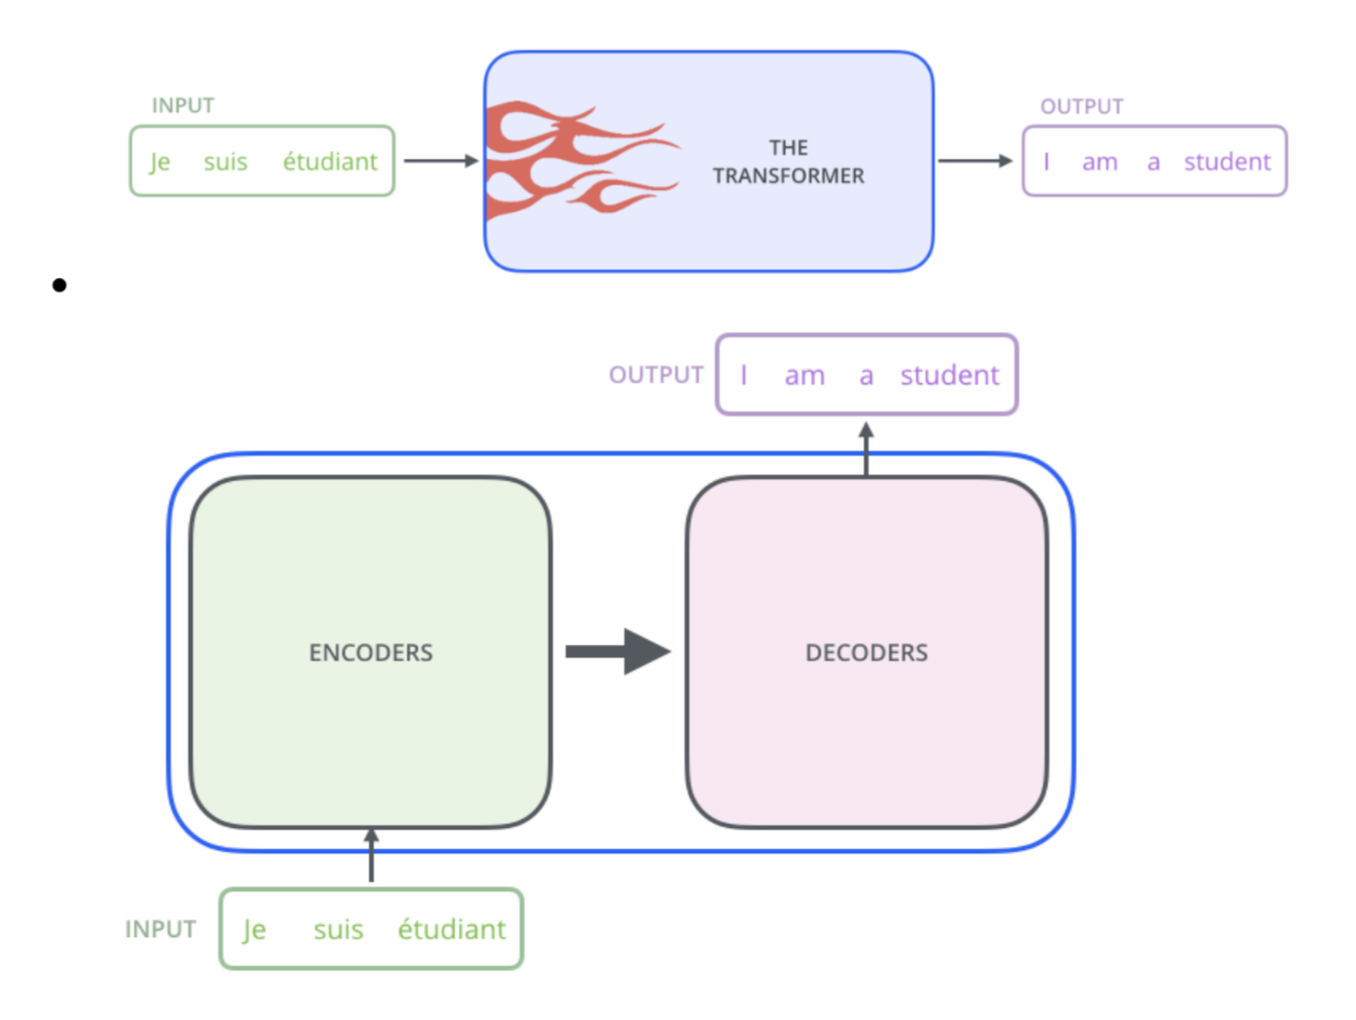
Choosing a model depends entirely on your task and constraints. For general-purpose text classification, DistilBERT is a reasonable default. It is roughly half the size of BERT-base with minimal accuracy loss on most benchmarks. For generation tasks, the T5 and BART families handle sequence-to-sequence work like summarization and translation. For question answering, models fine-tuned on SQuAD like the BERT variants perform well on extractive QA where the answer is a span of the original text. The Model Hub on Hugging Face hosts thousands of community models. Not all of them are what you would call production-ready. I have seen models with incorrect tokenizer configurations, models trained on data that completely mismatched their stated purpose, and models that simply failed to converge. Always check the evaluation metrics reported in the model card, not just the accuracy number. A model claiming 95% accuracy on an imbalanced dataset where 90% of samples belong to one class is essentially useless.
Common Pitfalls That Waste Time
The tokenizer and model must come from the same family. Using a BERT tokenizer with a RoBERTa model will produce incorrect results because they tokenize differently. RoBERTa removes the [CLS] token convention and uses different special tokens. This is a frequent source of confusion when people mix and match components from different models. Another issue is CUDA memory management. If you are running on GPU, forgetting to move tensors to the correct device is the most common error. The pipeline helper handles this automatically, but manual implementations require explicit device placement. Model loading itself can consume 2 to 4 gigabytes of VRAM for base-sized models. Larger models like GPT-NeoX-20B require significantly more and may need quantization or offloading to work on consumer hardware. Quantization reduces model size and memory usage at the cost of some accuracy. The transformers library supports bitsandbytes integration for 4-bit and 8-bit quantization. Loading a model in 4-bit mode typically cuts VRAM usage by roughly 60 percent with a 1 to 3 percent accuracy drop on most tasks. This is usually worth the tradeoff if you are running inference on limited hardware.
Fine-Tuning Considerations
Fine-tuning a transformer model from scratch requires substantially more resources and time than most beginners expect. A typical BERT fine-tuning job on a single GPU takes anywhere from 20 minutes to several hours depending on dataset size and batch configuration. The learning rate is the most critical hyperparameter. Values between 2e-5 and 5e-5 work for most cases. Using a learning rate that is too high will cause the pretrained weights to diverge from their useful representations within a few steps, which is sometimes called catastrophic forgetting. Learning rate schedulers matter significantly. A linear decay schedule with a warmup phase is standard practice. The warmup period, typically 10 percent of total training steps, gradually increases the learning rate before the decay phase begins. Skipping warmup often results in unstable training during early epochs. For small datasets under 1,000 examples, full fine-tuning is usually overkill. Parameter-efficient fine-tuning methods like LoRA (Low-Rank Adaptation) modify only a small subset of the model's parameters while keeping the pretrained weights frozen. LoRA typically reduces trainable parameters by 99 percent and can achieve performance competitive with full fine-tuning on many tasks. The PEFT library by Hugging Face makes this straightforward to implement.
Deployment Realities
Serving a transformer model in production is where the practical challenges become apparent. Inference latency for a single classification with DistilBERT on a GPU is roughly 5 to 15 milliseconds. On CPU it increases to 50 to 200 milliseconds depending on sequence length. Batch inference improves throughput significantly but introduces latency variability because the batch size determines processing time. Framework choice affects performance. TorchScript and ONNX export can improve inference speed by 20 to 40 percent compared to eager execution. TensorRT provides further optimizations for NVIDIA GPUs but requires rebuilding your model in a different computation graph format. For serving at scale, specialized inference servers like vLLM or TGI (Text Generation Inference) manage batching, KV-cache optimization, and request scheduling more efficiently than a custom Flask or FastAPI wrapper. Transformers Natural Language Processing has made impressive progress, but it is not a silver bullet. The models require substantial computational resources, they struggle with out-of-distribution inputs, and they can produce confident but incorrect outputs without any internal warning signal. For applications where accuracy is critical, combining a transformer-based system with rule-based fallbacks or smaller specialized models for edge cases is usually the right approach rather than relying solely on a large language model.
The library continues to evolve rapidly. New architectures, training techniques, and optimization methods appear regularly. Staying current means monitoring the papers page and the release notes rather than assuming a method that worked six months ago is still optimal.