Working with Transition States in Practice
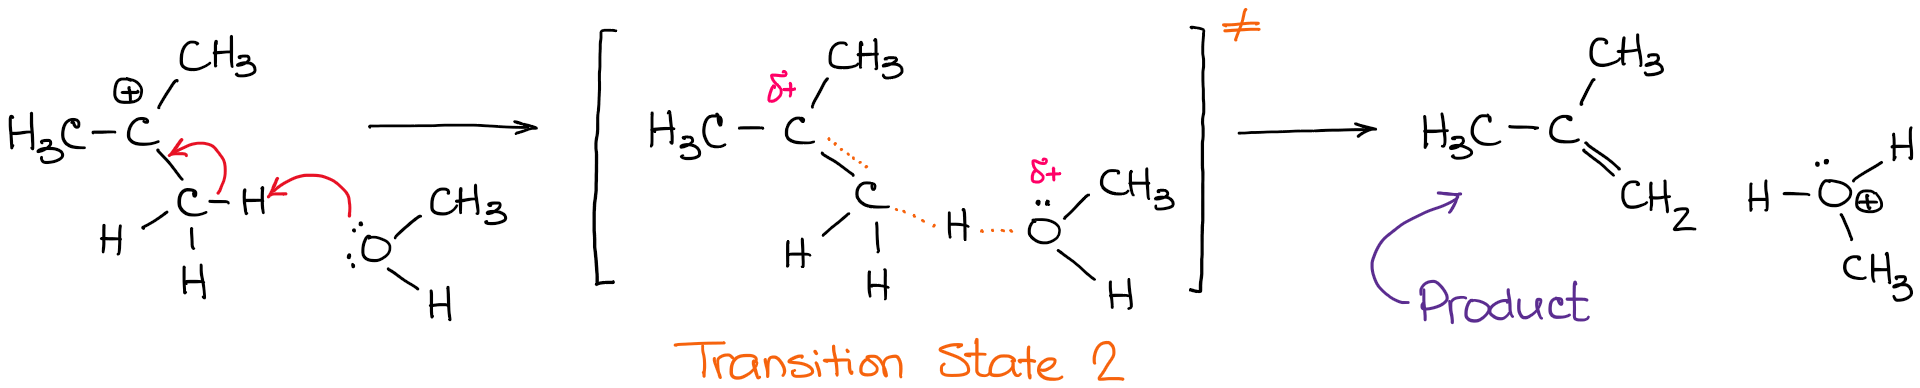
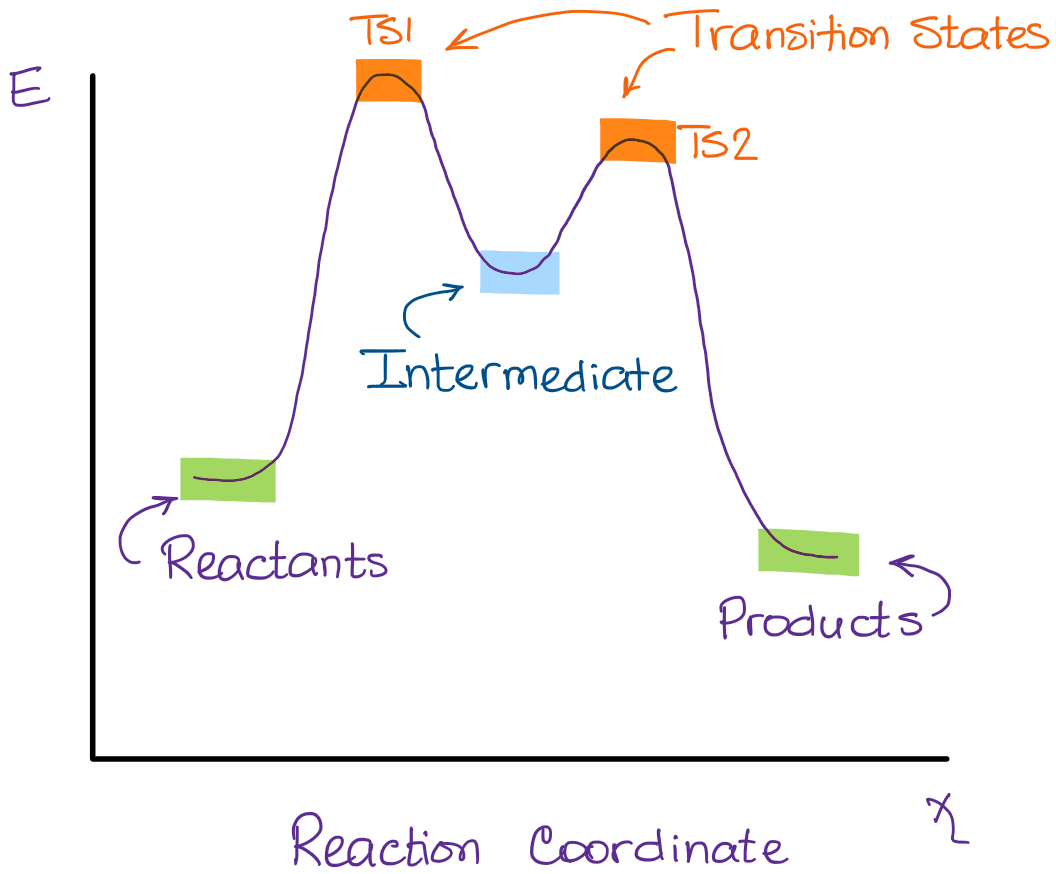
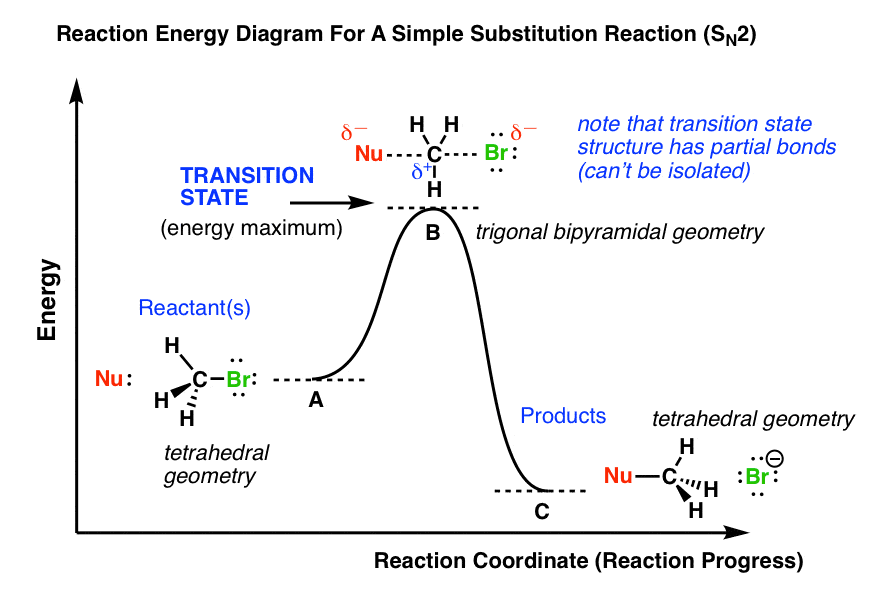
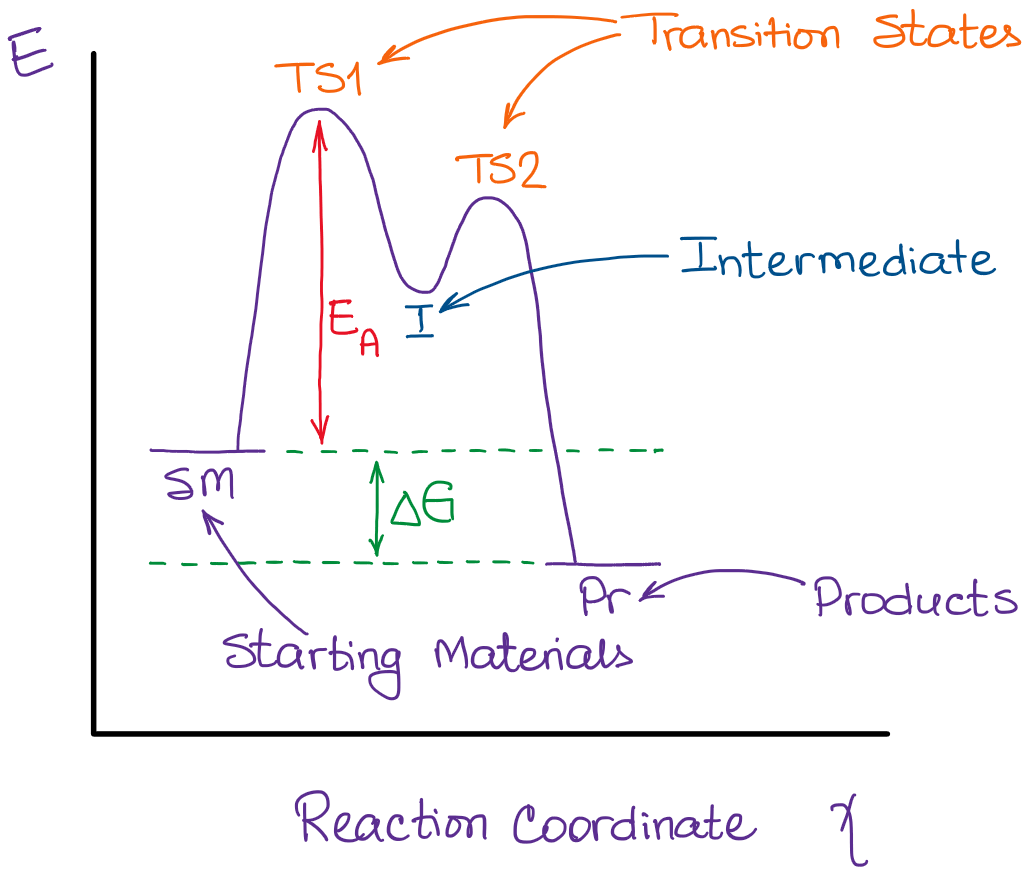
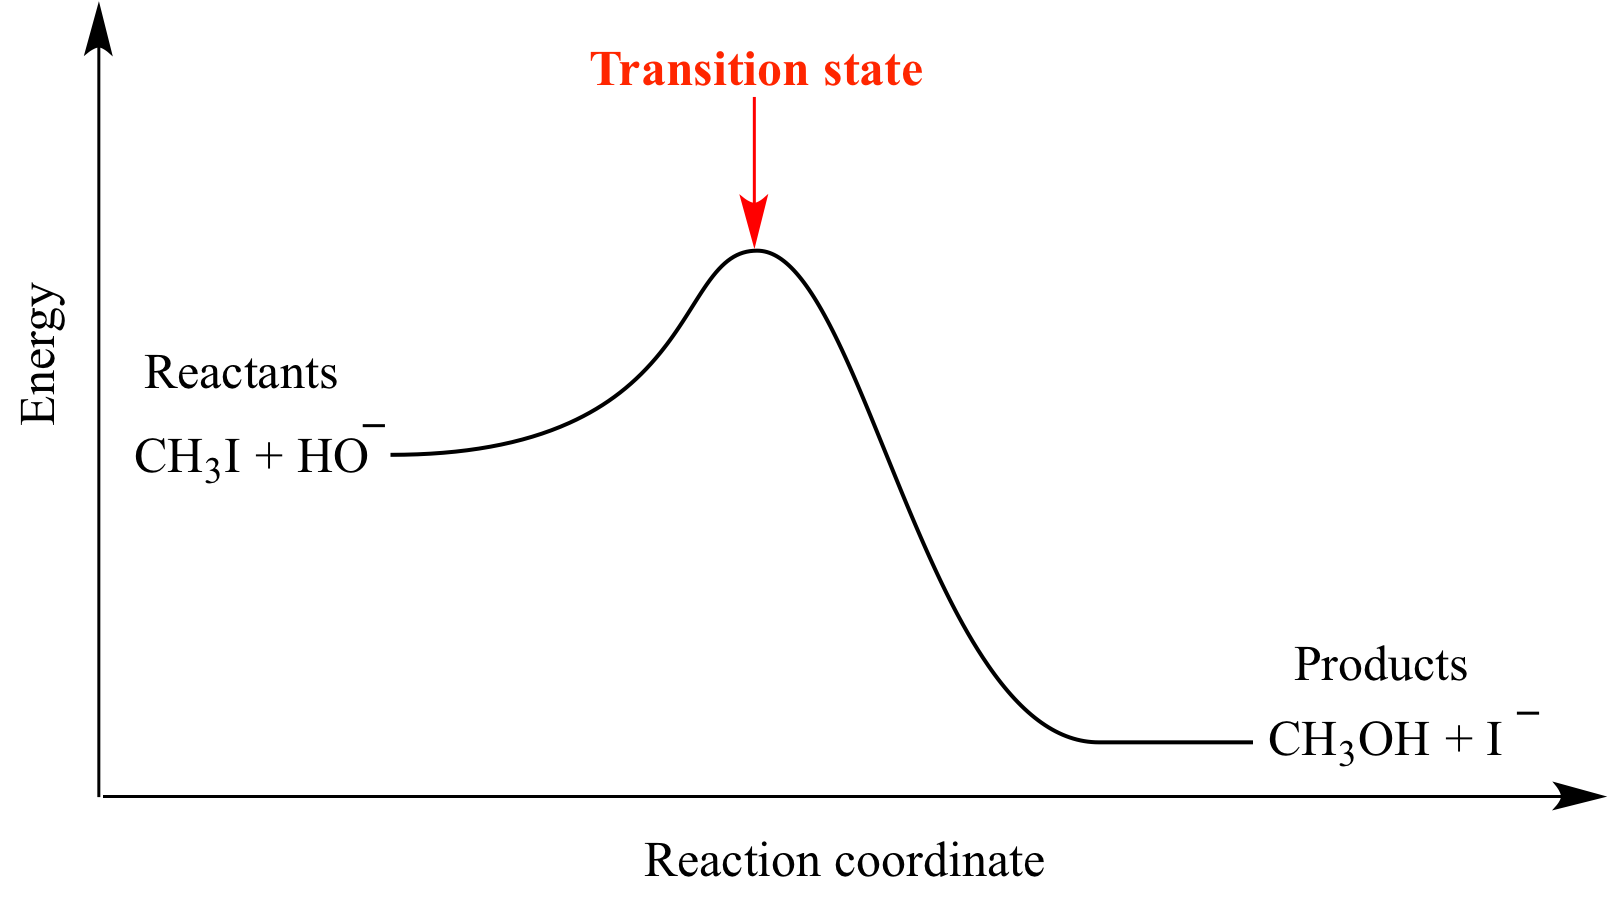
Most people learn about transition states in undergrad organic chemistry and then never touch them again until they need to figure out why a reaction they set up didn't go the way the literature predicted. That moment is when you actually need to understand Transition State Organic Chemistry properly, not just draw a wavy arrow and move on. The theory is straightforward. The practice is where things get annoying. A transition state is the highest energy point along a reaction coordinate. That's it. It's not a real intermediate you can isolate. It's a saddle point on the potential energy surface. In computational terms, that means one imaginary frequency when you do a geometry optimization. Everything else is real vibrations. If your TS calculation gives you two or more imaginary frequencies, you haven't found a transition state. You've found some random high-energy geometry that the optimizer stumbled into. The standard workflow for finding a transition state goes like this. You build a reasonable guess at the geometry of the TS. This might come from knowing the reaction mechanism, from intrinsic reaction coordinate calculations backwards from products or reactants, or from a relaxed scan where you slowly push the breaking bond length toward the expected TS value. Then you run a TS optimization using either the Berny algorithm or the eigenvector-following method. You verify the result with a frequency calculation. You confirm exactly one imaginary frequency. You then run an IRC calculation in both directions to make sure the TS actually connects the reactants and products you care about.
That's the textbook version. Here is what actually happens when you sit down to do this. Your initial guess will be wrong about ninety percent of the time. The optimizer will either converge to a different stationary point, diverge completely, or give you a geometry that looks reasonable but fails the frequency test. This is normal. The workaround is to generate multiple initial guesses by slightly perturbing bond lengths and angles around your best chemical intuition, then running optimizations in parallel. I typically generate twelve to sixteen guess structures for each TS I need to find. It usually takes one or two of them to converge properly.
Common pitfalls that waste days
The biggest mistake beginners make is assuming that a transition state geometry from a cheap method like PM6 or even HF will transfer well to a higher level calculation. It doesn't. The qualitative shape might be correct, but the bond lengths and angles can be off enough that the TS optimizer at DFT level starts from a geometry that is already too far from the true saddle point. Use at least B3LYP or M06-2X with a medium basis set like 6-31G(d) for the initial search. Don't bother with dispersion corrections during the search phase. Add them only when you're computing the final energy. Another issue that comes up constantly: solvent effects. Gas phase transition states are easy to find. Once you add a solvent model like SMD or CPCM, the energy landscape changes shape. What was a clean TS in the gas phase can become a shallow region with no clear saddle point. I ran into this specifically with a nucleophilic aromatic substitution reaction in methanol. The gas phase TS was trivial to locate. The methanol calculation gave me two competing geometries that were within four kcal/mol and neither had a clean single imaginary frequency. What I ended up doing was running a conformational search around the TS region using a systematic rotor scan, then reoptimizing each conformer with the solvent model. One of them had the correct single imaginary frequency and matched the IRC path. The others were just artifacts of the solvent model sampling a flat region. Don't skip the IRC verification. I've lost count of how many times I've seen someone publish a TS structure without checking whether it actually connects to the right reactants and products. A TS can converge mathematically but connect to completely different species than what you intended. Run the IRC. It takes maybe ten to fifteen minutes on a modern workstation for a typical organic reaction. Skipping it is irresponsible.
Get the Full Details
When transition state calculations fail entirely
Some reactions simply don't have a well-defined transition state in the traditional sense. Diffuse reactions, barrierless processes, and certain radical recombinations just don't form a saddle point. If your optimizer keeps failing no matter what you try, step back and check the reaction coordinate. Try plotting the energy as a function of the key geometric parameter. If there's no barrier, there's no TS to find. This happens more often than people expect, especially with SN2 reactions in highly polar solvents where the barrier can drop to nearly zero, or with certain pericyclic reactions where the surface is very flat near the top. For those cases, you're better off using variational transition state theory or just modeling the reaction as a barrierless process. The standard TS search algorithm is the wrong tool. There's no shame in recognizing that and switching methods. It saves weeks of fruitless optimization attempts.
Energy accuracy matters more than geometry accuracy
Your transition state geometry from a standard DFT calculation is usually good enough for qualitative analysis. The barrier height is where the real errors live. Single-point energy calculations at a higher level like DLPNO-CCSD(T) or at least a larger basis set with good treatment of dispersion will change your barrier by several kcal/mol compared to a raw B3LYP/6-31G(d) result. For kinetic isotope effect predictions, which depend exponentially on the barrier, that difference is everything. A two kcal/mol error translates to roughly a tenfold error in rate at room temperature. I use a two-step approach now that I've settled on. First, find the TS at B3LYP-D3(BJ)/def2-SVP with implicit solvent. Verify with IRC. Then run single-point energies at wB97X-V/def2-TZVP with SMD and, for critical cases, a DLPNO-CCSD(T) single point on top of that. This gives me barriers accurate to within about one kcal/mol for most organic reactions, which is good enough for deciding whether a proposed mechanism is plausible. It usually takes me about forty-five minutes to an hour per reaction on a standard lab workstation.
On using Transition State Organic Chemistry tools
If you're just starting out and want something that handles the workflow automatically, Gaussian with its built-in TS search and IRC capabilities covers most standard cases. ORCA is faster and free for academic use, though its TS algorithms can be finicky with certain systems. For very large systems or high-throughput screening, Semiempirical methods like GFN2-xTB followed by DFT refinement give decent results and are dramatically cheaper. A typical semiempirical TS search takes seconds rather than hours, which makes generating multiple conformers and reaction pathways practical. The software itself is widely available through your university's compute resources or directly from the vendors. Gaussian is commercial with a ~$10,000 annual license. ORCA is free for non-commercial academic use at orca.spoc.moe. GAMESS and NWChem are fully open source. If you're doing this work regularly, pick one and learn it well. The interface differences between programs are minor compared to the chemistry decisions you'll actually need to make.