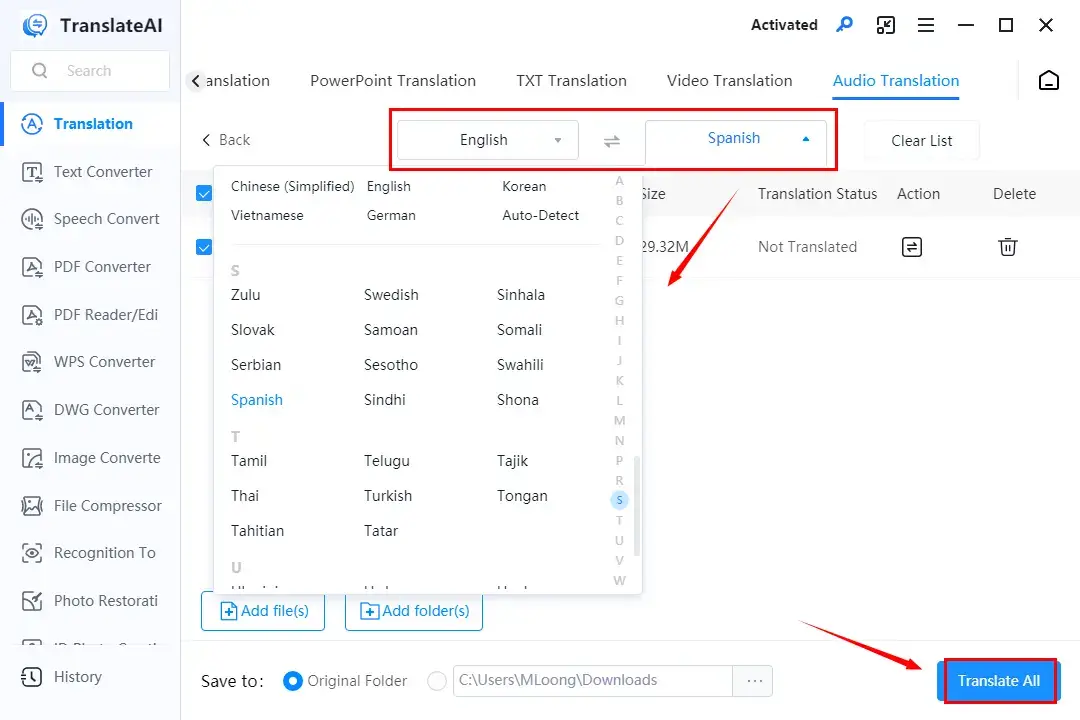
How to Actually Get the Job Done
Most people pick up a video, drop it into a free online tool, and expect it to come out sounding like it was originally recorded in the target language. That does not work. The pipeline is more complicated than that. You need to understand the steps first. Translate Video Audio To Another Language involves five distinct stages: extracting the audio track, transcribing speech using automatic speech recognition, translating the text, generating synthetic voice output, and syncing that voice back to the video while preserving timing and lip movement. Each stage introduces errors that compound across the pipeline. Getting good results means controlling the quality at each step.
The Actual Workflow
I use ElevenLabs for voice synthesis and Whisper for transcription. Here is what a real production looks like on my end. First, extract the audio. FFmpeg does this in about ten seconds on a standard laptop. Use a command like ffmpeg -i input.mp4 -vn -ar 44100 -ac 2 -ab 192k -f wav audio.wav. Do not skip the sample rate adjustment. A lot of YouTube content ships at 22050 Hz, which makes Whisper's accuracy tank significantly. Run the transcription through Whisper. The large-v3 model with timestamps gives you the most reliable output. It usually takes about three minutes per hour of audio on a machine with an M-series chip. If you do not need the timestamps, you can skip that flag, but you will regret it later when you are trying to sync the dubbed audio back.
Once you have the transcript, translate it. Do not use Google Translate directly on a full video transcript. It loses context between sentences, messes up pronouns, and ignores whether you are translating dialogue from a documentary, a fictional scene, or a corporate training video. I feed the transcript into GPT-4 through an API call with a system prompt that specifies the register, the target audience, and whether the content should read conversationally or formally. This takes about thirty seconds for a twenty-minute video. The translation step is where people waste the most time. They paste everything at once and get garbage back because the model hits context limits or degrades in quality on longer inputs. Break the transcript into segments of roughly two hundred words each. Process them individually. This actually runs faster overall because the model maintains coherence, and you can correct a single bad segment without reprocessing the whole file. After translation, generate the speech. ElevenLabs multilingual v2 handles English-to-Spanish, English-to-French, and English-to-German quite well now. The main issue is emotional range. The voices sound flat compared to human dubbing. For narration or explainer content, this is usually fine. For drama or comedy, it falls apart fast.
Get the Full Details
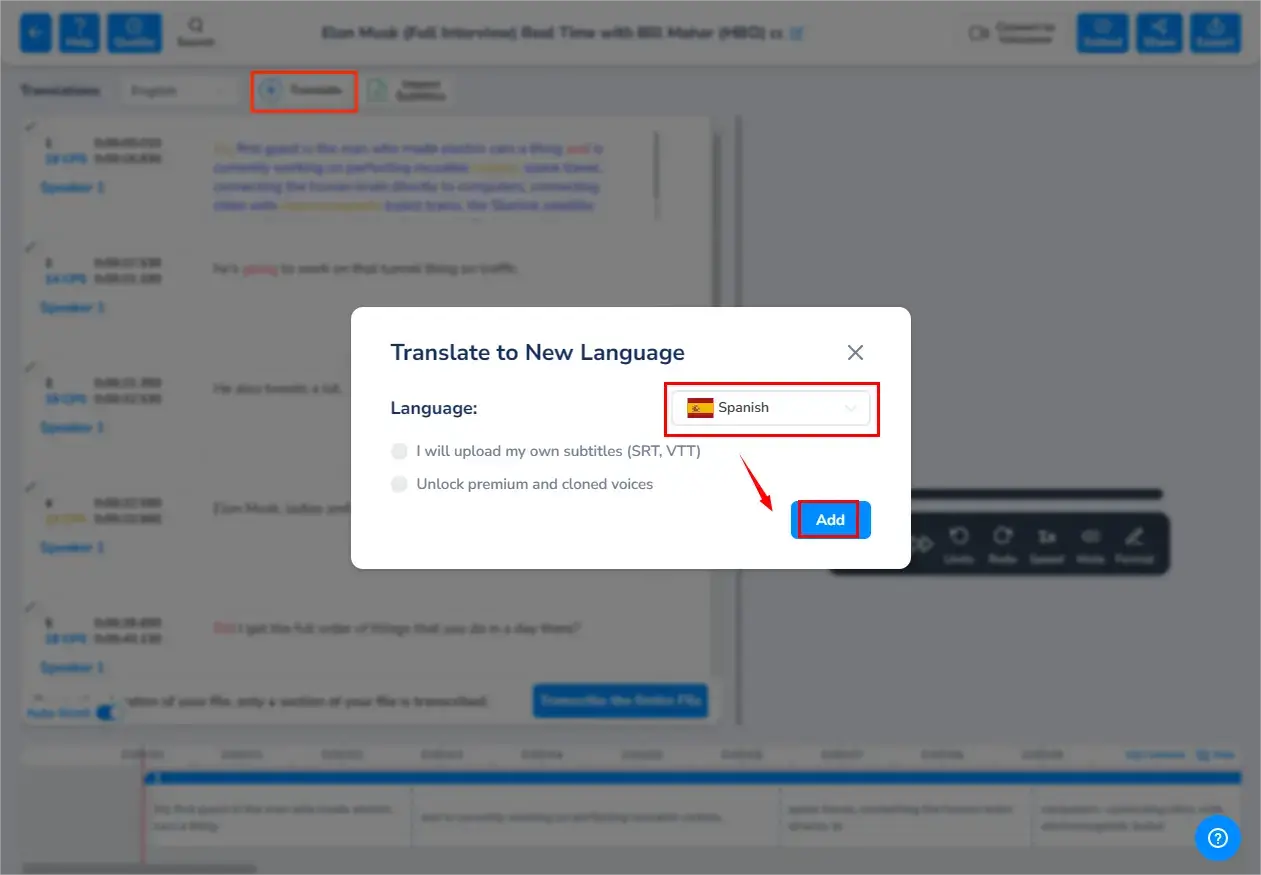
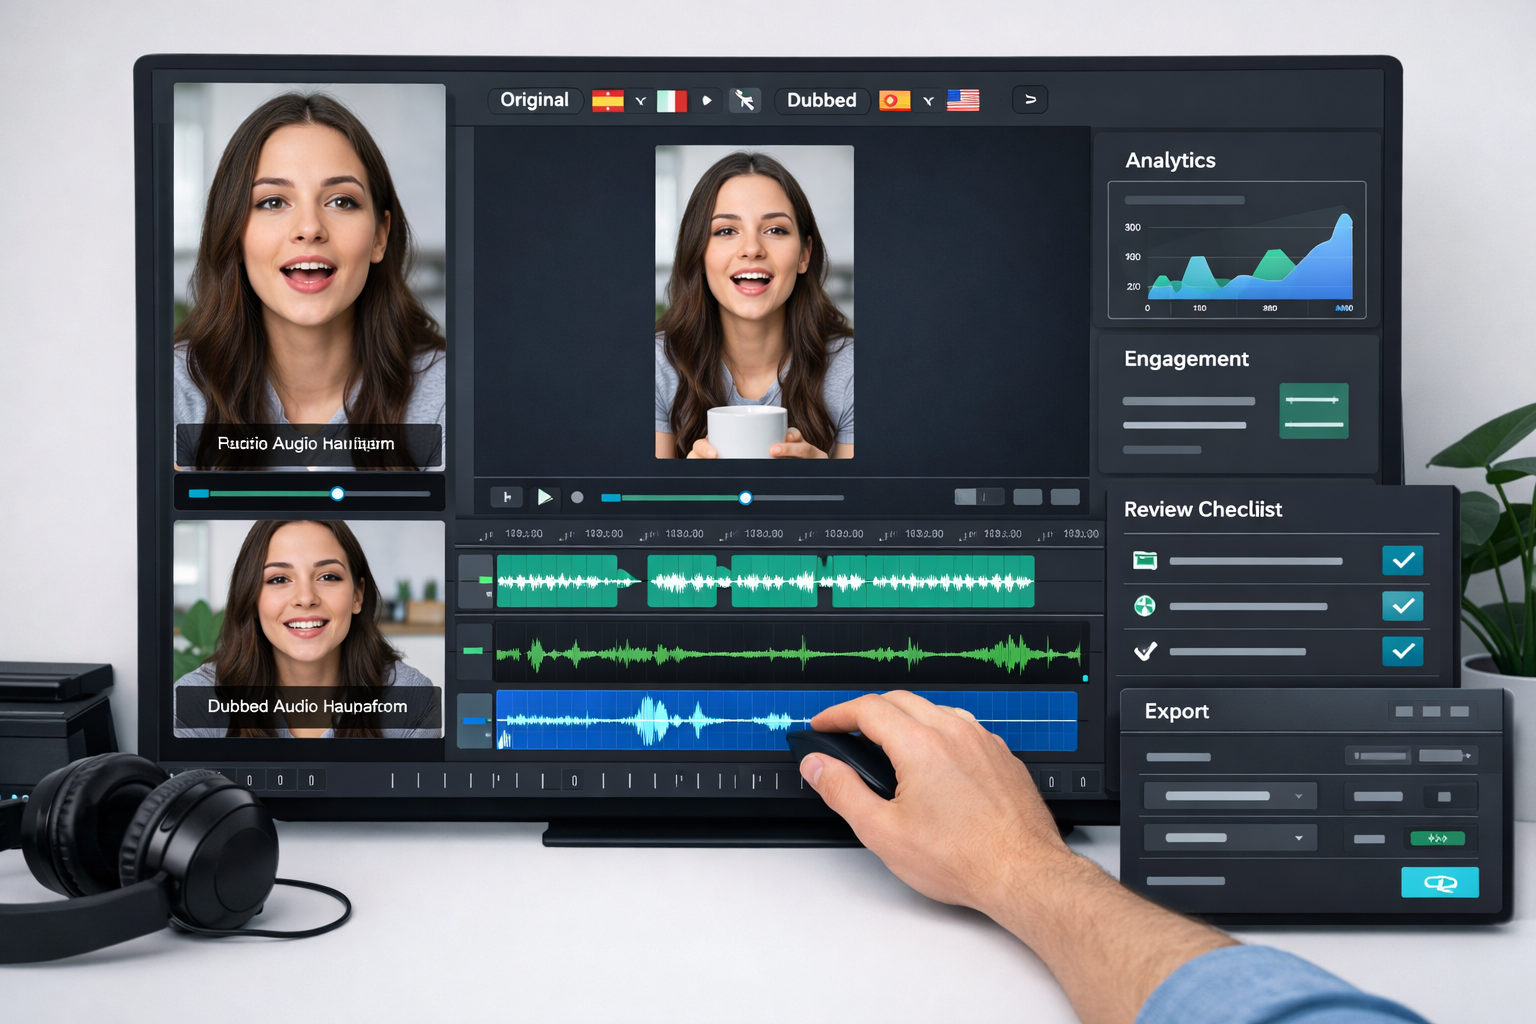
Syncing the dubbed audio to the video is the step nobody talks about. The translated text will almost never match the duration of the original speech. A sentence in Spanish is typically longer than the English equivalent. You need to either stretch the audio slightly or cut it to fit. I use a tool called Pictory for rough alignment, then manually adjust in DaVinci Resolve by matching the waveform peaks to the video's visual cues. This part took me about forty-five minutes for a typical ten-minute video. You can automate parts of it, but the automation produces visibly off-sync results most of the time. The lip-sync problem remains unsolved for consumer-level tools. If you are dubbing a talking-head video where the speaker faces the camera directly, the result will look obviously fake no matter what you do. Adobe's rougue-based lip-sync tool exists, but it only works inside their ecosystem and produces uncanny results for languages with different phonetic structures than the source.
A Specific Problem I Ran Into
I once had to translate a training video where the presenter spoke very slowly and paused between sentences for about two seconds each. The Whisper transcript captured those silences as separate segments, and the translation API treated each short phrase independently. The result was nonsense because idioms and technical terms lost their surrounding context when split apart. The workaround was to pre-process the audio and merge segments that were less than four seconds apart before sending anything to the translator. I wrote a small Python script that reads the Whisper JSON output, identifies silence gaps under four seconds, and concatenates those transcript blocks into single units. This gave the translation model enough context to produce coherent sentences. The script took me about an hour to write and debug, but it cut my rework time from three hours down to roughly twenty minutes.
What This Cannot Do
Automated translation pipelines cannot replicate human dubbing quality. The voices lack natural prosody, background music gets drowned out or has to be mixed back in manually, and accented speech sounds noticeably synthetic. If your budget allows for human dubbing, just hire people who speak the target language professionally. A proper dubbing session for a ten-minute piece costs between four hundred and eight hundred dollars depending on the language pair, and the result will be usable for anything beyond casual internal use. For internal corporate training videos, product demos, or social media content where the audience does not expect Hollywood-quality audio, this pipeline is genuinely useful. It takes about two hours from raw video to final export for a ten-minute piece if you are familiar with the tools. A complete beginner might spend six to eight hours on their first attempt.