Protein Synthesis and What Translation Actually Means in a Lab Setting
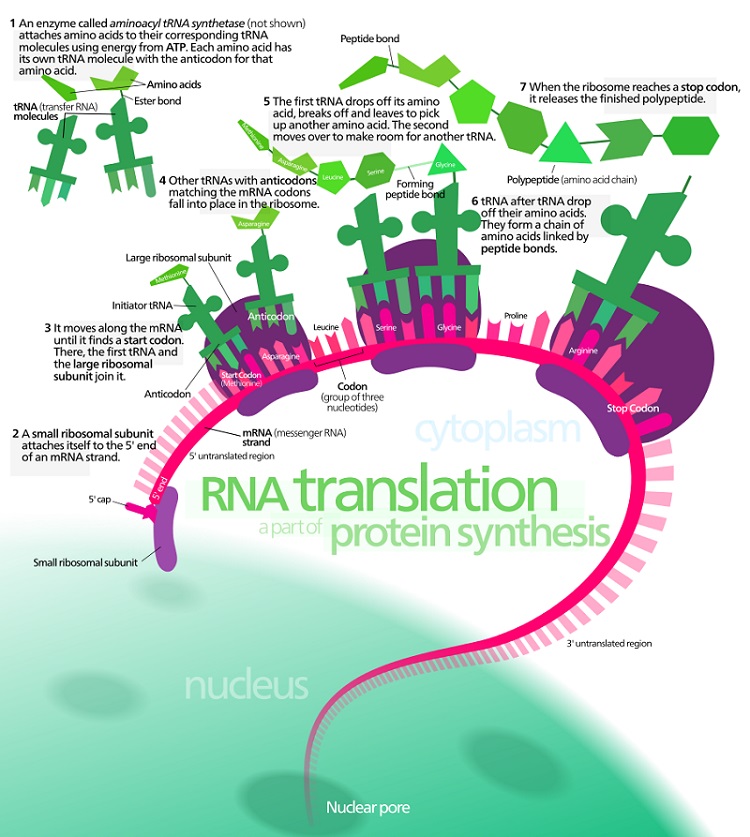
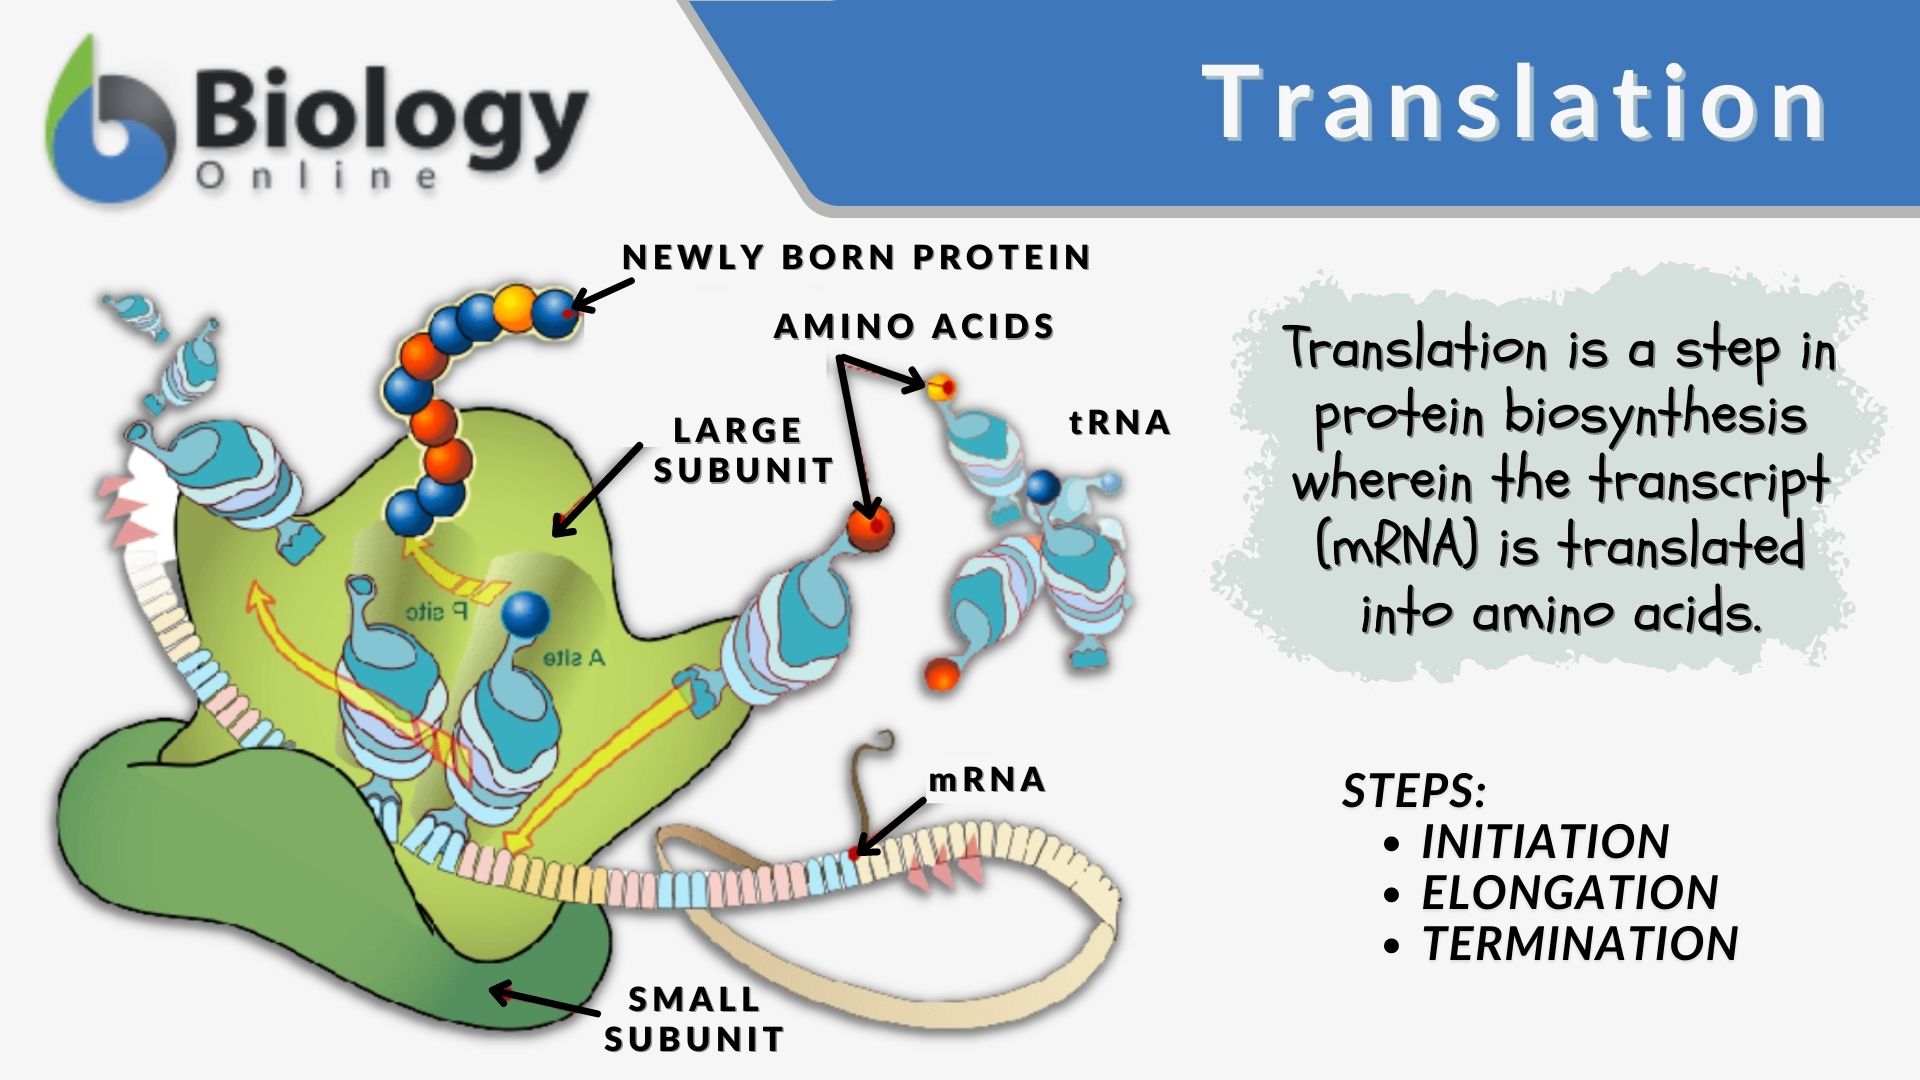
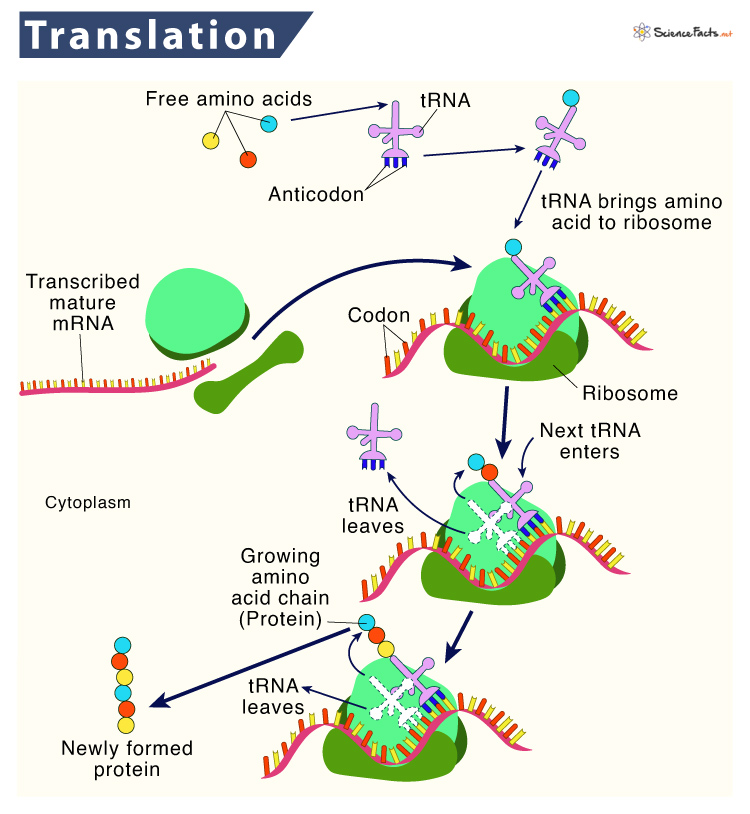
When people ask about the translation meaning in biology, they're usually referring to the second major step of gene expression, right after transcription. DNA gets copied into messenger RNA, and then that mRNA is read by a ribosome to assemble amino acids into a protein chain. It's not glamorous. It's also not as simple as "read code, make protein." Anyone who's actually worked with this process knows there are layers of regulation, waste, and occasional total failure built into every single step. I need to be clear about what happens here before we get into the practical stuff. The ribosome sits on an mRNA strand. It reads three nucleotides at a time. Those three-nucleotide units are called codons. Each codon matches to a specific amino acid through a transfer RNA molecule that carries the correct building block. The ribosome links amino acids together with peptide bonds. The chain grows. It folds. Sometimes it works. Sometimes it doesn't. That's the basic summary.
Understanding the Translation Meaning In Biology Beyond the Textbook Definition
The textbook version stops at codons and amino acids. Real biology doesn't. In practice, translation is where most of the control over gene expression actually happens. Cells don't mostly regulate how much mRNA exists. They regulate whether that mRNA gets translated, how fast it gets translated, and whether the resulting protein even folds correctly. This is important because understanding that shifts how you approach experiments involving protein expression. I ran into a specific problem a few years ago that illustrates this well. I was expressing a recombinant protein in E. coli using a standard plasmid vector. The mRNA was being produced fine. The primers checked out. The sequencing was clean. But the protein yield was essentially zero. I spent two weeks troubleshooting before I realized the issue wasn't transcription at all. It was translation. The codon usage in my gene sequence didn't match the tRNA abundance in the E. coli strain I was using. Certain rare codons were causing the ribosome to stall repeatedly, leading to truncated proteins and general nonsense. I switched to a strain optimized for rare codons and added a plasmid supply of extra tRNAs for those specific triplets. The yield jumped dramatically. This is the kind of thing that doesn't appear in introductory materials but will absolutely cost you time if you run into it. Let me walk through how the process actually functions mechanically. After transcription finishes, the mRNA needs to be processed in eukaryotic cells before it ever reaches a ribosome. A five prime cap gets added. A poly-A tail goes on the other end. Introns get spliced out. Only then does the mature mRNA exit the nucleus and encounter the translational machinery. Prokaryotes skip most of this because they don't have a nucleus. Their mRNA is essentially ready to go immediately, which is why bacterial systems are faster for expression work but also more error-prone when it comes to regulating output.
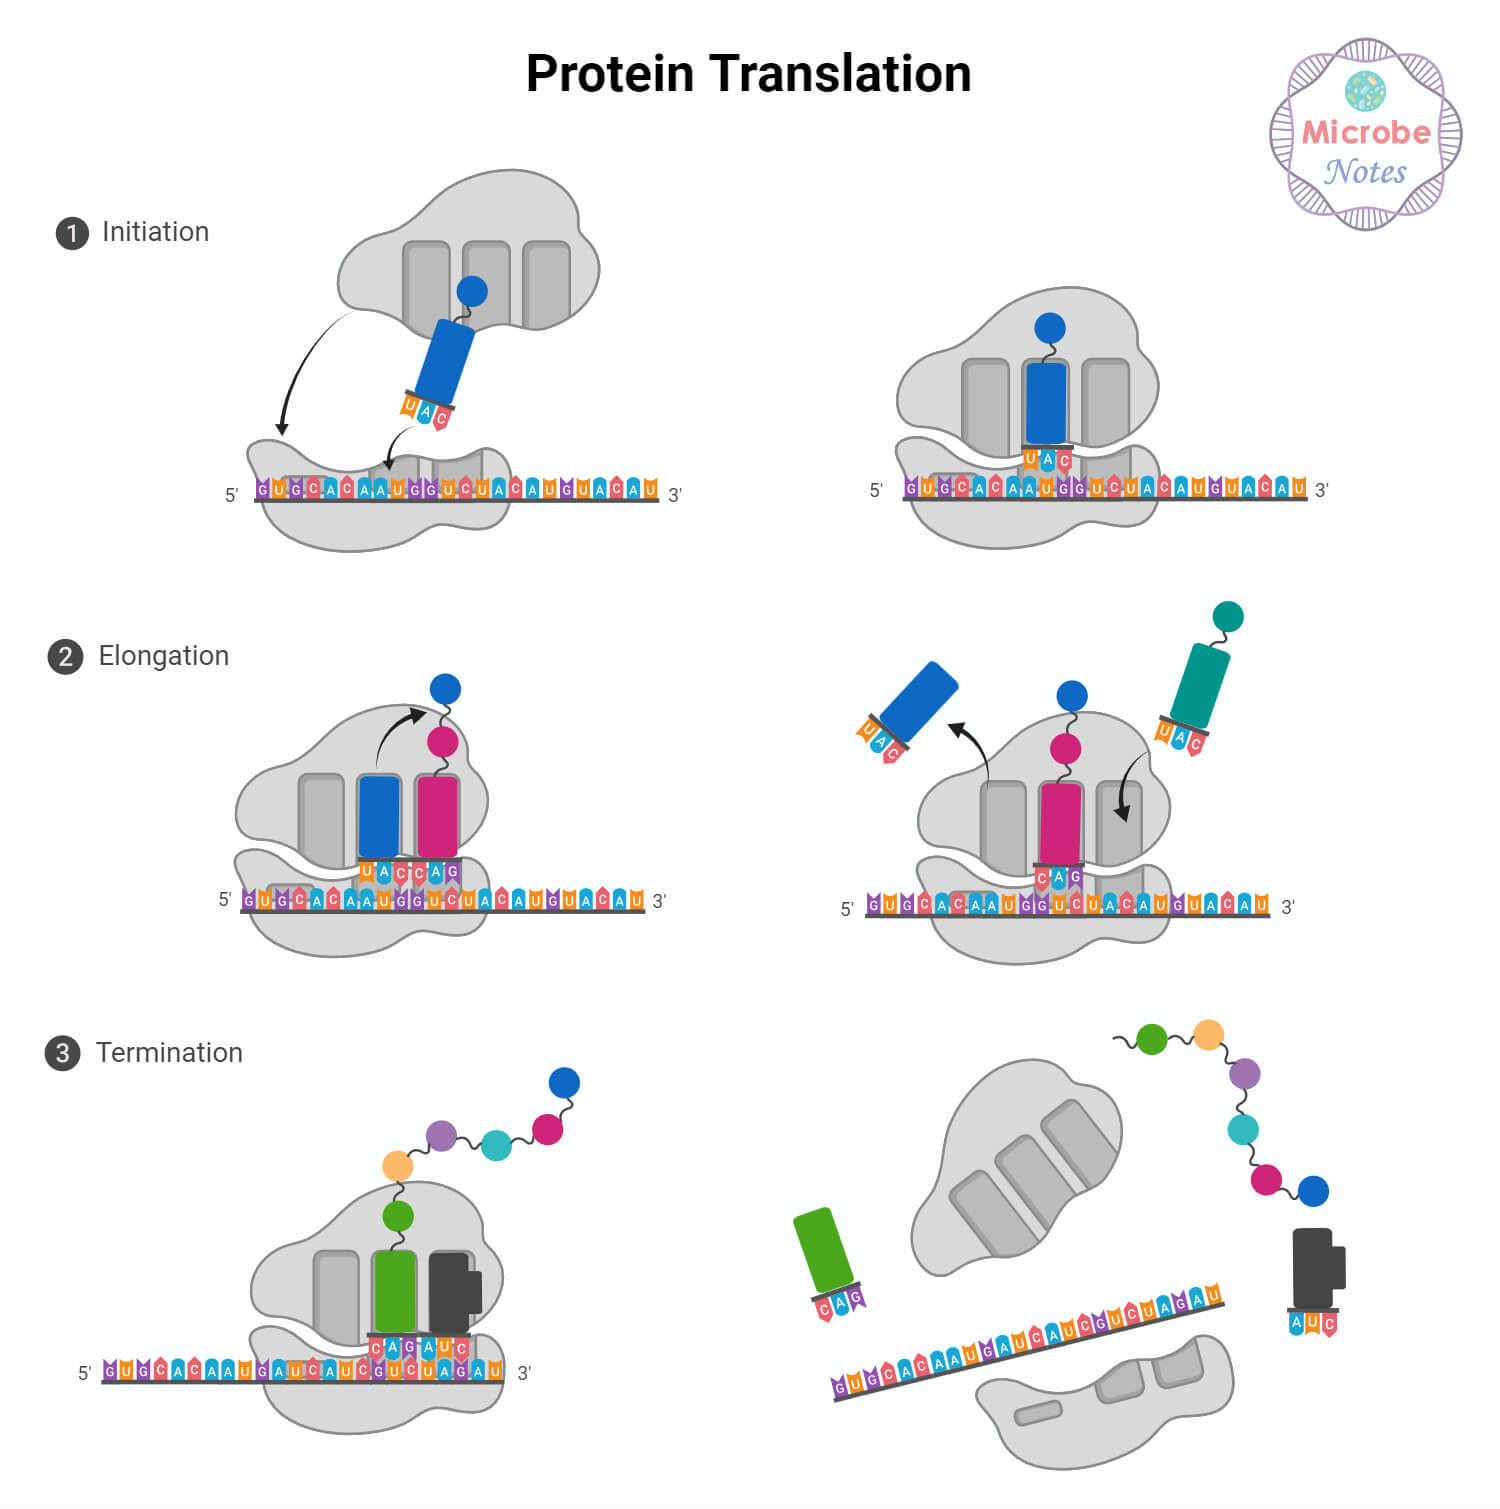
The initiation phase is where things get interesting and where a lot of people misunderstand the process. The small ribosomal subunit binds to the mRNA. In eukaryotes, it typically attaches at the five prime cap and scans downstream until it finds the start codon, which is almost always AUG. In prokaryotes, a sequence called the Shine-Dalgarno sequence, located upstream of the start codon, base-pairs with a complementary region on the ribosomal RNA to position the ribosome correctly. This difference matters enormously if you're designing constructs for expression in different systems. Using a eukaryotic-style mRNA in a bacterial system without the proper Shine-Dalgarno sequence means the ribosome has no idea where to begin reading, and you get nothing. During elongation, the ribosome has three sites: the A site, the P site, and the E site. The A site accepts the incoming aminoacyl-tRNA. The P site holds the tRNA carrying the growing polypeptide chain. The E site is where empty tRNAs exit. Each cycle involves bringing in the correct tRNA, forming a peptide bond, and translocating the ribosome three nucleotides forward. This repeats until a stop codon is reached. There are three stop codons: UAA, UAG, and UGA. These don't code for amino acids. Instead, release factors bind to them and trigger the ribosome to let go of the finished protein. One thing beginners consistently miss is that the genetic code is degenerate. Multiple codons can code for the same amino acid. Leucine alone has six different codons. This isn't a bug. It's a buffer against mutations. If a single nucleotide changes in a codon, there's a decent chance the new codon still specifies the same amino acid. This is called a synonymous or silent mutation. But here's the counter-intuitive part: silent mutations are not always silent in terms of protein output. Different codons are translated at different speeds depending on tRNA availability. A gene loaded with rare codons will translate slower and produce less protein, even though the amino acid sequence is technically correct. Codon optimization, which replaces rare codons with more common ones, is now a standard step in virtually any recombinant protein workflow, and it's usually worth the effort.
Get the Full Details
Folding is another area where translation and function intersect in ways that aren't always obvious. The newly synthesized polypeptide chain doesn't just hang out and fold on its own. Chaperone proteins assist in the folding process. Some proteins need post-translational modifications like glycosylation, phosphorylation, or disulfide bond formation to become functional. These modifications often happen co-translationally, meaning they occur while the protein is still being made. If you're expressing a eukaryotic protein in bacteria, you won't get these modifications because bacteria lack the necessary enzymes and organelles. The protein may fold into something, but it probably won't be the right something. This is why mammalian cell expression systems exist, despite being significantly more expensive and slower than bacterial ones. Now let me address the limitations because this is where the honest answer matters. Translation efficiency varies enormously between genes and between cell types. Even with codon optimization, some proteins are inherently difficult to express. Membrane proteins are notoriously problematic. Highly toxic proteins can kill the expression host before you get meaningful yield. Proteins with complex disulfide bond patterns often aggregate into inclusion bodies in bacterial systems rather than folding properly. There's no universal workaround for these issues. You test, you optimize, you sometimes give up and try a different expression system, and occasionally you just accept that the protein won't behave the way you want it to. The tools available today have changed how this work gets done. In silico codon optimization tools can analyze your sequence and suggest alternative codons. Software like GeneDesigner, JCat, and the IDT Codon Optimization Tool are commonly used. You input your gene sequence and select your expression host, and the algorithm outputs a modified sequence. The results are generally reliable for standard cases but they're not perfect. The algorithms don't account for mRNA secondary structure, which can create hairpins that block ribosome movement. They don't always consider rare codon clusters that might serve a regulatory purpose. And they certainly can't predict whether your protein will fold correctly or remain soluble. You still need empirical validation.
If you're trying to measure translation directly in the lab, there are a few established methods. Pulse-chase labeling with radioactive or stable isotope amino acids lets you track newly synthesized proteins over time. Ribosome profiling, or Ribo-seq, gives you a snapshot of exactly where ribosomes are positioned on mRNA transcripts across the entire transcriptome. It's a powerful technique but it requires specialized equipment and bioinformatics support. For most working labs, a simple Western blot or ELISA after expression is sufficient to confirm that your gene is being translated at reasonable levels. Another practical consideration is that translation rate affects protein quality. Faster translation doesn't always mean better results. When ribosomes move too quickly through certain regions of an mRNA, the protein doesn't have enough time to fold properly as it emerges from the ribosome. This can lead to misfolding and aggregation. Slower translation at critical points, sometimes achieved by intentionally including a few rare codons at strategic positions, can actually improve folding and function. The relationship between speed and quality isn't linear. It's context-dependent. This is another reason why brute-force optimization sometimes fails and why you need to think about the problem more holistically. There's also the matter of translation coupled with degradation. In both prokaryotes and eukaryotes, poorly translated or stalled ribosomes trigger quality control pathways that mark the incomplete protein for destruction. No-go decay and nonsense-mediated decay are two examples. If your construct has a premature stop codon, a frameshift, or a sequence that causes frequent stalling, the cell will actively degrade the mRNA before it produces much protein. This is one reason why checking your construct thoroughly before expression matters. A single nucleotide insertion from a PCR error can shift the reading frame and activate these degradation pathways, leaving you wondering why nothing is being produced when the mRNA should theoretically be fine.
The bottom line is that translation is the step where genetic information becomes functional product, and it's also the step with the most variables and the least room for naive assumptions. The definition is straightforward. The execution is not. If you're working with recombinant expression, spend time on construct design, pay attention to codon usage and mRNA structure, and expect that your first attempt might not give you what you want. The process of figuring out why it failed will teach you more about translation than any textbook summary ever will.