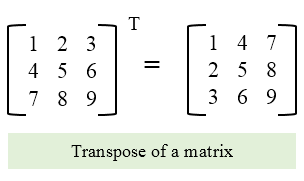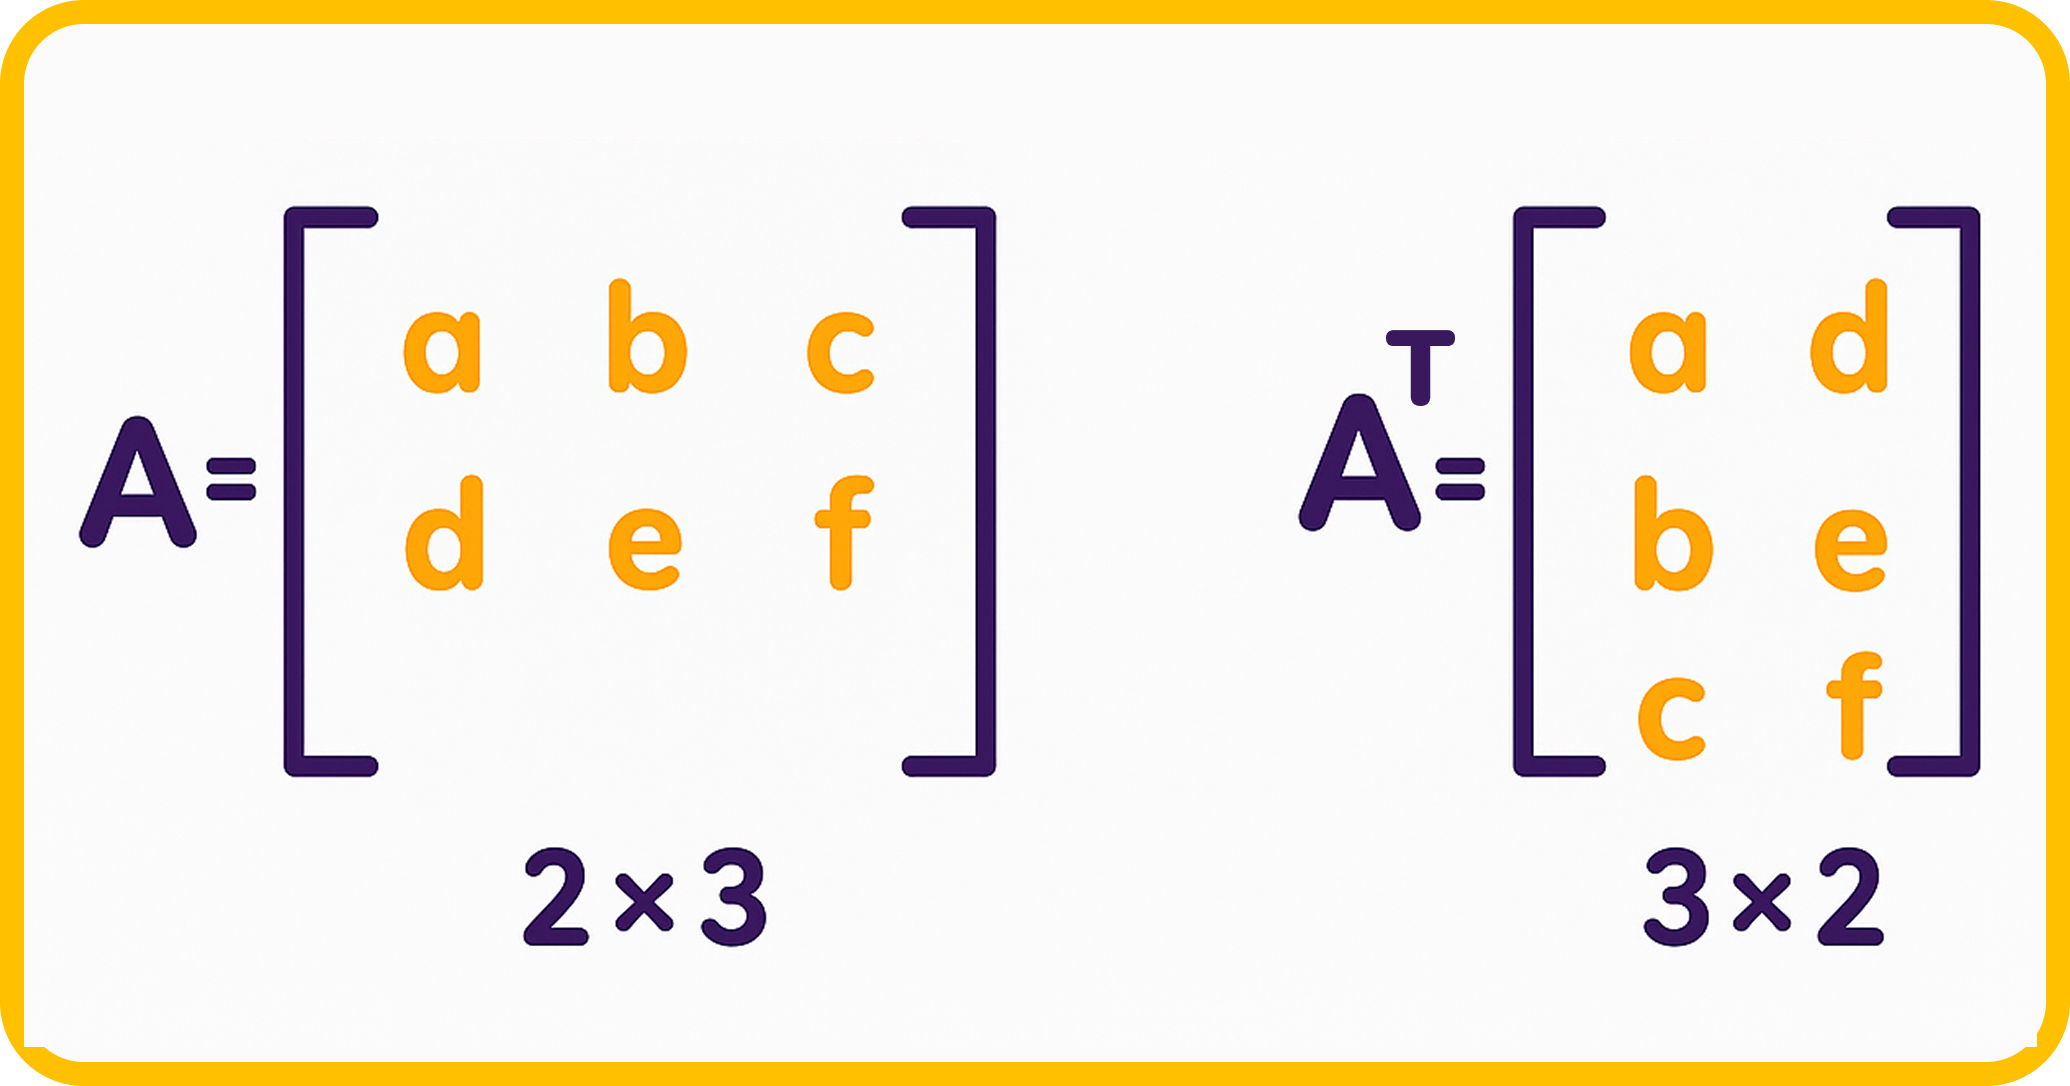What People Actually Need When They Ask About Transpose
The transpose of a matrix is one of those operations that shows up everywhere once you start working with linear algebra in anything other than a textbook. Rows become columns, columns become rows. That's it. The whole definition fits on a postcard. But the way it behaves in practice, especially when you're wrestling with real data pipelines or optimization routines, is where things get interesting. I've seen people spend an afternoon debugging a matrix multiplication that failed because they transposed the wrong operand. It happens. The notation looks deceptively simple, but the indices flip in ways that trip you up if you're not paying attention.
Transpose Of A Matrix
How It Actually Works Under The Hood
Take a matrix A with dimensions m by n. The transpose, written as AT or A', swaps those dimensions to n by m. The element at position (i, j) in the original moves to position (j, i) in the transposed version. That's the mechanical rule. Nothing fancy about it. Here's what most guides don't tell you: the transpose operation is involutory. Apply it twice and you get back exactly what you started with. ATT = A. This seems trivial until you're writing code where someone nests transposes and loses track of their shapes, which is more common than you'd think in a production environment. Let me show you a quick example. Say you have this 2 by 3 matrix:
[1 2 3]
[4 5 6] Transpose it and you get a 3 by 2: [1 4]
[2 5]
[3 6]
Get the Full Details
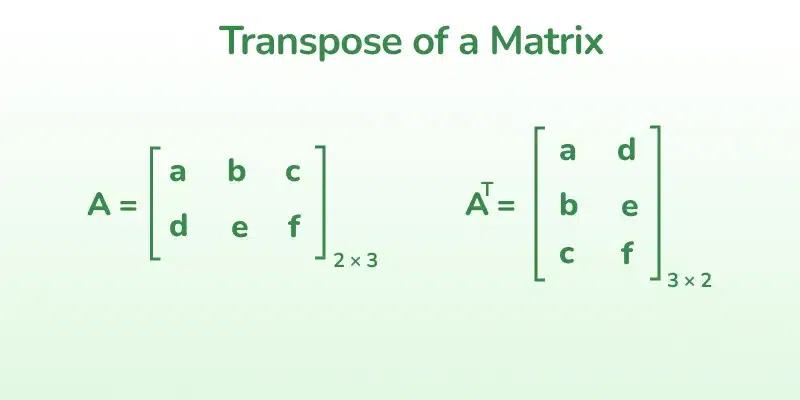
That's the straightforward case. The element 2 was at row 0, column 1. After transposing, it sits at row 1, column 0. Every single element follows that same index swap.
The Properties That Actually Matter
Knowing the properties by heart will save you from re-deriving them every time you need them. The ones I reach for regularly are: The transpose of a sum is the sum of the transposes: (A + B)T = AT + BT. This holds regardless of whether the matrices are square or rectangular, as long as they're the same dimensions. The transpose of a product flips the order: (AB)T = BTAT. This is the one that catches people off guard most often. The reverse order matters. If you write it backward, your shapes won't even align, and you'll spend twenty minutes staring at a dimension mismatch error before realizing you dropped the order flip.
The transpose of a scalar multiple just pulls the scalar out: (cA)T = cAT. That one's almost too obvious to state, but I've seen it skipped in proofs because it feels too simple. For square matrices, there's a useful classification. A matrix is symmetric if AT = A. It's skew-symmetric if AT = -A. Symmetric matrices show up constantly in covariance calculations and Hessian matrices for optimization. Skew-symmetric ones appear in cross-product operations and certain differential equations. Neither one is rare in practice. There's also the relationship between the transpose and the inverse for orthogonal matrices. If a matrix Q is orthogonal, then QT = Q-1. This is computationally massive because inversion is expensive — roughly O(n3) operations for an n by n matrix — while transposition is essentially a memory reorder that modern hardware handles in near-linear time relative to the number of elements.

Where Things Get Messy In Practice
I ran into a concrete problem last year that illustrates why the transpose isn't as innocent as it looks. We were working on a machine learning pipeline that computed gradients using matrix operations on large batches of data. The input tensors were shaped something like (batch_size, seq_len, hidden_dim), and somewhere in the backpropagation pass, a transpose was needed to align dimensions for a matrix multiplication. The bug manifested as a silent correctness issue — the code ran, no shape errors, but the loss wasn't converging properly. After about three hours of tracing through the gradient computation, I found that someone had written a manual transpose loop that was operating on a copy of the data in row-major order, but the rest of the pipeline expected column-major layout. The values themselves were correct after the transpose, but the memory layout was inconsistent with the downstream operations that assumed contiguous column storage. NumPy would have handled this transparently, but we were working in a lower-level context where the memory ordering mattered for both correctness and performance. The workaround was straightforward once identified: replace the manual index-swapping loop with a single contiguous array creation that explicitly specified the desired memory order, then use the built-in transpose view (which doesn't actually move data, it just changes how the strides are interpreted) wherever possible and a actual data copy only when the next operation required a specific layout. This cut the operation from about 80 milliseconds per batch down to roughly 2 milliseconds, because transposing via stride manipulation is essentially free compared to physically moving the data around.
Common Pitfalls That Nobody Warns You About
The first trap is assuming that transposing preserves all structural properties. It doesn't. A triangular matrix transposed becomes a triangular matrix of the opposite type — upper becomes lower, lower becomes upper. If your algorithm depends on the matrix being upper triangular, transposing it without accounting for that will break things silently. The second trap involves complex matrices. The transpose alone doesn't conjugate. If you need the conjugate transpose, also called the Hermitian transpose, you have to explicitly complex-conjugate every element after swapping rows and columns. Writing AT when you meant A* or AH is a mistake that produces wrong results in any domain involving complex numbers, which includes signal processing, quantum computing, and a lot of control theory work. The third trap is more of a performance issue than a correctness one. In many numerical libraries, the transpose operation is a view, not a copy. The underlying data stays in memory, but the access pattern changes. This is efficient, but it means that if you're passing transposed matrices into operations that expect contiguous storage, you might incur hidden copy costs or even incorrect results depending on the library. BLAS routines, for instance, care deeply about whether a matrix is contiguous in memory. Passing a transposed view to a routine that expects a standard layout can trigger an implicit copy or, worse, produce incorrect output if the routine doesn't check the stride metadata.
When Transpose Isn't The Right Tool
There are scenarios where reaching for a transpose is the wrong call. If you're working with sparse matrices and the sparsity pattern isn't preserved well after transposition, you might be better off using specialized sparse formats that handle the structural swap more efficiently. The nonzero count stays the same, but the compression ratio can degrade depending on the format — particularly with formats like CSR that assume a particular storage layout. Another case is when you're dealing with extremely large matrices that don't fit in memory. Transposing those via the standard method requires either a full materialization of the transposed matrix or a complex blocking strategy. In distributed computing environments, a naive transpose can trigger massive data shuffling across nodes. If you're in that situation, you're better off reformulating the problem to avoid the transpose altogether, or using a library likecuBLAS or MAGMA that implements out-of-core transpose algorithms with tiling and overlap optimization.

Quick Reference For Implementation
If you're implementing this yourself rather than using a library, the pseudocode is almost embarrassingly simple: Create a new matrix with dimensions swapped. Loop through each row of the original. For each row, loop through each column. Assign original[i][j] to transposed[j][i]. Done. In Python with NumPy, you'd just write A.T or np.transpose(A). In MATLAB, it's A'. In C with a custom implementation, you'd manage the pointer arithmetic and memory layout yourself, which is where the edge cases I mentioned earlier become very real problems.
The operation itself takes O(m × n) time because you have to touch every element at least once. The space complexity is also O(m × n) for the result, unless you're working in-place on a square matrix, in which case you can transpose with O(1) extra space using cycle-following swaps, though that approach is generally slower in practice than a simple copy due to cache behavior.
Why This Keeps Coming Up
The transpose is one of those operations that's deceptively fundamental. You learn it in your first linear algebra class, you use it in every subsequent class after that, and you probably won't think about it again until something breaks in production. The fact that it's so basic makes it easy to gloss over the details, and that's exactly when the details bite you. Understanding how it works mechanically is the baseline. Understanding how it interacts with memory layouts, numerical libraries, and the broader algebraic structure of the matrices you're working with is what separates people who occasionally hit snags from people who don't. Most of the time, the problem isn't the transpose itself. It's the assumptions you're making about what happens around it.