What Actually Happens When You Try to Solve TSP
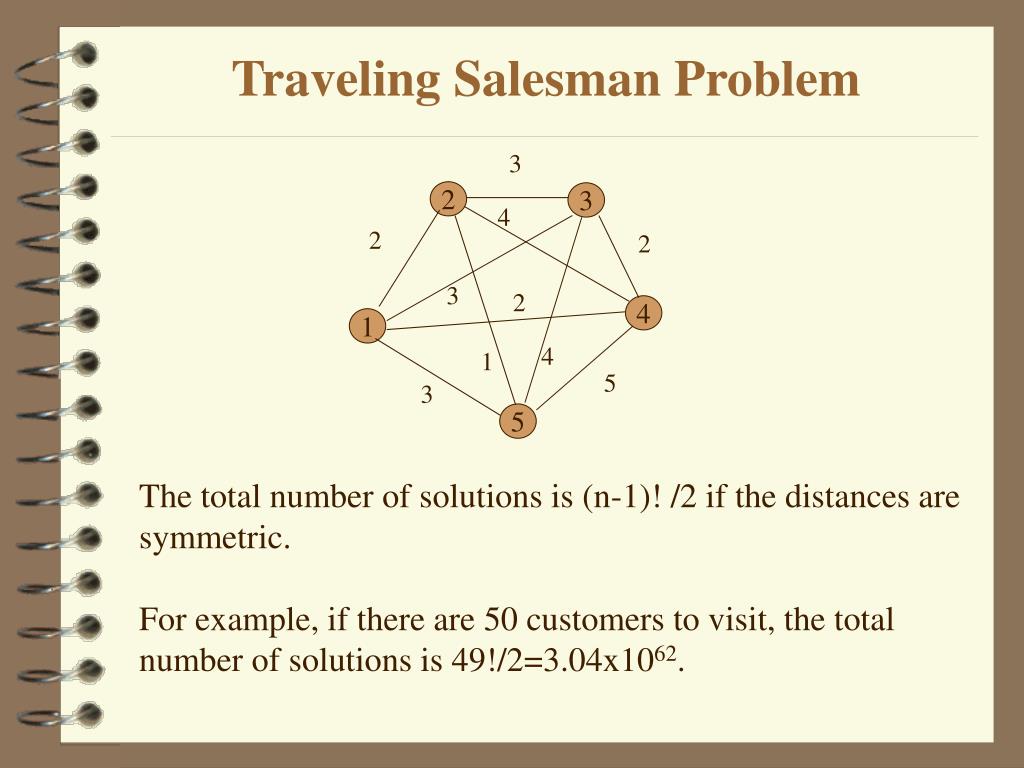
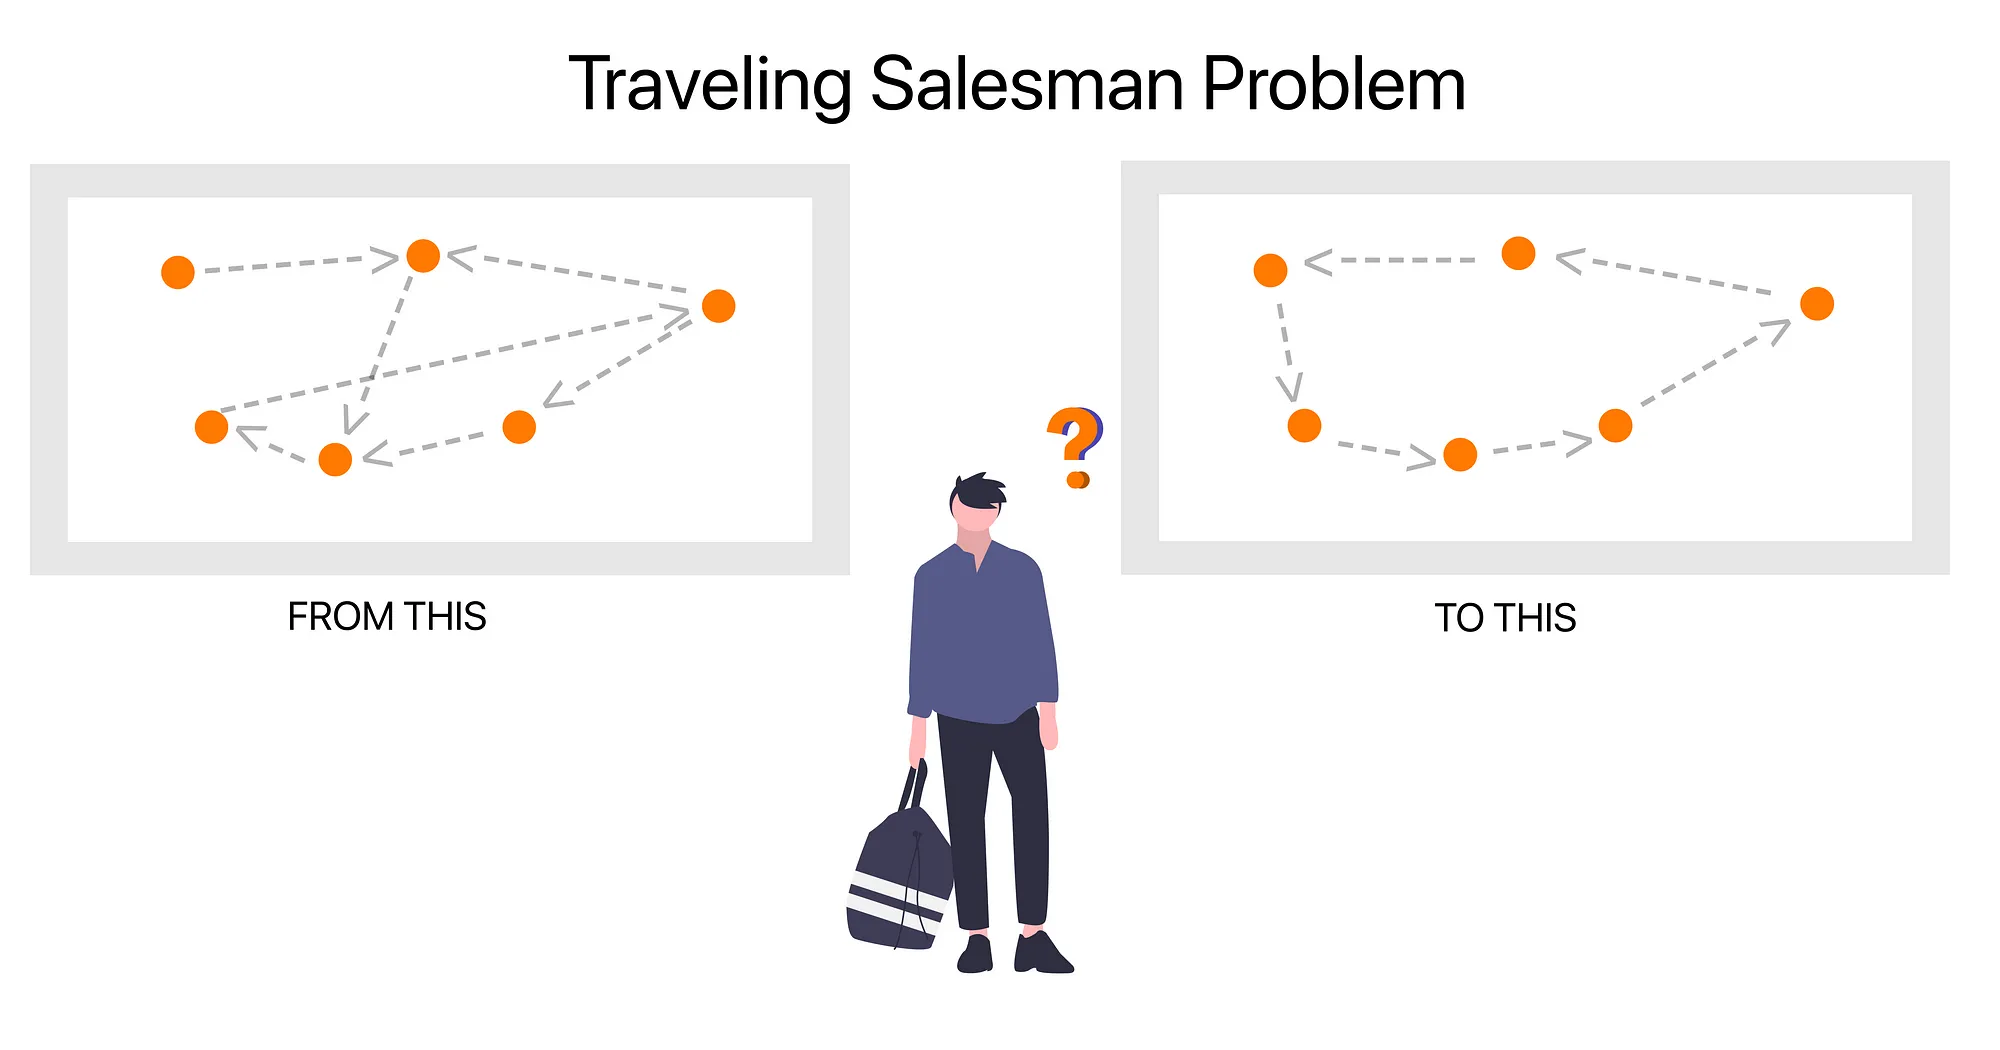
Most people learn about the Traveling Salesman Problem in an algorithms class and think they understand it because they can write a brute-force solution in ten minutes. The brute-force approach checks every possible permutation of cities and picks the shortest route. For seven cities that takes milliseconds. For twenty cities it would take longer than the age of the universe using classical hardware. That gap between the classroom example and real-world scale is where the actual work begins. I spent three years working on logistics optimization for a regional delivery company, and the Traveling Salesman Problem was essentially our daily headache. Not the textbook version with thirty cities and nice Euclidean distances, but the messier reality where you have time windows, capacity constraints, traffic patterns that change throughout the day, and drivers who occasionally take unauthorized breaks. The clean TSP formulation became a subproblem you solved dozens of times per hour as part of a larger routing engine.
Where the Traveling Salesman Problem Shows Up in Practice
Beyond the obvious logistics applications, TSP variants appear in circuit board drilling, DNA sequencing, satellite imaging scheduling, and even cleaning robot path planning. The common thread is always the same: you need to visit a set of locations exactly once while minimizing some cost metric. The metric might be distance, time, fuel consumption, or a weighted combination of all three. What changes between industries is how much the clean mathematical formulation deviates from what the requires. One thing beginners consistently miss is that the classic TSP assumes symmetric distances. City A to city B costs the same as city B to A. Real road networks rarely satisfy this assumption. One-way streets, toll roads with different rates in each direction, and traffic patterns that favor certain routes at certain times all break symmetry. The Asymmetric TSP adds significant complexity to algorithms that assume symmetry, and many off-the-shelf solvers either don't handle it or degrade gracefully when presented with asymmetric data. I learned this the hard way when we deployed a routing system for a medical supply delivery service in a hilly urban area. The elevation changes meant that truck fuel consumption was dramatically different depending on direction. A route that looked optimal on a flat-map calculation would burn twenty percent more fuel in practice. We ended up building a custom cost matrix that incorporated grade data from GIS layers, and even then we only approximated the real physics. The solver returned routes that were within five percent of optimal measured against actual GPS-tracked fuel consumption, which was acceptable for our margin structure but nowhere near the theoretical optimum.
How People Actually Solve It
Dynamic programming approaches like the Held-Karp algorithm give exact solutions in O(n² * 2) time. This is technically exponential, but for problems up to around two hundred cities it can produce provably optimal routes. The memory requirements are brutal though. Each subproblem state stores a bitmask of visited cities plus the current endpoint, and the table grows faster than most engineers expect. I once tried running Held-Karp on a cluster for a three-hundred-city instance and it ran out of memory before finishing. Not time, memory. The machine had sixty-four gigabytes and it needed roughly four times that. Branch and bound methods cut through large portions of the search space by maintaining upper and lower bounds on the best possible solution. When the lower bound for a partial route exceeds the best complete route found so far, that branch gets pruned. Modern exact solvers like Concorde use sophisticated branching strategies combined with cutting plane methods and can solve instances with thousands of cities to proven optimality. The catch is that worst-case complexity remains exponential, and there exist carefully constructed instances that make even Concorde struggle for hours. Heuristics and metaheuristics dominate practical applications because they deliver good-enough solutions in reasonable time. Christofides algorithm guarantees a solution within one and a half times the optimal for metric TSP, which sounds generous until you realize that for a two-hundred-city delivery route, being off by fifty percent could mean an extra forty trucks on the road. Lin-Kernighan heuristics routinely produce solutions within one percent of optimal for large instances and are the workhorse of most production routing systems. They work by iteratively improving a tour through edge swaps that might temporarily worsen the solution before finding the improvement that makes them worthwhile.
Get the Full Details
I used a modified Lin-Kernighan approach for a warehouse order-picking optimization where workers needed to collect items from different aisles. The twist was that workers could carry only a limited number of items at once, forcing them to return to a central packing station periodically. This turned the problem into a capacitated vehicle routing problem with time windows, which is NP-hard even without the TSP backbone. We solved it by decomposing the problem: first generate feasible pickup sequences using a nearest-neighbor heuristic seeded with demand density estimates, then improve each sequence with 2-opt and 3-opt moves, and finally optimize the return trips to the packing station as separate small TSP instances. The whole pipeline ran in under eight seconds per order batch on a standard server.
Common Implementation Pitfalls
Triangular inequality violations will break many heuristic algorithms. If your distance matrix doesn't satisfy d(A,C) d(A,B) + d(B,C), then shortcuts that the algorithm assumes are valid might actually make routes longer. This happens frequently when people use straight-line distances for problems that should use road-network distances, or when they combine data from multiple sources with different coordinate systems. Always validate your distance matrix before feeding it to a solver. Another issue isDegeneracy in the solution space. For certain city configurations, there can be exponentially many tours with nearly identical costs. Local search heuristics get stuck exploring flat regions where small moves don't improve the solution but also don't guide the search toward the global optimum. Adding random perturbations or using simulated annealing with carefully tuned temperature schedules helps escape these plateaus, but finding the right parameters often requires experimentation specific to your instance characteristics. When I worked on a drone delivery routing project, we encountered an interesting edge case where the optimal TSP tour required the drone to cross over a restricted airspace zone. The mathematical solution was correct, but operationally invalid. We solved this by adding penalty costs to edges that crossed restricted zones, effectively making those routes prohibitively expensive while preserving the overall optimization framework. The penalty values needed careful calibration. Too low and the solver still chose restricted routes. Too high and it produced unnecessarily long detours that violated battery constraints.
Scalability is where most implementations fail. A solver that handles five hundred cities in ten seconds might take hours at five thousand. The relationship isn't linear because heuristic algorithms often have superlinear complexity, and memory usage compounds the problem. For large-scale instances, parallelization becomes essential. Domain decomposition approaches split the city set into clusters, solve each cluster independently, then merge the partial solutions. Communication between cluster solves through shared boundary cities adds overhead but typically produces better results than solving the entire instance as one monolithic problem. The approximation algorithms literature offers theoretical guarantees that sound attractive but often don't translate to practical advantage. Christofides three-halves bound is elegant, but achieving it in practice requires computing a minimum weight perfect matching in a general graph, which itself is computationally expensive. For most engineering applications, a well-tuned heuristic that produces solutions within two percent of optimal runs faster than any approximation algorithm with a better theoretical bound.

Tools and Libraries
The Concorde TSP Solver is the gold standard for exact methods and is freely available for academic use. It implements branch-cut-and-price with sophisticated preprocessing and can solve large symmetric and asymmetric instances. The Python interface through pysopt makes integration straightforward. Google OR-Tools includes TSP solvers based on constraint programming and local search, with support for additional constraints like time windows and capacity that extend beyond pure TSP. For quick prototyping, NetworkX provides basic TSP heuristics including nearest neighbor and Christofides implementation. These are educational rather than production-quality, but useful for understanding algorithm mechanics before moving to specialized solvers. The CVRP and VRP extensions in most optimization libraries solve variants that incorporate TSP as a subproblem, so you rarely need a pure TSP solver if your actual problem includes capacity or time constraints. I maintain a personal collection of benchmark instances from the TSPLIB repository and have tested various solvers across different instance types. Symmetric Euclidean instances up to ten thousand cities solve to optimality within minutes using Concorde. Asymmetric instances with road-network data from real cities behave differently. A twelve-city instance based on actual German road distances took longer to solve than a one-thousand-city synthetic Euclidean instance. Problem structure matters more than problem size, and any solver that claims to handle all instances equally is either lying or hasn't been properly tested.
Building Your Own Solver
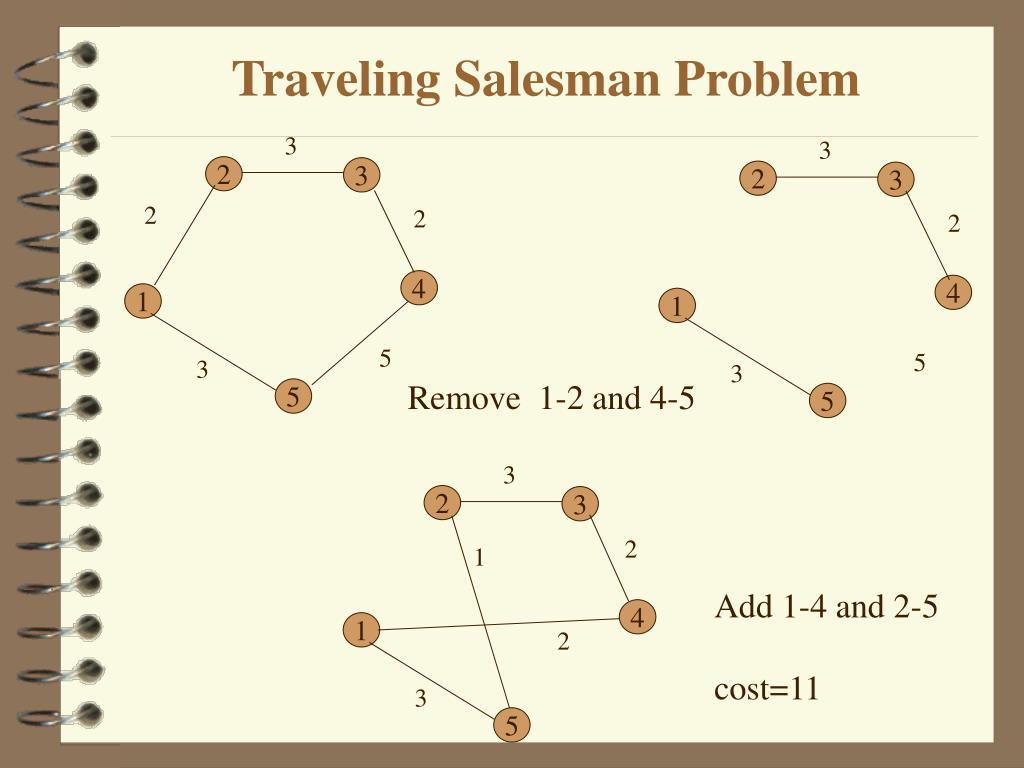
If you need to customize the objective function or add constraints that existing solvers don't support, rolling your own implementation gives you flexibility. Start with a nearest-neighbor heuristic to generate an initial feasible tour, then apply 2-opt improvement. The 2-opt move removes two edges and reconnects the resulting paths in the only way that maintains a valid tour. If the new tour is shorter, accept it and repeat. This simple local search often reaches within five percent of optimal for moderate-sized instances and runs in seconds. For production systems, I recommend combining multiple improvement operators. 2-opt handles basic edge swaps. 3-opt allows more complex reconnections. Or-opt moves entire subsequences of the tour to different positions. Simulated annealing or genetic algorithms provide the framework for accepting worse solutions during search to avoid local optima. The parameter space for these methods is large, and tuning them for your specific problem characteristics usually requires systematic experimentation rather than applying generic parameter settings from the literature. One practical consideration that often gets overlooked is input preprocessing. Removing dominated cities, aggregating nearby delivery points, and exploiting problem structure through clustering can reduce instance size significantly before the solver even sees the data. In one project, preprocessing reduced a twelve-hundred-city instance to an eight-hundred-city effective problem by merging delivery points that were closer than the service time precision allowed. The solver ran four times faster on the reduced instance, and the solution quality difference was statistically indistinguishable.
The Traveling Salesman Problem remains one of the most studied optimization problems precisely because it sits at the intersection of theoretical computer science and practical application. The algorithms are well-understood, the benchmarks are extensive, and the techniques transfer to more complex variants. But understanding why an algorithm works on paper and making it work reliably in production are different challenges that require attention to data quality, constraint handling, and performance characteristics specific to your use case.