What actually matters in the current wave of AI tooling
The market is saturated, and most of what gets called a "must-have" is just a wrapper around someone else's API with a fancier UI. I've been tracking this space for years, and the tools that survive beyond a quarter are the ones solving real bottlenecks, not the ones with the prettiest onboarding flow. Here's what I've actually kept in my stack and why. Local inference runners like Ollama and llama.cpp remain the backbone of any serious workflow. The reason is simple: latency, cost, and data privacy. When you're running hundreds of requests a day through a public API, your bill scales linearly and your data leaves your control. Running locally on a decent GPU gives you predictable costs and keeps everything in-house. The tradeoff is hardware. A 4090 handles 70B parameter models at reasonable speed, but if you're pushing multiple models simultaneously you'll want at least 48GB of VRAM or you'll be waiting on queue times that make the whole setup feel worse than just paying for API calls. I hit this wall last year when I was batching image edits through a local Stable Diffusion pipeline for a client project. The generate queue was backing up to 40+ items, and each render was taking 12 to 18 seconds on an 8GB card. The workaround was switching to a smaller fine-tuned checkpoint and using a controlnet preprocessor pipeline instead of waiting for full denoising passes. Processing time dropped to about 4 seconds per image. It's not elegant, but it's how you work around hardware limits without abandoning the local approach entirely.
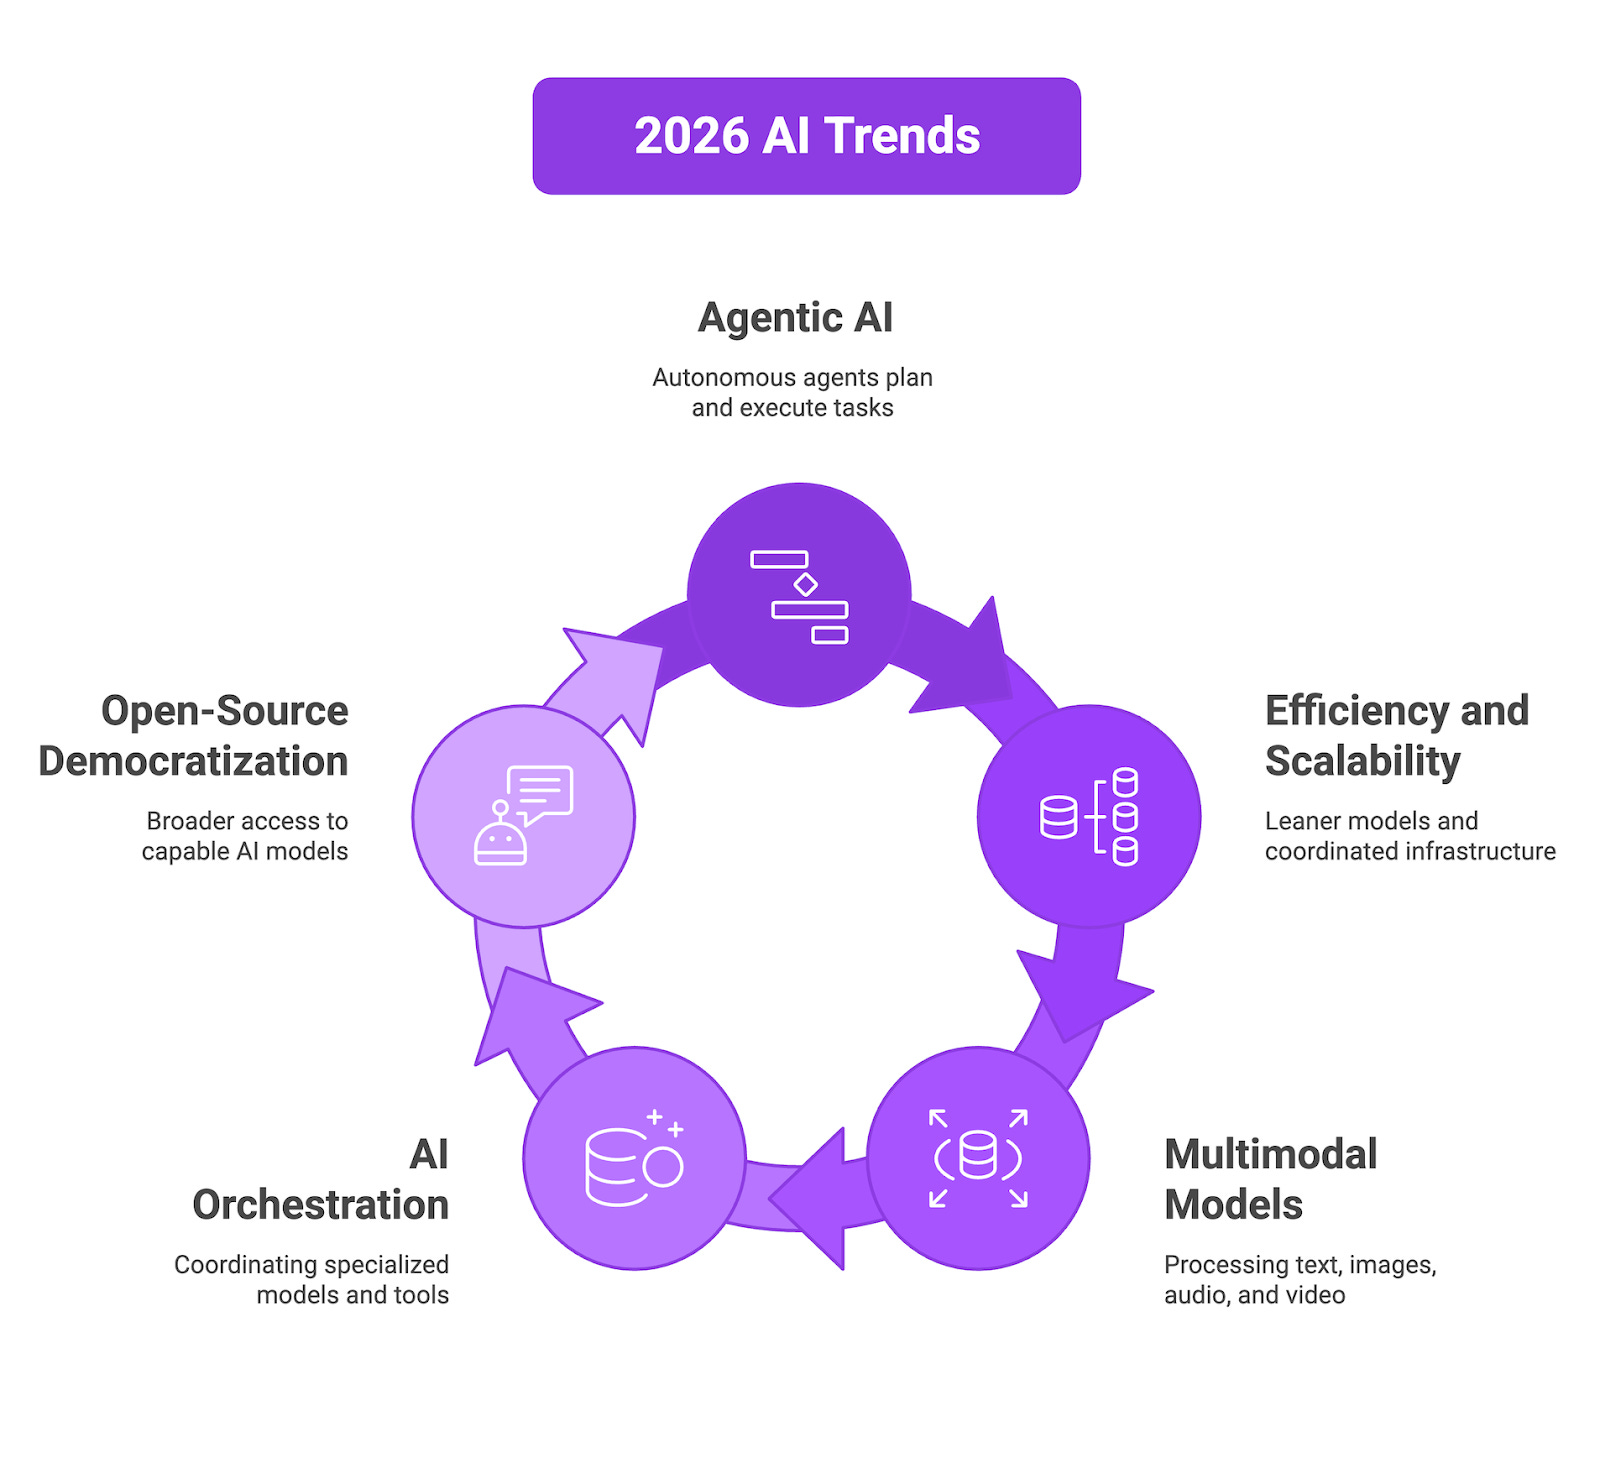
Agentic frameworks have moved from experimental to essential. LangGraph, CrewAI, and the newer AutoGen variants let you chain multiple model calls into something that resembles actual decision-making. The key insight most beginners miss is that agent loops don't improve quality — they improve throughput on complex multi-step tasks. If you just need a summary or a rewrite, a single model call is faster and more accurate. Agents become worth the overhead when you have tasks that require tool use, conditional branching, or multi-source research. I've seen teams cut report-generation time from 90 minutes to roughly 12 minutes by setting up a three-agent pipeline that handles research, drafting, and fact-checking separately. That's the real win, not some sci-fi autonomous assistant. Structured output validators deserve more attention than they get. Tools like Instructor, Marvin, and Pydantic AI enforce schema compliance on model outputs. The problem they solve is the inconsistency of LLM text generation. You can prompt a model to return JSON all day, but it will still occasionally return malformed brackets or extra commentary. Validators catch that at the code level and either retry automatically or flag it for review. This isn't a minor convenience — it's the difference between a pipeline that runs unattended and one that breaks every time a model has an off day. I once spent three days debugging a production issue where the downstream database was choking on a trailing comma in a JSON array. The model wasn't lying to me, it was just being slightly imprecise. A validator would have caught that in under a second. RAG systems remain the standard for giving models access to proprietary or dynamic data. The tools here have matured significantly. You're no longer stuck with basic semantic search — modern implementations support hybrid retrieval, reranking, and even graph-based document relationship mapping. The pitfall most people encounter is chunking strategy. Throw documents into a naive chunker and your retrieval quality tanks because context gets split mid-thought. I found that using a semantic splitter with overlap rather than a fixed-character split improved accuracy scores by roughly 30 percent on a legal document retrieval task. It sounds like a small detail, but it's the factor that separates a RAG system that works from one that looks good in a demo.
Voice and multimodal tools have hit a point where they're viable for production use, not just novelty. Real-time voice agents with sub-second latency exist now, and vision-language models can process screenshots, diagrams, and handwritten notes with reasonable accuracy. The catch is that multimodal models are significantly more expensive per token and slower to respond. If your use case can be handled with text alone, stay with text. Only add vision or audio when you actually need to interpret visual information or handle speech input. I tested a voice-based customer support flow and found that while the user experience felt impressive, the error rate on transcription was high enough in noisy environments that we ended up falling back to a text-first interface with voice as an optional channel. Code assistants have evolved past simple autocomplete. Tools like Continue, Codeium's enterprise tier, and GitHub Copilot Workspace handle full-file reasoning, not just next-token prediction. They can read your codebase, understand imports and dependencies, and suggest changes that respect the existing architecture. The realistic limit is that they still struggle with large, unfamiliar codebases where context window limits force truncation. A good workaround is to feed the assistant only the relevant files and recent diffs rather than the entire repo. This keeps the context focused and reduces hallucination rates noticeably. The broader pattern across all of these tools is the same: the technology is powerful but fragile. Each one works well under the right conditions and fails in predictable ways when pushed outside its comfort zone. The useful skill isn't finding the next shiny tool — it's understanding where each one breaks and building safeguards around those failure points. Budget two weeks to properly evaluate any new addition to your stack. Most teams skip that step, integrate something hastily, and then spend the next six months patching around its limitations.
Get the Full Details