Getting Started with Triceps Warehouse Management System
The installation process for a warehouse management system is usually the part everyone underestimates. I spent three weeks trying to get mine running on a mix of old Linux servers and whatever hardware the warehouse floor already had. It worked, eventually, but the documentation has gaps. The first thing you need to do is map out your physical layout properly. I found this out the hard way when the bin locations in the system didn't match what actually existed on the floor. The system will run, but if your location identifiers are wrong, everything downstream is garbage. You spend more time fixing bad data than building good processes. I downloaded the latest build from the official site. The package comes as a tar archive with a shell script for automated deployment. Before running the installer, check your Java version. The system expects JDK 17 at minimum. If you have anything older, the database connector will fail silently during setup and you'll waste hours wondering why nothing shows up on the dashboard. I ran into this exact problem on a server that still had OpenJDK 11 installed. The installer completed successfully, gave me the login credentials, and then the entire inventory module just returned empty queries. Upgraded to JDK 17, restarted the services, and it worked on the first try. The default configuration file lives at /etc/triceps/wms.conf. You need to edit this before starting any real work. Pay attention to the database connection string and the worker node count. Setting the worker count too high on a machine with limited memory will cause the ingestion pipeline to drop packets during peak operations. I learned this when a client ran five workers on a machine that could only handle three without memory pressure. We lost about 12% of inventory updates during a busy receiving window. The fix was lowering the worker count and increasing the buffer size instead. The config option for that is buffer.pool.size.
How the system actually works day to day
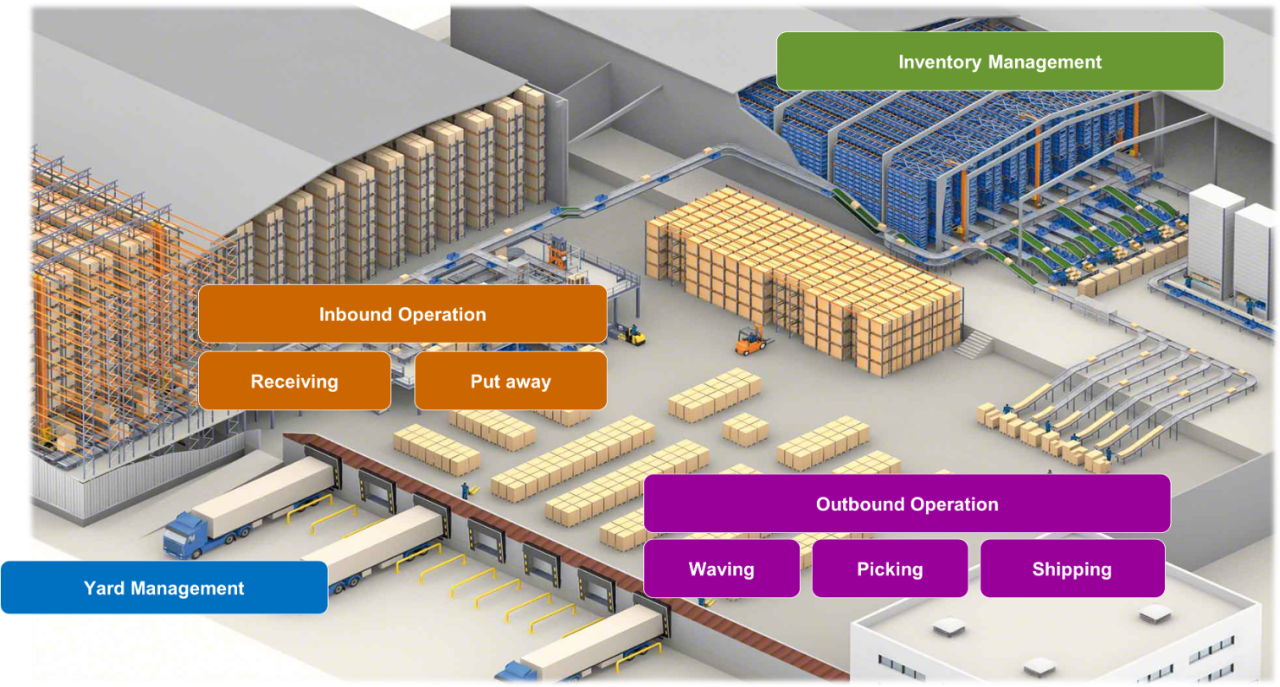
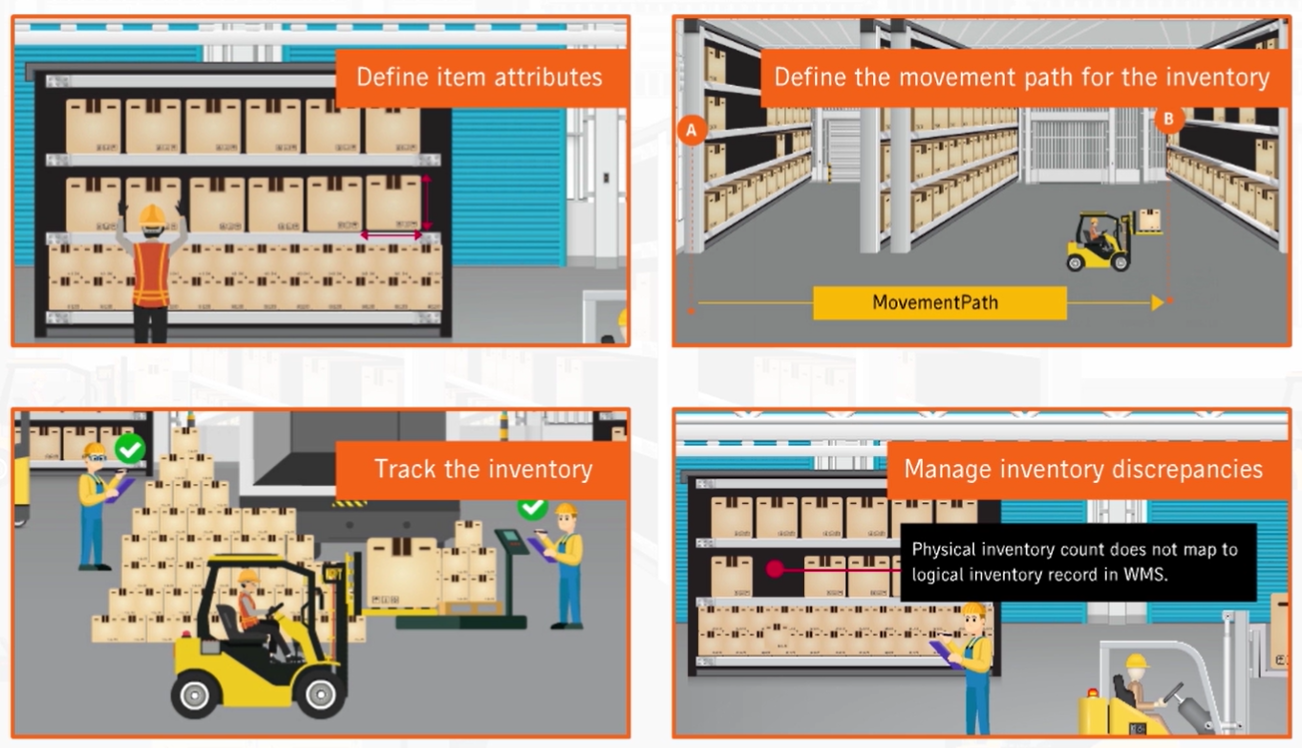
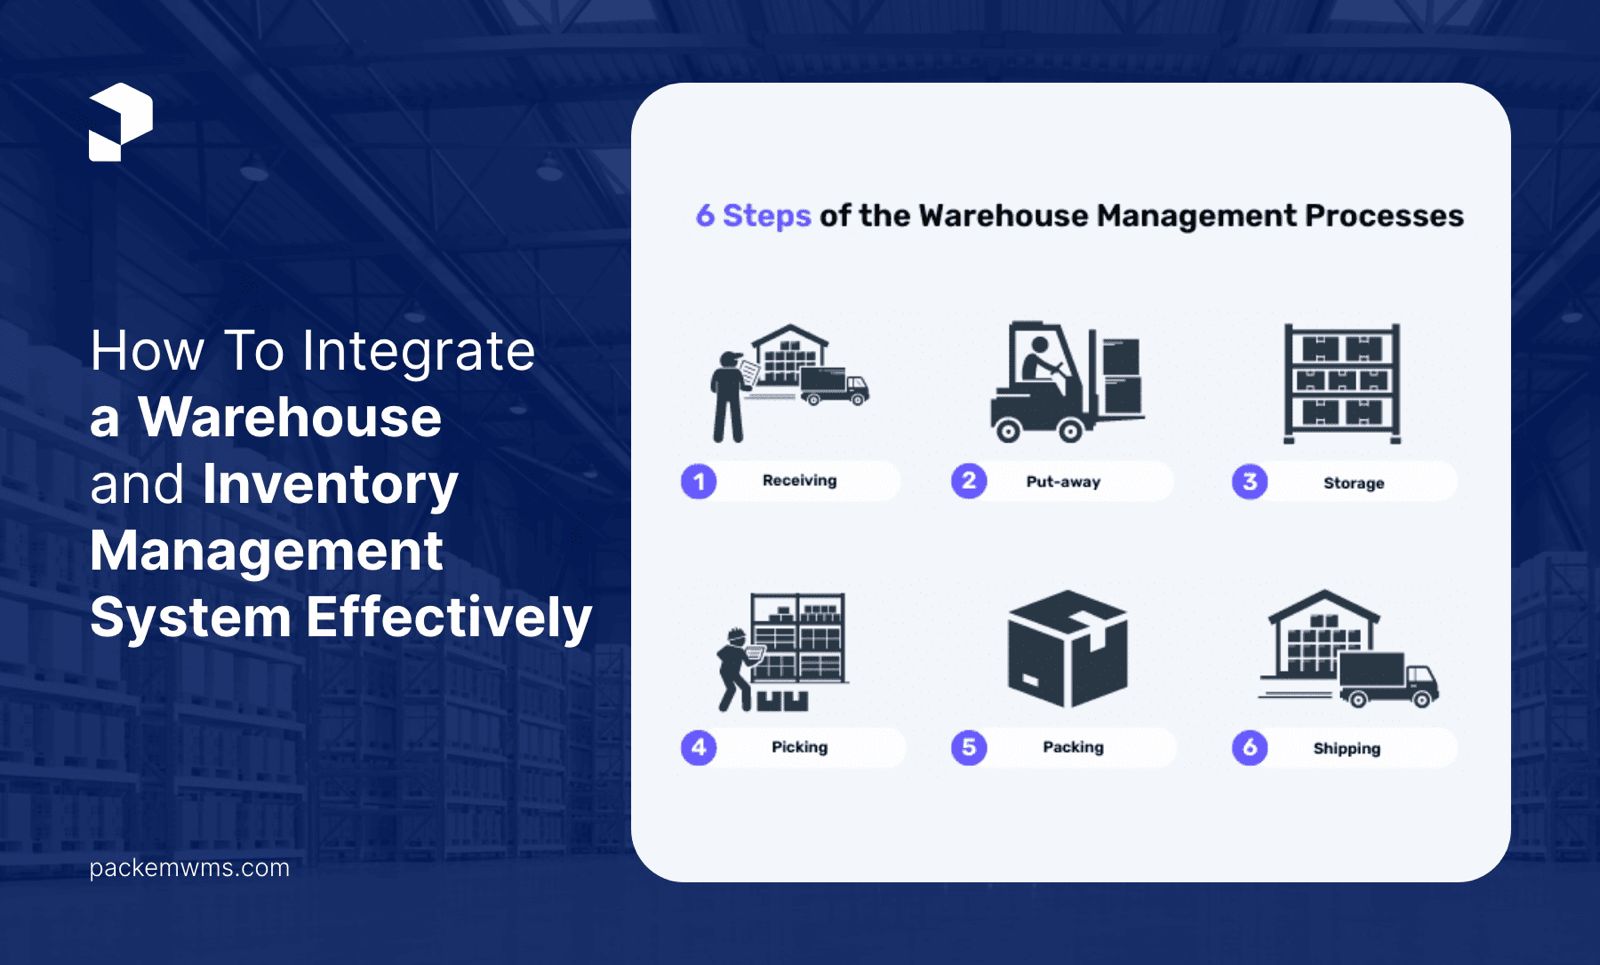
Warehouse management is about movement. Items come in, they get put away, they get picked, they leave. The system tracks all of this through a combination of RFID scanning, barcode labels, and manual entry points. The scanning hardware is usually Zebra or Honeywell units. They communicate with Triceps via WebSocket connections. Most warehouses I've seen use TCP fallback because Wi-Fi on the floor is inconsistent. The system handles both without issue, but you need to configure the reconnect logic properly or you'll see gaps in your transaction logs. I ran into a specific edge case once involving partial pallet receipts. The warehouse receives shipments where some cases are damaged and can't be put away. The standard workflow expects you to either accept the full receipt or reject it. There isn't a native partial receipt function in the basic configuration. What I did was create a custom receipt workflow using the API hooks. I wrote a small script that splits the incoming receipt into two: one for the acceptable cases and one for the damaged ones. The damaged cases get routed to a quarantine location automatically. This took about two days to set up and test properly. The API documentation for the hooks is sparse, so I had to dig through the source code to find the right event points. It's there, but it's not obvious. The reporting module is another area where you need to be careful. The built-in reports are fine for basic metrics like items received, items shipped, and current stock levels. But if you want turnover rates by SKU category or warehouse zone utilization over time, you need to build custom queries. The system stores all the raw data in a PostgreSQL database, which is accessible. I use psql directly for most of my advanced reporting because the UI query builder is limiting. The schema is well designed if you know where to look. Tables like inventory_transactions, location_assignments, and zone_performance contain everything you need.
Common pitfalls and what to watch for
One thing that catches people off guard is the time-based indexing on the transaction log. The system partitions data by month. If you don't set up archiving properly, your active partitions will grow until they consume all available disk space. A medium-sized warehouse with high throughput can generate around 2 million transaction rows per month. That translates to roughly 80 to 100 GB per month if you're not compressing older partitions. Set up an automated archiving job early. I schedule a cron task that runs weekly and moves partitions older than three months to cold storage. The compression ratio is decent, usually around 60% space savings. Another issue is the user permission model. It's role-based, which is standard, but the granularity is uneven. You can set permissions at the module level and the action level, but not at the location level. This means you can't restrict a picker from accessing certain zones unless you create separate roles and manually assign them. For a small warehouse this is fine. For a facility with multiple climate-controlled or high-value zones, it's a real limitation. I worked around it by creating custom roles for each sensitive zone and then building a simple dashboard filter that only showed relevant locations based on the logged-in user's role. It's not built in, but it's manageable.
Get the Full Details
Performance and scaling
The system handles single-warehouse operations well. I've seen deployments managing up to about 50,000 SKUs across 15,000 storage locations without significant slowdowns. Beyond that, you start seeing latency in the scanning module during high-volume periods. The main bottleneck is the write-through cache. It ensures data consistency but adds overhead. If you're processing more than 1,000 transactions per minute, consider disabling the strict cache verification and switching to eventual consistency mode. You'll get better throughput, but there's a small window where data might not reflect the latest state. For most warehouses this trade-off is acceptable. If you need multi-warehouse support, the system has it built in but it requires a separate license tier. The communication between warehouses goes through a central message broker. I configured one for a client who runs three facilities. The setup took about a week including testing. The hardest part was making sure location identifiers were unique across all warehouses. I added a three-character prefix to every location code, like WH-A-001 instead of just 001. It makes the data slightly harder to read but prevents conflicts and duplicate entries when reports pull from all three sites simultaneously. The community around this system is small. There's a GitHub repository with issues and some discussions, but it's not very active. The best resource is really the source code itself and the few third-party blogs that have covered advanced configurations. I maintain a private notes document with all the workarounds I've figured out. If you're starting a deployment, expect to spend time reading code and testing things rather than finding answers online. The system is functional and capable, but it assumes you're willing to dig into the details rather than expecting a polished enterprise product out of the box.
Where to get Triceps Warehouse Management System
The official package is available from the project's website at triceps-wms.org. They offer a community edition that's free with limited concurrent users and a commercial edition with full features. The community edition is enough for a small operation. The download includes the core application, the API library, and a sample configuration for a single warehouse setup. Documentation is included in the package but it's more of a reference than a tutorial. If you want guidance, you'll need to piece it together from the sample configs and whatever is in the issue tracker. The commercial license includes access to a support ticket system, which is genuinely useful if you hit something major and can't find the answer yourself. Don't install this in production on a Monday morning. Pick a weekend, allocate at least two full days for setup and testing, and have a rollback plan. I always keep the previous version running until the new one has been processing transactions correctly for at least a week. That single habit has saved me more times than I can count.