
Why Most Troubleshooting Guides Are Useless Under Pressure
I've read and written hundreds of troubleshooting guides over the years. The problem is almost never the content itself. It's the format. When someone is panicked because their production database is down at 2 AM, they don't want a five-step numbered list with detailed explanations of why each step matters. They want to know exactly what command to run, what output to expect, and what to do if the output is wrong. A well-constructed Troubleshooting Guide Cheat Sheet addresses that gap by collapsing verbose documentation into something you can scan in under ten seconds. The structure is deceptively simple but easy to get wrong. I typically organize entries in a decision-tree format rather than a linear sequence. Each branch point is a symptom, and each leaf node is either a resolution or a handoff point to escalate. Here's how I lay it out. Start with the symptom category. Broad but specific enough to route quickly. If the header says "system slow," nobody knows whether to check CPU, memory, disk I/O, or network latency. "High disk I/O wait (iowait > 40%)" gets you to the right subteam immediately. I spent three years watching support teams waste hours on vaguely categorized tickets before I started enforcing symptom-level precision in every guide I wrote.
For each symptom branch, list the primary diagnostic command or check first. Then the expected output. Then the fallback if the expected output doesn't appear. This third step is where most cheat sheets fail. They assume everything runs cleanly. It almost never does. I always include at least one edge-case path per entry, because the standard path being broken is usually the reason someone opens the guide in the first place. I had a particularly annoying incident with a Kubernetes cluster where pods were cycling through ContainerCreating states with no obvious error in the event logs. The cheat sheet entry for that symptom pointed to a node resource pressure check, but the actual root cause was a stale CSI driver lock from a node that had been drained and recommissioned. Standard troubleshooting steps wouldn't surface it because the lock wasn't visible through normal kubectl commands. I had to write a custom script that queried the node's kubelet socket directly for pending volume operations. That became a permanent addition to the cheat sheet with a dedicated escalation path. The lesson was that some failure modes live outside the standard tooling surface, and your guide needs a way to flag those.
The Components That Matter
A functional cheat sheet has five components. Everything else is decoration. Symptom identifier. This needs to be searchable and match language that real users will type into a search bar. "MySQL connection refused on port 3306" is better than "database connectivity issue." The latter might be a firewall rule, a crashed process, or a configuration drift. The former points directly at a single path. Quick diagnostic action. One command, one tool, or one UI navigation step. Not a paragraph. If your diagnostic action requires reading a manual, it's not quick enough for a cheat sheet. I enforce a hard limit: if the diagnostic step takes longer than thirty seconds to initiate, break it into a separate reference document and link to it.
Get the Full Details
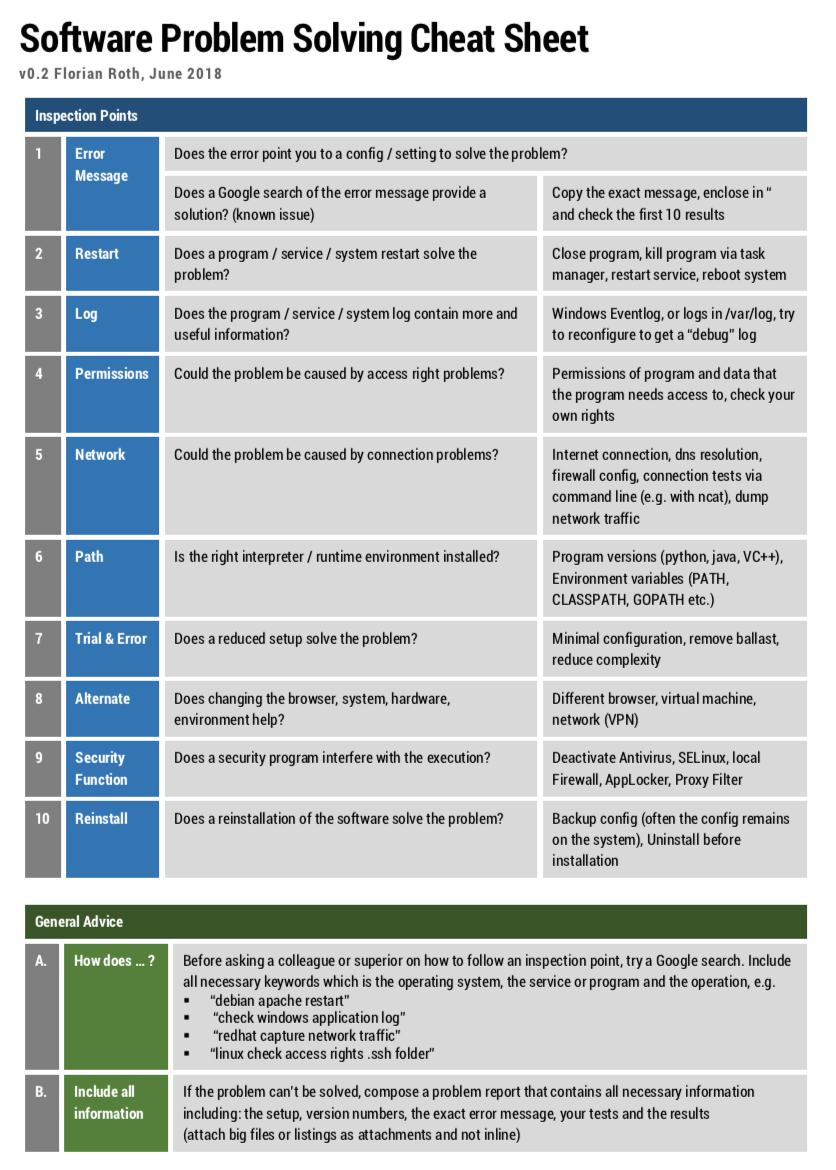
Expected result and decision point. After the diagnostic runs, what should the output look like? If it matches, proceed to the resolution. If it doesn't match, which alternate path do you follow? This is the branching logic that separates a cheat sheet from a runbook. A runbook assumes a single known path. A cheat sheet handles uncertainty. Resolution steps. Keep these numbered and imperative. No passive voice. No "it is recommended that you." Just "run this command, then verify X, then proceed to Y." People reading a cheat sheet under pressure don't want rhetorical hedging. Escalation trigger. Define exactly when the person following the guide should stop and escalate. Vague triggers like "if unresolved" are worthless. I use concrete markers: "if the issue persists after applying all three resolution steps within 15 minutes," or "if any diagnostic returns an error code prefixed with ERR_CRITICAL." The escalation path should include who to contact and what information to provide them upfront. I've seen experienced engineers skip escalation because the guide didn't give them permission to escalate, and they kept cycling through resolution attempts that weren't going to work.
Common Mistakes That Make Cheat Sheets Worse
The most common mistake I see is conflating a cheat sheet with a knowledge base article. They're different tools for different phases of a problem. A knowledge base article explains context and background. A cheat sheet is for action. If your document requires someone to understand the underlying architecture before they can use it, it's not a cheat sheet. It's a tutorial. Put it in a different document. Another frequent error is over-branching. Decision trees grow exponentially and become unreadable within three or four levels. I cap mine at two levels of branching depth, then group deeper complexity into a linked reference section. A cheat sheet should fit on a single screen or a half-sheet of paper. If it requires scrolling on mobile, it's too long. Version drift is the silent killer. I maintain a single source of truth for each cheat sheet and track changes with a version stamp and date. During a production outage last year, two team members followed slightly different versions of the same cheat sheet because one had been updated three days earlier and the other hadn't synced. The older version contained a deprecated command that returned a misleading success code. The newer version used the current API endpoint. Five minutes of wasted time that shouldn't have happened. Now I enforce that every cheat sheet lives in a centrally managed repository with automatic distribution to all local copies, and any modification requires a minimum of two reviewers.
When a Cheat Sheet Won't Help
This is important and often ignored. A Troubleshooting Guide Cheat Sheet is not a solution for novel problems, systemic architectural failures, or issues that lack observable symptoms. If the problem doesn't produce a diagnostic signal you can act on, no amount of structured guidance will help. In those cases, the right move is to document the gap and create an incident response protocol instead. Cheat sheets assume the problem space is bounded. When it isn't, you need a different mechanism entirely. I also recommend pairing a cheat sheet with a monitoring and alerting layer rather than relying on the guide alone. The fastest troubleshooting is the kind that never happens because the system caught the issue before a human had to notice. A cheat sheet is a fallback, not a primary strategy. Teams that treat them as equivalent end up with large, detailed documents that sit unused because the underlying systems never surface problems in detectable ways.

How to Distribute and Maintain One
Host the cheat sheet in a format that supports fast text search and doesn't require special software. Plain text, Markdown, or HTML all work. I prefer Markdown because it renders cleanly everywhere and version-controls well. Store it in the same repository as your infrastructure code so that changes to the system and changes to the guide happen in the same pull request cycle. I've seen guides become obsolete because they lived in a completely separate document management system that no one bothered to keep in sync. Schedule a quarterly review for every cheat sheet. Not an annual review. Quarterly. Systems change, tools get deprecated, new failure modes emerge, and documentation decays. A cheat sheet that hasn't been touched in six months is likely already behind the current state of whatever it's supposed to help you fix. If you want a starting template, the structure I just described maps cleanly onto any plain-text format. Symptom Diagnostic Expected Result Branch Decision Resolution Escalation Trigger. That's it. Five fields per entry. Nothing more. Everything else is noise.


