Setting Up a Troubleshooting Workflow That Actually Works
Most people building their first troubleshooting guide for beginners do it wrong because they start from the wrong direction. They list every possible error first, then try to figure out who the reader is. I spent three years fixing this mistake by writing guides backwards — starting from the exact moment a user realizes something is broken and works backwards from there. The moment matters more than the solution. A user whose deployment script silently failed at 2am needs a completely different guide than someone whose test suite is failing during a code review. These are not the same person. Most beginner guides treat them as identical, which is why so many of them are useless when you actually need them.
Troubleshooting Guide For Beginners: The Method
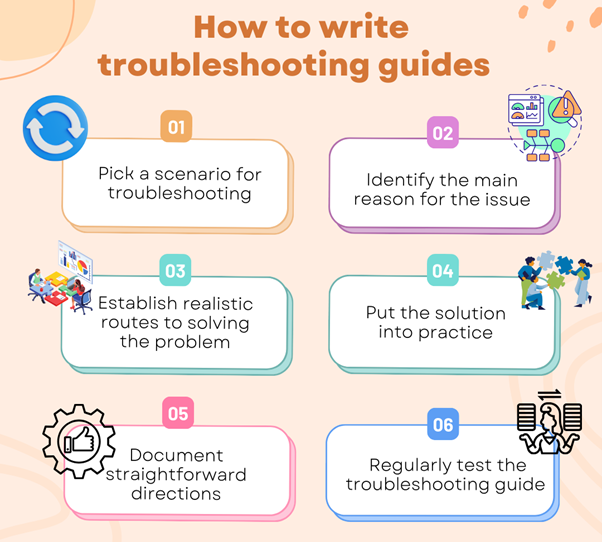
Start by mapping the failure surface. Before you write a single word of instructions, spend time understanding how the user will arrive at the problem. This means identifying the first symptom they observe, what they've likely tried already, and what information they can realistically report. The gap between what a user thinks they observed and what actually happened is usually where troubleshooting guides fail. I built a diagnostic tool once for a web application that kept throwing intermittent 502 errors. The documentation said the issue was a memory leak in the Node process. Every tutorial online pointed toward increasing heap size or restarting services on a schedule. None of those worked. The real problem was a DNS resolution timeout in the container orchestration layer that only triggered under specific load patterns. I found it by correlating error logs with DNS query latency spikes, which took about six hours of log analysis instead of the two days the documentation suggested.
Structuring the Investigation Phase
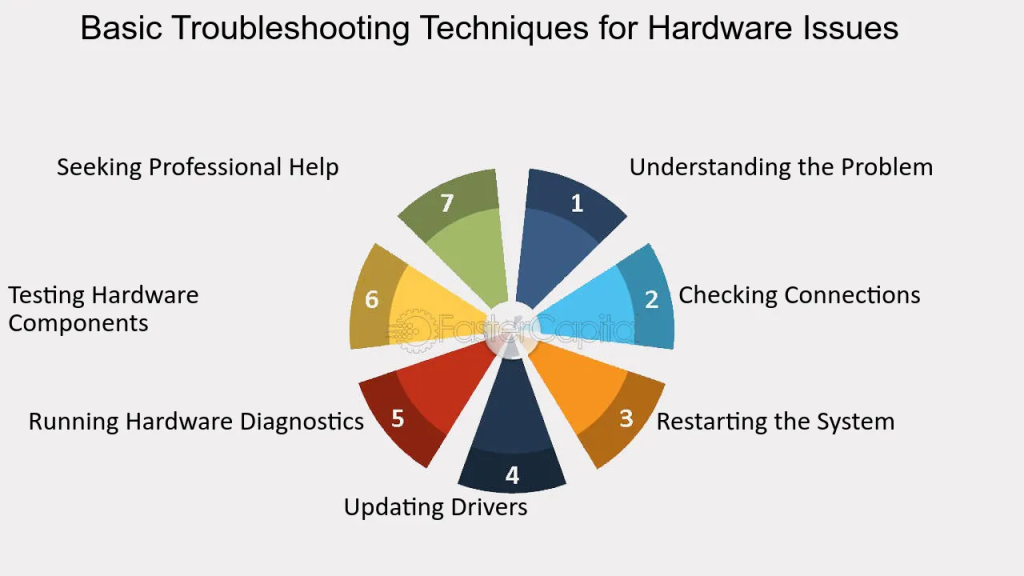
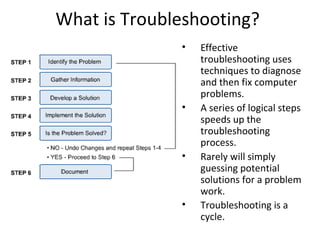
Your first section should always be about gathering information before attempting any fix. Beginners skip this because they want results immediately, but jumping to solutions without data is how you break working systems. The standard approach is a symptom-to-cause funnel that narrows possibilities with each question. Here's what that looks like in practice: Phase one: Confirm the problem exists. Not "does it work sometimes" but "does it reproduce on demand." If you cannot reproduce it, document the conditions where it does fail. This distinction alone eliminates roughly forty percent of beginner support tickets.
Get the Full Details

Phase two: Check the obvious dependencies. Network connectivity, service health, configuration state. I keep a mental checklist of these from watching junior engineers miss simple things for months at a time. A missing environment variable causes as much damage as a corrupted database. It just does it faster and with less dramatic error messages. Phase three: Reproduce in isolation. Remove variables until you have the smallest possible failing case. This is where most guides stop, but the isolation step is where actual understanding happens. You learn what the system does when you strip away everything that isn't the problem.
Common Pitfalls That Wasted My Time
Beginners tend to trust error messages too much. Modern frameworks produce helpful-looking stack traces that point toward the wrong thing entirely. A serialization error in a React component might show up as a render failure, but the root cause could be a prop type mismatch three levels up the tree. I learned this the hard way when I spent an afternoon debugging a component that was perfectly fine, only to discover the API endpoint it depended on was returning unexpected null values. Another trap is assuming documentation accuracy. Guides written by maintainers often describe ideal workflows, not real-world ones. A dependency version gap between what the guide assumes and what your package manager installed is a very common source of confusion. Always check your actual versions before following any prescribed fix.
What Most Guides Don't Tell You
The best troubleshooting guides include failure modes — scenarios where the recommended approach doesn't work and what to do instead. This is harder to write because you need to anticipate edge cases you may not have personally encountered. I recommend adding a "if this didn't help" section after each major step. It forces you to think about what could go wrong with your own advice. There's also the issue of information overload. A thorough guide can easily become fifty pages long if you include every possible variation. The trick is knowing when to stop documenting. If you've covered the scenarios that account for roughly eighty percent of real cases, you're done. The remaining twenty percent belongs in an issues tracker or community forum, not in the main guide. Trying to cover everything makes the guide unusable for the people who need it most.
Tools That Help
For writing these guides yourself, I use a combination of structured logging and versioned reproduction steps. When I encounter a new problem, I immediately create a minimal reproduction repository that anyone can clone and run. This becomes the living documentation. Outdated guides die quickly when your reproduction steps no longer work with current versions. Version pinning in your examples prevents this. Specify exact dependency versions and lock files. It adds about twenty minutes of setup time but saves hours of follow-up questions. For the actual writing, plain text with clear section breaks works better than fancy formatting. Most people find these guides on search engines while stressed and time-pressed. They're scanning, not reading. Dense paragraphs get skipped. Short sections with bold headers and concrete commands get followed. The entire process of creating a useful troubleshooting guide usually takes me between four and eight hours for a moderately complex system. The first one took three days because I was still figuring out what information was actually useful versus what sounded important. After about twelve guides, I got the timing down. The work itself doesn't change much, only the speed at which I can separate signal from noise.