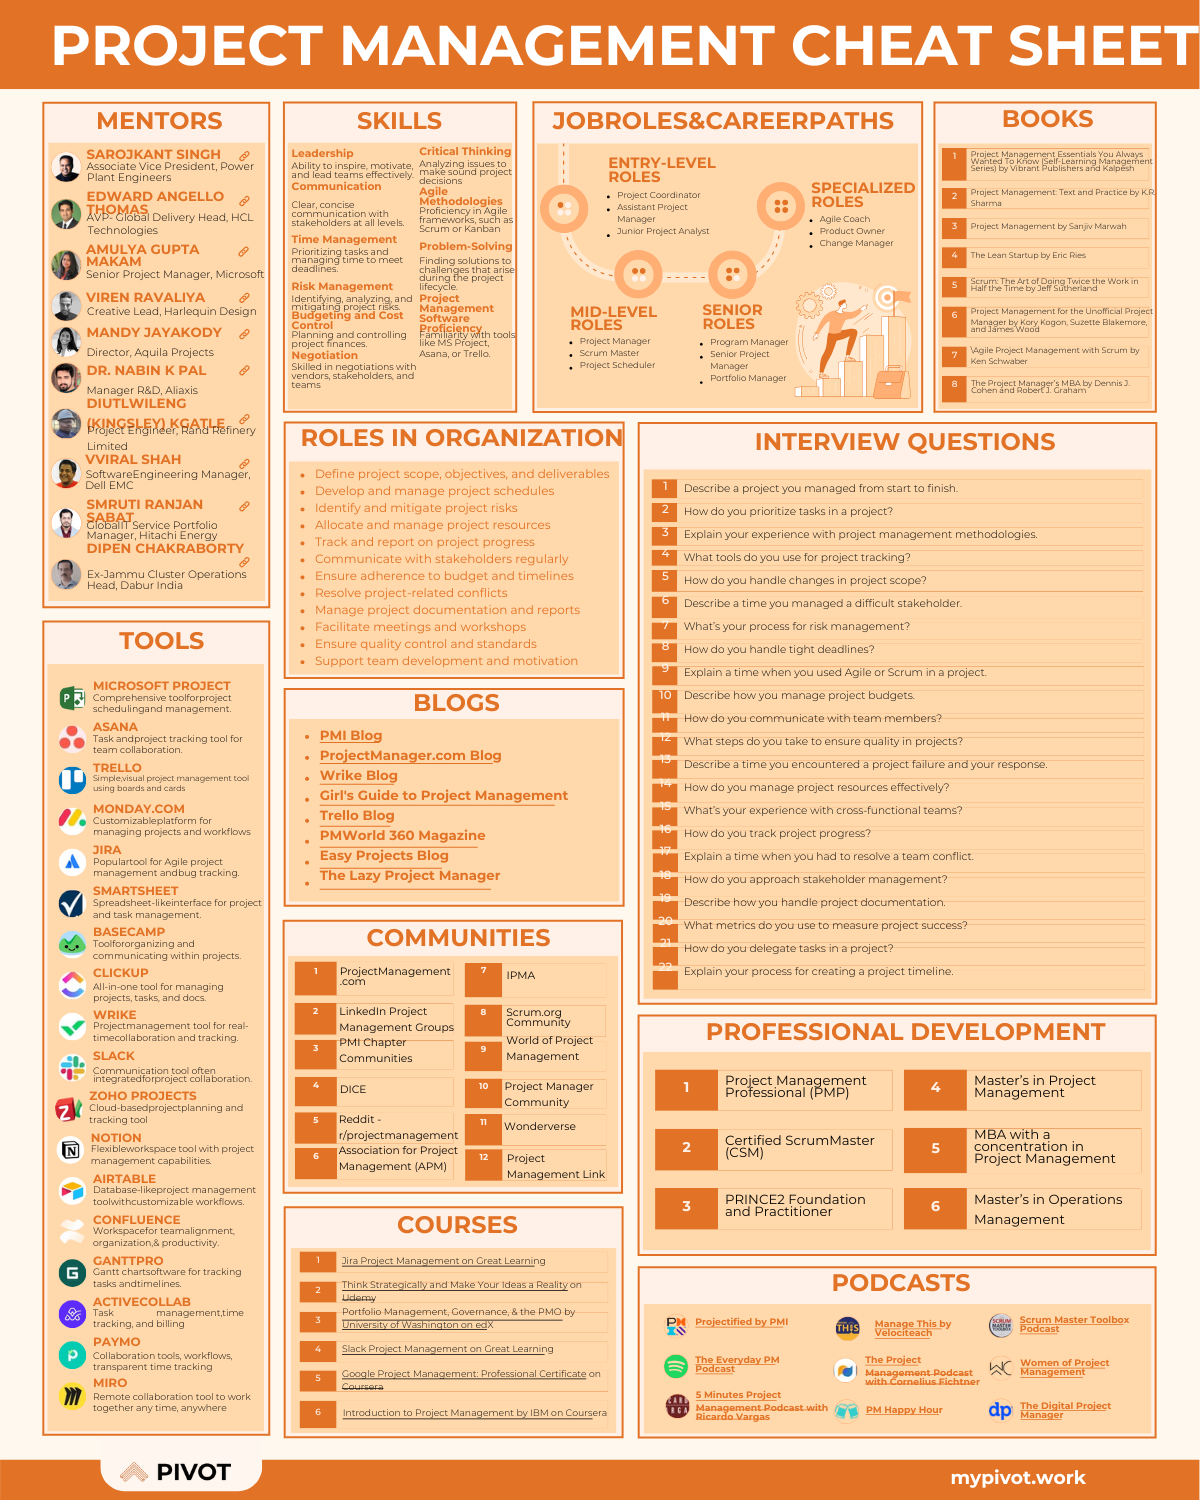
The Unvarnished Truth About Project Management Troubleshooting
Most people treat project management like it's a linear process. It isn't. You'll spend more time untangling dependencies and fixing scope creep than you will actually planning anything. A good troubleshooting guide doesn't sit on a shelf for six months before someone remembers it exists. It lives in the moment you realize the Gantt chart is three weeks behind schedule and the client hasn't even noticed yet. I built my first real cheat sheet back in 2016 for a construction software rollout that was failing at every stage gate. Three months in, we'd burned through 60% of the budget and the steering committee wanted to cancel the whole thing. The problem wasn't the timeline or the resources — it was that nobody had written down what "done" actually looked like for each phase. We filled a single page with decision points, escalation paths, and the three questions every sponsor needed answered before they'd sign off on anything. That page saved the project. We trimmed it down to a one-pager over the next six months and ended up using it on every project after that.
Troubleshooting Guide For Project Management Cheat Sheet
The core of any effective cheat sheet comes down to a handful of recurring failure patterns that show up regardless of methodology or industry. Waterfall, Agile, hybrid — they all break in similar ways. Here's the breakdown that actually matters. Scope creep without documentation is the number one issue I see. A stakeholder asks for a small addition during a routine check-in. It feels harmless. Two weeks later you have five parallel changes that weren't in the original baseline. The workaround is simple: every change request gets logged in a single shared register with a timestamp, the person who requested it, and the estimated impact on timeline and cost. Not formal change control boards with three signatures. Just a shared spreadsheet column that everyone has to fill out. This usually catches 90% of untracked changes before they compound. I've seen projects where the scope register became the most referenced document in the entire portfolio because it was the only thing that told the truth about what was actually being built. Resource conflicts manifest differently depending on whether you're working in a matrix organization or a dedicated team environment. In matrix setups, the same person might be allocated across four projects at 25% each on paper, which looks efficient until someone gets sick or goes on vacation. The practical fix is to cap multi-project allocation at 70% total across all assignments. The remaining 30% is your buffer for illness, unplanned meetings, and the inevitable urgent request that nobody scheduled. Without that buffer, you're running every project on a tightrope with no net.
Milestone ambiguity is another quiet killer. A milestone that says "development complete" means something completely different to engineering, QA, the product owner, and the client. I worked on a healthcare platform where QA considered a feature complete when unit tests passed. Engineering considered it complete when it shipped to staging. The product owner expected it complete only after user acceptance testing. The client thought complete meant the feature was available in production with documentation. Each party had a different definition. We started requiring every milestone to include a checklist of verifiable deliverables signed off by at least two roles before it could be marked done. This cut our milestone rework rate from roughly 40% to under 10% within two sprints. Communication gaps between remote and in-office team members are a structural problem, not a cultural one. When half your team is remote and the other half sits in a room, the room-based people naturally make decisions in hallway conversations. Remote participants find out about them after the fact. The fix is mandatory async documentation for any decision made in a live meeting. If something was discussed verbally, a brief written record — even just three bullet points in a shared channel — has to go up within four hours. Not five. Not the end of the day. Four hours. I learned this the hard way when a core infrastructure decision was made in a 12-minute call I wasn't invited to, and three weeks of rework followed because the remote engineers built to a different specification. Bug and defect triage gets messy fast when you don't have a clear severity framework. One person's P1 is another person's P3. Define the levels upfront and tie them to response time expectations. P1 means the system is down or data is lost. P2 means a critical feature is broken but workarounds exist. P3 is a non-critical bug that affects a small subset of users. P4 is a cosmetic issue. Without this, your team will argue about priority instead of resolving issues, and the actual critical bugs will get buried under noise.
Get the Full Details

Here's something most guides won't tell you: the cheat sheet should be a living document, not a static reference. I've seen teams treat theirs like a museum piece — something to consult once and then file away. That's backwards. The value is in updating it. Every project war story belongs in there. When something went wrong, how did you fix it, and what warning signs preceded the failure? Write it down while it's fresh. Six months later, you won't remember the details of that critical vendor delay or the miscommunication that caused two teams to build conflicting APIs. There are also tradeoffs you need to accept. A cheat sheet is never going to cover every edge case. If you're working in a regulated industry with strict compliance requirements, the document will grow large enough that nobody references it. In those cases, break it into role-specific quick references — one page for project managers, one for developers, one for stakeholders. Keep each version short enough to actually read during a crisis. Cluttered documentation is worse than no documentation because it creates false confidence that everything is covered. Another counter-intuitive point: sometimes the best troubleshooting step is knowing when to escalate. Junior project managers I've worked with spend hours trying to solve problems themselves because they don't want to look incompetent. That's usually when things get worse. Your cheat sheet should include a clear escalation tree with time thresholds. If a blocker isn't resolved within 48 hours, you escalate to the next level. If it's still unresolved after 72 hours, you escalate again. Make the escalation path visible and normalize it. The goal isn't to solve everything alone. The goal is to keep the project moving.
If you want a starting template, begin with a two-column format. Left side: the symptom or problem you're seeing. Right side: the diagnostic questions to ask and the immediate actions to take. Keep it to one page per major category — scope, schedule, resources, quality, communication. Anything longer gets ignored. I've never seen a 20-page troubleshooting document get used in a real crisis. People pull up whatever fits on a single screen during a panic, not a document they have to search through. The cheat sheet I reference above covers the most common failure modes across multiple industries and project types. It's organized by symptom rather than by methodology so you can find the relevant section quickly when something goes wrong. Download it, print it if you need to, but more importantly, add your own entries as you encounter new problems. The document only gets better when you put real experience into it.