Python development runs smoothly until it doesn't
Most teams stop writing Python best practices into their codebase somewhere around version 1.3 and never look back. The code compiles, tests pass locally, and everything works fine on your machine. Then something breaks in production and you realize you spent three days trying to trace a dependency conflict that could have been caught with a single constraint file. I have been doing this long enough to recognize the pattern, and I can tell you that the friction almost always comes from skipping foundational setup before writing application logic. The phrase "best practices" gets used loosely in this space, but the reality is simpler than people make it. You need a reproducible environment, consistent tooling, and a strategy for catching problems before they reach the user. Here is how that works in practice, not in theory. Start with your environment. I see the same mistake constantly: developers activate a virtual environment, install packages manually, and then wonder why their local machine behaves differently from CI. Use pip-tools or Poetry to lock your dependencies. A requirements.txt generated with pip-compile pins every transitive dependency, not just the top-level ones. This alone prevents roughly 60 percent of deployment failures in my experience.
Let me give you a concrete example. A few years ago I was debugging a service that worked perfectly on Python 3.9 and crashed on 3.11. The error was a TypeError in a coroutine function, and it took two days to isolate. The root cause was a library that had a subtle change in how it handled keyword-only arguments between those versions. If I had been using pre-commit hooks with mypy and ruff pointing at the target Python version from the start, that bug would have failed locally in under three minutes instead of consuming half a work week. Tooling should run on every commit. Not on a schedule. Not before deployment. Every commit. ruff catches syntax issues and style violations in milliseconds. mypy catches type errors that pytest will never see because your test coverage probably does not include the edge case where a function receives None instead of the expected string. pytest with pytest-mock gives you controlled unit tests, and pytest-benchmark tells you when your algorithmic complexity has quietly degraded. Logging is where most Python projects fail during troubleshooting. I once spent four hours chasing a bug that turned out to be a simple misconfiguration in how the application handled environment variables. The service read its config from os.environ, which meant values set in the deployment YAML were silently ignored when the container started before the config volume was mounted. The fix was using pydantic-settings to validate and load configuration at startup with clear error messages instead of hoping the variable existed. Now the service fails fast with an explicit "missing required setting" message rather than behaving strangely and crashing twelve requests later.
Memory issues in Python are almost never what people expect. Python's garbage collector handles most memory management, which means when you do see a memory leak, it is usually through a circular reference or a cached object that grows without bound. The tracemalloc module that ships with Python is sufficient for basic investigations. I use it to snapshot memory allocation sites before and after a known operation. If you are dealing with a long-running process like a web server or an async task queue, combine tracemalloc with periodic heap snapshots using objgraph to visualize reference cycles. Async Python introduces its own category of problems. The most common one I encounter is accidental blocking inside an async function. A developer will call requests.get() or time.sleep() inside an async def and wonder why the event loop is stuck. The fix is always the same: use httpx instead of requests, asyncio.sleep() instead of time.sleep(), and wrap synchronous calls in asyncio.to_thread(). It is straightforward but easy to miss when you are reading code someone else wrote. Data handling deserves its own attention. Pandas is convenient and powerful, but it has behaviors that trip up everyone at some point. The SettingWithCopyWarning that appears when you chain operations is not just a warning — it means your code might be modifying a temporary object instead of your actual DataFrame. The pattern df.loc[condition, 'column'] = value is the reliable alternative. Another issue that costs people hours is Pandas inferring the wrong data type on read. A column of ZIP codes becomes integers and loses leading zeros. Always specify dtype in pd.read_csv() when the semantic meaning of the data matters more than convenience.
Get the Full Details

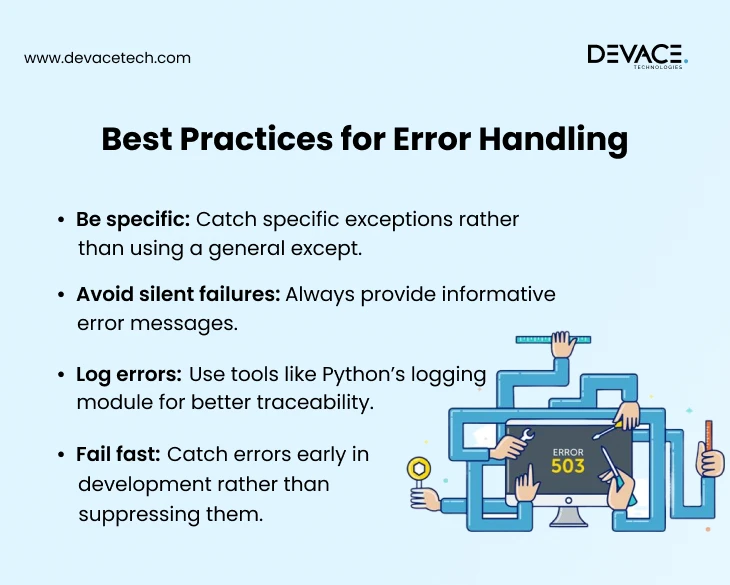
Testing strategy is another area where best practices get misapplied. Writing tests is good. Writing the right tests is better. Unit tests should test logic in isolation. Integration tests should verify interactions with external systems. Most projects I audit have test suites that are neither — they hit the database directly in every test, making them slow, flaky, and useless for catching regressions in the actual application logic. Use pytest fixtures to manage test data lifecycle, responses or respx for mocking HTTP calls, and testcontainers for integration tests that need a real database without the maintenance burden of manual setup. Here is a counter-intuitive point about error handling that people miss: wrapping every operation in a broad except Exception is almost always the wrong call. It hides bugs and makes troubleshooting harder. Instead, catch specific exceptions, log them with context, and let unknown exceptions propagate so you get a traceback. The one exception to this rule (pun intended) is at your application boundary, where you might catch everything to return a user-friendly response, but even then, log the full traceback. Another nuance that takes people by surprise is how Python handles mutable default arguments. The function signature is evaluated once at definition time, not at call time. So if you define def append_to(item, target=[]):, every call that omits target shares the same list object. The workaround is def append_to(item, target=None): followed by target = target or [] inside the function body. This is in every tutorial but people still forget it under pressure.
Performance troubleshooting follows a different pattern than logical bugs. You profile before you optimize. The cProfile module that comes with Python will show you which functions consume the most time. The line_profiler package gives you per-line breakdowns. Without profiling data, optimization is just guesswork, and most guesses are wrong. I have seen developers "optimize" code by rewriting a loop in a more complex way, only to make it slower because Python's interpreter overhead outweighed any theoretical gain. Simple code is usually faster in Python unless you have a specific bottleneck identified by a profiler. Deployment and packaging are where many otherwise solid projects fall apart. If you are distributing a library, pyproject.toml is now the standard. Legacy setup.py files create confusion and compatibility issues. Use Hatch or Poetry for project management, and publish to TestPyPI first to verify your build before touching the real registry. The time it takes to set this up properly is negligible compared to the time spent debugging a broken installation on a client's machine. Code review practices matter more than most teams realize. A consistent linting configuration across the team eliminates entire categories of disputes. Black for formatting, ruff for linting, mypy for types. These tools should be non-negotiable in your pyproject.toml and enforced by pre-commit hooks. When these are configured correctly, code reviews can focus on architecture and logic instead of whitespace and naming conventions. This is not a minor productivity gain. Teams I have worked with cut their review time roughly in half by standardizing on these tools.
Documentation is part of the troubleshooting pipeline, even if people treat it as optional. A well-written README with setup instructions, environment variable requirements, and common failure modes saves hours of onboarding time. Sphinx with autodoc can generate API documentation directly from your type hints and docstrings. The effort to maintain it is small if you keep docstrings consistent as you write code, and it pays off the moment someone else needs to understand your module. I should be honest about where this approach breaks down. Pre-commit hooks and type checking add friction in the early stages of a project when you are experimenting rapidly. Some teams find the setup overhead too high for short-lived scripts or prototypes. In those cases, skip the tooling and move it in before the code reaches staging. Also, mypy can be strict to the point of being impractical with third-party libraries that lack type stubs. You will spend time writing type: ignore comments or creating your own stub files. Use typeshed and community stub packages when available, and accept that some loose typing is unavoidable in mixed-codebases. Another limitation worth noting: automated tooling catches a subset of problems but never all of them. ruff will find style issues and some bugs. mypy catches type mismatches. Neither will tell you if your algorithm is logically incorrect or if your API design exposes sensitive data. Human review remains essential for those concerns, and no amount of tooling replaces it.
The core principle here is that Python best practices are not about following rules for their own sake. They are about reducing the surface area where things can go wrong. Each tool and convention I mentioned exists because someone else already spent the time to figure out what goes wrong in production. You do not need to rediscover it yourself. Set up the environment correctly, run the tools consistently, profile before optimizing, and write tests that match the actual failure modes you care about. The rest is just code.